Over on IEEE Spectrum, [Stephen Cass] has a project that would probably have seemed like a magic a few centuries ago. Imagine a box that uses a magnetic device to holds a locking bolt, requiring a magnet to disengage it. The only problem is that any strong magnet can open the box. [Stephen], instead, used an array of 64 Hall-effect sensors developed by [Peter Jansen] to look for a specific magnetic gesture.
Inside is a Teensy that can read the 8×8 grid of sensors. A magnetic stylus allows you to draw an unlock pattern. The system lets you train the gesture you want. There are a few problems. The sensor covers a small area, so it is hard to reliably produce the gesture. Putting an obvious mark on the box is a dead giveaway, so [Stephen] put a Celtic knotwork pattern on the box and uses part of it as a reference.
The other problem is that if you run out of battery, the box is locked forever. Well, at least until you apply mechanical force and break the box open. Wireless charging would be an option, but we might favor a small jack that would allow you to plug in an external battery.
This is a clever use of the sensor. However, we might have preferred a mechanical solution that didn’t require batteries. Or, perhaps, you could use a few normally open and normally closed reed switches to make a kind of magnetic combination lock. It would still need a battery, but it wouldn’t draw current until you connected the switches. Both methods also have drawbacks, of course. Like most things, you just get to pick the drawbacks you can live with.
Hackaday Editors Elliot Williams and Al Williams met to review the week in Hackaday. Turns out, it was a week for tiny things, cybersecurity, nostalgia, and projects that would have been nearly impossible for the average hacker not that long ago. But first, you can hear a little about the upcoming Supercon badge and the trials of importing and exporting parts for the badges.
How many props does your drone have? [Joshua] has one. Want to fabricate semiconductors at home? Do you have a microwave? What about using NFC in your next project? There’s all that and more in this episode.
The quick hacks include a request from NASA for ideas (and, yes, there is prize money) and slide rule tricks, among other things. For the can’t miss articles, the cybersecurity weekly got some appreciation and Al took a trip down memory lane at the Altair 8800 he always wanted.
Check out the links if you want to follow along, and as always, tell us what you think about this episode in the comments, or drop us a line on the mailbag.
Thanks to [Silver Dog Australia] for some new sting sounds for the podcast. Send us your sound, questions, or thoughts on the podcast for next week’s mailbag: mailbag@hackaday.com
I recently got the Amazon Christmas toy book in the mail, and it is definitely the modern version of the Sears Christmas Wish Book for last century’s youth. Or at least the majority of last century’s youth. For the true hacker, we had a different set of wishes. Recently, I found something I’ve clung to for over 50 years: the 1975 “The Age of Altair” catalog from MITS. Now that was a wish book!
The poor thing has been dragged around for decades and, I’m sad to say, it looks it. It isn’t totally trash, but I decided I should scan it. Then I realized that Bitsavers has already done it for me and with a much nicer copy, too. The images in this post are from their scan instead.
About the Altair
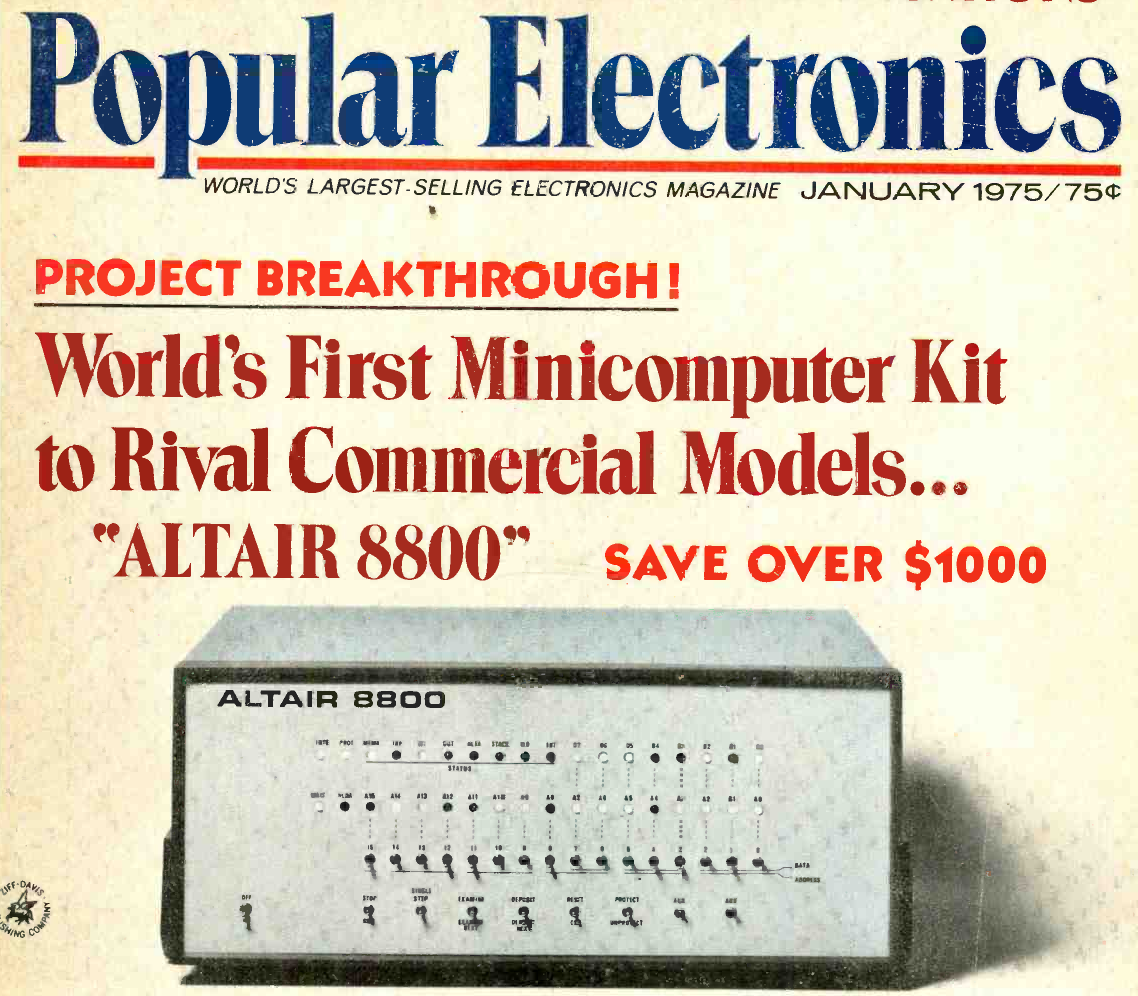
The magazine that started it all (World Radio History).
If your first computer ran Windows, you might not get the significance of the Altair. Back in 1974, the idea of having your own computer was practically ludicrous. Sure, Radio Electronics had published plans for the Mark 8 in July of that year. But it used an anemic 8008 CPU, and it wasn’t easy to get all the parts you’d need to build one. Other limited computers, like the Kenbak-1 or the occasional surplus minicomputer, ended up in personal hands. But you couldn’t just decide you wanted a real computer, plunk down some money, and have one delivered unless you had extremely deep pockets.
To stay on magazine stands longer, old print mags would come out earlier than their cover date suggested. The January 1975 Popular Electronics arrived, actually, in December of 1974 — just in time for the holidays. It showed a computer you could buy as a kit or assembled: the Altair 8800. Many of us were mesmerized by the idea of owning an actual useful computer.
Reality Check
Of course, the problem is, it wasn’t actually a useful computer. All by itself, it was a bunch of switches and LEDs with a CPU. You’d need memory, and even a little was super expensive. But it was still cheaper than anything else. Want a terminal and enough memory to run BASIC? That’s going to be even more.
In those days, magazines had “bingo cards.” Each ad had a number, and if you wanted more information, you circled that number on the card and mailed it to the magazine. A while later, you’d be rewarded with mail from the company in question. I have no idea how many of the “Age of Altair” catalogs were sent, but I know I got one.
The machine on the cover didn’t look much like the machine in the magazine. The story is that the original machine was sent to the magazine for photography and was lost in the return shipping. But either way, it looked like a small minicomputer of the era.
Micro
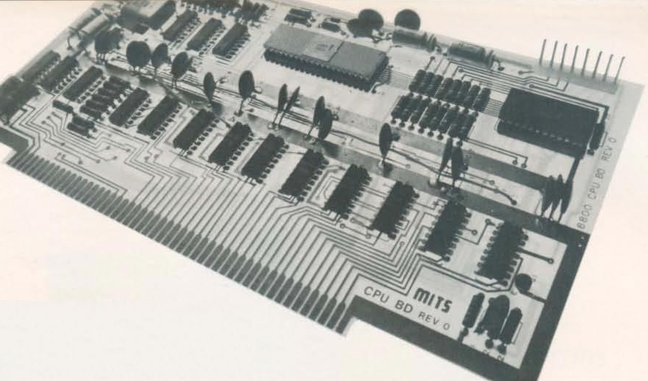
The CPU board used what would later be called the S-100 bus.
The catalog notes a cycle time of two microseconds, or about 500 kHz. That’s a little misleading. The CPU actually ran at 2 MHz, but each instruction took multiple clock periods, and some instructions required several machine cycles. Even a simple NOP took two microseconds, while more complex instructions could take considerably longer. It wasn’t a speed demon.
One nice thing about the Altair is that it had a card cage, and you could plug in whatever you wanted with what would later be called the S-100 bus. Of course, to save money, you might not get all the card guides and connectors.
If you had deep pockets, you could get fast static memory. This would cost more and provide less memory, but the chips stored bits in flip-flops, and it was fast. Or you could opt for more dynamic memory, which stored data in tiny capacitors on its memory chips. The downside is that the memory had to periodically refresh itself, stealing cycles away from the already slow CPU.
Down with Switches
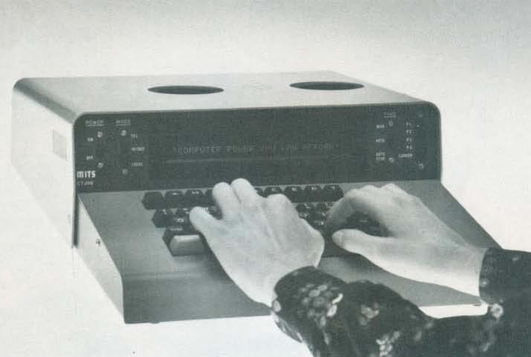
The Comter 256 showed a whole 32 characters at a time!
Naturally, you didn’t want to flip switches all the time. MITS offered the Comter 256 terminal. It had 256 bytes of its own storage and a whopping 32-character display. It even had holes to stick your phone in, if you wanted to talk to a remote computer.
This was, of course, not very practical. Your best bet was a TeleType. The TeleType Model 33 had a printer and a keyboard. The ASR variant had a paper tape reader and punch, too. Mass storage and a printer that operated at 10 characters per second. No screen, though. Everything you did was on paper. And it was pricey, too.
Software
The catalog offered a 4K and 8K BASIC along with “Extended” BASIC, which needed 12K but got you double precision math, PRINT USING, and disk I/O. There was also a single page of 8080 instructions in binary. I remember fixating on that page, trying to understand how you’d program this machine. There was a lot of missing detail.
Pricing
For as cheap as these were compared to the alternatives, they were still out of reach for many people, especially a kid. The computer itself was just a bit over $600 unless you wanted to build it yourself. Then you could save just under $200.
You couldn’t do anything without memory, though. A board that could hold 1 kB of static RAM (but only came with 256 bytes) was $134 assembled, plus $61 for every 256 bytes after that. If you wanted the board fully loaded, they discounted that to $209. The slower 4 kB dynamic RAM board was a cool $338. If you didn’t have paper tape, you probably wanted the interface to load and save programs from cassette. That was another $174.
Wanted something with a keyboard? The Comter terminal was $885, but for $35 more, you could get one that would also work with your cassette recorder to save and load things. Or opt for the TeleType for $1,500. You might be tempted by the 88-VLCT (the “low cost terminal”) at only $169. But if you saw it, it only had seven numeric keys (for octal) and two other buttons.
That’s not all. Those terminals had to plug into something. That board would run you around $140, depending on which variant you wanted. Even something like a real-time clock was an extra purchase.
The base computer price had four available slots, one of which held the CPU. So if you had a CPU, two memory cards, and a serial I/O card, you were full unless you bought more slots. To make it easier, you could buy a bundle. The cheapest was just shy of $3,000.
Perspective
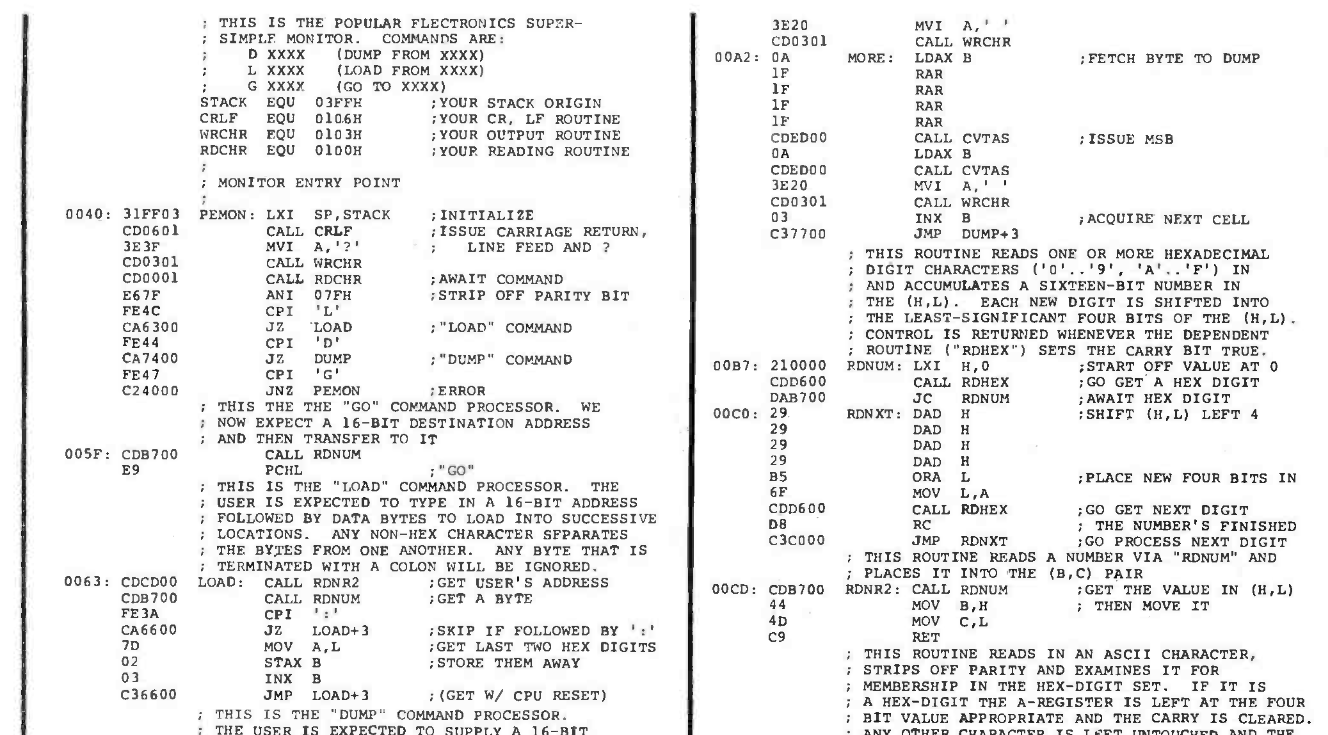
Why are the addresses backward? Part of the PEMON monitor from the November 1975 Popular Electronics.
I know. It is easy enough to spend $3,000 on a state-of-the-art computer today and, at the time, this was pretty state-of-the-art. But in today’s dollars, that’s about $19,000. A new car was about $5,000, and $3,000 would get you a very nice used car. An average home ran about $42,000, and $3,000 would be a hefty part of a down payment. The median income in 1975? Under $14,000.
Still, these were the first real computers you could at least imagine buying. It wouldn’t be long before the prices of even better machines dropped considerably.
I wasn’t the only one who wanted one of these machines. I conspired with friends to pool money to get one, but we never managed it. I pored over machine code listings in later magazines and the instruction reference in the catalog, trying to puzzle it out. I finally did. In those days, you couldn’t just download the manuals or watch a video about it.
Then again, the value of an original working Altair 8800 today makes it, again, out of reach for most of us. There are always faithful recreations. Or even less-than-faithful ones. I have plenty of these recreations and simulations now, but I still have kept the catalog I pored over so many years ago.
If you are one of those people who visualize things physically better than in the abstract, then Regex Marble Run by [bottomless] might be for you. You enter a test expression and a string, and the site generates a virtual marble machine that lets you see the regular expression pick apart the string in a physical way.
Click this link, and you’ll see the regular expression “^[hH]ack.[dD][^0-9]*$” which, if you aren’t a regular expression user, might seem a bit cryptic. However, it is fairly simple if you take it bit-by-bit.
The caret character tells it to match the start of the string. So “^dog” will match “dog” and “dog food” but won’t match “food for a dog.” The following bit “[hH]” will match either “h” or “H”. Then there is “ack” which is just what you think it is. So a string starting with “hack” or “Hack” might match (depending on the rest of the expression.
The period means match any single character. Then there’s another “[]” but this time with “dD” to match any kind of D. The next “[]” character class is a range from 0-9, but since there is a caret, the match is negated. So “[^0-9]” means match anything except a digit from 0 to 9. The “*” means we can have zero or more of these. So “HackxD” matches, but so does “HackxDXYZabc” for now. Trick question: Does “HackxDXYZabc123” match? So far, yes, but it only matches to the lowercase “c” character.
The final character, “$” means end of string. So now “HackxDXYZabc123” does not match because we are still in the middle of the string. However, “HackxDXYZabc” will match since the previous “*” “ate” the rest of the string.
Head spinning? The site will let you see each letter of a test string as a marble that falls through the different parts of the regular expression. Balls that pass wind up in the left-hand box, while failures are in the right-hand box. Will it help you? We don’t know, but it is fun to watch.
If you need a micro-manipulator, you probably already have a good idea of what it does. For example, you might be moving a probe over an IC die or wafer. You might be looking at something through a microscope. The key is moving something in very small, precise increments along three axes. An open-source design for a micro-manipulator has seen significant improvements lately. You can see several videos about the device below.
The device uses stepper motors, parallel kinematics, and miniature ball joints to achieve precise motion. The recent version 4.0 update fixes a few problems. According to the GitHub page:
Self-collision during homing fixed.
Connection of the ball joint block with screws only was not well constrained and could be rotated a bit.
No reliable way to ensure consistent linkage rod length
Unnecessary ball joint friction
Accurate ball position heavily dependent on print quality and corner rounding
Rubber bands could not be changed or removed once glued in.
We’ve covered earlier versions of this device, and we were watching the improvements to the ball joints. Since then, the project has updated much of its mechanical design and documentation, and it has also changed the API that drives it. It can even use tools in g-code now to support things like fine control over laser engraving.
If you prefer something old-school manual, consider a 3D-printed one.
YouTube, like the Internet, has its plusses and minuses. On the plus side, you can find information on just about anything. On the minus side, you don’t always know if that information is of any value. On the plus side, you can connect to experts who have an uncanny knack for explaining things. On the negative side, you can find people who — let’s just say aren’t. Lucky for us, [Kerry Wong] is very knowledgeable about test instruments, so when we see a review from him, like the one for the ZOYI ZT-XC1 LCR meter and multimeter, we know we will get good information. Check out that review in the video below.
It used to be unusual to have an LCR meter that could measure inductance or capacitance in a home lab. But now it isn’t a big deal, and many multimeters and testers can at least attempt to read these quantities.
[Kerry] noted that the charging port is on the back, which is not very handy, but he also points out it isn’t a showstopper. Oddly, in multimeter mode, the device won’t read capacitance or current, so that makes it less handy as a multimeter.
One of the limitations of many capacitance measurement meters is that they can’t easily account for the capacitance of the test leads. This meter has two adapters that plug into the front of the meter for LCR measurements. That’s great, as long as what you want to measure fits into one of those adapters. If not, then you are out of luck. One adapter fits through-hole components, and the other one is a clever jig for holding surface-mount parts.
We always enjoy listening to [Kerry] talk about oscilloscopes. He even dabbles in reviewing test clips.
We know [The Action Lab] always has something hands-on. This time, the video shows a toroidal plasma demo and how it relates to nuclear fusion. Plasma has a high temperature, and if you use physical electrodes to excite the plasma, this high temperature tends to destroy the electrodes. But thanks to the relationship between electricity and magnetism, you can create plasma with an alternating magnetic field instead of physical electrodes.
The actual practical device is a 10 MHz source with a coil and a low-pressure globe full of xenon gas. It looks pretty cool. Of course, the little tabletop demo isn’t strong enough to drive a fusion reaction. But if you scale it up and make some modifications, including using hydrogen, you get a tokamak reactor.
The problem, of course, is that current reactors need more energy to operate than they produce. But we keep hearing that nuclear fusion is right around the corner. One day, that’ll probably be true.
Of course, you can build your own fusion device. Just don’t expect to generate net power.
[Bob the Science Guy] remembers how to use a slide rule. Even after all these years, it is pretty easy to remember how to multiply and divide. If you can’t remember, you can usually work it out, as long as you understand how slide rules work. But what about sine, cosine, and quadratics? [Bob’s] been making videos about topics like this, and if you’ve wanted to put your slide rule collection to practical use, you’ll enjoy these videos. You can see one below.
The trick to the slide rule is that it is deceptively simple. You are in effect adding logarithms and then taking an antilog. The issue is that you still have to have some intuition about the scale of the answer since 2×3 works out the same as 2×3000 or 200×300.
But it is even trickier than that. Adding and subtracting is not easy on the slide rule. [Bob] shows how to use your math skills to convert problems that might have been addition problems into trig problems. So while it might seem more complicated to use trig, it may help work the problem on the slide rule.
We aren’t sure what [Lazy_Duck] is doing with video games, but it must require a lot of controllers. Dismayed at the cost and complexity of commercial gamepads, they started soldering and 3D printing to get a cheaper basic controller.
The emphasis is on throwing things together, so there’s no dedicated PCB. Just a protoboard with an RP2040-Zero, a joystick, a few buttons, and a microswitch. A 3D-printed case rounds out the project.
On the printing side, the device uses heat-set threaded inserts, which should make for a very sturdy build. For software, the GP2040-CE firmware handles everything, acting like a controller and managing configuration via a web page.
Even if you don’t want a cheap gamepad, you could apply the principles and software used here to create any kind of gamepad you want. The firmware makes good use of the dual-core RP2040. It also offers a lot you could add to your version of the cheap controller, like OLED displays, RGB LEDs, and more.
Of course, you could also get fancy with the 3D printing side, too. For example, a resin printer makes nice button caps.
If you already know what a nonius is, you can probably skip this post. But, if like us, you would have to look it up, we’ll tell you what we found out. It turns out, a translation mistake taught us a new word and some history we weren’t aware of.
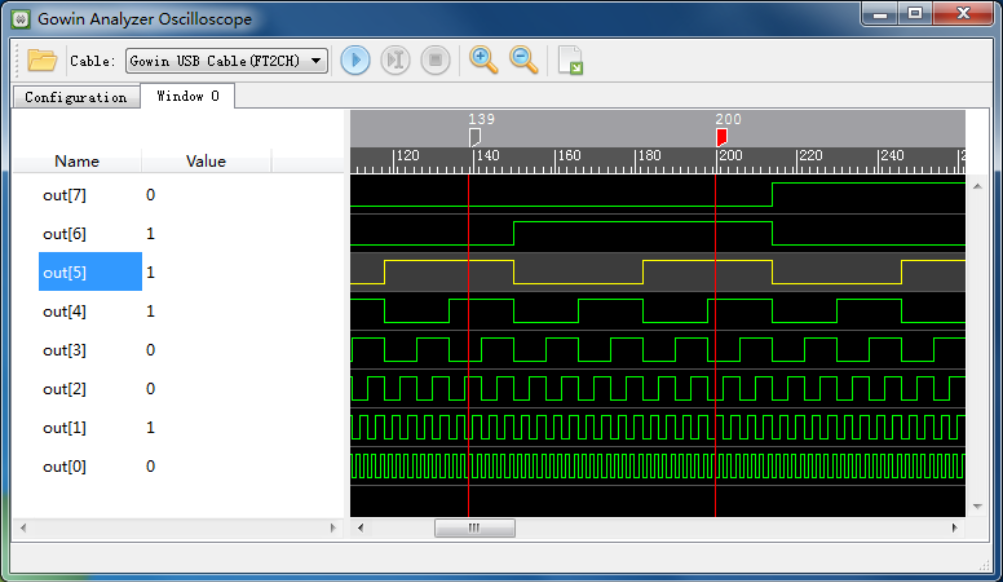
In the manual, this is captioned: Figure 4-7 Nonius Display (Standard Mode)
Have a look at the adjacent graphic from a waveform display. What would you call the vertical red lines at positions 139 and 200?
We’d probably call them markers. Or maybe cursors. The manual, however, calls each one a “nonius”. It refers to them that way multiple times.
Oddly, the manual also has sentences like “Select one nonius and right-click, and then select ‘Remove Marker’ in the next window to delete the nonius.”
So, clearly, a nonius is the vertical line marker or cursor. But that, of course, begs a question…
What is a Nonius?
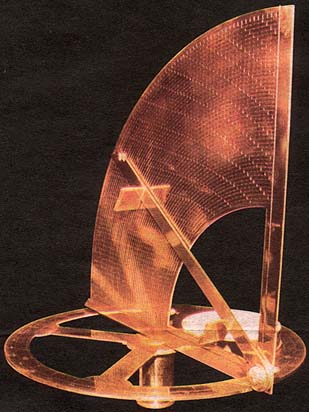
“Nonio originale” by [Henrique Leitão]Have you ever heard of the vernier scale? If you’ve done navigation, used a traditional caliper, or tuned an old shortwave receiver, you probably have. [Pierre Vernier] developed it in 1631 as a way to better interpolate values on a scale.
However, there was an earlier version used to improve measurements on astrolabes. A Portuguese navigator named [Pedro Nunes] created this type of astrolabe in 1542. The Latinized version of his name is [Petrus Nonius]. What are the odds of him inventing… oh wait, they named it after him. That does make more sense.
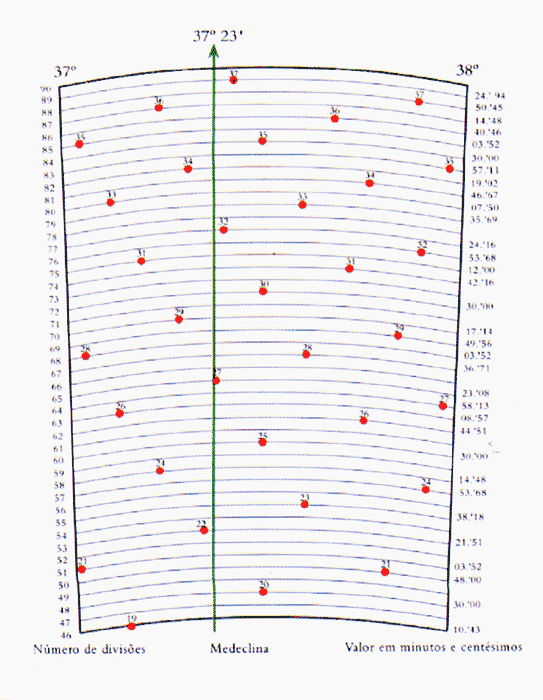
The nonius is a series of concentric circles traced on the instrument. Working towards the center, each circle has fewer divisions than the previous one. In fact, if the outer ring had 90 marks for 90 degrees, the next ring would have 89, and the following one would have 88.
The astrolabe’s line, the “alidade”, would cross all these circles but would be closest to one mark on one circle. Given that mark and that circle, you could look up the correct answer.
One degree of a nonius showing 37º 23′.
For example, the image shows such a system from [Nunes] himself. It shows the circle from 37 degrees to 38 degrees. You can see the 89th circle has only one mark for 37. The other marks are in other sectors of the outer ring. The 88th, for example, has two marks for 36 and 37.
On ring 65, the line runs right over the 27, which is hard to read because the line covers it up. With a table lookup, you’d find the correct value was 37º 23′ within 0.08′. Not bad. [Nunes] was considered one of the greatest mathematicians of his time.
But we had never heard of him, which goes to show that being a mathematician is not a good way to get lasting fame. [Charles V], [Nostradamus], and [John Calvin] were all born around the same time and, while not household names, are more likely to be known today than [Nunes].
And while this is interesting, it raises another question: Why did the GOWIN software instruction manual call the vertical marker line on a scope trace a nonius?
Why Nonius?
Lost in translation
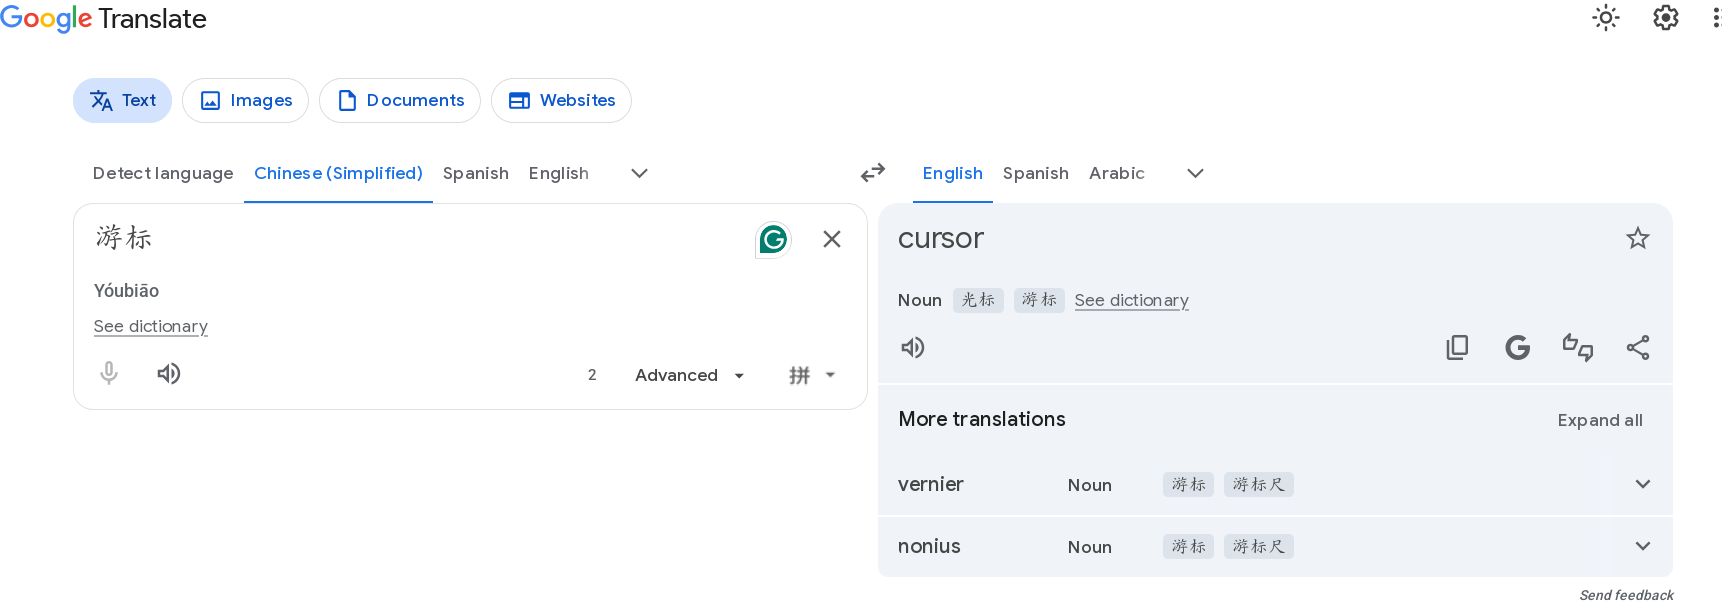
Our guess is that this is a translation mix-up: Chinese 游标 can mean either a computing cursor or a vernier. Or a nonius. Someone apparently selected the wrong English equivalent.
Of course, we figured it out. Plus, we learned a new word and a little history. So we aren’t complaining.
Astrolabes are pretty amazing. Navigation was so important that it drove many technological advancements. Of course, measuring things in general was also of keen interest to our forefathers.
In the last few installments, we looked at using the Tang Nano 20K with both the GOWIN tools and some open-source tools. The open-source tools certainly had the advantage of letting you simulate and debug your design before sending it to the actual chip. However, as we’ll see, the GOWIN tools include a very easy-to-use, capable logic analyzer.
Setup
First, you’ll need a GAO config file. When you create one in the editor, you are given a number of complex options. With an active GAO file, the tool builds a logic analyzer into your design, and the file sets the trigger conditions.
Here’s a tip. You can only have one active GAO file. Sometimes you don’t want the logic analyzer. Other times you might want an alternate configuration. If you right-click almost any file in the IDE’s Design tab, you’ll see you can disable it. That gives it a big red X and excludes it from future builds. Well, at least until you enable it again. This lets you pick between multiple GAO files, or even multiple Verilog files, for a particular build (e.g., one for tests and another for production).
If you create a GAO file from scratch, it will ask you if you want “Lite Mode.” As far as I can tell, you will never want this mode. Always use Standard Mode. In addition, you nearly always want RTL mode, which shows you (mostly) the symbols you’ve defined and not the ones added during processing.
You can find the entire manual online, of course. However, the video below and the rest of the post will get you started quickly.
GAO Basics
To set up probing, we need to understand the design, so the rest of this post covers the Verilog we’ll use to test the logic analyzer feature, and you’ll see how the analyzer works in a video. Here are a few sneak peeks at what the analyzer output we’ll see at the end looks like:
The left-hand image shows the pulse that flips the LEDs, which is tricky because the sampling clock is 27 MHz. The right-hand side shows serial data and uses a slower clock specifically used for debugging.
Inside the Verilog
Verilog can be dangerous. If you already know how to program, Verilog looks just enough like a programming language to encourage you to think about it the wrong way. You can’t think of Verilog as code. It describes how you want hardware to behave. A key part of that is clocks.
Most practical digital systems have some kind of clock that makes things work. Very simple things like our last example might not need them, but practical systems almost always do. In theory, you can make asynchronous logic, but it is very difficult. Synchronous logic — those with a clock controlling things — is vastly more common.
Why Clocks?
We think of signals as changing instantly, but they don’t. They change at slightly different times for many reasons: wire length, capacitance, differences in device construction, temperature, and probably many other things. So let’s think of an exaggerated example. Suppose you have a super safe car. If it detects the motor is running and the door is open, it kills the engine. That’s an AND gate, and for the purposes of exaggeration, suppose the signals from the door and the engine that feed the AND gate take a random amount of time between 100 and 900 milliseconds to get to the AND gate.
Normally, it wouldn’t matter much. You close the door, check your mirror, turn on your playlist, and you start the car. But suppose you were in a panic. You jump in the car and immediately try to start it. The engine start signal could get there before the signal that the door is open turns off. Suddenly, your engine cuts off right after you start it. Not cool.
This is a bit made up, but the problem is real. Suppose you want to add two numbers. One number changes from 11 to 22 while the other changes from 5 to 10. You want 16 and 32 as results. But instead you get 16, 27, and then 32. Or maybe 16, 21, and then 32. Still not cool.
So clocks basically let you give everything enough time to settle down and then figure out the output. Those outputs will stay stable until the next clock. That’s grossly oversimplified, but we’ll talk more about it later. Each thing in your design takes some time, and the longest time, in general, will dictate your maximum clock rate. So if one part of your design takes a microsecond to reliably change, your frequency will have to have a longer period than that.
Check out the example file. This is regular Verilog, although SystemVerilog (.sv files) has some advantages that you can utilize that I’ll point out. The example we’ve been using is a very simple design that just drives some LEDs on the 20K board. The input clock will be 27 MHz, so to make the LEDs blink, we will need to count many clock cycles and only change the LEDs sometimes.
In addition, it is going to use IP — predefined blocks — to build a UART. The function is simple and contrived. By default, entering a character through the UART will echo it. However, if you push the user button on the board, it will switch the board to a mode where it adds one to the character before resending it. If you push the button again, the output will be a straight echo. When you push the button in either case, the device will send an asterisk.
From the Top
At the top of the file you’ll see this line:
default nettype none
This is a good idea because without it, Verilog will happily create new nets from typos. For example:
countt=count+1;
Now count doesn’t change, but a new wire, countt is set and never used. The only problem is that some of the GOWIN IP expects the default nettype to be wire so at the end of your files, you need to put it back:
default nettype wire
Another quirk is that while some tools will realize that if you specify an input or an output, it should infer that you mean a wire unless you say otherwise. The GOWIN tools will refuse to do this if you set the default type to none.
Modular
The next part is the led module. This is a reusable piece, in theory. However, it is also our top block. The #() syntax allows me to set some parameters you can change when you create one of these modules, as well as the defaults. For example, in the previous testbench I wrote:
led #(.CLOCK_FREQUENCY(10, .INTERVAL_MS(1000)) uut(.reset(reset), .Clock(clk)...
This sets a slow clock and interval for simulation purposes instead of using the defaults. Not all modules have parameters. After that, though, there is what looks like an argument list of inputs and outputs. These are the ports you can use if this isn’t your top module, but since this one is the top module, we’ll need constraints to assign them to particular pins on the FPGA.
The localparam statements are like #defines in C, and we use them to set the required counter and figure out the number of bits we need for the counter ($clog2 gives us the base 2 logarithm at compile time).
Most of the time we deal with wires. Something has to drive them. They are perfect for connecting to things. But then there are also regs. You might think these are flip-flops, but that’s not exactly true. They are just Verilog variables, if you will.
It is easy to think of wires and regs as being 1 or 0, but it turns out Verilog also supports values like X (unknown) and Z (sort of like open collector). In fact, SystemVerilog allows you to write logic instead of wire or reg, something we’ll talk about soon. However, there is so much “plain” Verilog out there that it is important to understand it even if you plan to use the more modern SystemVerilog in your own work.
Look at this line:
reg [COUNT_BITS-1:0] interval_count;
The IP Generator has plenty of choices and links to documentation.
This tells us that we have a reg named interval_count. It has bits that range from bit 0 (least significant) to COUNT_BITS-1. Note that you can reverse those if it makes sense for your design. Or start at bit 1, for example. This is not an array, although Verilog does support arrays. This is a multi-bit variable. If you don’t specify the bits (like the interval_tick definition that appears next) then the variable is a single bit.
The next bit of code defines reg and wire variables that will connect to the UART. For now, we aren’t building our own UART. We’re using the IP provided by GOWIN. One problem with this is that it is really made to connect to a microprocessor, so we are going to cheat a little to make it simple to use. You can insert IP into a project from the Tools menu under IP Core Generator.
The final setup section handles the pushbutton input and LED state. The pushbuttons are not synchronized to the clock and this can lead to a major problem. Plus, mechanical switches can bounce — that is, they don’t go off then on. They go off, on, off, on, off, on, off, and then — after a few milliseconds — they settle in the on state. There is a debounce module included to help with these problems. For now, we’ll just use it like we’ll use the UART, even though this module is in debounce.v.
Instantiation
Here’s how we create a debounce module. You could, in theory, create as many as you like:
The name of the instance is button_filter, and we’ve set parameters to tell it our clock frequency and the debounce time, which is 10 milliseconds. The connectors are the clock and reset lines, along with the button input and a clean version of the button as an output.
Assignment: UART
There are a few lines that start with assign. These are Verilog’s soldering irons. You can connect a wire output to some variable or expression, and then that is what that wire will be. We’ve seen that in the earlier LED-only demos.
Then there is a much more complex instantiation of the UART. Although it has more ins and outs, it is basically the same as connecting the debounce module. Note that in some cases I just force fixed data to a pin (e.g., 3’b001, which is a three-bit binary constant, or 8’hff, which is an 8-bit FF hex. Some connections are wires or regs. Some are expressions like ~reset (the inverse of reset).
The upshot is simple. When uart_rx_ready_n goes low, you can read a character from uart_rx_data. The transmit has a similar setup.
The Flop
The rest of the file has three always expressions. There are two things you can do with always (in fact, SystemVerilog separates these out as we will see in the future). For now, we will focus on how to write clocked flip flops using always @.
The simplest one is the last one that toggles the LED state:
always @(posedge Clock) begin
  if (reset)
    led_state <= 1'b0;
  else if (interval_tick)
   led_state <= ~led_state;
end
This will create a flip-flop that triggers on the positive edge of Clock. If the reset line is high, the flip-flop will set led_state to 0. Otherwise, it will set the led state to the inverse of whatever it was before.
There are a few things to note here. First, led_state can’t be set anywhere else but inside this always block. The other problem is a bit trickier. Note that the assignments use <= and not =. You could write = but that leads to a problem. Imagine this code inside an always block:
qout=3'b000;
if (b) quot=~quot;
Verilog would interpret this to mean that quot should be set to 0 before the next line. Remember, though, that Verilog at “run time” doesn’t step through code line-by-line. So it would infer a latch to hold this value and feed it to the logic that handles the second line.
Not only is this not what you want, but it generates strange things on the device that will not operate efficiently. Instead, you want to use the <= assignment. In essence, every value of quot read in the always block will be whatever quot was at the clock edge. Then, at the end of the block, the last <= assignment “wins.”
This is probably what you really meant anyway and avoids creating strange latches that will, at best, slow down your design. In practice, you can think of it as the flip-flops will capture inputs on the clock edge, then produce outputs that will be ready (at least) by the next clock edge.
Metastability
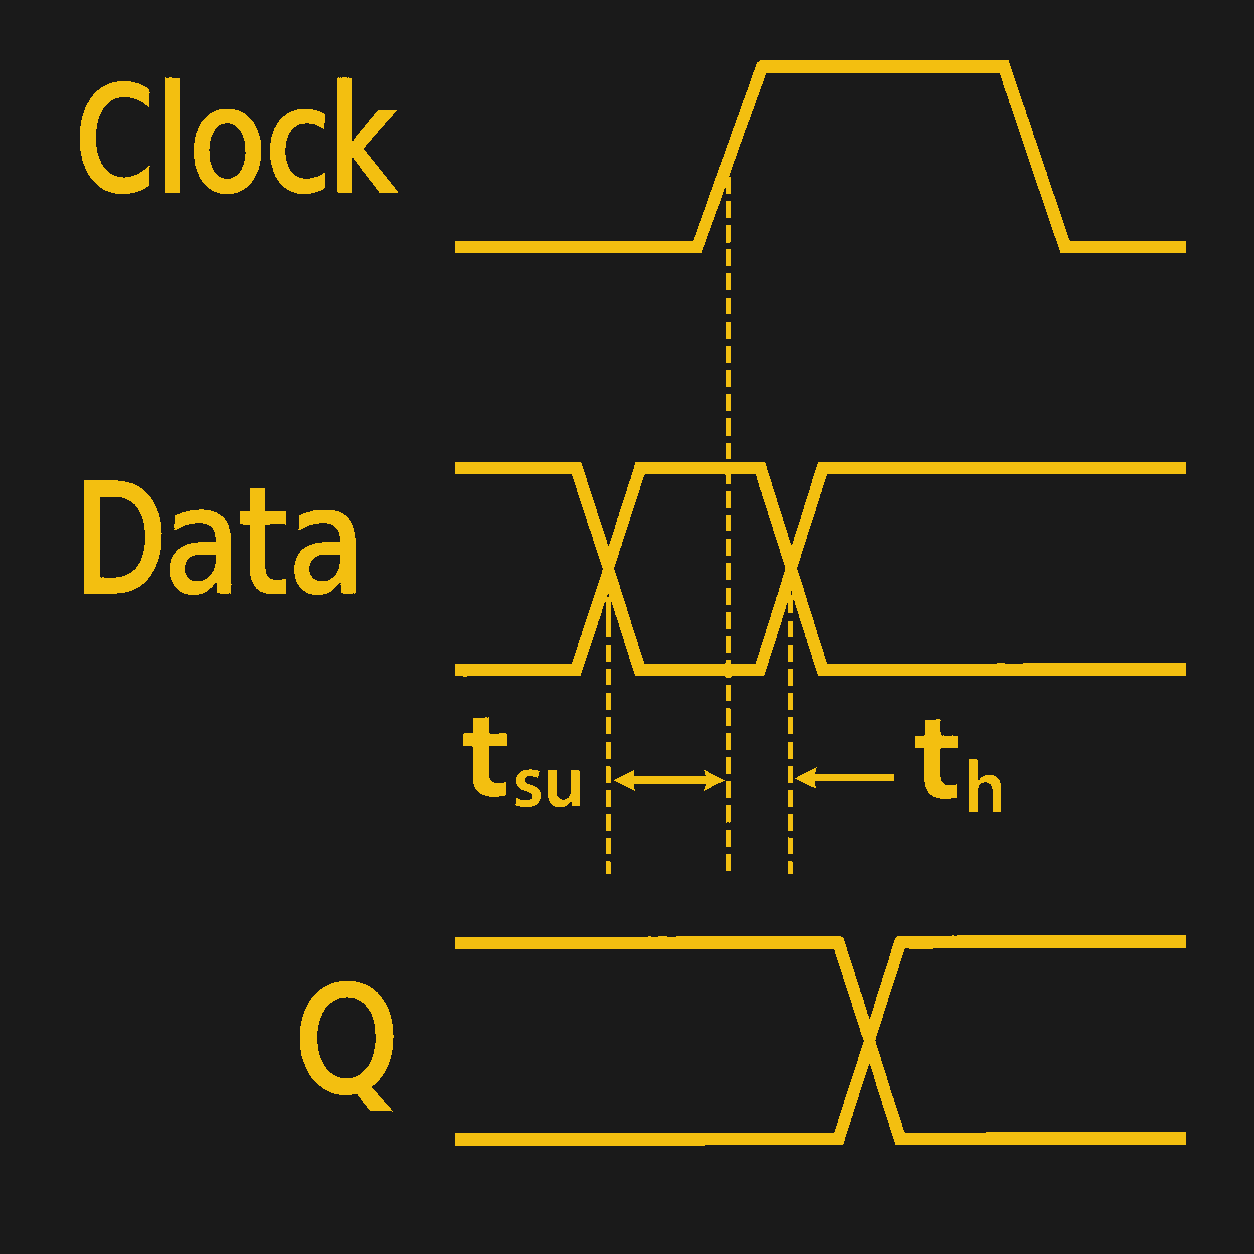
Data must be stable for the setup time through the hold time.
I mentioned the debounce module did two things: debounces the mechanical switch and synchronizes with the clock. The problem is that we imagine flip-flops to be perfect but, of course, they are not. Any practical flip-flop has a setup time and a hold time. Imagine a very bad flip-flop that had a setup time of 100 milliseconds and a hold time of 50 milliseconds. That would mean that an input has to be stable for at least 100 milliseconds before the clock trigger and can’t change until 50 milliseconds after the trigger.
This is one thing that affects your maximum clock speed. Logic has to have time to stabilize before the clock triggers. But if something is coming from another clock or, worse still, asynchronously, then you run a risk. If the flip-flop’s requirements are not met, it can go metastable, where it could be in an indeterminate state or even oscillate wildly.
The most common way to combat this is to delay the signal with a few flip-flops. The idea is that even if one flip-flop goes metastable, it won’t go all through the system. Just something to be aware of if you deal with something asynchronous or try to connect flip-flops using one clock to those using a different clock.
If a Picture’s Worth…
Now that we know what’s going on in the Verilog, we’re ready to set up the logic analyzer. You can find out how that works in the video below. You can also grab the files on GitHub.
Be sure to drop by the Discord. If you need a refresher on digital logic, there are always the FPGA Bootcamps.
When you first learn to program, memory seems pretty straightforward. You have a bunch of bytes, each with an address. If you want to read or write something, you specify the address, and the computer goes to that place and does your bidding. Sure, some addresses might be reserved for hardware or the operating system, but the general idea is simple: memory is a big array of bytes.
Just like we pretend that a wire is a perfect conductor, the big array of memory model used to be a slight twisting of the truth. On a modern computer, however, it is almost entirely a lie. The address you use probably isn’t a physical address. The data you read might not come from RAM at all. Even if it does, it might be sitting in one of several caches. And if you follow the rabbit hole far enough, you discover that your SSD is arguably just another level in the memory hierarchy.
The Need For Speed
The fundamental problem is that processors have gotten much faster than memory. A modern processor can execute several instructions per clock cycle, but accessing ordinary DRAM can take hundreds of cycles. If the processor had to wait for RAM every time it needed data, much of that impressive computing power would go to waste.
The solution is caching. Keep copies of frequently used data in smaller, faster memories closer to the processor. Most modern desktop processors have at least three levels of cache. The L1 cache is tiny but extremely fast, and often split between instructions and data. L2 is larger and somewhat slower, while L3 is even larger and usually slower as well.
Things get interesting with multiple cores, as is often the case these days. Typically, each core has its own L1 and L2 caches, while several cores share an L3 cache. But that’s not universal. Some processors share L2 caches between cores. Others have multiple L3 caches, each serving a group of cores. The exact arrangement depends on the processor architecture.
One important detail: caches don’t generally work byte by byte. They transfer and track blocks called cache lines, commonly 64 bytes on modern desktop processors. If you read one byte that isn’t cached, the processor generally fetches the entire line containing that byte.
This is why sequential memory access is often much faster than random access. If you read the next byte, there’s a good chance it’s already in the cache. Hardware prefetchers may even anticipate what you’ll need next.
But there can be problems. Imagine two cores modifying completely different variables. If those variables happen to occupy the same cache line, the cores may repeatedly invalidate each other’s copies, wasting time even though they aren’t logically sharing data.
Protocols such as MESI keep the caches coherent, coordinating which core owns a line and which copies are valid. MESI is an acronym for cache line states: modified, exclusive, shared, or invalid. Memory systems must figure out how to keep caches in sync. But coherence doesn’t eliminate the need for synchronization or memory-ordering rules in multithreaded programs. The point is that even our simple byte-addressed memory is secretly operating in larger chunks.
The Address Isn’t Real, Either
So far, we’ve assumed that the address you supply identifies a location in RAM. Usually, it doesn’t. Modern operating systems use virtual memory. Your program sees a virtual address space that the operating system and processor cooperate to map onto physical memory.
The memory management unit, or MMU, translates virtual addresses into physical addresses, typically using page tables. This lets different programs use identical virtual addresses without interfering with one another. It also provides memory protection and allows physical pages to be shared.
Of course, translating addresses takes time. So we add another cache.
The translation lookaside buffer, or TLB, remembers recently used address translations. A TLB hit avoids a potentially expensive page-table walk. Some processors even have multiple levels of TLBs. Unlike the ordinary CPU cache, which generally operates on cache lines, virtual memory usually works with pages, often 4 KB, although larger pages are also supported.
Notice what’s happening. We have caches for data, caches for instructions, and caches for the information needed to locate the data and instructions.
The simple act of reading a variable has become surprisingly complicated.
Not All RAM Is Created Equal
Even if we get through the caches and finally reach RAM, things aren’t necessarily simple. On systems with multiple processors or certain multicore arrangements, memory access can be non-uniform. This is called NUMA, or Non-Uniform Memory Access.
A processor may have relatively fast access to memory attached to its own NUMA node, while accessing memory associated with another node requires crossing an interconnect. Both locations are ordinary RAM, and both may appear in the same address space, but the access times and available bandwidth can differ.
The operating system tries to place memory near the processors using it. Moving a thread to another CPU can therefore change its memory performance, even though the program’s addresses haven’t changed.
And NUMA isn’t limited to traditional multiprocessor servers. Modern systems with chiplets, heterogeneous memory, and technologies such as CXL are making memory topology increasingly interesting.
What If It Isn’t In Memory?
Virtual memory has another trick. A virtual page doesn’t necessarily have to be backed by physical RAM at the moment you access it.
When a program accesses a page that isn’t currently mapped in a usable way, the processor generates a page fault. The operating system decides what to do. Sometimes it simply allocates a fresh page. Sometimes it retrieves data from an executable or memory-mapped file. Other times, the page was moved out of RAM to swap space and must be retrieved. Note that things like executable data are generally immutable, so most operating systems won’t swap them out. They simply trash them and know they can reload the same page later when needed.
This means your program can address data that isn’t presently in physical memory. Naturally, accessing an SSD is much slower than accessing RAM, so excessive swapping can bring a computer to its knees.
Virtual memory doesn’t actually require swapping, though. Address translation and protection are useful even on systems that never move pages to disk.
Your SSD Is Memory, Too
Suppose your program reads a file. You might imagine that the operating system sends a request to the SSD and waits for the data. But if the file was recently accessed, the data may already be in RAM.
Operating systems maintain a filesystem page cache, keeping frequently or recently accessed file data in memory. Writes may also be buffered in RAM before eventually reaching persistent storage.
This makes RAM act like a cache for secondary storage, much as L3 acts like a cache for RAM.
The analogy isn’t perfect. RAM is also the primary working storage for running programs, and anonymous memory isn’t necessarily a copy of anything on disk. But the general hierarchy is clear: registers, CPU caches, RAM, and persistent storage provide progressively different tradeoffs between speed, capacity, and cost.
Even SSDs have their own caches and address translations. Their flash translation layers map logical block addresses onto physical flash locations, hiding wear leveling and garbage collection from the host. Apparently, nobody wants to tell the truth about addresses.
Compressing The Middle
But what if we could make RAM effectively larger without adding more? Compression offers another way to complicate our memory hierarchy. Instead of immediately moving an infrequently used page to disk, why not compress it and keep it in RAM?
Linux has two well-known mechanisms for doing this: zram and zswap. Zram creates a compressed block device in RAM. It’s commonly used as a swap device, allowing pages to be stored in compressed form rather than written to physical storage.
Zswap, on the other hand, is a compressed cache in front of a swap device. When Linux decides to swap out a page, zswap attempts to compress and retain it in RAM. If necessary, pages can eventually be evicted to the backing swap device.
Both trade processor time for memory capacity and reduced storage I/O. Decompressing a page costs CPU cycles, but that can be considerably cheaper than retrieving it from an SSD.
There’s a catch, though. These mechanisms operate through the swap subsystem. When a compressed page is needed again, it must be decompressed into an ordinary page before the program can access it. That means page faults, memory management overhead, and moving data around. But what if compressed memory could behave more like ordinary RAM?
Rather than treating compressed memory as a conventional swap device, CRAM proposes exposing it through a special NUMA node. Linux can then use existing memory-management mechanisms to move pages between ordinary DRAM and compressed memory. The most interesting part is the hardware-assisted compression and decompression, which allows access at much finer granularity than conventional page-oriented compressed swap.
The developers report impressive benchmark results, including read performance that approaches ordinary DRAM in some tests and dramatic improvements over zram for selected workloads.
That doesn’t mean compression has suddenly become free. Writes, compression ratios, hardware requirements, and managing incompressible data all matter. CRAM is still developmental work, not ready for everyday use.
But it illustrates where the memory hierarchy is heading. Instead of simply deciding whether a page is in RAM or on disk, the operating system may choose among ordinary RAM, compressed memory, slower memory tiers, and secondary storage.
The Illusion Is The Feature
Most programmers don’t need to think about any of this most of the time. That’s the point of an abstraction. But when performance matters, the illusion starts to leak. Sequential access can beat random access by enormous margins. Two threads modifying unrelated variables can fight over cache lines. Moving a process between CPUs can change its memory latency. A page that looks like ordinary memory might actually require decompression or a trip to an SSD.
On smaller embedded systems, of course, the picture may be very different. Without an MMU or elaborate caches, memory can look much more like the simple physical address space we learned about in the first place.
We started with an array of bytes. We ended up with a hierarchy of caches, translation tables, NUMA nodes, compressed memory pools, and persistent storage devices, all cooperating to maintain that simple illusion. Amazing how complicated something so simple can be.
If you would like an AI “personal agent” but don’t want your data on some opaque cloud computer, there’s a new option that appears to be somewhat nicer: [rociiu] has talorys, an AI agent that runs in your Cloudflare account. True, it is still on a cloud computer, but it is your account on a cloud computer. It is designed so you can use it on Cloudflare’s free account with reasonable limits, and the code running is all on GitHub, so you can — if you are so inclined — look to see what it is doing. The data, too, is all in your cloud instance.
This seems like a reasonable compromise. Cloudflare provides the hosting, and the software in your virtual computer does all the work. At least, that’s how it is promoted. Honestly, we haven’t combed over the code, but the assertion is “Free-tier friendly… no telemetry.”
We are fairly sure they are using Cloudflare’s AI engines, too, so it would be interesting to see how much of your data they could, in theory, harvest in transit. Of course, your data is still in the cloud, so if you are really worried about privacy, this might not be for you. But since everything is in your account and open, you can at least have more control over what’s there. For example, you can easily download or delete your data. You can even see exactly what prompts it uses.
Are there downsides? Sure. The tool can’t integrate with your calendar, for example. It can’t deal with e-mail, nor can it search the web. It won’t write code for you. This isn’t meant to be a general-purpose chatbot replacement. It is more like an AI tool for keeping a task list.
While Cloudflare does have a free tier, it does have daily limits, and you may hit them. And, of course, if things like this get too popular, they could reduce those limits. The system does let you export your data, though.
It isn’t flawless. We asked it to set up three recurring meetings. It got one right, put the other one in for Sunday instead of Monday (even though the title said Monday), and hit a Cloudflare rate limit and failed to create the third one. We asked it to retry the failed one once, and it didn’t work. So I waited a bit and tried again. It claimed it worked. However, when I looked at the schedule, it wasn’t there.
We then asked it to fix the Sunday schedule and add the one it had missed again. It did add it that time. It also added the Monday meeting, but despite saying it would delete the Sunday one, it didn’t. I manually deleted it.
Installation is easy. You can connect a domain you own to Cloudflare or use the subdomain on pages.dev that they give you, which works fine. You run a single command on your computer. It handles authentication to the server and sets up all the services and data stores.
So essentially it is a to-do, reminder, and note-taking system. However, it does work well when it works. It can remember things and will find things it remembers or in notes very easily. Can you do that with non-AI tools? Of course. Not to mention, any of the “big” chatbots can do all of that and more. But not in your own hosted server account.
Besides, it is interesting that for small uses, Cloudflare offers plenty of free-tier compute resources that might come in handy for other projects. It is nice to have some free cloud-based computers, as we noted in a recent Linux Fu post where we used Oracle’s free servers.
Atomic clocks are super accurate. But, unsurprisingly, some atomic clocks are better than others, depending on your definition of better. Researchers at Vienna University claim to have a superior thorium-based atomic clock. It isn’t necessarily more accurate than other atomic clocks, but it is self-regulating.
Apparently, prior atomic clocks need help to stay stable. But scientists have thought that thorium, with its very narrow gap between two states, would make an excellent clock with the help of a laser. However, the laser has to have precise properties that, at least in early experiments, were provided by another nuclear clock.
Obviously, you’d like to be able to use a laser to excite the source — a thorium crystal in this case — and then use the output of that to adjust the laser. That’s apparently what the team has done. If the laser drifts, the thorium nuclei absorb less light, and that adjusts the output frequency to compensate. If you can follow the physics, you can read the source paper in Nature.
Optical atomic clocks are the way to go for time standards, but this research has promise to provide even more accurate results in the future.
You’ve probably heard of Mars Pathfinder, the NASA lander and its Sojourner rover that took up residence on Mars in 1997. At first, all was well, but after a few days, the lander suffered a series of total system resets. A watchdog timer detected a problem and forced reboots. [Vivek Bhageria’s] recent post looks into what happened and the eventual solution.
The root cause was priority inversion. This happens when a lower-priority task holds a resource needed by a higher-priority task and prevents the higher-priority task from executing. In this case, the operating system was VxWorks, but this can happen on any kind of priority scheduling system.
The simplified version is that there were two tasks that each used the same mutex to avoid stepping on each other. The highest priority was a data distribution task. The lowest priority task dealt with meteorology data processing. There was also a medium-priority task that handled bus maintenance.
The failure would occur when the low-priority task had the mutex and lost its time slot before releasing it. The high-priority task would then find it couldn’t take the mutex. However, the low-priority task didn’t get control again because of the medium-priority tasks waiting to run.
In effect, the high-priority task was now waiting on something that couldn’t become available until the lowest-priority task was able to run. That’s priority inversion.
Sadly, engineers noticed this happening occasionally during testing but, as we are often prone to do, they chalked it up to glitches. As one of our old bosses used to say: “If you don’t know why it happened, then you don’t know that it won’t happen again.”
VxWorks, of course, understands that this might happen and, luckily, there was enough capability on the spacecraft to turn priority inheritance on for the mutex in question. This allows the low-priority task to get a boost because a higher-priority task is waiting on it.
You can read more about the details in the post. We also covered this a decade ago with our own analysis.
Mechanical and prone to failure, switches can seem quaint these days. Plus, everyone is used to having touch screens on their phones and other devices. So why not use touch sensors on your next project? [Tarantula3] has details on using the TP223 instead of ordinary switches.
These inexpensive modules work through plastic, glass, or wood, opening up many interesting possibilities for building a front panel. Of course, the thicker the surface above the module, the less sensitive the switch is, but that’s not always a bad thing. In particular, you may want to reduce sensitivity anyway. Thicker panels, reducing the size of the touch pad, or adding an external capacitor can reduce the sensor’s range.
You may be worried about eating up batteries with a bunch of electronic switches. But according to [Tarantula3], the modules consume less than 2 microamps at rest. You can configure the modules with our favorite scripting language: solder. There are two jumpers, initially unsoldered, and this results in four possible states. By default, the output goes high when someone is touching the sensor and stays high until they release.
However, you can solder jumper A to invert the output. Jumper B causes the switch output to toggle on each press. Of course, you can also do both jumpers, which toggles but has the opposite default state. If you get false triggers, consider adding a small capacitor to filter the power supply to the module.
We imagine that electroplating is like making PC boards or soldering surface-mount chips. Before you’ve done it, it seems like a lot. Afterward, you can’t remember why it was such a big deal. [Kovancapol] wants to show you how to plate a mirror-finish nickel over your tools, and while it looks like a lot to set up, we are guessing that it gets easy once you have everything together.
There is a bit of chemical setup, as you might expect with reagents like nickel sulfate and nickel chloride. Then there’s the glassware, nickel anodes, and a power supply. As you can see in the video, the results look very nice. We can’t help but wonder what other uses you might have for this process.
A conductive coating on a 3D print might be feasible. We aren’t sure soldering PCB traces would be worth it since nickel gets hard to solder as it oxidizes. You can mix and match plating for some pretty impressive results.

 Login