❌

Reading view

There are new articles available, click to refresh the page.

Creating AI value with enterprise context

Across a business, any number of AI platforms, systems, and tools may be at work simultaneously—for example, AI-powered customer platforms, conversational assistants, and workflow and process automation tools. Each one is sophisticated, advanced, and quick to respond. But, when set to work, the outcomes and actions that emerge may be wrong, confused, or lacking a proper understanding of the business. Many organizations find themselves in this situation—and it could be one of key reasons they struggle to extract returns on their AI investments.

An MIT Technology Review Insights poll finds that while every organization surveyed is using AI today to some degree, fewer than one in five (16%) are extracting transformative value from their deployments. The largest percentage of respondents (40%) say they are seeing moderate gains in specific tasks or teams, while 21% report meaningful gains, leaving 23% that are seeing minimal returns or none at all.

Companies are mostly still piloting AI use cases (according to 38% of respondents) or using it to assist employees’ work with tools like co-pilots or chat assistants (35%). Just 12% of enterprises have AI agents in production and 3% say they are using AI to do most of the work in key processes.

“There’s a big gap between what the models are capable of and how the models are actually being useful inside organizations,” says Prukalpa Sankar, co-founder of Atlan. “For every real-life intent and purpose, artificial general intelligence is already here. It’s just not really useful in most companies today.”

The missing layer, Sankar says, is context, or how well AI understands a business. A context layer is the architectural infrastructure that sits between an organization’s business systems (for example, systems of record and data, and its AI platforms). It translates enterprise intelligence into governed, machine-usable context for AI agents or models and helps knowledge compound. “Without a context layer for AI, it’s almost like you’re hiring the smartest intern in the world, blindfolding them, and throwing them into your organization,” Sankar says.

Download the report

This content was produced by Insights, MIT Technology Review’s custom content arm, not its editorial staff. It was researched and written by humans, with any AI tools that may have been used limited to production processes under human oversight.

Industrial Intelligence: The next growth opportunity for manufacturing

Every manufacturer has its own industrial intelligence. Some is documented, and some resides in the knowledge of experienced workers.

Consider an experienced operator preparing to restart a line after a changeover. The machine settings matter, but so does knowing how a particular material behaves, what happened during the previous shift, and when an apparently minor variation deserves a closer look. A procedure can describe the sequence, but successful execution depends on the judgment that comes from experience and the organization’s accumulated know-how.

That combination is industrial intelligence: a manufacturer’s accumulated know-how, operating practices, production data, and understanding of its own business.

The opportunity now is to make more of that intelligence available wherever decisions are made, then connect it to the physical world of manufacturing. The strategic destination is not more agents, but rather to turn the existing business intelligence into an engine for profitable growth.

Individual knowledge can be translated into organizational advantage

Expertise has limited reach when it stays with one person, inside one system, or within one plant. Leaders now must determine how to extend that reach without stripping away the context that makes the knowledge useful.

For example, an engineer evaluating a process change needs more than a production record. They need to understand the circumstances behind it: the equipment configuration, the quality requirements, and the trade-offs an operator made. Connecting those elements can help people apply experience beyond the place where it originated.

When individual knowledge becomes widely accessible, innovation can spread to the maintenance workshop, the planning office, the engineering team, and the production floor. More people can contribute because more people can work with what the organization knows.

But access to knowledge is only part of the opportunity. Manufacturing ultimately is physical, and it depends on materials, machines, and products.

When intelligence participates in action

Physical AI describes systems that can perceive conditions, reason about them, and take action within the physical world. By connecting machines and processes, manufacturers get a clearer view of what is happening on the factory floor. Agents can then reason on top of that information to identify patterns, predict problems, and determine the best course of action. Physical AI brings business intelligence into the physical process, allowing machines and systems to respond to changing conditions.

Consider a robotic-handling operation encountering variation in the parts arriving at its station. Vision can help the system assess a part’s position. A model informed by the material and task can help determine an appropriate movement. Connected controls can then execute an adjustment within validated limits. The value is not merely seeing the variation; it is responding appropriately.

The same principle applies to quality operations. When Toyota Industries connected previously fragmented paint shop data, engineering and operations teams were given the context needed to understand defect drivers. The company reports that analysis cycles fell from five days to under four hours, while its pilot reduced relevant paint defects by about 25%. The breakthrough was not simply identifying another signal; it was helping people understand why defects were occurring and respond before the outcome was locked in.

This is the type of situation where industrial intelligence has become essential. Data may reveal what is happening, but industrial intelligence provides the context for what should happen, which constraints cannot be breached, and when uncertainty requires human judgment.

Simulation offers a way to examine proposed actions before applying them to equipment. Manufacturers can explore how a change might affect a process in a digital environment. That does not remove the need for physical validation, but it creates room to learn without treating the production line as the first experiment.

Responsible deployment, therefore, begins with operational discipline. Leaders need to establish clear authority or what systems may change, reliable connections to equipment, defined safety boundaries, and a record of decisions and actions. People must be able to recognize uncertainty, intervene, and bring equipment to a safe state. Trust rests on those practical arrangements, not on confidence in a model alone.

More capable machines, more capable people

Manufacturing has long combined human ingenuity with increasingly capable tools. Physical AI extends that relationship. Intelligent equipment can take on suitable repetitive or physically demanding tasks, while agent-assisted operations can help people navigate information-intensive decisions and changing conditions.

The aim is not to make machines smarter; it is to see what people can build when knowledge can travel, intelligence can act, and ambition has more room to become reality.

Rockwell Automation illustrates the point. At its Singapore plant, technicians use a maintenance copilot that combines manufacturing data, machine manuals, and knowledge captured from experienced workers. This system has reduced the time required for new workers to learn how to troubleshoot hundreds of machines from nine months to three. An engineer could explore more process alternatives before committing to a change. An operator could help improve the system’s response rather than repeatedly managing the same exception.

This type of progress requires investment in equipment but also in people: training, time to learn, and playing a meaningful role in shaping how systems work. Machines become more capable so people can become more capable.

Industrial Intelligence is the answer to sustainable growth

Industrial intelligence connects what a manufacturer knows: the experience of its people, the signals from its operations, and the lessons accumulated over time. Physical AI gives that intelligence a way to act in the physical world, turning knowledge into decisions and decisions into action.

The next challenge for industry is not simply to produce more, but to grow without adding complexity at the same rate. Intelligence can help manufacturers turn experience into scalable capability—improving productivity, accelerating innovation, expanding capacity, and enabling people to solve problems that were previously difficult to tackle.

The next frontier of industry is not smarter machines or more automated factories; it is businesses that can continuously learn, adapt, and act. The opportunity is to turn the intelligence embedded in every operation into a compounding advantage for growth.

Watch the video series to learn how industrial customers are unlocking intelligence across the value chain, and join Microsoft at Microsoft Ignite to see what’s next for Industrial Intelligence.

This content was produced by Microsoft. It was not written by MIT Technology Review’s editorial staff.


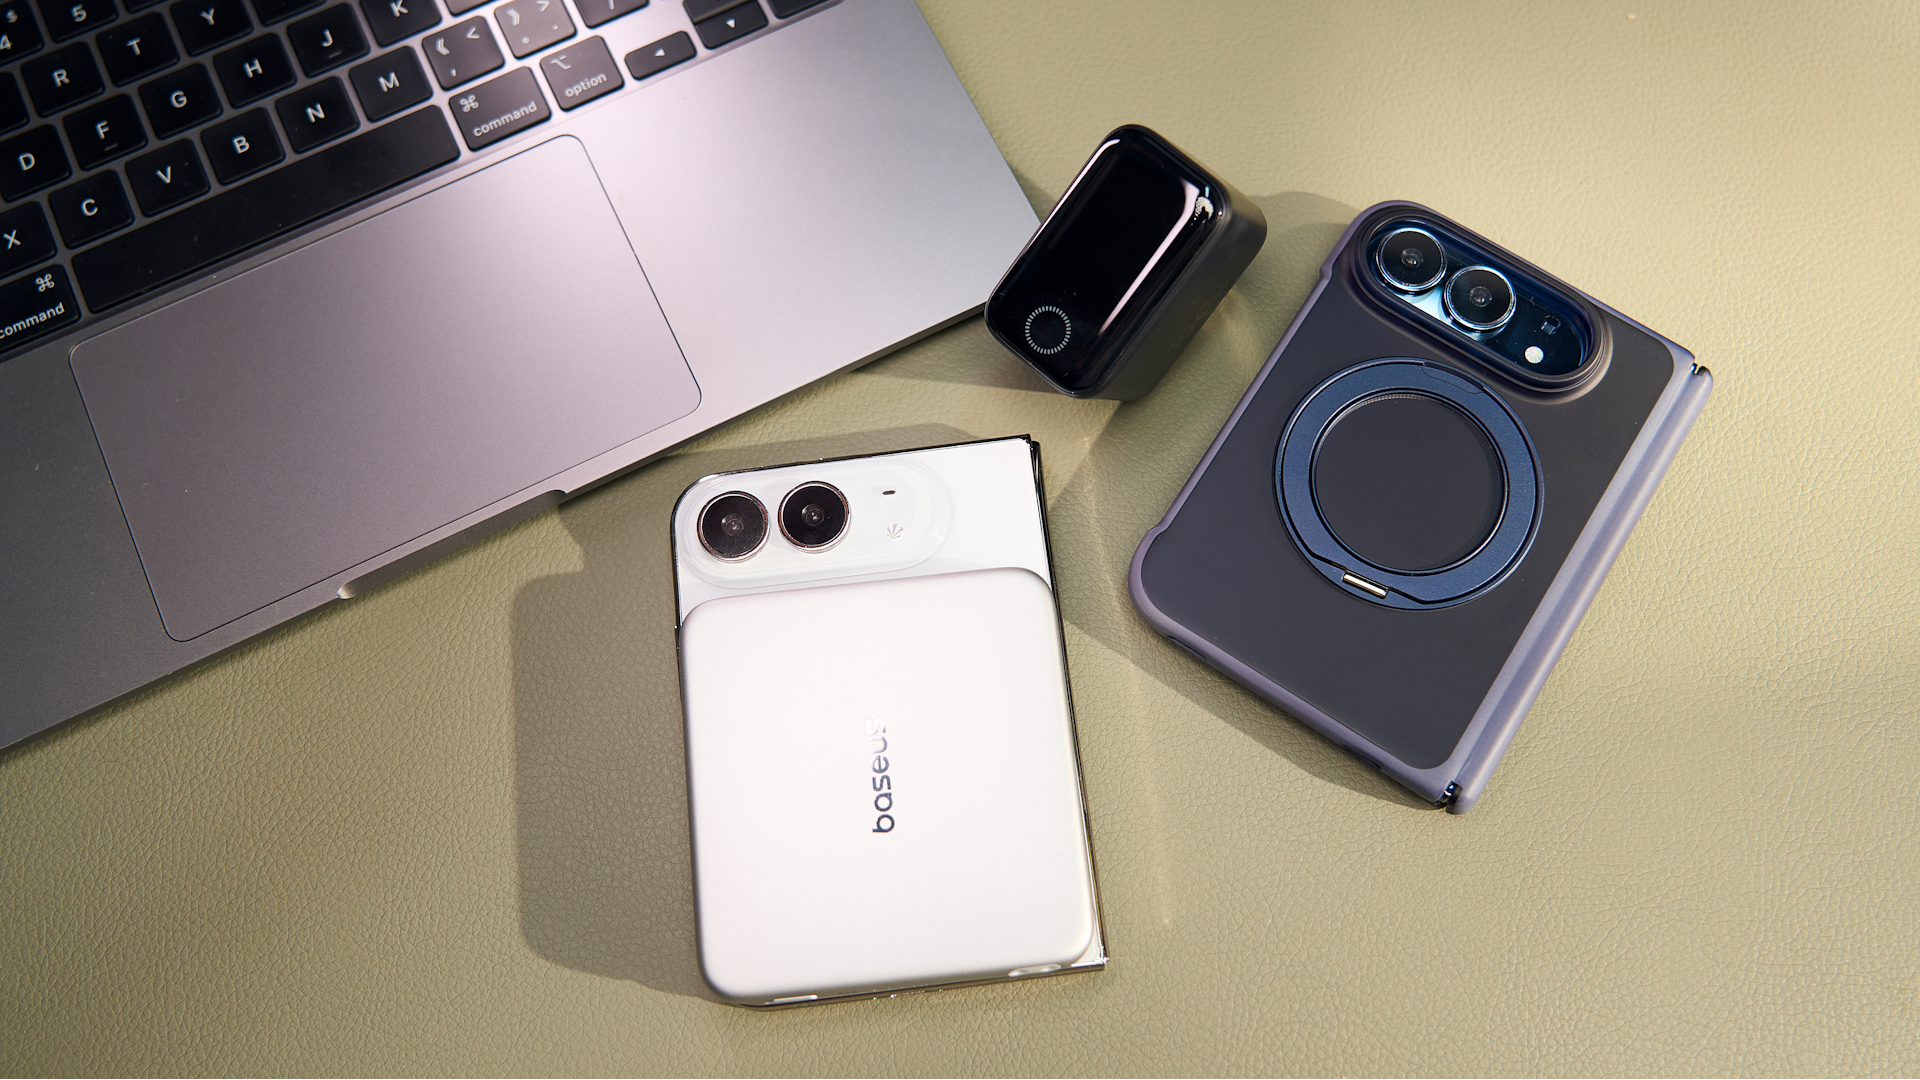
Charging a foldable iPhone is different. Here's what Baseus built for the iPhone Duo

Apple's first foldable, the iPhone Duo, opens up into a much bigger screen than any iPhone before it. That's the whole appeal. It also means the accessories you already own may not suit it as well as they did your last phone. A magnetic power bank shaped for a standard iPhone can sit awkwardly on a device with a different footprint, and anything chunky works against the slim profile that makes a foldable worth carrying in the first place.

Designing an AI serving harness built to last

The next competitive advantage in enterprise AI has less to do with which model you choose than with what you build around it.

That’s an important shift. For the past several years, much of the AI conversation has centered on model capability: bigger models, better reasoning, larger context windows, higher benchmark scores. Those advances have been extraordinary. But as AI moves from experimentation to production, the question facing enterprise leaders has changed—it’s no longer, “what can the model do?”—it’s now, “Can we deliver that intelligence reliably, economically, and at scale?”

Increasingly, the answer depends on the serving harness—the engineering system surrounding the model, including the architecture, memory management, scheduling, and optimization decisions that determine how efficiently model intelligence becomes a production capability.

For technical executives, that changes where AI investment should go—and what they should demand from the architecture supporting it.

Start with the workload, not the model

There is no universally “best” model or AI architecture. There is only the right solution for the business problem.

A customer-facing assistant optimized for fast responses has fundamentally different requirements from a document-processing pipeline that can run overnight. An internal knowledge application and a high-volume customer service platform may use the same foundation model but require very different serving architectures.

The workload defines the constraints. The constraints should determine the architecture.

That sounds simple, but it runs counter to the way many organizations have approached early AI deployments. During a proof of concept, model accuracy naturally dominates the discussion. Production introduces constraints that are much easier to ignore when only a handful of users are involved: latency, concurrency, memory pressure, GPU utilization, infrastructure cost, and unpredictable traffic.

A model that produces marginally better answers is not necessarily the better production choice if it doubles inference costs or cannot meet the application’s latency requirements. Not every workload needs a Ferrari. Sometimes the smarter engineering decision is the model that delivers exactly the performance the business needs without paying for capability it doesn’t.

The objective should be to deploy the right intelligence at the right cost for the workload. That makes serving architecture more than an engineering concern. It becomes an investment decision: where to spend on compute, where to optimize, and where additional model capability simply isn’t worth the cost.

Engineer the system, not the model

Once AI reaches production, seemingly isolated engineering decisions begin affecting one another. Serving architecture influences memory utilization. Memory management affects concurrency. Concurrency shapes batching and scheduling, and scheduling affects GPU utilization and latency.

Only then can techniques such as quantization, speculative decoding, or optimized attention mechanisms deliver their full value. This interdependence matters because organizations can spend considerably more on infrastructure without solving the constraint limiting performance.

GPU memory is a good example. During inference, the model’s weights remain fixed, but the key-value (KV) cache grows with active requests and context length. As concurrency increases, a system can run short of usable GPU memory even when compute capacity is still available. Adding more compute without understanding that bottleneck may simply make an inefficient system more expensive.

The lesson for technology leaders is broader than memory management: Measure before you optimize. Identify the dominant constraint. Address it. Measure the result. Then determine if another bottleneck emerged. Repeat.

Don’t think of optimization techniques as Pokémon cards: The goal isn’t to collect them all. The goal is to apply the technique that removes the highest-impact constraint while preserving the application’s business requirements.

For technology leaders, that demands a different governance question. Instead of asking which AI capabilities the organization can deploy, ask which constraints stand between a proven capability and sustainable business value.

Build for change, not today’s benchmark

Perhaps the most important reason to invest in the serving harness is that today’s leading model will probably not be tomorrow’s. Models will improve. Hardware will evolve. New optimization techniques will emerge. The architecture surrounding them should make those changes easier to absorb, not force the enterprise to rebuild its AI platform every time technology advances.

That makes adaptability an increasingly important outcome of AI strategy.

Organizations that build serving systems around workload requirements, clear service-level objectives, and measurable production economics gain the ability to evaluate new models and infrastructure against what the business actually needs. A model change can become an evaluation and configuration decision rather than an architectural reset.

EXL researchers have explored these production challenges in greater depth in the EXL Engineering the Harness series. It examines how serving architecture, memory management, scheduling, and inference optimization work together to make enterprise AI more efficient, scalable, and economically sustainable.

Increasingly, enterprises have access to many of the same models. Sustainable differentiation comes from how effectively an organization turns that intelligence into business outcomes.

The model provides the intelligence. The harness determines whether the enterprise can deliver outcomes reliably, economically, and at scale.

This content was produced by EXL. It was not written by MIT Technology Review’s editorial staff.

The Foundations of Scalable AI

A scalable AI system requires a strong foundation. Data, engineering, platforms, operating models, and governance must converge to work as one. This session from MIT Technology Review’s EmTech Future conference explores what it takes to build that foundation in a highly regulated environment and how a responsible, trustworthy implementation can turn emerging capabilities, including agentic systems, into lasting value for investors.


About the speaker

Jing Wang, Principal, Center for AI and Insights, Vanguard

Jing Wang leads Vanguard’s Center for AI & Insights (CAI), advancing the firm’s AI, machine learning, generative AI, and behavioral science capabilities. Her team drives enterprise-wide innovation, research, and delivery, enabling Vanguard to translate emerging technologies into trusted solutions that enhance client experiences, improve investor outcomes, and create measurable business value.

Before her current position, Jing served in a range of leadership roles across Vanguard’s Financial Services, Workplace Solutions, International, and Corporate Services divisions. Throughout her tenure, she has led teams and enterprise initiatives that advanced strategic priorities, strengthened client outcomes, and drove business performance across the firm.

She joined Vanguard in 2009 after several years as a Principal at the Boston Consulting Group. Jing earned a B.S. in Physics from the University of Science and Technology of China, a Ph.D. from the University of Pennsylvania, and an M.B.A. in Finance and Marketing from the Wharton School of Business at the University of Pennsylvania. Jing holds Series 7, 24, and 65 licenses.

Hand off your post-meeting work to the Comu Action Pro

Add up the hours you spend in meetings each week, then add up the time you spend dealing with them afterwards. For many people in sales and consulting, those two numbers are uncomfortably close. You need to tidy notes, update the CRM, send a follow-up email while the conversation is still fresh, and get any deadlines on your calendar before they slip your mind.

Making the case for context-aware AI

Enterprise AI can generate recommendations, automate tasks, and help organizations make decisions faster. But without an understanding of how a business actually operates, even powerful models can miss the constraints and relationships that determine whether a decision is the right one. As companies look to move AI from experimentation into everyday operations, the challenge ahead is giving technology the context to act usefully within complex business processes.

For Devavrat Shah, chief scientist of enterprise AI at Celonis, that context is central to what he calls “decision intelligence.” AI agents can support individual tasks within larger decision-making processes, he argues, but they need to understand the role each task plays and the business conditions surrounding it. “You can’t just do that in a vacuum,” he says. Without the right operational context, agents risk overlooking important constraints, making costly mistakes, or consuming excessive computing resources as they try to work out what they need to know.

The solution begins with connecting AI to the processes and data enterprises already use. A contextual layer can help agents understand workflows, operate within defined guardrails, and produce recommendations that people can review and approve. Shah advises organizations to start with a specific business decision, identify its most difficult steps, and test whether AI can improve them. Measuring gains in speed and value can then help determine whether an application is worth scaling.

This approach could also change how employees spend their time. Automating repetitive, manual work and coordinating tasks across teams could free people to focus on more complex strategic decisions. Realizing that benefit, however, will require investment in workforce education, so employees can understand AI outputs and their implications instead of just handing decisions over to agents.

Looking to the future, Shah sees opportunities extending from routine operational tasks to enterprise-wide planning in areas such as finance, workforce management, marketing, and sales. With the right context, AI could help organizations evaluate options and make consequential decisions more quickly. As Shah puts it, “Now, maybe [resource planning] should not take that much time, and people are actually making the right choices quickly.”

This episode of Business Lab is produced in partnership with Celonis.

Full Transcript

Megan Tatum: From MIT Technology Review, I’m Megan Tatum, and this is Business Lab, the show that helps business leaders make sense of new technologies coming out of the lab and into the marketplace.

This podcast is produced in partnership with Celonis.

Now, enterprise AI is at something of a crossroads. After years of experimentation, demos, and pilots, leadership teams want clear proof that scaling up will positively impact their bottom line, but many are missing an integral part of the puzzle. By acting without operational context, enterprise AI and AI agents are performing at a significant deficit. They’re applying generalized principles to specialized scenarios and coming up short, leaving business leaders understandably unconvinced and AI’s potential unrealized.

Two words for you: context matters.

My guest today is Devavrat Shah, chief scientist of enterprise AI at Celonis.

Welcome, Devavrat.

Devavrat Shah: Hello, Megan. Thanks for having me here.

Megan: Thank you so much for being here with us today. Devavrat, just to start, why is it so crucial that organizations are thinking about operational context as it relates to enterprise AI right now? What makes it such a critical part of that transition I was talking about from experimentation to scale?

Devavrat: It’s a fantastic question. And as you correctly noted, we’re at the cusp of becoming experimental to mainstream as far as AI is concerned. As you know, I’ve been teaching AI at MIT as a professor for more than the last two decades, so it’s no surprise that I’m very bullish about AI’s future in enterprises.

The way I think about where AI can make the biggest difference in enterprises is in decision making, helping enterprise make decisions, or putting it other way, how do we bring decision intelligence to enterprises? As we think about decisions, how do we make decisions today? Take MIT Tech Review, take Celonis, take MIT, take any large organization. We have different types of decisions we want to make in very broad strokes. There are decisions which are strategic decisions like episodic, other decisions which are operational that need to be done with a high frequency. In either of them, we have some processes in place. You do this first, you do that first, you do that first, you do that first. Many of us help coordinate those things. Many of us play roles within it, what Jensen Huang calls task. And once you get those things done step by step, then you reach decision.

Now, it’s those tasks, or what I would call roles, that’s where AI can bring in an atomic manner agentic power so that we can at least parts of decisions, if not all of the decisions, we can augment support and maybe sometimes when it’s a painful automate. And to get to that, to know which role to do, which task to do, we really need to know the context. You can’t just do that in a vacuum. And that’s why context with AI put together in the right way would bring what I would call decision intelligence to enterprise. And that’s where I think there’ll be the biggest transformation that would come.

Megan: Right. To drill down into that into a bit more detail, we know many organizations are, as you say, embracing identic AI right now with this potential for increasingly autonomous decision making. If context isn’t introduced in parallel, what are the commercial risks at play?

Devavrat: Fantastic. Let’s just take the setting I was describing. We are trying to automate a role or support a role or augment a role depending on the type of decision, depending upon type of task. And let’s for a second imagine that all these, as they’re called, frontier labs have built these amazing models and amazing AI infrastructure so that everything that’s happened in the universe and it’s likely to happen in the universe is all there.

Now, we have a small decision that we want to make for that very specific context is there. And without having access to that, this massive system, this extremely bright person would figure that out eventually by asking lots of questions, the way we do it as humans, and then finally do the right thing. The problem is to get to that, it will do so much compute at some level that to get simple tasks done, we are spending massive amount of compute. So that’s scenario one.

In reality, that’s not going to be the scenario, and we’ll miss some important context, important constraint, important guardrail, and then we’ll make a mistake. And sometimes that mistake can be okay. It’s like me giving you a recommendation saying, go restaurant A, and maybe you may not enjoy the dinner, versus sometimes mistakes will be very, very expensive. That is me telling you what the financial forecast is and somehow that leads to the company’s doom.

Megan: Right. So in an enterprise setting, these are really business critical decisions that are being made. So the impact is that much more if we get this wrong, isn’t it? And on a practical level then, what are the different ways that organizations can add in this context layer we’re talking about? How does Celonis, for example, deliver that operational context via a real time digital twin of an organization?

Devavrat: Absolutely. I think if it might be useful just to double click on the history of Celonis. As you know, Celonis, as an organization, came into existence with the mission, with the goal of helping organizations adhere to their ideal processes, build better processes, enable people to work with multiple processes in an intertwined manner. And that’s where their primary, let’s call it a DNA, has been about what I would call process intelligence. Take how enterprises help put multiple things together, digitize them, enable people to get their processes better, understand where the issues are, and then how do you re-engineer the process within organizations so that things can happen better.

Now, if you want to bring decision intelligence into this, each atomic step of this process that was potentially was done before by experts, people, now we want agents to help us enable that. And that’s where knowing this context of a process within enterprise and then bringing AI agents along with that, what I would like to call it as a roled agents, exactly provide the right way to bring decision intelligence to enterprises. And this is how Celonis brings context to help enterprise make better decision.

Megan: Right. And then in terms of how this works as well, how does the context layer relate to both the layer below, that’s the systems of record layer, and also the layer above, that identic layer?

Devavrat: That’s a fantastic question, Megan. The layer below primarily is, if we call it system of record, primarily it’s the workflow tools that are there and then the event logs that they generate around it. The layer above is either business user experts consuming information, or they’re consuming that information maybe through agents working on top of that context layer. And this is where the way context model, as Celonis calls it, is designed is to do three things simultaneously. One is to get the right abstraction of the layer below, so that the right pieces of the process can be agentified. Two is to bring the rolled agents for each of these pieces in a structured guardrailed manner. And then the three is to be agent first so that if there are other agentic infrastructure that are already talking to it, they can naturally talk to it so that then they can bring the right output for humans or experts to review, look at it, approve, and maybe then at times automate.

Megan: Fantastic. And for all the benefits that we’re talking about with this, are there also challenges when it comes to implementing a context layer? For example, do most organizations have the right data in place to provide AI with the context it needs? And if not, I wonder what some of the practical steps are that they might need to take to address that.

Devavrat: It’s again, a crucial question to make this real. We can imagine an ideal world, but if we cannot reach the ideal world, then it’s just ideal. So now in this setting, as we discussed the three layers, one being the layer which is the layer below system of record and workflow tools. In some sense, those things already exist. They don’t need to be complete. They don’t need to be in the cleanest possible manner. The way context model is designed with agentic’s architecture, it manages to connect to those things and make sense of it.

And then things on top is very much in control of Celonis’s infrastructure, so it’s not that complicated. The crucial thing here though is when one goes to enterprise, when one opens up, let’s say a system of record or workflow tool, event logs or things like that, one has to go through, what I would call, classical InfoSec to make sure that you can trust a vendor’s software that’s coming into your organization. And I think that is the primary process that is a step between, before and after, if I may call it.

Megan: Right. So that’s the real crucial step for people to be taking here. And as AI agents with context are able to make more complex, more accurate hopefully decisions, I wonder what you think the role of human intelligence and input will be moving forward, and how can organizations perhaps strike the balance between the two?

Devavrat: There are the benefits and then there are the challenges. Benefits are clear. If you have right AI agents in a right role manner going through your decision processes, hopefully they’re doing it quicker and hence your decisions are taken earlier so that your opportunity cost is not lost. You are taking decisions in time, you can plan much better, et cetera, et cetera. This is especially useful when you have to take very manual, repetitive, grungy tasks where access to workforce, coordination between people become crucial parts of the decision process. In a sense, that’s where the huge value can come in. The flip side of that is that means that people won’t be doing that.

On the other hand, the other type of decision that we always make, which are strategic decisions. It could be a small strategic decision, it could be large strategic decision, but the strategic decisions that typically most organizations don’t have bandwidth to take to think, that opportunity would open up and that’s where likely lots of humans and experts would engage more. In a sense, now they would have better support helping them rationally think through what are the choices that they have, how do different choices compare? And then at the end of the day, it’s organization’s role to decide which of the option to take because it belongs to their interest in mind where they want to go.

And so in a sense, there will be what I would call shift of workforce in terms of instead of doing a lot more repetitive, a lot less repetitive, but a lot more strategic work and that’s where people will have to spend time.

The other place where I am personally very optimistic is like every technology change creates new work that it’s difficult to predict at the time of change. My hope is that there will be another type of opportunity and work that will be created where we’ll be engaging our workforce. Goes without saying, this would mean that we will have to carefully think through reeducating or educating some of our workforce thoughtfully. And I think as an academic in me, as an educator in me, I really feel that the timescale at which these changes are happening are so fast. So we need to also act in a similar manner.

Megan: For any decision maker listening to this, how should they start implementing these changes? For example, how can they prepare their workforce? What role should governance play as well?

Devavrat: Okay, that’s a great question. If you want to start, the first thing you need to do is identify a decision where you want to bring intelligence. Let’s identify the process around it. Let’s identify each step of the process. Let’s take the most crucial, difficult step in that. Let’s try to bring AI agents to help you to do that. And then from there you go and then let’s measure how much speed are we getting, how much value are we getting? And that’ll help us understand whether this was worth it. So that’s one.

Second is governance. Well, we’re going to bring AI in this prescriptive manner for each task in a role. That means that for that role, we can tell what it can or cannot do very clearly. And Celonis prescribes certified role agents for these things. This helps you clearly have an understanding of what sort of contract would be for this.

And the third thing, which is people, and now this is where it’s really important, is a part which gets automated, but then there’s a part where experts will be in the loop and this is where they need to understand the outputs of AI, how do you work with that and what its implication would be? And this is where some AI education is needed and then some tool education is needed.

Megan: Yes, absolutely. The pace is incredible, isn’t it, in this space? And speaking of, I suppose if we could close with a look ahead, given the right context, of course, what are the use cases perhaps for enterprise AI that are on the horizon that you think could be most impactful or perhaps what you’re simply most excited about?

Devavrat: I think I would categorize them into three types. They’re all decision intelligence, decision-making, but there are three types. One, what I would call many repetitive manual labor-intensive, so that’s one.

Two, what I would call coordination style tasks. A lot of work that we do right now as an information workforce that’s spent in coordination, that’s why email spreadsheets, et cetera. A lot of that would be done much better, much quicker and less boring, so to speak.

And then the third is where, especially as a support to human decision-makers to provide strategic support augmentation, and that’s a third type of decisions that would be done. If I think of any planning process in enterprises, so financial planning, workforce planning, marketing, sales, product, anything, all of those are business critical decisions that we make that take annual planning process, take annual time. Now maybe it should not take that much time, and people are actually making the right choices quickly.

Megan: That’d be fantastic, wouldn’t it? Fantastic. Thank you so much for that brilliant conversation, Devavrat. That was Devavrat Shah, chief scientist of enterprise AI at Celonis, whom I spoke with from Brighton in England.

That’s it for this episode of Business Lab. I’m your host, Megan Tatum. I’m a contributing editor and host for Insights, the custom publishing division of MIT Technology Review. We were founded in 1899 at the Massachusetts Institute of Technology, and you can find us in print, on the web, and at events each year around the world. For more information about us and the show, please check out our website at technologyreview.com.

This show is available wherever you get your podcasts. And if you enjoyed this episode, we hope you’ll take a moment to rate and review us. Business Lab is a production of MIT Technology Review, and this episode was produced by Giro Studios. Thanks so much for listening. Goodbye.

This content was produced by Insights, MIT Technology Review’s custom content arm, not its editorial staff. It was researched and written by humans, with any AI tools that may have been used limited to production processes under human oversight.

AI’s hidden storage bill: What inference leaves behind

Ask most executives to picture the cost of AI and they’ll likely see GPUs—racks of accelerators with gigawatts of power—and a waitlist for silicon. But that picture leaves something out: Data storage costs.

What happens to data after a model responds? Much of the back-end data that’s generated—from billions of daily prompts, images, and videos—needs to be stored. But data storage is one of the harder infrastructure costs to plan for, and it’s often overlooked in initial AI infrastructure planning.

As inference scales, the data footprint grows with it

Traditionally, AI infrastructure conversations have centered on the compute-intensive process of training a model. Training is finite: a run starts, burns through compute, and ends. But inference runs continuously, every time a model answers a prompt. For infrastructure planning, that difference matters: A training run is a project you can budget for and retire. Inference doesn’t retire; every inference request leaves something behind.

Take AI-generated video. In this workload, the back-end spend can be significant. From internal measurements, WD found that an 8-second clip (returned to a user as a 3.97MB 720p file) left more than 500MB of associated data behind on the back end, including logs, cached context, immediate renders, backups, and safety records. That’s a 130x increase over the output file size the user saw. Scale this to an enterprise generating longer, higher resolution video and the back-end footprint grows into the hundreds of gigabytes per clip.

And that back-end footprint is growing fast. McKinsey projects AI inference demand will grow at a 35% CAGR through 2030, versus 22% for training, making up more than 40% of total data center demand by the end of the decade.

A recent WD-sponsored IDC global white paper that surveyed 763 IT and business decision makers found that nearly 95% of respondents reported an increase in data volume due to generative AI over the past 12 months, with roughly 61% reporting growth of 25% or more.

“You can think of having more storage as an optimization for keeping the GPUs busy,” said a senior product manager of a hyperscale cloud service provider quoted in report. “The biggest challenge is to ensure that the GPUs are not idle, waiting for data to show up—hours of GPU idle time becomes very expensive, very fast.” Put in dollar terms: if your storage spend is growing 25% year over year while your compute budget grows in the more predictable cyclical way, storage ends up outpacing the budget line that receives the most attention.

Matching storage to the AI data life cycle

Compute demand rises and falls with training cycles, product launches, and hardware refreshes. But the volume of retained data doesn’t fall back down with it when compute demand slows. Model logs, synthetic outputs, inference results, and more keep accumulating, and organizations are holding onto more of it for longer.

This changes the role of retained data. Information that once moved into an archive and rarely surfaced can now become an input to future AI workloads. As more data is retained, retrieved, and reused, storage must support not only growing capacity, but increasingly dynamic access to it. The same WD-IDC survey found 96% of respondents anticipate needing faster archive retrieval to support inference or retrieval-augmented generation (RAG).

AI workloads require both performance and capacity, with different technologies serving different needs across the data lifecycle. And for the vast volumes of data that must be retained and revisited, HDDs provide a cost-effective, high-capacity foundation, with a significant cost-per-terabyte advantage  

What this means for how AI gets budgeted

For a CFO or CIO, this means “AI infrastructure spend” may be scoped too narrowly on compute. A model that idles while data loads costs about as much as one idling for lack of a GPU. But the storage bottleneck stays hidden until it’s already a problem, surfacing in operating costs and retrieval delays rather than a CapEx line next to the accelerators.

Consider a retailer generating AI product videos for its catalog, or an insurer running claims documents through a RAG pipeline for faster underwriting. In both cases, the compute cost is a known, budgeted quantity: a per-generation or per-query rate that finance can forecast. The storage cost is different: It compounds with every video generated and every claim processed, because none of that back-end data disappears once the task is finished.

A team that budgets AI as “compute plus a rounding error for storage” may find, in 12 to 18 months, that the rounding error has become a significant fraction of the program’s total cost—right around the time leadership is deciding whether to expand.

Building for economically scalable capacity

Addressing this challenge starts with architecture. Storage strategy tends to be designed for expensive, hot-tier performance (for data accessed instantly and constantly), while most AI data by volume accumulates in the warm, cool, and cold tiers behind it.

What enterprises need is economically scalable capacity: Infrastructure designed for the full AI data life cycle, balancing performance with capacity, power, reliability, and total cost of ownership as data persists, compounds, and is increasingly reused. That means treating archives that once sat untouched as active assets for RAG and inference, and setting retention policies for data’s growing strategic value rather than its original storage cost. It also means recognizing that decisions about storage play out across fleets, not individual drives.

Such infrastructure requires storage tiers, where individualized power consumption, reliability, density, and operational efficiency all determine whether the system remains economically sustainable as capacity scales.

There are three questions to ask about your organization’s AI infrastructure budget:

  1. What’s our data retention policy for AI-generated content, and who set(s) it?
  2. Is our storage procurement tied to training-time performance needs, or to the actual life cycle of the data we’re producing?
  3. If our AI usage doubled next year, would our storage cost double with it, or worse?

Most organizations cannot answer all three with confidence. That’s the gap worth closing before the next budget cycle, not after.

This content was produced by WD. It was not written by MIT Technology Review’s editorial staff.

The new economics of enterprise AI

Imagine your company just discovered electricity. At first only a few machines run on it, and nobody worries about efficiency — consumption is low and the value is obvious. But once electricity becomes infrastructure, every process depends on it, and the question changes from “can we use it?” to “how efficiently are we using it?”

Enterprise AI is going through the same shift. What began as isolated chatbot and copilot experiments is becoming a foundational layer of the business, with models, agents, and data increasingly interconnected in production workloads. The important question stops being what a token or GPU-hour costs. It becomes how efficiently the AI environment converts paid capacity into useful business outcomes.

That’s the metric worth tracking: effective cost per useful outcome — the total platform, model, operations, and capacity cost required to complete work the business can actually use, whether a resolved request or a completed workflow.

Three ways to run AI

Utilization is central to the economics. Directing more work to paid-for capacity lowers effective unit cost; idle GPUs, fragmented workloads, and oversized models all raise the cost of every useful result. Enterprises generally choose among three models:

A bespoke stack — procuring infrastructure and controls in-house. This approach is flexible, but it creates a continuing burden, since teams must revalidate the environment as models and policies change.

On-demand consumption — hyperscalers reduce the assembly burden and suit low or uncertain demand, but charges rise with every prompt or agent action.

An integrated private AI platform — owned or dedicated capacity paired with a validated stack. The advantage isn’t free inference; it’s control over efficiency levers like scheduling, model selection, GPU partitioning, and cache management.

The right model depends on the workload. APIs can be rational for experimentation or variable demand. As workloads become sustained and business-critical, enterprises need to weigh not just what they consume, but how efficiently they operate the system.

Ownership is an operating discipline

Buying a Formula 1 race car and parking it in your garage means owning one of the most sophisticated vehicles ever built — but ownership alone doesn’t make you competitive; you still need drivers, mechanics, and track time to justify it. AI infrastructure works the same way.

One of the biggest misconceptions in enterprise AI is that owning infrastructure automatically improves economics. Owning GPUs creates the opportunity for better economics, but only if the organization has sufficient demand and operational discipline to keep resources productive.

The infrastructure that returns the best ROI isn’t a reference architecture or a bespoke build-out — it’s a fully integrated, qualified stack that lets teams route tasks to the least costly model that meets quality requirements and reuse context through techniques such as KV-cache management, reducing wasted capacity while maintaining responsiveness.

Without these practices, committed infrastructure can become stranded capital. With them, rising demand improves economics as fixed costs are amortized across more useful work — increasingly important in agentic systems, where economics are shaped less by any single prompt than by the efficiency of the complete environment.

From deployment to value

HPE Private Cloud AI is a production-ready foundation combining infrastructure, software, models, tools, governance, and services, reducing the integration burden of operating private AI at scale. Its architecture lets teams manage scheduling, model selection, GPU partitioning, and cache management as operational levers, aligning capacity and service levels with each workload’s requirements. It also includes a 90-day engagement with forward-deployed engineers who help customer teams deploy initial use cases and establish repeatable operating practices.

In independent testing commissioned by HPE, an integrated platform serving multiple workloads at high utilization delivered a lower effective cost per token than repeatedly renting equivalent capacity. Actual results will vary based on workload mix and utilization.

Measure what matters

Token consumption remains useful, but it isn’t a complete measure of AI economics. A fuller enterprise view tracks cost per business-relevant outcome, accelerator utilization, and model choice relative to task complexity.

Enterprises already operating private AI should ask how mature their utilization is, and how workload volume will change over the next 12 to 18 months. Those earlier in the journey should build these practices in from the first deployment, so strategy anticipates growth before demand becomes a bottleneck.

For low-volume, unpredictable demand, an API or hyperscaler may remain sensible. But as AI becomes a continuous production capability, enterprises have a growing incentive to control utilization, amortize fixed costs, and manage the environment as a long-term operating asset. The strategic question isn’t whether enterprises will pay for AI — it’s whether they will understand, and ultimately own, the economics behind it.

To learn more about HPE Private Cloud AI, please visit HPE.

This content was produced by HPE. It was not written by MIT Technology Review’s editorial staff.

AI adoption by industry shows what other sectors can learn

The current narrative around artificial intelligence in the workplace is largely driven by Silicon Valley. But treating the tech sector as an island misses the actual trends in technology adoption–tech is just the first industry in line.

As generative AI and automation tools mature, the shifts currently reshaping software engineering and product management will inevitably filter into healthcare, education, retail, and manufacturing. The variation in adoption rates today isn’t a sign that non-tech industries are falling behind, but rather a reflection of the different speeds at which industries absorb new workflows. For leaders and their teams outside of tech, this differential pace provides a practical blueprint for how AI adoption unfolds, and where the opportunities lie.

The AI adoption spectrum by industry

Recent survey data from TripleTen highlights just how stark the current adoption curve is across different sectors of the economy (see Figure 1).

Figure 1: The AI adoption curve remains steep across industries, but non-tech industry adoption rates are increasing.

Source: TripleTen, 2026

While tech leads the way, finance emerges as a clear second: 48% of finance workers have been asked to use AI chatbots, and 32% have been asked to automate parts of their workflow. This demonstrates how rapidly knowledge work integrates AI once clear use cases emerge.

By contrast, sectors like healthcare (18% asked to use chatbots) and education (25%) reflect lower initial exposure. Because these broad industry categories encompass a mix of specialized hands-on professionals, clinical or instructional personnel, and back-office administrative staff, universal adoption was never going to happen overnight. Integrating automated tools into compliance-heavy or human-facing operations requires a more deliberate pace, which is reflected by the lower numbers.

The AI skills workers are being asked to learn

Across all surveyed industries, 79% of workers report being asked to learn at least one skill they didn’t previously have. Looking at the specific competencies demanded in tech today offers a preview of the skill sets likely to shift into other sectors (see Figure 2).

Figure 2: Workforces across industries are learning new skills.

Source: TripleTen, 2026

Although some of these sound like niche skills confined to tech, many of them will translate to frontline work across sectors—from hospital systems managing patient logistics to school districts processing administrative reporting.

One skill gets less attention than it should. Only 30% of managers and owners call judging whether AI output is right or wrong an absolute must, which puts it sixth on a list of seven. As AI tools reach more industries, this is the skill that catches mistakes before they cause problems. It is also where work experience helps most: To spot a wrong answer, you need to know what the right one looks like.

How early AI adoption helps your career

Early AI adoption offers clear professional leverage: TripleTen’s survey data shows that when managers learned a new skill or automation process from an employee, 88% of those employee-led AI innovations became standard company practice.

In early-adopting industries, employees who identify repetitive administrative tasks and use AI tools to streamline them have a voice in shaping organizational policy. As healthcare networks, educational institutions, and retail operations begin broader rollouts of AI-enabled software, workers who understand how to validate outputs, prompt models, and automate routine tasks will hold a strong advantage. Being the person who can streamline administrative overhead promises better chances for retention, promotions, and wage growth.

Ana Riabova, the AI strategy and enablement lead at TripleTen, says, “Everyone talks about saving time, but the real win with early adoption is expanding what you can actually do. People who get ahead are using it to handle things they used to have to hand off. It doesn’t matter how senior or junior you are. You keep your core skills, but suddenly you aren’t boxed in by them anymore.”

The AI resource gap: Who pays for training and how workers learn

If non-tech industries absorb these tools more gradually, the challenge for workers lies in getting access to quality learning resources. Workers’ out-of-pocket investment in training varies significantly by industry:

  • Tech: $1,758 average (13% spent $0)
  • Finance: $1,664 average (24% spent $0)
  • Healthcare: $990 average (45% spent $0)
  • Education: $883 average (42% spent $0)

Nearly half of healthcare and education workers spent nothing out of pocket on professional development last year. Furthermore, tech workers actively leverage a larger variety of learning channels (see Figure 3).

Figure 3: Professional development efforts mirror the AI adoption curve.

Source: TripleTen, 2026

Tech workers are nearly twice as likely as all workers to use AI chatbots as learning tools (48% vs. 27%), and more than twice as likely as workers outside tech (21%), effectively using AI to accelerate their acquisition of other skills.

However, ask workers whom they trust most to teach them a new job skill, and they choose someone currently doing that job (31%). Fewer pick an official certification program (19%), an AI tool (16%), or a university professor (6%).

Conclusion

The difference in AI adoption rates across industries is not a story of who is succeeding and who is failing. Rather, it’s a timeline of how technology diffuses through an economy. Tech and finance are testing the mechanics of AI integration today. For workers in healthcare, education, retail, and manufacturing, the current phase provides a valuable window to observe which skills generate real productivity gains—allowing them to build those competencies before they become standard industry expectations.

This content was produced by TripleTen. It was not written by MIT Technology Review’s editorial staff.

AI breakthroughs in robotics won’t change your life any time soon

The story is a collaboration between MIT Technology Review and Aventine, a non-profit research foundation that creates and supports content about how technology and science are changing the way we live.

A robot shaped like a human—white with a black head and torso—has been popping up on video feeds. Perhaps you’ve seen it dance or pass popcorn, put trash in a bin, vacuum, or press the button of a microwave. Or maybe you’ve watched it fall backward while handing out water bottles or struggle to iron a shirt. 

This would be Tesla’s Optimus, an AI-powered humanoid robot that Elon Musk, the company’s CEO, believes will be “not just Tesla’s biggest product ever, but probably the biggest product ever,” headed to work on factory floors and, later, in our homes. Eventually it “will have human and then superhuman dexterity,” he told shareholders in July. Optimus robots could automate almost all human labor—from hauling sheet metal to folding laundry—for as little as $20,000 each, Musk argues. Speaking at the World Economic Forum’s annual meeting in Davos, Switzerland, in January, he predicted they could be on sale to the public by the end of 2027.

Musk is not alone in his evangelism. Marc Andreessen, cofounder and general partner of the Silicon Valley venture capital firm Andreessen Horowitz, has said that robotics could become the “biggest industry in the history of the planet.” In January, Jensen Huang, CEO of Nvidia, said that humanoid robots would match human-level ability this year. According to Morgan Stanley, the number of robots that “resemble and act like humans” is likely to reach nearly 1 billion by 2050, creating a market worth over $5 trillion. 

Elon Musk predicts that Tesla’s Optimus humanoid could be one the world’s best-selling products. For now, it’s most often seen handing out food and drinks at Tesla events.
SIPA VIA AP IMAGES

Such proclamations are in large part fueled by the idea that the same AI advances behind tools like OpenAI’s ChatGPT and Anthropic’s Claude will enable a new generation of robots to imitate human movement the way chatbots imitate human language. But many robotics researchers are skeptical, arguing that such assumptions minimize the challenges of using an intelligence built on language and images to master the infinite variability of the physical world. “None of those companies [building humanoid robots]—absolutely none of them—has any idea how to make those robots smart enough to be useful,” Yann LeCun, often referred to as one of the godfathers of AI, said at another event during the January Davos conference.  

Researchers also point out that the tendency to conflate humanoid robots made to resemble people with so-called generalist machines able to learn and perform multiple tasks is misleading. ”It’s very easy to make a robot that looks like a person,” explains Jonathan Hurst, cofounder and chief robot officer of Agility Robotics and professor of robotics at Oregon State University. “It is dramatically more difficult to make a machine that moves or behaves dynamically or physically like a person.”  

These tensions—over whether all-purpose humanoid robots are just around the corner or nowhere in sight, and whether current forms of AI are all that’s needed to perfect them—are playing out in robotics labs across the country, where the hype over timelines is obscuring painstaking but meaningful progress.

A decade or so ago, a series of breakthroughs led to a generative AI revolution that turned the long-imagined possibility of artificial intelligence into reality. Roboticists—though they disagree on exactly when this will happen—believe that an equally transformative revolution is possible in robotics, one that will endow machines with physical intuition and fluidity that has long been out of reach. As progress in robotics inches forward, the question is whether the same methods and tools that fueled advances in AI are enough to get there, or if an entirely new path is required.

Robots meet advanced AI

To see one of the smartest robot brains working today, it’s worth looking at what Google DeepMind can do with a piece of equipment called ALOHA 2, short for “A Low-cost Open-source Hardware System for Bimanual Teleoperation.” 

Roboticists have long clashed over whether a humanlike form is necessary for generalist robots, with proponents arguing that it will help them slot into the world as it exists and detractors saying it’s not worth the trouble. ALOHA 2 reflects this second way of thinking. Not much to look at, it’s just a pair of arms, some grippers, and a couple of cameras. But despite its seeming simplicity, it is a workhorse for researchers at Google DeepMind, who use it to test their most advanced AI for robotics system, Gemini Robotics, in their various labs.

When controlled by Gemini Robotics, ALOHA 2 becomes more of a generalist robot, in the sense that it can perform any number of tasks based on examples it’s been trained on. Ask it to pack a lunchbox and, as evidenced by a video of this exercise, it can use two pincer grippers to delicately place a piece of white bread into a Ziploc bag, close it, place a bunch of grapes in a Tupperware container, secure the lid, and then carefully move the items into a lunchbox before zipping it up. 

It’s not a great lunch. But the fact that the robot can put it together represents an objective step forward from what was possible even, say, three years ago. 

This is in large part due to AI and its impact on what are known as robot policies, which controls how a general-purpose robot will need to assess and understand its surroundings, plan how to move within them, and then perform its task correctly.

The ALOHA 2 robot isn’t much more than two mechanical arms on a bench top, but it serves as a testbed for cutting-edge AI robotics models. These animations are based on human teleoperation of the robot arms, data that is used to train Google DeepMind’s models. (Video: Google DeepMind / Stanford University / Hoku Labs)

Historically, these policies were based on rules developed by engineers who hard-coded them into the robot’s software—thousands of lines of code that would determine each millimeter of a robot’s movements in hundreds of tasks. What’s been happening for the last few years—and what is largely responsible for the optimism about generalist robots—is that robot policies are being handed over to advanced AI systems instead of being coded into the robot’s software. This first happened with VLMs, or vision-language models. These are similar to large language models, but they’re trained on images as well as words. Show a VLM a picture of a coffee spill and ask it to find a tool to clean up the mess, and it can identify a nearby cloth. This sort of immediate contextual understanding didn’t exist a couple of years ago when robot policies were hard-coded. 

Next came vision-language-action models, which enable robots to assess their environment and take action within it. The models do this by adding yet another component: motion commands. VLAs are trained on a series of images or videos related to performing a given task along with associated data about how a robot arm moves to perform it. That movement data is typically collected through teleoperation, in which a human uses remote controls to lead a robot through an action. This sort of training allows the AI to learn how to command the robot to move and operate during a given task. Place a VLA-powered robot in front of a desk and tell it to “close a laptop” or “wrap up the headphone wire,” and it will survey the scene, identify the relevant object, plan a way to execute the request, and then swing its arms into action—at least if it has seen this task accomplished before. 

The Gemini Robotics model is a VLA, trained on many hours of human demonstrations depicting a vast array of different actions. As a result, it can perform relatively complex tasks like picking up snow peas with kitchen tongs, doing origami, or putting together a simple lunch. It’s impressive, but there’s a glaring limitation: For now, if a robot controlled by a VLA is asked to perform a task that falls outside its training set, it’s highly likely to fail. 

“Thinking about the space of all tasks, a real generalist policy would be able to do everything along that spectrum,” says Edward Johns, a robotics professor at Imperial College London. Today, though, a Gemini Robotics model can do only “a few things here and a few things there.”

The search for true generality

So how do we get robots to be able to do more things? The usual answer is probably not surprising: Train them on more data.  

More data, the thinking goes, equals more examples, and more examples equals more generality. Google DeepMind, for instance, wants to pull together “as much data as possible,” says Pannag Sanketi, a former tech lead in robotics at the company who’s currently working on his own AI robotics project. But where to get it? Large language models had the benefit of oceans of existing text for training. There is no corresponding pool of high-quality physical demonstrations on which to train robots. Researchers have a few ways to make up for this, but all have flaws. One is to employ large numbers of people to create and collect teleoperation data (costly and time-consuming). Another is to train VLAs on videos of people performing activities (the resulting data quality is poor). Yet another is to deploy robots in the real world and use data collected from those experiences to further refine AI models (robots aren’t safe or reliable outside labs). Sanketi thinks a “multi-prong” approach that uses data collected from all these sources is the most likely path forward.

But the belief that training data alone is the answer is far from universal. Agility’s Hurst describes it as “a fundamentally flawed premise.” 

The issue is that tasks in the real world quickly explode in complexity. If you’re trying to, say, make coffee, there are myriad variables: No two kitchens are identical; coffee machines work in different ways; different cups require different grips; coffee grounds, hot water, and milk all need to be handled differently. Even this simple task requires understanding an ever-changing menu of possibilities. Achieving generality through VLAs, Hurst argues, would require “complete data coverage of all of the things that [a robot] could ever do.” Or, in other words, an almost infinite pool of training data. 

LeCun is dismissive of the whole approach. “The [AI] approaches that have been successful for language do not work for high-dimensional, continuous, noisy data”—the kind of data that is commonplace in robotics, he said in Davos. “You have to use something else.”

The leading contender for “something else” is the so-called world model—a form of AI trained less on text than on a combination of video, three-dimensional scans, and sensor data and built to predict the outcomes of actions in the real world. The aim is to build models that possess an internal representation of reality precise enough to capture how the physical world actually operates—how objects move, collide, fall, and deform. If roboticists could train machines in simulations faithful enough to real-world physics, development would become faster, cheaper, and safer, reducing the need for real-world testing. Even more transformative, robots equipped with world models could reason about their surroundings rather than merely reacting to them, helping them anticipate the consequences of an action before taking it.

Google DeepMind’s latest AI models for robots are increasingly dextrous, if rather slow and erratic

Companies like Nvidia and Google are working on the technology, and investor cash is pouring into high-profile startups. World Labs, cofounded by the Stanford AI researcher Fei-Fei Li, raised $1 billion in funding in February and was acquired by AMD at the end of September for $8.2 billion. AMI Labs, cofounded by LeCun (formerly Meta’s chief AI scientist), also raised $1 billion in March. Yet by their own admission, it is still early days. Late last year Li described the field as “nascent,” adding that “foundational approaches are still being established.” In a June Substack she described daunting challenges. For now, world models are a promising area of research rather than an immediate route to general-purpose robotics, but we are beginning to see glimmers of what they could achieve.

One such glimpse came with a small but potentially significant leap forward that took place in a San Francisco robotics lab last April. 

A breakthrough?

In the heart of San Francisco’s Mission District, the startup Physical Intelligence—or PI (as in π), as it likes to be known—is focused on developing a universal brain that could, theoretically, turn any robot into a generalist. Using an everything-including-the-kitchen sink approach to training AI models for robots, the company recently observed a hint of what a robotic brain equipped with a world model could be capable of. 

In 2024, PI published details of its first generalist robotics system, called π0, a VLA it claimed was the “most capable and dexterous generalist robot policy to date.” The model was initially trained on a 10,000-hour proprietary collection of human demonstrations gathered through teleoperation as well as several open-source robot datasets. A version released in spring 2025, π0.5, was trained on a wider variety of datasets, including labeled images from the web, lending it more versatility. A fall 2025 update, π0.6, added reinforcement learning to the model.  

Each update yielded important improvements to the model’s performance, increasing its menu of abilities from slowly folding laundry to putting things away in new environments to completing tasks like folding boxes with a higher success rate. Then, in April 2026, π0.7 seemed to catapult PI into new territory. This version makes use of a less powerful world model that generates images of steps necessary to perform a task. As the robot undertakes the job, this “lightweight” model feeds it snapshots of what to do next. 

How do you teach a robot to use a knife? At the startup Physical Intelligence, it begins with designing the right AI architecture, which includes components dedicated to language, vision and motion. This will help it relate commands — “hey robot, chop my vegetables!” — to appropriate actions.
WINNI WINTERMEYER
Data to train the AI can come from many sources, but one of the most important is human demonstrations. An employee at the startup controls a robot arm through teleoperation, exposing the AI to the task of slicing a zucchini.
WINNI WINTERMEYER

A researcher points out a detail from a training video to his colleague on a laptop screen
Researchers train the AI model on hundred of examples of human demonstrations, as well images from the web and first-person video.
WINNI WINTERMEYER
Robot grippers cutting a yellow squash with a kitchen knife
Once the AI is trained, the team presents it a task it has not seen before, such as chopping this summer squash. When a robot hasn’t seen the exact task before — it may wonder if that’s a yellow zucchini, or an unusual banana — it can mess up. But any failures can be used to help refine the model.
WINNI WINTERMEYER

The company claims that the model exhibits the first signs of compositional generalization, a term for AI systems’ ability to perform skills they’ve never been exposed to by recombining ones learned in their training data. One test involved asking a model to “load a sweet potato into the air fryer”—a task it had never previously encountered. In a demonstration video, the machine futzes around a little, makes a few false starts, and eventually manages a reasonable effort, though it doesn’t finish the task completely.

Sergey Levine, a professor at the University of California, Berkeley, and a cofounder of PI, is excited by the potential: “It’s actually the first time that we’ve convincingly seen that kind of compositional generalization, where we can basically ask the model to do tasks that we did not specifically collect data for and train it to do, and it’ll actually make a passable attempt.” 

The success led the team to wonder how the model was able to achieve such a feat. After some digging, they found snippets of relevant labeled teleoperation data lurking in the training material, including two examples of a human controller using the robot to push an air fryer basket into the fryer. Those shreds of data might have been enough to enable π0.7 to almost air-fry a sweet potato.

For now, it remains unclear just how impressive π0.7’s abilities to generalize are. Still, given how fleeting the model’s exposure to air fryers had been, it offers a glimpse into how far cutting-edge research can currently take robots. 

“70% success is like it doesn’t work”

You might be sensing a disconnect between the halting baby steps robots are making in labs—“Look! It put a sweet potato into an air fryer!”—and the dazzling, lifelike nimbleness on view during many demonstrations and videos, where robots are seen doing everything from dancing on a stage to courteously serving drinks. Such demos often don’t clearly reveal a key fact: In many instances, humans are controlling the robot or have carefully scripted its actions. (The robot that appeared onstage with Nvidia CEO Jensen Huang in March 2025, for example, seemingly responding to his instructions and following him around, was remote-controlled by what its makers called “a puppeteer behind the scenes.”) 

For now, fully autonomous motion planning so that a robot knows where it should go—especially in new, chaotic environments like a construction site or a unfamiliar home—remains a largely unsolved challenge. A bigger challenge still—albeit one that is often related—lies in getting robots to tackle larger, more ambiguous jobs that include multiple tasks and require decisions about how and in what order they’re done. This would be the difference between a robot that can put a plate into a microwave and one that can successfully respond to the prompt “Make dinner” by exploring the refrigerator, chopping ingredients, and firing up the stove. Google DeepMind’s best attempts at something like this—which involved asking its robot to survey a kitchen and pack all the ingredients for a mushroom risotto into a basket—have so far resulted in failure.

Adding to the challenge, a practical robot must essentially get it right every time. With VLAs, “people are very excited when their result goes from 50% success to 70% success,” says Marc Raibert, founder of Boston Dynamics. “But 70% success is like it doesn’t work, right?”

split screen of nine clips with different robots attempting tasks; some are teleoperated and a few have collided with objects or fallen.
Demonstrations often make robots look useful, but the machines still mess up far too often to be used reliably in homes and factories.
AP IMAGES, SHUTTERSTOCK, 1X, AGILITY ROBOTICS, GOOGLE DEEPMIND

The few humanoids that are being tested in real-life settings are undertaking extremely limited tasks in tightly controlled environments. They’re far from generalists. Agility has hundreds of robots deployed across trials in facilities owned by GXO Logistics, Amazon, and Schaeffler, according to the company. But for now, Hurst says, the robots are targeting simple tasks such as moving bins and totes around. Even then, he adds, it took years to develop robots safe enough for logistics firms to even contemplate using them. For his part, Elon Musk claimed in May 2025 that “thousands” of his Optimus robots would be working at Tesla factories by the end of the year, but in January of this year he said that the company had only “some of the Tesla Optimus robots doing simple tasks in the factory.”

While humanoids are starting to venture onto the factory floor, making the jump to households will be even more difficult. Right now, should you so desire, you can preorder the 1X Neo home robot, expected to be ready for delivery sometime later this year. Yours for $20,000, it promises to take on “the boring and mundane tasks around the house”—putting away dishes, answering the door, tidying the living room—“so you can focus on what matters to you.” The idea is for this five-foot-six-inch robot to one day perform all those tasks autonomously, but for now a remote human operator is needed for it to do most things. (Yes, a person would need permission to peer into your home through the robot’s cameras.) Asked how long it will be until fully autonomous robots are ready for domestic work, Hurst said, “If I had to pick a number, I’d say it’s 10 years before robots are … actually doing useful things in people’s homes.”

When that happens, the robots might well be Chinese, as China is well ahead of the West in terms of production. Nearly 90% of the roughly 15,000 humanoid robots shipped in 2025 were made by Chinese companies, according to the market intelligence company Omdia and the Chinese robotics firm Unitree. One model produced by Unitree, which shipped more humanoid robots than any other company last year, costs less than $6,000. Such an affordable price could go a long way toward making robots more attractive to consumers, though the company expects its machines to be used in industrial applications first. (If you’re wondering who is buying all these Chinese robots, by the way, the AP recently reported that orders come predominantly from corporate and academic labs and state-owned enterprises.)

We’ve been here before 

The dream of building a humanoid robot runs deep: As far back as 1495, Leonardo da Vinci sketched out designs for a mechanical knight, controlled by cables and pulleys. Through the 20th century, machines of sci-fi fever dreams have come and gone. 

Jeanne Dowling reaches up to light a cigarette for Elektro, a seven foot robot built by Westinghouse.
Westinghouse’s Elektro was a sensation at the 1939 World Fair.
GETTY IMAGES

Westinghouse’s seven-foot-tall box on legs, Elektro, hit the New York World’s Fair in 1939, smoking a cigarette. WABOT-1, built by Waseda University in Japan in 1973, was the first full-scale, programmable humanoid robot. Honda’s ASIMO, unveiled in 2000, was probably the first such machine to prove at all competent—it could, at least to some degree, climb steps, recognize faces, and autonomously move through spaces. But the robot was discontinued in 2018, unable to advance far enough beyond what it could do in demonstrations to be useful. 

All, at the time, were impressive—even jaw-dropping—feats of engineering. But none were ready to navigate the real world. Today’s robots, even with the transformative power of advanced AI, still face the same existential challenge.

Building a safer path to autonomous industrial AI

Industrial AI is entering a new phase. After decades of predictive analytics and other specialized applications, advances in foundation models, physical AI, and agentic AI are making it possible to automate more complex tasks across industrial environments. But unlike AI that operates purely in the digital world, industrial AI can interact directly with physical systems, where an unexpected decision can have consequences for safety, reliability, and critical infrastructure.

That makes responsible deployment central to the next wave of industrial automation. “How do we leverage these technologies while maintaining safety, while maintaining reliable operations, while still being able to deliver on the promises of the new capabilities?” asks Arti Garg, chief technologist at AVEVA. The challenge is particularly acute as newer AI systems become more capable but also harder to predict and explain.

One foundation for making that transition work is data. Industrial systems often contain information across telemetry, service logs, engineering documents, and other disparate sources. Newer technologies can help connect and correlate that information more quickly, giving operators real-time support when diagnosing problems. AI-powered robots could take that a step further by gathering information in hazardous environments without requiring workers to enter them.

But greater autonomy also requires new approaches to governance. AVEVA’s framework for responsible AI emphasizes security, efficiency, and human safety and oversight. Garg argues that AI should augment rather than replace people in critical decision loops, with guardrails determining where automated systems can act and where human supervisors remain responsible.

Sustainability is another part of that equation. AI can help manage complex power systems as renewable generation grows, while organizations also need better ways to understand AI’s own environmental footprint. Garg is involved in an IEEE working group developing a standard methodology for measuring that impact across electricity, energy, resources, water, and carbon.

The next phase could bring industrial AI further into the physical world, from autonomous robots and drones to AI-assisted coding that allows domain experts to build new applications. But realizing that potential will require more than deploying new technology, says Garg. Organizations will need to rethink business processes, establish appropriate safeguards, and give experienced workers new ways to apply their expertise, creating a model of automation that is not only more autonomous, but safer, more efficient, and more sustainable.

“Autonomous systems, whether they’re robots or drones, are really going to change the way that we work in plants, in power systems, on mining sites,” says Garg. “In a way, that will make these types of operations more efficient, much safer for the human beings involved and more productive.”

This episode of Business Lab is produced in partnership with AVEVA.

Full Transcript

Megan Tatum: From MIT Technology Review, I’m Megan Tatum, and this is Business Lab, the show that helps business leaders make sense of new technologies coming out of the lab and into the marketplace.

Industrial AI may not be new, but it is developing at a breakneck pace. From modern predictive analytics that can preempt equipment failures, to autonomous robots tasked with inspecting high risk machinery, emerging applications have the potential to transform operational efficiencies. But often used in high consequence environments with minimal margin for error, industrial AI deployed without clarity, security, or accountability could also have catastrophic consequences for critical infrastructure over time. As industries rush to embrace the latest technologies, the goal should always be responsible AI designed to support, rather than replace that all important human judgment.

Two words for you: sustainable automation.

My guest today is Arti Garg, chief technologist at AVEVA.

This podcast is produced in partnership with AVEVA.

Welcome, Arti.

Arti Garg: Thank you, Megan. It’s great to be here.

Megan: Thank you so much for joining us. And just to start, if we could set some context for our discussion, can you share a bit about the current state of industrial AI and what AVEVA is working on at the moment as well?

Arti: Yeah, more than happy to. And I want to go back to what you already stated, which is that in some ways, industrial AI is not new. It’s something that, even here at AVEVA, we’ve been working on for more than 20 years, really thinking about how AI can enhance applications in the industrial sector.

But what has changed quite substantially in maybe the last few years is the type of AI. We’ve really moved to these general purpose foundation models, which enable a lot more people to leverage advanced AI technologies. In addition to that, in just the last couple of years, there’s been an explosion in what’s known as physical AI and the types of AI that can really accelerate the capabilities of robotics and autonomous systems. And also agentic AI, which also allows for automation at more of the software level.

And what we’re seeing is that while in the past there has been some hesitancy to adopt models that don’t totally have predictable outcomes, there’s been a rapid acceleration in adoption of AI even in the industrial sector. One study suggests maybe that’s almost a 78% increase over the past just two years within the industrial sector. So yes, that’s an inflection point, but it’s almost like a step function if you think about it with respect to AI adoption.

And what we’re really thinking about now at AVEVA is, how do we think about this? How do we think about incorporating these new and very powerful AI technologies in environments where customers have mission-critical operations, human safety is a significant factor? Those are some of the primary concerns that our customers have when they think about adopting any new technology. We’re doing that in narrow where these newer types of AI aren’t necessarily predictable, in terms of how they behave. That’s one of the areas we’re really thinking about is, how do we leverage these technologies while maintaining safety, while maintaining reliable operations, while still being able to deliver on the promises of the new capabilities?

Megan: There’s so many things to consider at once, isn’t it? And you outlined there some of the huge developments we’ve seen in this space in recent years. What makes this such a pivotal moment for industrial AI specifically? What has changed to make some of those perhaps more out there hypotheticals much more plausible?

Arti: Well, I think one of the big things, one of the big challenges within industrial AI, and this is something that as AVEVA, it’s in our blood, it’s in our core DNA, is that to really leverage any kind of digital technology in the industrial space, one of the first important things you often need to do is gather and correlate data from disparate systems, so that maybe I have telemetry coming off of a pump or a mixer, and I want to be able to correlate that with service logs so I know maybe the last time that someone had done some maintenance on that pump or mixer. And maybe I also want to be able to correlate that with the original design documentation and some of the original documentation on how to maintain that, so that if something is happening, I can do a better job diagnosing what’s going wrong and how to address it. This has always been a core challenge in the industrial space.

I think that what’s happening now is that with newer technologies, even things like graph databases and being able to leverage AI to really match disparate data sets much faster, we’re able to get to the point where if something goes wrong, instead of an operator maybe needing to spend a little bit of time doing this research to really understand how do these different components fit together of information, they may have just an iPad with an AI that can very quickly go and fetch that information, correlate it and help in real time, almost, diagnose what is happening.

Even a little bit more out there, but not as out there as you might think is, I still describe this with a human operator with potentially a mobile tablet, but imagine now I can also have a robot moving through that environment also gathering data and either with onboard computation or a quick connection to an operator who doesn’t necessarily now have to go out into a dangerous, potentially somewhat hazardous space, be able to gather data and enable that very quick diagnostic as well. And I think that’s really what’s exciting right now and what all of these new technologies that I’ve talked about are helping to enable.

And I think then from our perspective, trying to really leverage all of those means that we have to think a lot now about our governance approach to this. How do we leverage AI in a way that keeps it contained, if you will?

Megan: Yeah, absolutely. And on that governance point, how does AVEVA define responsible AI and what do you see as the primary benefits?

Arti: Yeah, so I think for us, we think about a triple mandate around responsible AI, and that means that it’s secure, it’s efficient, and that includes environmentally efficient, and then it really preserves human safety and human oversight above all. And for us, that’s what some of our core pillars of responsible AI include. And for us, that means we think about internally as we build tools, a multi-layered governance approach where we’ve got both for how we use AI as a company and then how we deploy AI into our products. We’ve got a similar framework that we leverage across both, a kind of joint governance model, both around how we’re leveraging AI and also how we’re infusing AI into our products to allow our customers to leverage AI in their operations.

But I would say one of the core foundational principles underneath all of these is that human beings still remain centered in how we think about how AI is leveraged. And so human judgment, human responsibility, human ethics are still core to how we think about where AI can add benefits, and we think about it more as augmenting rather than replacing human beings in critical decision loops, if you will.

Megan: Right, which is such an important distinction, isn’t it? And in terms of the next phase of development, there’s growing sentiment that agentic AI will soon allow these industrial systems to operate much more autonomously. I wonder, what makes the risks in industrial settings different from AI risk in a purely digital context? And I suppose on the flip side, what are the benefits and opportunities of that same software defined automation?

Arti: I think we can start with the risks and then go to the benefits. I think ultimately, I would say the biggest risk in the industrial setting is that we are interacting with real physical systems, often physical systems that are very capable of delivering important outcomes that keep our world running, whether that’s delivering power, whether that’s mining for natural resources. But usually. Those physical systems are also operating in hazardous environments, the equipment itself is capable of also having human safety implications. Anytime you’re interfacing software with a physical system that can have real world consequences, you have to be extra careful. And we’ve always had that, again, we’ve had that in our DNA at AVEVA from the beginning, being mindful of that end user and that end application, which is not just something on a computer screen.

Even as we’ve deployed AI over the past few decades into our systems, we’ve typically leaned toward really trying to pick the best fit model, really understand that model’s behavior if we’re going to use, for example, we have a proprietary anomaly detection model that works in a lot of operational environments. Now, as we’re thinking about some of these newer AI capabilities, which by design are hard to understand how they behave, they’re not fundamentally explainable in the way we’ve thought about even AI or statistical models in the past, and actually their behavior can change over time as they learn and get tuned to new capabilities. That’s really the potential risk of automating a physical system based on capabilities that can evolve over time is one of the things that we have to be really mindful of and really thoughtful around, where are we willing to put some of that increased automation into practice?

But at the same time, I think there’s a real opportunity there, because I glossed over this idea that, okay, well, models evolve, but so do human beings, and sometimes that’s a good thing. We talk about humans having expertise and they gain understanding over their careers of how a system works. If we can actually leverage the ability of some of these newer AI capabilities, these sort of reasoning models often have underlying agentic capabilities, to learn and gather experience faster, and potentially even more importantly or more valuably, take experience that’s learned at one site and apply it to another site, then that’s a real opportunity to take what we already know works for human beings, which is that sometimes you just have to learn by doing and be able to apply that and scale that through AI. That’s where I see potentially a real opportunity in this space.

One of the things that we’re really aware of in the industrial sector is just the way that our workforce is changing. I think that almost half, not quite half, of the industrial workforce is set to retire in the next five years, and that’s a lot of expertise and experience that means that we’re going to lose in the sector. If there’s ways to make sure that we can capture that in ways that are actionable, in ways that can also help a newer generation of workers that are used to experience things in a different way, apply that expertise, apply that knowledge, then I think that’s a huge opportunity within the industrial space.

Megan: Yeah, absolutely. Clearly, some huge opportunities there particularly against the backdrop of other market and workforce changes as you’ve outlined there. I suppose building on that, what is the potential for these autonomous industrial AI systems when built and deployed responsibly to facilitate even faster, more sustainable industrial processes?

Arti: I think there’s a couple different ways to think about this. One is, what are the demands of potentially more environmentally sustainable processes? I’ll use one example of something that my team has been working on in partnership with Idaho National Laboratory here in the U.S. as part of their testing for AI grid resilience project.

One of the challenges in the electric grid as we’re moving toward a future where we have a lot more intermittent renewable power generation sources, often distributed rooftop solar for example, is it’s becoming much more challenging to manage the grid both from really understanding where electric capacity is coming in, electric load is pulling off of the grid. In addition to that, being able to maintain just power quality because instead of having one spinning asset delivering the frequency of electricity that’s going across the grid, you’ve got a lot of smaller systems. AI is actually quite critical for being able to manage that grid of the future. And this is one of the things that we’ve been working in partnership is, how can we do that? How can we help grid operators better understand what’s happening across their system, identify where things might be behaving anomalously so they can detect that early and then remediate for it?

At the same time though, I always talk about that’s an example of where AI can potentially help us accelerate the transition to a lower carbon energy future. At the same time, I think there’s a lot of conversation around the sustainability of AI itself. What are the power requirements? What are the resource requirements needed to run AI? And before I get into how do we think about that at AVEVA, because it is definitely something we think about and I think a lot of actors in the space are thinking about, I want to point out, is one of the challenges is that there’s really no agreed upon method to measure the environmental impact of AI. You see a lot of these stories, like one query on some kind of chat interface is X amount of gallons of water or this amount of electricity use. But the truth is that community-wide, there’s no agreed upon standard.

One of the things that I’m involved with is a standards working group that was launched by the IEEE two years ago, a little over two years ago. I’m the chair of that working group, it’s called the P7100 Standards Working Group on measuring the environmental impact of AI. And one of the things we’re trying to do is really identify all the different areas over which we want to think about environmental sustainability associated with AI, and then having one standard methodology that works and that can be adopted both from a reporting perspective and potentially also from an oversight or regulatory perspective. That becomes really important for any sort of real understanding of how AI impacts the environment is just we have to know, what does it use? We want to look holistically at that. Our standards cover electricity and energy consumption, it covers resource usage, it covers water consumption, and it also covers carbon.

But all of that said, I think it’s important for us to understand the footprint of AI, but I think it’s also important for us to simultaneously recognize that a bigger model uses more compute and more compute probably leverages more resources. The more that we can be intentional and pick the right size model for the right application, the more we can already start down that path of being more environmentally efficient in the AI that we run. One of the potentially nice side effects of that is the more purpose-built a model, the less likely it is to misbehave in unpredictable ways, if you choose correctly your architecture. There’s some sort of ancillary benefits that go beyond environmental sustainability.

Megan: Fascinating. It’s really, really interesting to hear some of the work going on behind the scenes there, because I think we’ll all have heard some of the statistics around the environmental impact, as you say. So, it’s great to understand some of the work going on there to really clarify that.

And we’ve talked a little bit about AI augmenting humans earlier. As systems gain greater autonomy, how should organizations think about that balance between closed loop automation, human in the loop accountability? What guardrails need to be in place? And how are governments and cross-border actors approaching those concerns as well?

Arti: There’s a lot packed into that question, so I’ll try to answer it somewhat one by one. First, starting with that sort of balance between closed loop and human in the loop, automation and accountability. One of the things that we talk about in the industrial sector is from human operator to human supervisor of systems, of industrial systems. And if I’m honest about that, we’re still trying to figure that out. When a human’s in a loop in an automated system, you’re really thinking about a system may process all the data and then make a recommendation.

We’ve got a solution that we’ve been working on more jointly with a few different customers where we’re able to take in a lot of their operational data, also some simulations of how their systems work, and be able to provide, say, recommendations around, you should now operate at this set point instead of that set point based on some of the other conditions that are changing in your plant. There’s a lot of interest in moving from having that be a recommended set point to have an automation that can automatically adjust the set point. And we’ve actually had some successful real-world pilots around that as well.

But when you get into that, obviously it makes people very nervous if you’re changing set points on industrial equipment. That’s where you maybe continue to have some guardrails around like, you can’t go outside of a certain band, for example, of operations, or we only allow the automation in certain areas. That’s where the human supervisor, the same way a human supervisor might give employees a lot of bandwidth or a lot of flexibility to make decisions around certain things, around other things, they’re hard and fast, like this is the deadline or this is the sort of production target. It’s like that. So thinking about, how do you put the appropriate guardrails?

The challenge is, AIs are not human beings, and so the guardrails look different, and I think that’s one of the things that there’s still to think about. That question of, what guardrails should be put in place? I think that it’s going to be probably dependent a little bit on the application, but over time I think we’re all going to learn, and so being really upfront and thoughtful about how we do this I think is important.

But the opportunity though, potentially, is really great. I’ve already mentioned that AI can be very useful in synthesizing a lot of information and bringing to the forefront, this is what matters. That’s something that we do want to create some space to experiment around, but what’s then important is making sure that a human being understands the risk.

I’ll give a little bit of a personal story because it might be illustrative. This weekend, I bought a little toy robot and decided I wanted to program it to do some stuff, and I found AI very, very helpful to get me started to read all the documentation. Putting the robot together was straightforward, they had nice instructions, but there’s a pretty heavy software developer kit that’s already there, but going through and reading all that documentation can take a while. AI was super helpful to help me surface, this is the function that does this, to help me get started. But occasionally, it made really bad recommendations on the best way to troubleshoot something.

That’s where I think having the human being in the loop, being able to say, “I know that it’s not going to be the best software architect or the best troubleshooter,” is really helpful because I had the opportunity to leverage AI for what it’s good for, synthesizing and surfacing a lot of information, but being able to say, “I don’t think that’s the most efficient first step. Let’s try something else.” That’s where it’s a really different way of working, but it’s something that I think as humans get more comfortable with the power and limitations of AI, you can start to teach people how to work with it, and it’s very different from how you would work with other digital tools.

One of the things that is important when it comes to AI is recognizing just the breadth of things that it touches and the breadth of impacts that it’s going to have, whether it’s on the environment, as we’ve discussed, whether it’s on productivity as sort of implicit in this entire discussion, whether it’s on labor force, whether it’s on just how economies work. From my eye, and I’m by no means a policy expert in this area, but from my eye, what I’m seeing is that different governments are prioritizing different aspects of that from how they’re thinking about regulatory and other kind of governance approaches.

Megan: We’re absolutely seeing some really vastly different approaches to this, aren’t we, around the world? I wondered to illustrate some of this, if you could share perhaps some case studies you’ve seen, maybe talking us through what lessons they could hold for other organizations perhaps a little earlier in their own AI journeys.

Arti: I think a lot of the key areas where we’re seeing very clear benefits of adopting AI in the industrial sector, the core to all of them is actually getting the data right and getting the right foundation of data so that you can build AI on top of it.

One of our customers, SCG Chemicals, which is a petrochemical company in Thailand, they had this vision of producing a reliability platform for their operations that was as AI-driven as possible. But a core part of that was actually getting the data right, being able to have all of their information in the right place, leveraging some of AVEVA’s tools to do that. Bringing together operational data and also engineering data. And then putting on top of that AI capabilities, in this case, one of our capabilities called AVEVA Predictive Analytics that deploys some proprietary models to do things like detect anomalies, so that they could really much earlier identify potential operational risks. And instead of having unplanned downtime, translate that to planned downtime. When you translate unplanned downtime to planned downtime, you can get a huge improvement in plant reliability.

At this point they’re targeting something like 99% plant reliability and a very, very high return on investment from the platform that they put in place. Again, in early pilot days, it was almost a 9x ROI, and so that’s really quite impressive. But what I want to emphasize is that it’s kind of a multi-layered problem to get it right.

Megan: Those are some really striking results, though. I mean, for industrial leaders who perhaps are still hesitant to explore AI, I wonder, what do you think is the cost of taking a more wait and see approach?

Arti: I think, again, this is an area where the industrial sector has a little bit of a different calculus to apply to this type of problem. In general, I think you would hear most business experts say that you can’t afford to take a wait and see approach to AI because it is so transformative across every sector of society and economy, and certainly in the industrial space, we’re not immune to that. But I do think that some of the challenges that I’ve outlined today also puts leaders in the industrial space into a mindset of sometimes potentially being a fast follower rather than the first adopter of newer technologies, just because the risk is so high.

But that being said, I think one of the challenges is that the risks that we’ve covered today around infusing systems that don’t always behave predictably with physical systems is that I don’t know that there’s a lot of other sectors that are going to be solving those problems. That’s where what I’m seeing is actually a lot of interest and excitement in trying new things and willingness to do that because there’s a recognition that applied correctly and applied with the right guardrails and safeguards in place, these technologies really have truly transformative potential from a resource usage standpoint, from a human safety standpoint, from a productivity standpoint.

I think the calculus has shifted a little bit in the sector to we want to actually try these things out. But then it becomes more, how do we try these things out in environments that we can make a little bit more sandboxed or safe to test out what some of the unique challenges we’re going to face in the industrial sector are?

Megan: Yeah, absolutely. It’s just hard to ignore the potential nowadays, isn’t it? And just to close with a slightly future forward look, I suppose, what are you most enthusiastic about in terms of the long-term potential of responsible autonomous industrial AI systems?

Arti: Yeah. Well, I think that there’s a couple of different trajectories. One of the things that I think within the next 18 months for sure, we’re going to see an increase of people with deep domain expertise who maybe didn’t grow up with a software background, be able to adopt AI assisted coding techniques to really be able to build the things that they weren’t able to build before.

That’s really exciting in my career, which way back when I was actually an industrial data scientist, I would say I always felt the most energized and that I learned the most talking to the people that were on the front lines of operations, having to monitor a lot of different equipment and understanding how it all worked together. They really have a lot of expertise, and being able to put in their hands the ability to very quickly develop new applications is I think going to really lead to a lot of new ideas that many of us in the industrial software space maybe wouldn’t even have thought about and really understood how to put. I think that’s really exciting.

I think then looking beyond that, I was a little bit of a, not to say a robotic skeptic, because clearly robotics and autonomous systems are going to be important, especially given the types of environments, whether they’re hazardous or remote, that industrial equipment operates in. But I just actually think things are moving a lot faster than I had anticipated. I’m really interested to see how these physical embodiments of AI systems start to really transform, again, how we think about operations.

One of the things about any new technology in any environment is that to really gain value from it, you have to change the way you do things. I would say for close to 10 years now, I’ve been giving talks on AI adoption and I always say the biggest barrier to AI adoption is not anything to do with the technology. It’s not even to do with the data, although data are often the biggest sticking point, it’s really to do with, are you going to change your business processes to be able to work with the way this technology is good or not good at things?

Autonomous systems, whether they’re robots or drones, are really going to change the way that we work in plants, in power systems, on mining sites. And I think that will make these types of operations more efficient, much safer for the human beings involved and more productive. So, I’m quite excited about that.

I don’t know entirely what direction it will go, but one of the things that I think about a lot is that if you go back to I, Robot and Isaac Asimov’s book, the premise of those was that robotics would be the first broadly adopted AI, not computer-based systems. We went in the other direction and I think it’s really interesting to now see all of this converging.

Megan: Yeah, absolutely. See robotics catches up a bit. So many exciting things on the horizon, that’s for sure. Thank you so much, for your time.

That was Arti Garg, chief technologist at AVEVA, whom I spoke with from Brighton in England.

That’s it for this episode of Business Lab. I’m your host, Megan Tatum. I’m a contributing editor at Insights, the custom publishing division of MIT Technology Review. We were founded in 1899 at the Massachusetts Institute of Technology, and you can find us in print, on the web, and at events each year around the world. For more information about us and the show, please check out our website at technologyreview.com.

This show is available wherever you get your podcasts. And if you enjoyed us, we hope you’ll take a moment to rate and review us. Business Lab is a production of MIT Technology Review, and this episode was produced by Giro Studios. Thank you so much for listening. Goodbye.

Learn more at aveva.com.

This content was produced by Insights, MIT Technology Review’s custom content arm, not its editorial staff. It was researched and written by humans, with any AI tools that may have been used limited to production processes under human oversight.

Connecting AI agents to enterprise knowledge

For all the data that AI systems continually amass and analyze, enterprise AI agents often suffer from a curious shortcoming: a lack of knowledge. More than data, knowledge is the understanding of what the data means in the context of individual organizations. AI agents need this understanding to reason about situations, make decisions, and ultimately take actions. Without sufficient knowledge, agents are prone to making flawed and unreliable decisions.

A lack of knowledge, our research finds, is a major reason agentic AI use cases never make it to production. Competitive pressure is making it urgent to address this. Organizations need to deploy and scale more of their agentic projects to capture the efficiency gains AI promises. Falling short risks wasting the investment already sunk into these projects, and it cedes ground to rivals already putting their agents to work more effectively.

The purpose of this report, which is based on a survey of 300 data, AI, and other technology executives, is threefold. First, it seeks to gauge organizations’ agentic knowledge capabilities (i.e., their ability to give AI agents a full contextual understanding of the data they ingest) across semantic knowledge, episodic memory, and procedural knowledge.

Second, the report probes the challenges organizations face in improving access to knowledge and ultimately to getting more agent use cases into production. Third, it explores the measures organizations are taking to overcome these challenges.

The key findings include the following:

Data and knowledge weaknesses consistently stall AI agent progress. On average, only around a third (34%) of organizations’ agentic AI projects make it into production. Even high-tech firms struggle with this. Legacy data systems, security and privacy concerns, and a lack of knowledge and context are the key points of failure.

Strong knowledge capabilities correlate with agent success. A small group of production leaders (organizations where on average 61% of agentic projects advance beyond pilot) have stronger knowledge capabilities than the rest, especially when it comes to semantics. This advantage tracks closely with their higher production rate.

Fragmented data hugely complicates knowledge access. Data fragmentation (the inadequate sharing of data across systems) was most commonly cited as a top challenge to expanding agents’ access to knowledge (cited by 55%). Production leaders, by contrast, are more likely to see security and privacy concerns as a major concern (cited by 72% of this group).

Most firms aim to strengthen the link between data and agents. Among steps that can yield higher quality agent decisions, executives expect the biggest impact to come from strengthening the structural foundation between the organization’s data and its AI agents. The experts we interviewed see a knowledge layer as a prime way to achieve this.

Investment priorities to boost knowledge range from pipelines to knowledge graphs. To expand agent access to knowledge, organizations will prioritize investments in retrieval technologies, like ingestion pipelines, AI-ready APIs, and retrieval-augmented generation (RAG); in AI evaluation agents; and in knowledge graphs.

Download the report

This content was produced by Insights, MIT Technology Review’s custom content arm, not its editorial staff. It was researched and written by humans, with any AI tools that may have been used limited to production processes under human oversight.

Bringing predictive analytics to the agentic AI era 

In 2026, the question for enterprise AI is no longer whether predictive models can outperform statistical forecasts—that argument is settled. The big question now is how to enable predictive systems to act on their own conclusions without drifting from business intent. The frontier has moved from prediction to autonomous decision making, and the gap between leaders and laggards is widening accordingly.

“Enterprises are done with a backward-looking point of view; they want to be more forward-thinking,” says Vishal Gupta, partner at research firm Everest Group.

Intelligent analytics, powered by technologies like deep learning and generative AI, are making this possible. Real-time training allows AI to evolve continuously instead of waiting for quarterly refreshes. In addition, the data that newer predictive engines rely upon has expanded to encompass not just neat, numerical records but also messy, unstructured sources of insight-rich interactions. As a result, AI-powered analytics are moving enterprises from passive hindsight to pragmatic foresight.

AI takes predictive analytics—a broad discipline that includes predictive modeling, data prep, analysis workflows, interpretation of results, and decision-making applications—to new heights. “In many ways I think the word ‘analytics’ is giving way to AI,” says Gupta. “Everything is becoming AI.”

Download the report

This content was produced by Insights, MIT Technology Review’s custom content arm, not its editorial staff. It was researched and written by humans, with any AI tools that may have been used limited to production processes under human oversight.

Redefining enterprise intelligence with autonomous AI

Enterprise AI is no longer a future ambition. It is in full operational flight. Model capabilities are advancing faster than most organizations can absorb, while the cost of performance continues to fall. Globally, AI investment is set to reach $2.5 trillion in 2026, up 44% from the previous year.

For many enterprises, this investment has produced fragmentation. Intelligence can accumulate in silos so that sales agents are unaware of open support tickets, for instance, or marketing systems are personalizing content without visibility into what finance already knows about a customer. Each function may perform well in isolation, but the enterprise as a whole learns little and has less information to act upon.

The shift from AI as a tool to AI as an operating model—what we call the “agentic shift” in this report—demands something more fundamental than better models or faster infrastructure. It requires connecting people, processes, and data in real time, along with the governance and control to act on that intelligence reliably.

This means rethinking both architecture and operating models simultaneously. First, rebuilding data infrastructure for accessibility rather than volume. Second, replacing fixed tech stacks with composable architectures that can evolve as models and tools change. And, lastly, resolving questions of AI sovereignty, including where intelligence runs, who controls it, and how it operates across organizational and jurisdictional boundaries.

Key findings include the following:

Enterprise AI’s scaling problem is structural. Process-first companies are pulling ahead. Global AI spending is rising sharply and model capabilities are advancing faster than most organizations can integrate them. Yet the majority of enterprises are still not growing revenue through AI or fundamentally rethinking how they operate. The companies generating sustained returns share a common discipline. They treat process redesign as the work that precedes model selection, building for how the technology will evolve rather than retrofitting roles and workflows after deployment. For them, the agentic shift begins with the operating model.

Data readiness, not data abundance, is what makes AI compoundable. Most enterprises discover too late that having data and having AI-ready data are very different things. A sovereign, composable foundation—one that queries and prepares data where it resides, without migration or centralization—can convert raw data estates into intelligence that AI agents can act upon. As data residency laws, multicloud environments, and structural complexity make centralization increasingly impractical, sovereign control over where models run and data lives is what keeps that adaptability intact.

Download the report.

This content was produced by Insights, MIT Technology Review’s custom content arm, not its editorial staff. It was researched and written by humans, with any AI tools that may have been used limited to production processes under human oversight.


❌