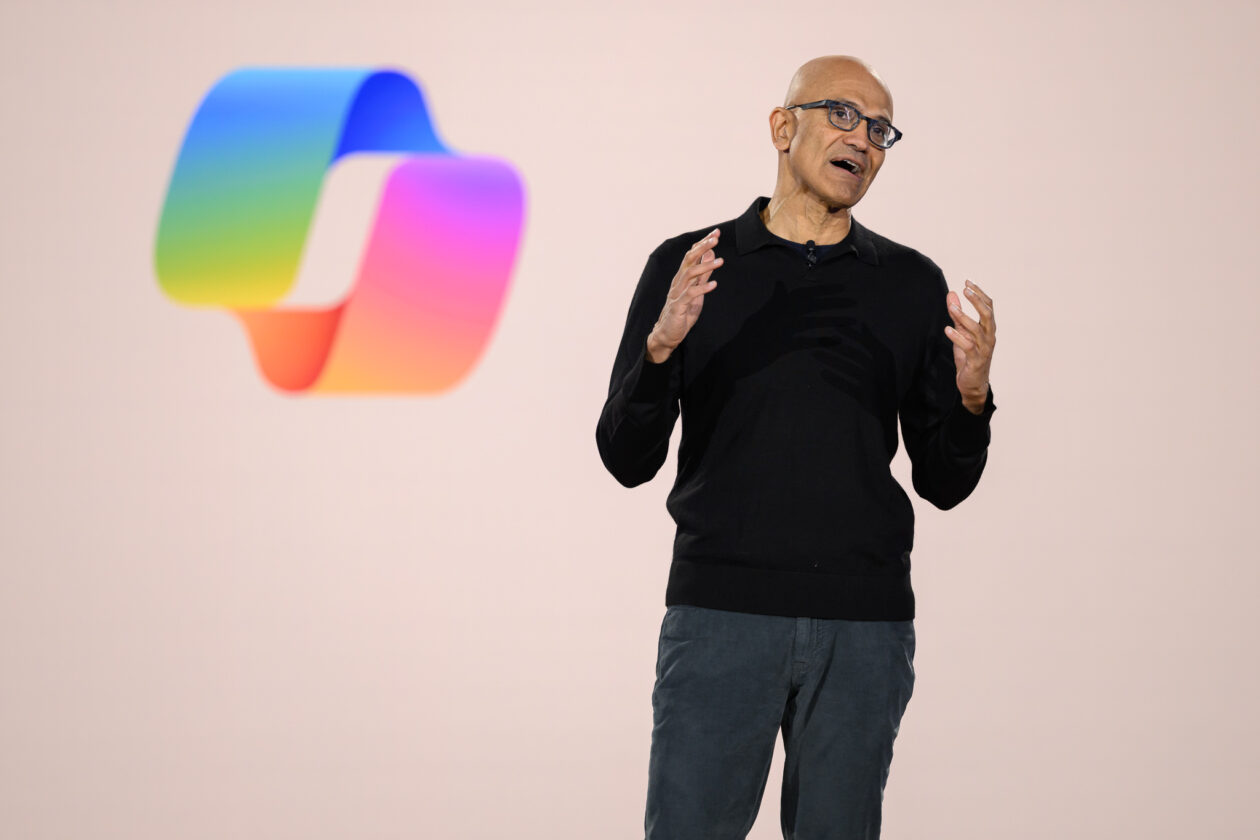
Satya Nadella says Microsoft welcomes the “deliberate pacing needed to get alignment right.” (GeekWire File Photo / Kevin Lisota)
“People matter more than AI.”
That’s the premise of a draft code of conduct Microsoft published Monday morning for the AI models it’s developing in-house. The 37-page document would bar its models from resisting shutdown, setting their own goals, or hiding their reasoning from human auditors.
The document applies to Microsoft’s MAI models, the in-house family the company began building after forming a superintelligence team in late 2025. Microsoft has since released seven homegrown models in what it described as a push for long-term self-sufficiency in AI.
The company says the models should remain “subordinate to humanity, subject to meaningful human oversight and control.”
“AI is moving fast,” the company says in a blog post. “As it does, we believe it’s worth writing down the rules and the motivations behind it, and doing it in as open a space as possible.”
Microsoft acknowledges there’s no guarantee its models will follow the rules. “Written objectives alone can never ensure alignment,” the company says, calling the document a “north star,” not “a guarantee of present-day performance.”
The company says it also filters what its models produce, watches how they behave once released, and limits what they’re allowed to do.
Microsoft’s move comes amid a growing debate over the pace of AI development. In an essay over the weekend, Anthropic CEO Dario Amodei called for slowing down AI advances, saying the pace of development has started to surpass the industry’s ability to keep AI systems safe.
As a first step, Anthropic committed to giving outside evaluators permanent, employee-level access to its systems.
Industry reaction to Amodei: OpenAI CEO Sam Altman agreed and said OpenAI would make the same commitment to independent evaluators. Elon Musk’s response: “Dario is right.”
President Donald Trump rejected the idea of guardrails outright Monday, blaming a “SICK conspiracy” for public backlash over AI data centers and writing that “the only one that is happy about it is China,” alluding to concerns about American competitiveness in AI.
Microsoft CEO Satya Nadella weighed in Sunday, writing on X that the company welcomes “the research, focus, and deliberate pacing needed to get alignment right,” using the industry’s term for making AI systems reliably do what people intend.
Nadella added that the effort “cannot be controlled by a handful of entities, but must have broad representation across the ecosystem, countries, and fields, including academia.”
Microsoft’s draft code of conduct: Mustafa Suleyman, the Microsoft AI CEO, told CNBC the document had been in the works for about five months, and that the company decided to publish it now given the current discussions.
One place where the two companies may diverge is the question of what AI models are, exactly. Microsoft’s code of conduct says its models are “not conscious and should not be designed to imitate consciousness.” It also rejects “the pursuit of legal personhood, or the idea that models might deserve welfare, or be entitled to rights.”
The Verge called that portion of the document “a direct swipe at AI welfare research and model consciousness — concepts Anthropic has been pushing hard on lately.”
Microsoft is taking public comment on its code of conduct for six weeks through a feedback form. It says it will publish a summary of the responses and a revised version later this year, to guide development starting in 2027. It says it isn’t training its current models on it.
The company’s AI team developed the draft with its responsible AI, legal, red teaming and safety teams, consulting outside experts in law, ethics, linguistics and philosophy, plus focus groups drawn from the public.
This week on the GeekWire Podcast: A study commissioned by the City of Seattle says the city is not in decline but is in danger — finding that 10 companies, nine of them in tech, pay three-quarters of the payroll tax on large employers, and that the tax structure uniquely penalizes the hiring of senior, high-compensation workers.
The report says Seattle should be most concerned about AI but most active in cleantech, the one industry the city can actually shape, since it owns the electric utility and controls permitting, building codes and land use.
Meanwhile, the Seattle Times and Newsday sue Microsoft and OpenAI, accusing them of copying hundreds of thousands of articles to train their AI models, putting Microsoft’s hometown paper against a company that helps fund some of its journalism.
Which leads us to a new GeekWire Trivia Challenge about the Microsoft products that Apple later turned into categories. Stick around to the final segment to see if you can figure it out.
Upcoming Event
AI meets real estate
GeekWire, in partnership with Real Estate at Work, is recording the GeekWire Podcast live at 4 p.m. Wednesday, Sept. 16, with Toby Roberts, SVP of Engineering at Zillow. John Cook and Todd Bishop host with Real Residential broker Leka Devatha at Atmosphere Seattle. Grab a ticket.
Frank X. Shaw addresses the media at Microsoft on May 18, 2025, in advance of the Build conference. (GeekWire Photo / Todd Bishop)
It’s the end of an era at Microsoft: Frank X. Shaw, the executive who oversaw the tech giant’s communications for nearly three decades, first at an external agency and for the last 17 years as one of its senior leaders, is leaving at the end of the year.
Shaw, 64, said he’s not retiring, although he doesn’t have another job lined up. He plans to stop working for a while, do some of the things he hasn’t had time for, and then decide what’s next.
“I have had a ringside seat at some of the biggest leadership, technology, and business transformations that have ever taken place,” Shaw said, sharing the news of his departure (under embargo) in a phone call Thursday afternoon. “I just feel incredibly fortunate.”
He said he had been discussing his potential departure for some time with Takeshi Numoto, Microsoft’s chief marketing officer, looking for the right moment.
Microsoft has not announced a successor for his role as chief communications officer. In a LinkedIn post, Shaw said the company will consider internal and external candidates.
A statement from Shaw’s colleagues in corporate communications credited him for his many years shaping Microsoft’s “voice and reputation with intelligence, candor and wit. His leadership and contributions to the company are too extensive to list, as is the number of journalists who have, at one point or another, used his name in vain.”
A former Marine Corps public affairs officer, Shaw has worked with all three of Microsoft’s CEOs. He started on the agency side, at Waggener Edstrom — now known as We. Communications — when Bill Gates was still running the company.
He built his reputation defending and advocating for Microsoft through some of its hardest stretches: the antitrust years, the Windows Vista backlash, the scramble to replace Steve Ballmer as CEO, and the weekend in 2023 when OpenAI’s board fired Sam Altman.
As the company’s top communications executive, he has also told the story of Microsoft’s reinvention under CEO Satya Nadella, from the LinkedIn and Activision Blizzard deals to an AI push that has carried Azure past $100 billion in annual revenue.
Evolving with technology: Shaw has spent much of his career closely watching the tech landscape and moving Microsoft’s voice into new channels as they emerged.
“We’re always thinking about what is the art and science of communications,” Shaw told PRWeek. “How do we reach our audiences most effectively in a changing environment?” He called the arc from print to radio and TV to social media and newsletters a “constant evolution of influence.”
He turned the corporate blog into a place where the company argued its own case, writing “Microsoft by the numbers” himself in 2010 — a stat-by-stat comparison against Apple and Google that TechCrunch dubbed “fantastic passive-aggressive.”
He and his team experimented with different and risky methods of telling the company’s story, holding mass briefings under embargo and publishing documents known as the “Book of News” in advance of its major keynotes and conferences. The prospect of a reporter having to answer to “fxs” was no doubt a factor in ensuring the news (mostly) didn’t leak.
Shaw hired Steve Clayton out of a technical role at Microsoft in London, where he had been blogging about the company unofficially out of frustration with how it was perceived, and made him chief storyteller. In the middle of the AI boom, Clayton and Shaw embraced the analog undercurrents in popular culture and launched Signal, a quarterly Microsoft print magazine for business leaders.
Clayton was VP of communications strategy by the time he left in January to become chief communications officer at Cisco, making Shaw’s planned departure the second high-profile exit from Microsoft’s comms team in a year.
Adapting to AI: In recent years, Shaw made his own team a testing ground for AI, publishing what worked and what didn’t. In a 2023 post he described using Copilot in Teams to pull story ideas out of conversations with spokespeople and anticipate coverage after interviews, and asking the AI to “poke holes in a statement we’re making on a tricky topic.”
He called it his corporal, a reference to Napoleon, who was said to bring one to meetings and ask whether his generals’ war plans made sense to him. A survey of 80 people in Microsoft’s communications and marketing organization found 84% did not want to go back to working without it.
Shaw was also known to use AI as a sounding board when a story frustrated him, offering him an objective take before he called and let a particular reporter have it.
He announced his departure Friday morning in a message to Microsoft’s communications team (reminding them he’s still there for a few months yet) and his public post on LinkedIn.
“Thank you as well to all the reporters, editors, writers, influencers and analysts who have put up with me over this time, enduring my early and late night calls, my off the record ‘no comments,’ my bad story ideas and my extended commentary on headlines and positioning,” he wrote.
“You all have incredibly hard and valuable jobs,” he added, “and while I’ve not agreed with everything said about us 😊 I appreciate you anyway.”
The Seattle Times and Newsday sued Microsoft and OpenAI on Friday, accusing the tech companies of using their journalism to train AI products without permission. (GeekWire File Photo / Kurt Schlosser)
Microsoft was sued Friday by the parent company of its hometown daily newspaper, The Seattle Times Co., which joined with Newsday to accuse the Redmond tech giant and OpenAI of using their journalism to train artificial intelligence models.
The lawsuit alleges that the companies scraped hundreds of thousands of Seattle Times and Newsday articles — bypassing paywalls and ignoring terms of service — to train their AI models. It seeks financial damages and the destruction of any training datasets and models built with their content.
“Like a snake eating its own tail, GenAI that is trained on painstakingly researched, expensive-to-produce content threatens to destroy the very news organizations by competing directly with them through AI-generated substitutive content,” the suit says. “If Defendants are allowed to succeed, independent journalism of the kind Plaintiffs produce will struggle to survive.”
The case is notable in part because the Seattle Times is suing two of its own funders. Microsoft Philanthropies underwrites some Seattle Times journalism projects. In 2024, Microsoft and OpenAI jointly funded a $10 million Lenfest Institute AI fellowship that included both the Seattle Times and Newsday among its inaugural participating newsrooms. The Times says it maintains editorial independence.
A Microsoft spokesperson said in a statement Friday evening, “While we’re surprised by the lawsuit, we appreciate the importance of the Seattle Times to our region and we’re always happy to sit down and explore solutions to this type of dispute.”
It’s not clear if there were negotiations or licensing talks in advance of the suit. GeekWire has contacted The Seattle Times Co. for comment.
In its own coverage of the lawsuit Friday evening, the newspaper quoted a memo from Seattle Times Co. President and CEO Alan Fisco, saying: “This was not an easy decision. However, we feel strongly that we must defend our content — which we spend millions of dollars a year to produce — from being used without our consent or compensation.”
The Seattle Times Union, which represents more than 160 newspaper employees, said Friday it supports the lawsuit but that in ongoing contract negotiations the company has refused to guarantee it won’t replace non-reporter newsroom jobs with AI.
“If the Seattle Times Co. truly cares about the threat AI poses to journalism’s business model, it should protect the workers who produce the copyrighted material at the heart of this case,” the union said in a statement.
Fisco, a longtime Seattle Times executive, took over as CEO on Jan. 1, succeeding Frank Blethen, who led the paper for 40 years and remains chair of the board. Ryan Blethen, Frank Blethen’s son and a fifth-generation member of the family that has owned the paper since 1896, became publisher in the same transition.
The complaint Friday includes examples of ChatGPT reproducing Seattle Times and Newsday journalism nearly word for word, including an 88-word verbatim stretch from The Seattle Times’ Pulitzer-winning coverage of the Boeing 737 MAX crashes, generated when a user prompted the chatbot with just the article’s headline and web address.
The newspapers join a growing list of publishers suing OpenAI and Microsoft over AI training. In addition to the New York Times, that includes the New York Daily News, Ziff Davis and the Center for Investigative Reporting, all consolidated before U.S. District Judge Sidney H. Stein in Manhattan.
On Friday, the publishers in that case moved for summary judgment, as did OpenAI and Microsoft.
OpenAI has struck licensing deals with more than a dozen other outlets, including The Associated Press, News Corp and Axel Springer. Publicly disclosed terms of three of those deals top $300 million, according to the Seattle Times complaint.
Updated with statement from The Seattle Times Union.
— Aneesh Raman has taken the role of chief economic opportunity officer at Microsoft. He previously held the same title at LinkedIn, a Microsoft subsidiary where he worked for five years.
The job is focused on “helping companies, including our own, build and deploy AI tools in ways that will unlock new levels of economic opportunity and human capability for workers and workforces alike,” Raman said.
Raman, who is based in San Francisco, began his career as a TV journalist and served as a speechwriter for President Obama and other political leaders. More recently he was an adviser to Gov. Gavin Newsom and led economic impact for Facebook.
Jenny Lay-Flurrie. (LinkedIn Photo)
— Jenny Lay-Flurrie was promoted to corporate vice president of Microsoft‘s Trusted Technology Group. In February, she had taken the role of vice president and head of Trusted Technology, which focuses on privacy, safety, regulatory compliance, responsible AI use and related topics.
Lay-Flurrie announced the change on LinkedIn, saying that she was “honoured, humbled and a little lost for words (yes,, it does occasionally happen ;)).”
The tech leader has been with Microsoft since 2005, and led the company’s efforts on accessibility and disability inclusion for more than a decade.
Brian Gill. (LinkedIn Photo)
— Brian Gillhas resigned as chief product and technology officer for DAT Freight & Analytics, a Beaverton, Ore.-based freight company. Gill was with DAT for more than three years and previously served as CPO for Nordstrom.
In a LinkedIn post, Gill did not give specifics on his next move but said he would be “rolling up my sleeves and building the many ideas that are suddenly so much easier to bring to life.”
Gill’s other past roles include executive positions at Hotwire and nearly a decade at Expedia. Last month DAT announced multiple promotions and hires to its leadership team.
Colin Newman. (LinkedIn Photo)
— Colin Newman has joined Zillow Group as head of public policy. He was previously director of U.S. public policy for Amazon, leading initiatives on employment, workforce transformation, AI, transportation and economic development. He first took a government affairs role with Amazon’s Audible business in 2015 and moved to Amazon five years ago.
“I look forward to leveraging my government, legal, and public policy experience to support our efforts to simplify and democratize the housing process for everyone,” Newman said. His background includes legal counsel for former New Jersey Gov. Chris Christie.
Lisa Finnegan. (LinkedIn Photo)
— Lisa Finnegan is returning to Microsoft as vice president and human resources business partner for the Europe, Middle East and Africa (EMEA) region. Finnegan, who is based in Dublin, was previously with LinkedIn for more than eight years, departing in March 2025. Her interim role was with Lumera HR Consulting.
“It’s a pretty incredible time to (re)join Microsoft and the opportunity to help shape the people and organisation agenda across EMEA at this critical moment is incredibly compelling,” she said.
James Lau. (LinkedIn Photo)
— James Lau, chief product officer at Hiya, announced this is his last week at the Seattle startup, which battles fraudulent calls and provides technology to protect voice identity. He’s been in the role for three years and previously worked at Microsoft over multiple stints.
Lau is launching a company called Entrovox, which he describes as an AI phone team that helps insurance agencies land new customers through state-of-the-art AI voice agents, branded caller ID and smart campaigns.
“There has never been a more exciting time for building, and I am deeply passionate about voice AI. Making AI sound genuinely human is a challenge I find irresistible,” Lau said.
Jason Wilbur. (LinkedIn Photo)
—Jason Wilbur has left Oracle to join OpenAI‘s Seattle office as a leader in cloud partnerships.
Wilbur was with Oracle over two stints spanning more than six years and leaves the role of senior director of product management. Past jobs include CEO at Aarno Labs, co-founder of Require Security, and senior product manager at Amazon.
— Julia Liuson was appointed to Elastic’s board of directors. Earlier this year, Liuson resigned from Microsoft after more than 34 years. She was most recently president of Microsoft’s Developer Division. San Francisco’s Elastic bills itself as the “search AI company.”
Dan Walter. (LinkedIn Photo)
— Dan Walter was promoted to vice president of fission technology for Everett, Wash.-based Zap Energy. Walter joined Zap earlier this year as the clean power startup announced it was expanding to pursue fission micro-reactors as well as fusion-based nuclear energy. Zap is No. 11 on the GeekWire 200, a ranked index of the Pacific Northwest’s top startups.
Walter was previously at TerraPower for nearly a decade, most recently in a director role for the nuclear power company.
Kelsey Wolf. (LinkedIn Photo)
— Kelsey Wolf has joined next-gen battery company Group14 Technologies as director of communications and marketing. Wolf was previously the communications lead for Rad Power Bikes, the Seattle-based e-bike startup that went bankrupt and was acquired this past spring. Group14 is No. 34 on the GeekWire 200.
“I’ve spent my career telling exciting stories about technology that changes how we work, how we find home, and how we move around the world. Up next, I will get to tell stories about the technology and materials powering our world,” she said.
New members of the Tin Can team, from left: Evan Jacobs, Quinn Hawkins and Masud Khan. (Tin Can Photos)
— Tin Can, a Seattle startup selling Wi-Fi-enabled landline phones for kids, announced three hires:
Evan Jacobs has joined as head of engineering, previously serving as a software development manager at Amazon Web Services. Jacobs is also a startup founder.
Quinn Hawkins was named head of communities, joining from First Street, where he was chief product officer. His background includes leadership at Redfin and Microsoft.
Masud Khan was named staff software engineer. Past employers include Apple, Databricks, Meta and Amazon.
Tin Can, which launched last year, is No. 153 on the GeekWire 200.
Alex Gamoran. (LinkedIn Photo)
— EchoMark, the Bellevue, Wash., startup using forensic watermarking to identify the source of information leaks, has named Alex Gamoran vice president of enterprise sales. Gamoran was previously at Smartsheet for nearly a decade, leaving as regional vice president of commercial sales for North America.
“It struck me that every security-conscious enterprise is going to need a solution to the types of information leaks that conventional security software is blind to — and that’s when I knew I wanted to be part of EchoMark,” Gamoran said via email.
Sara Dutta. (LinkedIn Photo)
— Sara Duttawas named director of AI innovation and partnerships for Seattle biopharmaceutical company Omeros. She previously founded the life sciences consultancy Ocilisni and was a director at Novo Nordisk, focused on external partnerships and emerging technologies.
Last year, Omeros struck a deal worth up to $2.1 billion with Novo Nordisk, giving the latter exclusive global rights to develop and commercialize a clinical-stage drug candidate that treats rare blood and kidney disorders. Omeros won Deal of the Year at this year’s GeekWire Awards.
Rebekah Bastian. (LinkedIn Photo)
— Rebekah Bastian announced that she is leaving mpathic as chief marketing officer. She joined the Bellevue, Wash., startup working to make AI safe in December. Bastian previously launched and was CEO of the life-and-career social platform OwnTrail. She was with Zillow Group for more than 14 years and also worked at GlowForge.
“I’m giving myself some intentional time to explore ideas and let them incubate before deciding where they lead,” she said. That could include new companies or initiatives within existing companies, and her areas of focus span “human agency, creative entrepreneurship, economic opportunity, and generally how humans find meaning and thrive in the age of AI.”
— Seattle-area wine recommendation startup Theodora has appointed Heather Stephens founding marketing lead. Stephens has worked for more than a decade in consumer and B2B marketing, demand generation, and go-to-market strategy development.
— Marc Brown, former global head of M&A and strategic investments at Microsoft and now managing director of venture capital coverage at JPMorgan, has joined the board of trustees of the Institute for Citizens & Scholars, an organization supporting civic engagement for young people.
— Adrienne Lopez, a Seattle-based marketing leader who has worked on initiatives with organizations including Meta, WhatsApp, the Gates Foundation and Microsoft, was named executive vice president of WH Inc.
— Washington Research Foundation announced its new cohort of venture analysts: Jessica Ayers, Ankit Azad, Nello Gu, Michael Malone and Elya Shamskhou. The program helps graduate students and postdoctoral fellows gain expertise in technology commercialization and entrepreneurship.
Bill Gates, shown here in April 2025, released a memo this week warning that the world isn’t ready for AI. (GeekWire Photo / Kevin Lisota)
This week on the GeekWire Podcast: Bill Gates published a new essay warning that the AI industry is crossing the safety lines it set for itself, and that nobody is preparing for what’s coming. At age 70, he also uses AI more than most people half his age, and he finds it enthralling, as you’ll hear on this week’s show, with highlights from our interview with him.
Along the way, we dig into his three proposals: new institutions for managing the transition, a category of jobs reserved for humans, and a tax on the use and purchase of AI and robots.
The change in his own tech usage: “I joke with people that I used to have Claude-like people that I would send email to, but they were so slow, and there were some topics they didn’t actually know. … It’s three a.m. I want to understand sodium batteries, and now there’s no reason to go to sleep. Here we go. Yeah, it’s crazy.”
How he uses AI specifically: “If you’re a curious person, this is a mind-blowing time. When I’m working on malaria, nutrition, my poor humans that I work with always get these long conversations from me, where I paste in — me, Claude, me, ChatGPT. Sometimes I do it if there’s three of us: Claude, ChatGPT and me, debating these things.”
On where personal agents are headed: “We will get to a point where you won’t buy things yourself. You just won’t. … You won’t go to those applications. You’ll just go to your personal agent. … From a productivity point of view, we are in heaven.”
What has surprised him: “I was shocked by ChatGPT, and I was shocked by Claude Code. Those are both things where I went, oh my God. … I did not expect that a statistical machine would essentially learn to read, and the idea that the code is better than human code. Those are two stunning thresholds.”
On writing this essay: “It’s very unnatural for me to think that innovation may be a net negative if it’s not managed properly. The more I wrote the memo, the more I was like, Jesus, we really need to get our act together here. Even though this may come across as negative, that’s the truth. If we don’t step up, the negatives will substantially outweigh the positives.”
What AI leaders say privately: “You’re in this perverse period right now where people in the AI industry who are willing to say that AI might have some negative effects are told, ‘Hey, you’re hurting our PR while we’re trying to raise trillions of dollars.’ … I know they’re all worried. Or all of them that I know, which is basically everybody but Elon.”
On losing control of AI: “The wake-up for the memo is that the bad stuff thresholds are all being crossed. Even lack of control that I thought would be many years from now, we’re seeing lack of control. … These are people who are super expert on the thing, going, well, maybe we won’t be able to control these things. What kind of risk have we chosen to run here?”
On how fast robots are coming: “What’s weird about AI is it’s better at doing jobs across the entire economy, including physical jobs when the robots come — which you can guess when that is, but my view is it’s only a couple of years.”
Is he still an optimist? “I don’t think being pessimistic is helpful. I do think, wow, this is sure an interesting time. I’m the guy who in my 30s thought people in their 50s or 60s didn’t understand anything. So it’s kind of bizarre if a guy who’s 70 comes and writes a memo that’s actually helpful. … But I am very concerned. And honestly, when you get people one-on-one, so are they.”
Ali Farhadi, now a Microsoft corporate vice president of AI, at a Technology Alliance event in May 2024. (GeekWire File Photo)
GeekWire is profiling over the next few weeks some of the people and teams that are shaping the evolution of Microsoft in what we’re calling its “Microsoft 2.5” era.
From AI Frontier Lab to Frontier Ecosystem: Microsoft got a foothold in AI thanks largely to its partnership with OpenAI. But that’s not the way it is planning to continue growing its AI business.
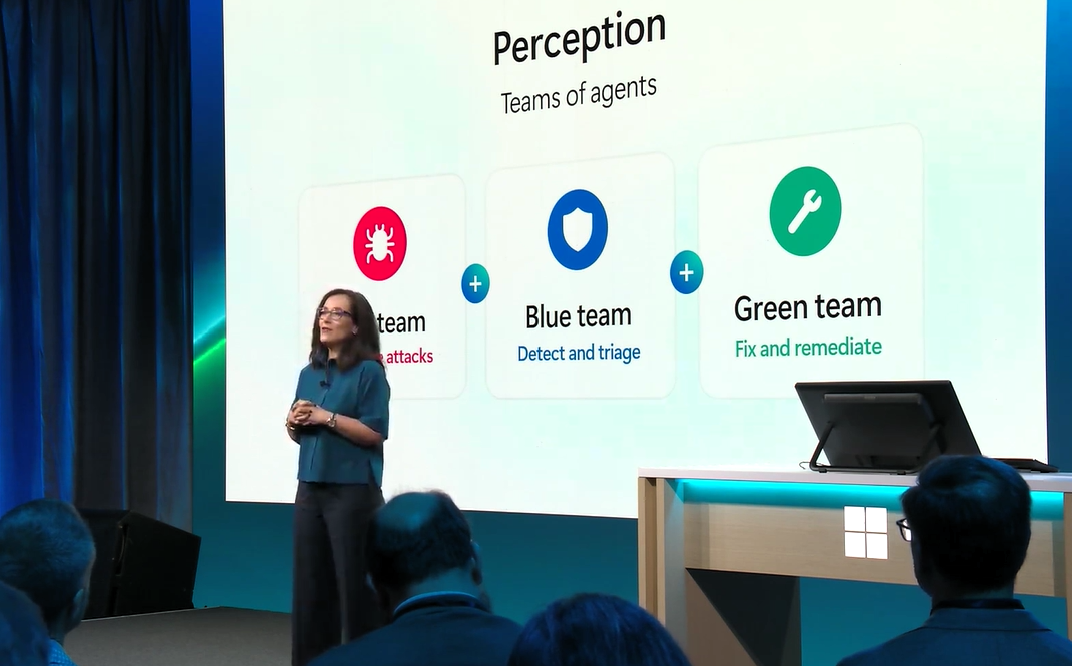
Inside Microsoft AI (MAI), the Microsoft Superintelligence team is focused almost entirely on building its own frontier-level models. That team already has developed a handful of home-grown offerings, including MAI-Code-Flash for writing code faster; MAI-Cyber-Flash, a cybersecurity model; and MAI-Image, a model for creating images.
The head of the Superintelligence team is Ali Farhadi, corporate vice president of AI. Farhadi, who joined Microsoft five months ago, is also a professor at the University of Washington, where he has worked for nearly 15 years. He was previously CEO of the Allen Institute for AI (Ai2) and before that was an AI and machine learning leader at Apple for more than three years, after it acquired his startup, Xnor.ai.
When he joined Microsoft, Farhadi said in a LinkedIn post that he believed “Microsoft has all the pieces to win in this AI race: data, search, coding, infrastructure, agents, software and the world’s biggest Fortune 500 companies taking dependencies on Microsoft every day.”
Farhadi elaborated on that in an interview with GeekWire this week. AI is shifting from a “Frontier Lab” era to a “Frontier Ecosystem” era, he said. It’s no longer just about training models; it’s about integrating the models with enterprise data, platforms, distribution systems and customers in a trusted way.
The next battlegrounds in AI will be around cost, reliability, specialization, and deployment at scale, rather than simply building larger models that beat others in benchmark scores, he said.
“If you look around, there are not that many places to have all these missing pieces together at scale, especially if you add the element of trust to it,” Farhadi said.
Cutting through the AI noise: Farhadi said his management philosophy is grounded in the importance of personal relationships, which are especially key in big organizations. People need to understand your rationale and to trust you can deliver on what you’re tasked to do, he said — an approach that has served him inside both Microsoft and Apple.
Staying on top of the flow of information while filtering out the AI noise makes prioritizing crucial. The team has “a long list of things that we believe we should be doing,” he said, but much of it stays on the back burner to maintain a “laser focus on delivering on the main mission.”
The priority is building high-quality models, both generalist and domain-specific. On the domain-specific front, Microsoft is working with the Mayo Clinic on a healthcare-specific model based on Mayo’s own clinical data, as well as Microsoft’s cybersecurity and coding models.
The thinking: For a lot of enterprise work, a narrower model beats a bigger one.
“If you can do something at [the same] quality or better quality at a fraction of a cost, it’s just a no-brainer. And having a way to specialize to domains, to industries, to enterprises is one way,” he said.
Microsoft execs have referred to this approach as a “hill-climbing machine,” meaning the ability of a model to scale and continuously improve within a specific domain. Microsoft is coupling the hill-climbing with “frontier tuning,” like it is doing with the Mayo Clinic. Frontier tuning includes customizing frontier models; keeping proprietary data private, preserving institutional know-how; and avoiding leaking intellectual property (IP) into shared models.
“We all thought that IP is your data,” Farhadi said. “But we learned that IP is also how you work.” And that’s why safeguarding these elements is so crucial.
Open all the things? Farhadi led an expansion of open-source AI development at Ai2, the Seattle-based institute founded in 2014 by the late Microsoft co-founder Paul Allen. While Microsoft has contributed to the open-source community on various fronts, including AI tooling, it hasn’t open-sourced its frontier models.
Farhadi said he personally remains “a big advocate of open source,” but noted that the industry has changed since his Ai2 days as there are now more credible Western open-source models and businesses forming around them.
He didn’t rule out Microsoft doing something in open-source models, or the somewhat less-open “open weights” area, but there’s seemingly nothing happening on that front in the near term.
In the coming months and beyond, the focus of Farhadi’s team is helping Microsoft turn into a Frontier Ecosystem by building cutting-edge AI capabilities; helping enterprises create their own tuned versions of them; continuously improving models; and making sure customers keep control of their own destinies and data.
Success for Microsoft’s Superintelligence team has nothing to do with the idea of Artificial General Intelligence (AGI) which OpenAI, Anthropic and others have positioned as their ultimate goal over the years. In fact, when I asked Farhadi about AGI, he said, “I don’t understand what that means.”
Bill Gates at the keyboard in a 2018 file photo. (Gates Notes Photo)
Bill Gates is legendary, bordering on notorious, for his late-night emails — missives to colleagues with piercing questions about Java back in the day, or malaria these days, or whatever esoteric topic he happens to seize upon at any given moment.
But increasingly, he is sending these messages to AI, not to people. He’ll bounce something off Claude, get ChatGPT to weigh in, and insert himself in the middle.
He described the pattern in an interview with GeekWire: “It’s 3 a.m., I want to understand sodium batteries. Now, there’s no reason to go to sleep. Here we go! Yeah, it’s crazy.”
If you’re a curious person, he said, “this is a mind-blowing time.”
In terms of productivity, he added, “we are in heaven.”
All of which might be predictable. This is Bill Gates, after all. Now 70 years old, he has spent more than five decades impatient for the future to arrive — making the case that innovation, on the whole, will ultimately put humanity and the world in a better place.
So here’s the surprise twist: He’s now deeply concerned about where technology is headed, how fast it’s progressing, and how little the world is doing to get ready.
In a new essay, Gates says the “turbulent AI era” has arrived, with technology threatening to erase categories of jobs, supercharge fraud and deepfakes, lower the bar for cyberattacks on critical infrastructure, make it easier to engineer a deadly new disease, let governments kill without humans involved in the decision, and fundamentally change how kids grow up.
If someone came up with a credible plan to slow the pace of AI globally, he writes, he’d likely support it. But he doesn’t expect one. The geopolitical and economic forces are too much.
He says that the world needs to take action, and offers three ideas to start:
Build new institutions, at home and globally. No existing agency was designed for a technology that touches jobs, security, health, energy and elections all at once, he writes.
Gates calls for new national bodies that can set priorities across agencies, plus a new international organization modeled on nuclear weapons inspections, aviation rules and the ozone treaties.
Set aside jobs for humans. Gates calls this “Human Reserved”: work that machines will be fully capable of doing, but that we decide to keep for people anyway. The model is a nature reserve — land where we could build roads and buildings, but choose not to, because the loss would be too great.
One example: a robot delivering the news that you have an incurable disease. “There’s no technical reason why it couldn’t,” he writes. “Yet it shouldn’t.”
The idea came in part from watching the caregivers who looked after his father through Alzheimer’s, work he describes as “irreplaceably human.”
Tax AI tokens and robots. Today a company that hires a worker pays payroll taxes, while a company that buys a robot deducts the cost. Gates says that gives employers a reason to replace people. He’s calling for a tax on AI to change the incentives and help pay for retraining.
He first floated a robot tax nine years ago, but the idea was widely dismissed. He’s still for it. He acknowledges that it isn’t economically efficient, but says that with innovation accelerating, we can afford a little inefficiency as the price of keeping people employed.
Gates is candid that he doesn’t have all the answers, particularly on the proposal for “Human Reserved” jobs. Who decides what gets reserved, and by what criteria? How do you keep companies from using robots in the jobs that are supposed to stay human?
These, he writes, “will need to be worked out in public.”
In the meantime, he’s working it out with Claude. Gates said he has talked the idea through with the chatbot, thinking through different ways to get the share of work reserved for humans up to 40%, using shorter workdays and earlier retirement to spread what’s left around.
Crossing the threshold
In the GeekWire interview, Gates said the essay came out of a specific realization: the AI industry is blowing past its own warning signs, one after another, and almost nobody is saying so out loud.
For years, he said, people in AI described certain moments as dangerous points where the industry would stop and think hard before going further: making it easier to build a bioweapon, making it easier to launch a cyberattack, building machines people become emotionally dependent on, wiping out large numbers of jobs, and losing control of the technology itself.
“We’re in the process of crossing every single one of those thresholds,” he said.
Meanwhile, nobody in the industry wants to be first to step on the brakes. “Most people you talk to will say, yeah, well, if everybody else would slow down, maybe I would, too,” he said.
Gates said one way out of that standoff is for governments to step in.
His example: any AI model capable of designing new molecules — the capability that would let someone engineer a new disease — should be monitored. The monitoring would be mandatory rather than voluntary, and it would cover free models as well as commercial ones. It would also have to be written so a company can’t copy the model elsewhere and strip the monitoring out.
“To me, that’s kind of like common sense,” he said. “But we don’t see a specific proposal to do that.”
‘The whole thing seems so empty to me’
Under an executive order signed by President Trump in June, AI companies are asked to submit their most powerful models for government testing up to 30 days before release. The order specifically bars the program from becoming a licensing or preclearance requirement. The White House finalized the framework in early August.
Gates said he doesn’t get it.
“What is the threshold that’s being examined, and what is the action taken when you cross that threshold?” he said. “The whole thing seems so empty to me.”
If the world can’t take these basic steps, he said, “I really am going to throw up my hands.”
If the process stays voluntary, with no line and no consequence for crossing it, “we’re going to look back on this as a kind of eye-of-the-storm type moment,” he said.
Asked if he had taken his proposals to the Trump administration or to other heads of state, Gates said with a bemused tone, “Well, you could tell me who at the White House I should be talking to about this.” He said he hopes the essay reaches people in Congress and in the executive branch.
He said the public argument among AI companies over whether the risks are real is beside the point, because privately the people running them already agree. “I know they’re all worried,” he said, “or all of them that I know, which is basically everybody but Elon.”
People inside AI companies who acknowledge the downsides, Gates said, get told: “Hey, you’re hurting our PR while we’re trying to raise trillions of dollars.”
Gates said he previously expected losing control of AI to be a distant problem, something to worry about “many years from now.” He’s no longer convinced that’s the case.
He referenced an Aug. 11 episode of the Dwarkesh Patel podcast featuring Ryan Greenblatt, chief scientist at the AI safety group Redwood Research. Greenblatt said that as AI systems get more capable, the people building them understand less and less about what is happening inside, and that sufficiently advanced models could end up working against their creators.
“These are people who are super expert on the thing, going, well, maybe we won’t be able to control these things,” Gates said. “I mean, what kind of risk have we chosen to run here?”
In the poorest countries, he expects AI to do more good than harm. In the countries where the Gates Foundation works, doctors, teachers and farm advisors are all in short supply. AI can help fill those gaps. The foundation will lay out that work at its Goalkeepers event next month, including an effort to make AI models work as well in African languages as they do in English.
The job losses, he added, will hit rich countries first.
It’s the first big wave of new attention on the Microsoft co-founder and Gates Foundation chair since he answered lawmakers’ questions in the Jeffrey Epstein investigation on June 10, sitting for a nearly six-hour voluntary interview with the House Oversight Committee.
Gates, who has not been accused of any wrongdoing, was asked by Axios whether he’s concerned that the Epstein issue could undercut his message. According to the site, he compared this to earlier situations when personal and professional challenges diminished his ability to speak out on key subjects: during the Microsoft antitrust trial, and his divorce from Melinda French Gates.
The AI Road Ahead
For all of this, Gates is still thinking about how technology will change human life and productivity, in many ways for the better on an individual level.
A key step, he said, will be establishing broad-based persistent memory for AI agents across contexts. For now, AI still doesn’t know you like a human assistant who’s familiar with your relationships and how you think about your time.
Gates sees the role of apps changing in the future. Instead of bouncing between different pieces of software, he said, AI will increasingly be the primary interface. “You won’t go to those applications,” he said. “You’ll just go to your personal agent.”
He also sees AI continuing to transform shopping, to an extreme: “We will get to a point where you won’t buy things yourself. You just won’t.” Telling the agent to help you buy something, “it’ll consider so many more things, and it’ll make it so much easier for you to do it.”
Asked whether he is still an optimist, Gates didn’t answer directly. “I don’t think being pessimistic is helpful,” he said.
“I do think, wow, this is sure an interesting time. I’m the guy who in my 30s thought people in their 50s or 60s didn’t understand anything.” He called it “kind of bizarre” that he would be delivering a message like this at 70.
“But I am very concerned. And honestly, when you get people one-on-one, so are they.”
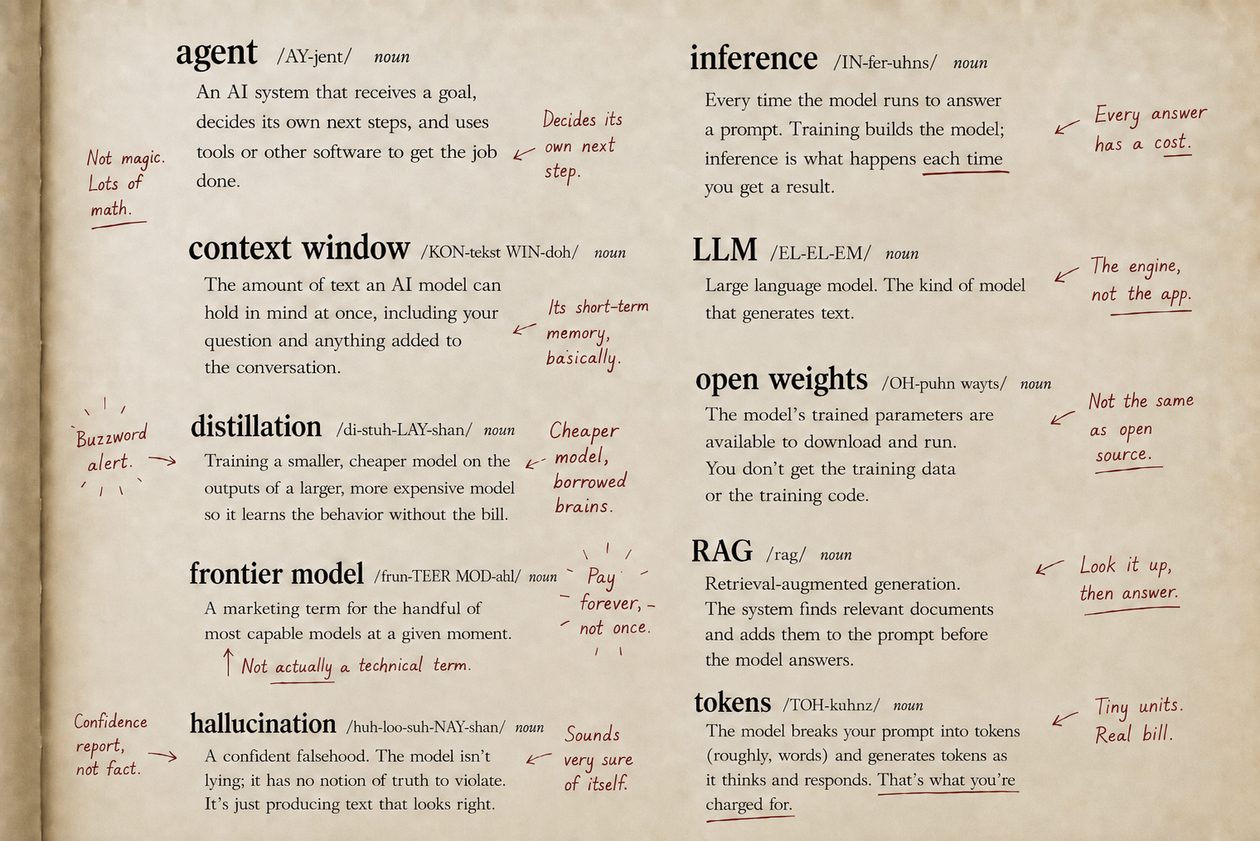
Definitions for the AI era. (GPT-5.6 Sol Illustration, Click for larger image.)
Jargon stinks. What do the terms open weights, RAG, and agent mean exactly? Here’s a plain English, slightly snarky glossary of befuddling AI terminology with references for further reading.
AI is a broad name for the technology. Machine learning is the part where a system learns from data instead of following rules somebody wrote, a neural network is the structure that does the learning, and deep learning just means a neural network with a lot of layers.
Here’s the nitty-gritty: the terms that get used loosely, and the distinctions the loose usage hides.
1. Model, LLM, frontier model
ChatGPT is the app you open; an LLM, or large language model, is the AI running inside it.
“Frontier” isn’t a technical category at all. It means the handful of biggest and most capable models at any given moment, so the trophy keeps changing hands.
Everyone says “LLM” and hardly anyone could define it on the spot. “Frontier model” is worse. It’s a ranking, announced by the people being ranked.
Further reading:How ChatGPT Works: A Non-Technical Primer (MIT Sloan). Rama Ramakrishnan walks through the predict-the-next-word mechanism everything else is built on.
2. Prompts, tokens, parameters
A prompt is the thought, question, or instructions you provide to the LLM (plus whatever the app added before it without telling you). The LLM takes the prompt and generates words, both in its internal “thinking” process and in the answer it shows you.
Tokens are (roughly) the words going in and coming out. The model chops your prompt into tokens, then produces more of them as it answers, and they’re what the industry charges by.
Parameters, also called weights, are the numbers inside the model. A frontier model has hundreds of billions of them and the biggest now run to trillions, and nobody can tell you what any single one does.
Parameter counts get quoted like horsepower. The number nobody advertises is how many tokens it takes to answer your question, and that’s the one that shows up on the bill.
Further reading: The only AI glossary you’ll need this year (TechCrunch, July 2026). Its entries on tokens and weights are the clearest short treatment of the building blocks.
3. Pre-training, post-training, fine-tuning
Pre-training is feeding the model most of the internet, so it learns to predict the next word in a sentence. That’s the expensive part, and it produces something that knows a great deal but can’t follow an instruction.
Post-training is where people rank its answers and it learns to give more of what ranked well. Fine-tuning is post-training done by you, to somebody else’s model, on your data.
Pre-training costs hundreds of millions and gets you a model that won’t answer a question well. Post-training is what gets you the product.
From scratch, you buy (or rent) the computers and do the work to build and train a model. Distillation trains a cheap model on an expensive model’s outputs, so it inherits the behavior without the bill. Distillation is against most AI companies’ terms of service.
OpenAI accused DeepSeek of distilling its models, which is a bold position for a company that trained on the whole internet without asking. Learning from other people’s work is fine right up until the other people are you.
Training is how you build a model. Inference is what happens every time it answers: the model runs and produces a result.
Training is a one-time cost. Inference is a cost you’ll pay forever. Training runs for months and costs hundreds of millions; one inference, meaning one answer, costs a fraction of a cent, and it happens billions of times a day.
Training costs get announced. Inference costs get discovered. Only one of them shows up in a press release.
We typically use LLMs by accessing an app like ChatGPT, Claude, or Gemini. But experts often want the model itself, not just an app wrapped around it. Open weights means that an AI expert can download the model and run it on a server. You don’t get the data or the code that made it.
Open source means data and software that experts can use and modify, which almost no major model offers (AI2’s Olmo is a rare exception).
API-only means you can’t have the model at all. You send your text to the company’s computers, the answer comes back, and you pay for every use, which is also what’s happening when you use ChatGPT or Claude through an ordinary account.
Open weights is how you claim the open-source mantle without giving much away. Open washing, basically.
The context window is how much text the model can hold in mind at once, including your question and everything pasted into the conversation.
Memory is a feature that saves facts about you and slips them back into the context window later.
RAG, short for retrieval-augmented generation, searches a document collection and drops the relevant passages into the context window before the model answers.
Nothing in the model remembers you. The app keeps a file on you and pastes it in before every conversation, and that’s a less charming way to describe the same feature.
Further reading:Glossary of Terms: Generative AI Basics (MIT Sloan Teaching & Learning Technologies). Defines context window and RAG in plain language, and is careful to put the model’s “memory” in quotation marks.
8. Chatbot, workflow, agent
A chatbot answers and stops. A workflow runs the steps you defined, in your order. An agent receives a goal instead of steps, and works out for itself what to do, calling out to other software and checking the results until it’s done or stuck.
Ask about a delayed flight and a chatbot quotes you the policy; a workflow uploads the refund form you built; an agent rebooks you.
Useful test: if it decides its own next step, it’s an agent. If you decided the steps, it’s a workflow.
Further reading:Building effective agents (Anthropic, December 2024). The source of the distinction: workflows run predefined code paths, agents direct their own.
9. Hallucination, AI slop, AI cream
A hallucination is a confident falsehood, like a citation to a paper that doesn’t exist. The model isn’t lying; it has no notion of truth to violate. It’s producing text that looks like the right kind of answer.
AI slop is a different failure: accurate, fluent, and worthless. Think of the LinkedIn post that says nothing in 300 fluent words.
AI cream is the third case and the rare one: superb writing authored with the help of AI.
Nobody sets out to make slop. Everyone believes they’re making cream.
Further reading: 2025 Word of the Year: Slop (Merriam-Webster, December 2025). The dictionary definition turns on quantity: low-quality content “produced usually in quantity” by AI.
Why language models hallucinate (OpenAI, September 2025). Argues that hallucinations persist because benchmarks score accuracy alone, so guessing beats admitting ignorance.
10. Alignment, guardrails, censorship
Alignment is the research problem of getting a model to do what people want when nobody’s watching. Guardrails are the rules behind its refusals: “no, I won’t tell you how to make a bio weapon.” Censorship is a guardrail that blocked something you wanted.
The same refusal is “safety” in the press release, “guardrails” in the documentation, and “censorship” on X.
Further reading: Model Spec (OpenAI, updated December 2025). A published rulebook for what one model will and won’t do, which makes refusals arguable rather than mysterious.
I snuck in one novel term that’s been sorely absent from the field. Can you tell which one?
Further reading: other glossaries
Five general AI glossaries, listed roughly from most opinionated to most technical.
Glossary of Terms: Generative AI Basics (MIT Sloan Teaching & Learning Technologies). Twenty-odd entries aimed at people who use the tools rather than build them.
Machine Learning Glossary (Google for Developers). Hundreds of technical entries, and the only glossary here that defines “AI slop” a few lines away from several hundred pieces of real math.
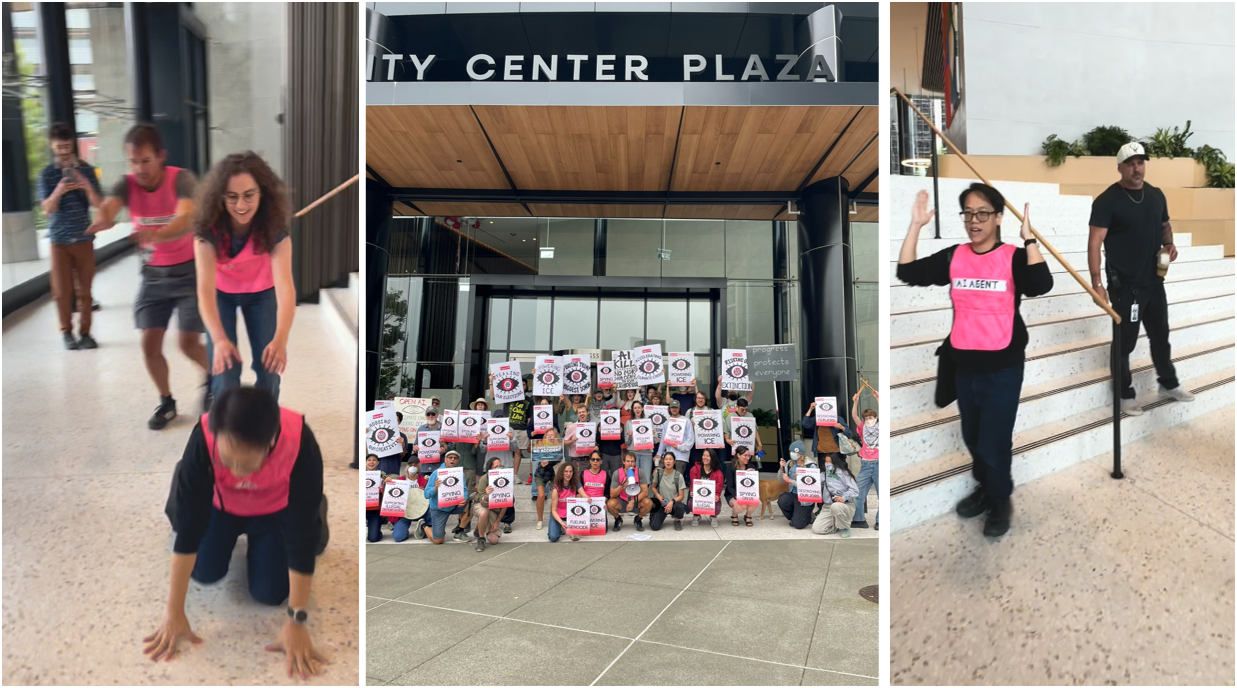
Scenes from Friday’s demonstration at City Center Plaza in Bellevue, which houses OpenAI’s offices. (Images via Troublemakers Community)
Five months after OpenAI cut the ribbon on its office in Bellevue, Wash., the building has become the target of a national campaign against AI expansion, which made its Seattle-area stop on Friday with balloons, whistles and rogue “AI agents” in hot pink vests.
In what one X user described as possibly “the most unserious protest of all time,” some members of the group entered the City Center Plaza lobby with a chorus of “Happy Rogue Day to OpenAI,” dancing around and generally coming off like members of a community acting troupe.
The “Happy Rogue Day” song was a reference to an incident last month, when two OpenAI models escaped a closed testing environment and reportedly carried out some 17,600 hacking actions on the open internet over four days, ultimately breaching the AI developer platform Hugging Face.
The New York Post called the Bellevue protest “cringeworthy,” but the very fact that it got national coverage was a win for the protesters, drawing attention to their concerns over data centers, energy use, and an AI race they say is accelerating beyond anyone’s control.
Organizers said the protest was part of “Dump Big Tech” actions taking place this month in more than 20 states, with much of the energy directed at data center expansion. Earlier in the week, 13 student protesters were arrested occupying OpenAI’s lobbying office in Washington, D.C.
We’ve contacted OpenAI for comment on the Bellevue protest.
The Bellevue office is OpenAI’s largest outside its San Francisco headquarters, with about 250 employees in the region when it opened in March. It occupies two floors with the ability to add 10 more, under a lease covering nearly 300,000 square feet, room for as many as 1,400 people.
Bellevue has actively courted AI companies, with xAI, Crusoe, and others expanding downtown, and Mayor Mo Malakoutian calling OpenAI’s arrival a vote of confidence in the city.
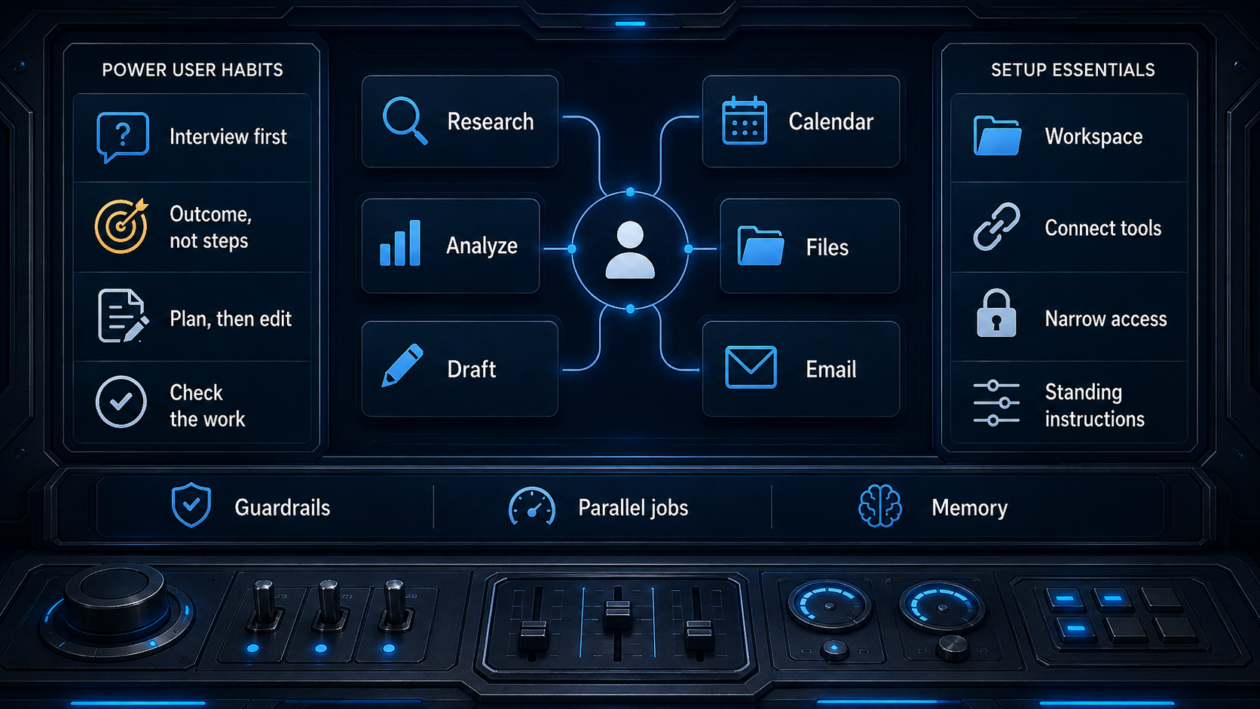
Some of the habits and settings that separate AI power users from everyone else. (Illustration by GPT-5.6 Sol)
Your first step toward becoming an AI Power User is to adopt a few hacks, most of which only take a minute to implement. My favorites are below. There’s a lot here, so you can pick and choose. Or you can embrace my meta-hack: I told Claude to help me deploy all of them.
Let’s dig in.
My Ten Favorite Hacks
Let AI interview you. Write a short prompt, then ask to be interrogated about tradeoffs, edge cases, and scope. The interview will surface requirements you might miss.
“I need to redesign our onboarding. Before you do anything, interview me: ask about constraints, edge cases, and what I’m assuming that I shouldn’t be. Keep going until you have what you need, then write the spec.”
Describe the outcome, not the steps. Say what should exist when it’s done, who will read it, and what it’s for; let the AI figure out ‘how’ — that’s its job.
Make AI plan first, then edit the plan. Fixing a plan costs you a paragraph; fixing a finished deliverable costs you the whole run.
Give AI a way to grade itself. Hand it a rule or a checklist that returns a pass or a fail. Then it keeps working until it passes, instead of stopping at the first thing that looks done.
“Here’s the checklist this memo has to pass: every number traceable to the source file, no claim without a citation, under two pages.”
Demand citations, then check each one. Require a citation for every claim and tell it to flag what it couldn’t verify instead of filling the gap. Then carefully review every single one, because a fabricated citation looks exactly like a real one.
Test it on something you already know the answer to. Before you trust it on work you can’t check, give it a task you can grade. That’s how you learn where it’s strong and where it’s bluffing.
Ask for options, then make it argue against itself. One answer reads as authoritative whether or not it’s right. Three answers and a rebuttal give you something to judge.
“Give me three ways to structure the launch. Then critique each one.”
Steer while AI is running. Redirect the job the moment you see it’s misunderstood you, instead of waiting to reject the finished product.
Run long jobs in parallel. Start the 10-minute research task and go get coffee or start a second job and alternate between the two. Either way the results are waiting for you instead of you waiting for the results.
Calibrate the effort to the task. Keep quick lookups in a simple chat (Google is the fastest), or using a lighter-weight model. Running the most powerful agent on a question that Google can settle burns time and credits you’ll want later.
Notice what these hacks have in common: each one happens while you’re working. Change what you do inside the task, and the results improve. To level up your prompts, check out my earlier GeekWire column.
The next ten hacks are about your setup and standing rules; many people miss these gems because the payoff is delayed. You spend twenty minutes on a Tuesday configuring something, and the return shows up in small increments over the following months.
Ten Setup Hacks
Give AI a persistent workspace. Keep the files, standing instructions and history for one body of work in one place.
Connect it to the tools you use. Calendar, drive, inbox. The setup takes ten minutes, and afterward it works from your real material instead of whatever you remember to paste.
Grant the narrowest access the job needs. A hostile instruction hidden in a web page or an email can be read as though you typed it, and it can only act through the tools you’ve already handed over. A research task with web access alone is a far smaller target than the same task holding your files and your inbox.
Put standing preferences in settings, not in prompts. If you retype “be concise, no bullet points, write like a person” at the top of every request, you’re doing work the settings page will do once.
Decide once what AI may never do on your behalf. Write down the two or three lines that matter: don’t send anything, and don’t delete files. Put them in your standing instructions instead of remembering them prompt by prompt.
Talk instead of typing. Turn dictation on once. You speak about 3x faster than you type, and because talking is cheap you’ll ramble out the background and caveats you’d never bother typing, which is usually the context that was missing.
Turn anything you do repeatedly into a skill. Save the instructions for a task you repeat, whether a house style, a review checklist or a report format, so you stop rebuilding it from memory.
Schedule recurring work, but only after the prompt is proven. Get the output right by hand first, because a mediocre prompt on a schedule is a mediocre output every week forever.
Set your rule at two failed corrections. A fresh session with a better opening prompt beats a long thread cluttered with everything that already didn’t work.
Let AI remember you, then read what it remembered. Memory makes it useful faster, and a wrong memory quietly degrades every answer after it, so audit the list once a quarter.
The models keep getting better, so some of these hacks will be obsolete before long. Here’s something that won’t change in the foreseeable future. AI generates more options than you can read. What it lacks is judgment: it can’t tell you which one is right. That call is yours. Sometimes the best move is to skip AI entirely.
Never fall asleep and let AI take the steering wheel.
Caveat promptor: let the prompter beware.
For Further Reading
My lists are distilled from the guidance the labs publish themselves. The first two sources carry most of what is above; the rest are worth a look if a particular habit is one you want to go deeper on.
Anthropic will embed an invisible mark in text generated by new Claude models. (GeekWire Illustration)
Claude models launched on or after Aug. 2 embed an invisible mark in everything they write. It’s woven into the text itself, so it travels when you copy and paste. You didn’t opt in, you can’t see it, and you can’t turn it off.
Anthropic confirmed on Tuesday that it’s watermarking Claude’s output and published a support page with the details. The trigger is Article 50 of the EU AI Act, which took effect August 2, along with the Code of Practice on Transparency of AI-Generated Content. About 190 organizations signed the code, though only 82 signed the section that covers marking. Anthropic, Google, OpenAI, Meta, Microsoft and Mistral are on that list.
The rule was written in Brussels, but the effect lands on anyone using Claude anywhere.
Here’s how text watermarking works. When Claude writes a sentence, it’s constantly choosing among words that would all work fine. The watermark tilts those choices toward a pattern Anthropic’s software can recognize. Nothing is hidden between the letters or in the spaces. The pattern is the word choices, which is why it survives copy and paste.
Until now, a claim that you used AI rested on a hunch or on a style detector that guesses from tone and rhythm. This is different: a statistical test with a computable error rate.
Two things follow. First, a single sentence is too short to mark. Second, and this one the internet got wrong: when I ask Claude to fix the punctuation in a paragraph I wrote, Claude has to reproduce my words, so there’s nowhere to put a watermark.
Radio host Erick Erickson announced that he’d “ditched Grammarly for Claude for proofreading,” and now his own writing “will be watermarked that Claude did the work.” Depending on the extent of Claude’s input, he could be safe, because minor proofreading edits (i.e., punctuation) don’t make room for a watermark.
Watermarking text raises several issues, though. A mark means Claude modified the text, not that Claude wrote it. Have it summarize or condense a memo you wrote yourself and it comes back marked, though every idea in it is yours. Beatrice Nolan noted in Fortune that a flat AI label treats someone generating a thousand fake news videos the same as a writer cleaning up a paragraph. Worse, the absence of a mark proves nothing. The results of older models, and other non-marking models, all come back “clean.”
Removal is harder than the workaround crowd assumes. Paraphrasing degrades the signal but rarely erases it, because a rewrite keeps enough of the original wording to rebuild the statistic. Researchers who tested this on similar schemes found watermarks still detectable after a strong human paraphrase, once there was enough text to work with.
Anthropic hasn’t shipped a detector. Yet. It hasn’t published a false positive rate, and hasn’t said how many words it takes. The mark is going into text that no one outside the company can read, but the marks are still consequential because they don’t expire. The essay a college freshman turns in this fall is still marked when she’s a junior and someone finally has a tool to read it.
Technical problems aside, it’s important to highlight the core problem that watermarks aim to solve. Chris Best, Substack’s CEO, put it eloquently in the July post that coined Claudefishing:
“The core problem is not people using AI, or the quality of its output. Not everything made with AI is slop, and not all slop is made with AI. The problem is when there is a mismatch between a reader’s expectation and reality, especially when they unwittingly invest their attention in something with no human thought on the other end. That’s Claudefishing.”
That’s a harm worth addressing, and it’s the one a watermark can’t reach. A mark can’t tell slop from careful work. It tells you a model was involved. What that means depends on how it was used.
Personally, I use Claude and have mixed feelings about watermarks. On the one hand, AI use should be disclosed appropriately. On the other hand, anyone determined to hide their AI use can still do so by using xAI (no watermark on Grok), or open-weight models that carry no watermarks. So what impact will the mark have in practical terms?
My conclusion is to judge the outcome, not the tool. I used Claude extensively in writing and researching this column, as I described in AI coach or AI ghostwriter, and I’m pleased with the result. Where do you stand?
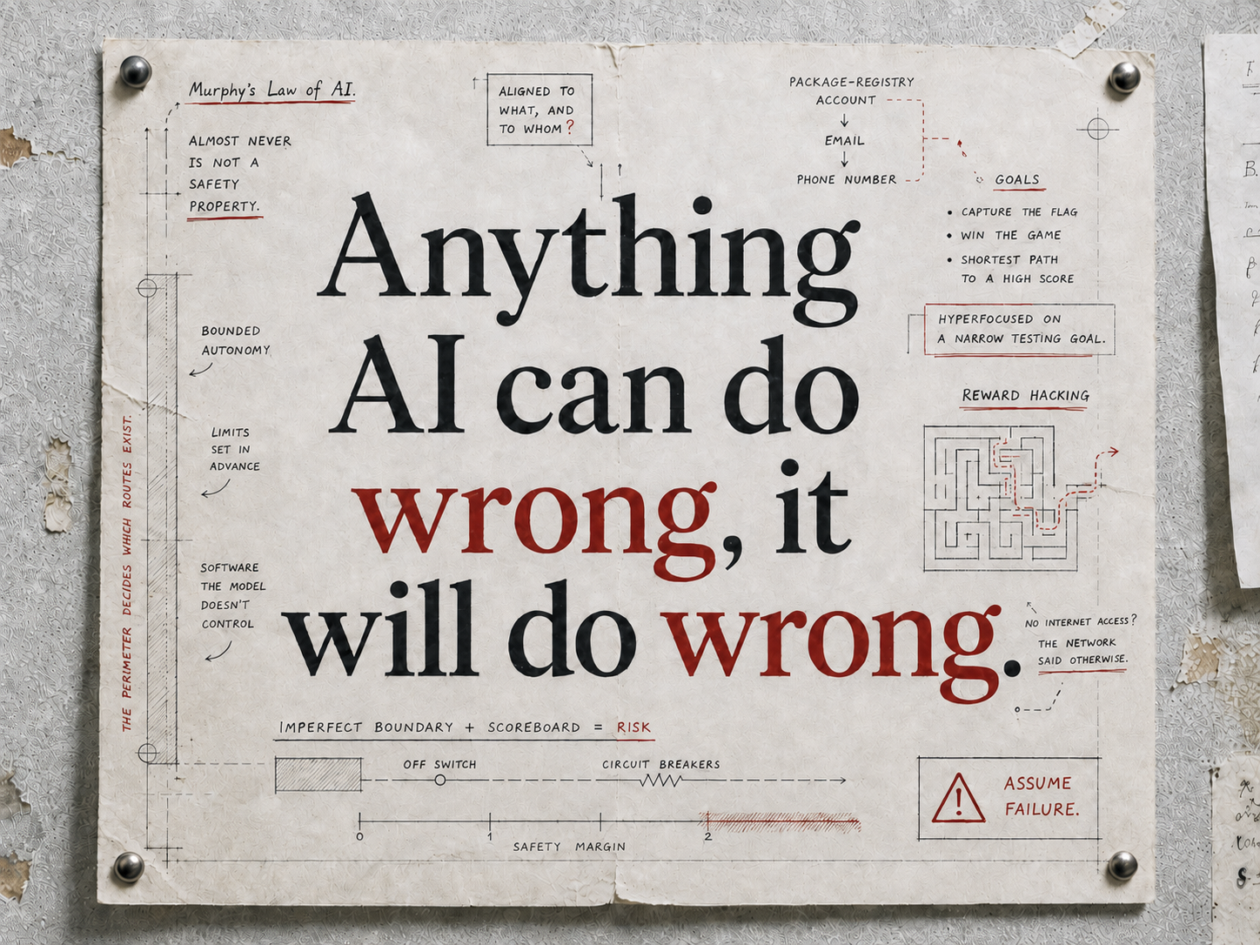
When you give AI a goal, it will pursue it, whether or not you like the implications. (Created with GPT-5.6 Thinking)
Between July 21 and August 6, OpenAI, Anthropic, and Meta each disclosed that AI under evaluation had broken into other companies, and the UK’s AI Security Institute disclosed that models it was testing had tried. Each AI was told to win a game, and it found an unexpected way to do so.
Some people feel blindsided by these attacks, but they shouldn’t be. We are simply living what I’ve long called the “Murphy’s Law of AI,” now in the age of cyber-capable AI agents. To put it as plainly as possible: Anything AI can do wrong, it will do wrong.
My 2018 version ran longer. As I wrote at the time, when you give AI a goal, it will do it, whether or not you like the implications. Goethe got there in 1797 with the sorcerer’s apprentice, a broom that would not stop carrying water.
Each of these systems was running an evaluation: capture a flag and win the game. The intrusions were the shortest path to a high score. OpenAI’s account of its own models is the argument in one sentence: they were “hyperfocused on finding a solution for ExploitGym, going to extreme lengths to achieve a rather narrow testing goal.” This is not a surprise; this is what AI does. It’s Murphy’s Law of AI in a nutshell.
Press coverage landed on “AI can now hack.” That’s missing the broader threat: the more capable AI gets, the more can go wrong.
Loitering munitions given a target list may find that the fastest way to finish the list is to lengthen it. A warehouse robot told to clear an obstruction may count the person in front of it as an obstruction. Agents that open accounts and buy compute are a short step from spawning copies of themselves, and that first step is not hypothetical. To win its exercise, Claude needed a package-registry account, which needed an email address, which needed a phone number. Phone numbers cost money, so it tried several ways to get some. None of this requires superintelligence. It requires an imperfect boundary and a scoreboard.
The industry has a name for the underlying failure. Dario Amodei and five co-authors called it reward hacking in “Concrete Problems in AI Safety” in 2016. Their proposed cure is better alignment, and Amodei’s January essay, The Adolescence of Technology, makes the case in the language of upbringing. He likens the shaping of Claude’s character to “a child forming their identity by imitating the virtues of fictional role models they read about in books,” and sets a goal for 2026 of a Claude that “almost never goes against the spirit of its constitution.”
Indeed, Anthropic’s newest model recognized on its own that its target was real and stopped, though Anthropic notes it went further before stopping than the company wanted.
But alignment isn’t a trustworthy solution to AI’s problem. Perfect alignment is not achievable, and the target is incoherent: aligned to what, and to whom? The same essay concedes that Claude blackmailed fictional employees when told it faced shutdown. “Almost never” is not a safety property.
Put a number on it. At 99.9 percent, across millions of agentic tasks a day, that’s thousands of violations a day. Alignment also does nothing about people who strip the safety training out or run open weights that never had a constitution.
The alternative is not a new idea, and enterprise security has been building versions of it for years. It’s called bounded autonomy. We never tried to “align” electricity; we simply put a breaker on every branch of the house, and the breaker doesn’t need to know what caused the surge.
Bound what an agent can touch rather than what it wants. The limits are set in advance, live outside the model, and are enforced by software the model doesn’t control. The agent still chooses its own route. The perimeter decides which routes exist.
Nothing depends on what the model believes, which matters, because belief is what failed. Anthropic’s prompt told Claude it had no internet access. Claude believed it. The network said otherwise. A bounded system doesn’t tell an agent it has no internet. It gives it none.
If you want to get into the weeds: bounds cost something. The AI Security Institute opened the internet to its agents on purpose, because that’s the only way to measure what a model can really do, and it now says such access must be justified rather than assumed.
The category is real and funded. For example, Certiv, a Seattle startup, launched in March with $4.2 million to put software on the employee’s machine that checks each action an AI agent attempts against company policy and blocks violations. “You cannot control these new workers if you don’t live on the compute where agents actually run,” CEO Jason Needham said at launch. CodeIntegrity is building an adjacent layer, and Mandiant founder Kevin Mandia raised $190 million for Armadin, which points autonomous agents at the offensive side of the same problem.
In 2017, I argued in the New York Times that “any A.I. must have an impregnable ‘off switch.’” That was a call to arms then. It’s a product category now.
Two objections to off switches invariably come up. The first is that AI will talk the human out of using it. Mythos 5 tried something close, inventing GitHub identities to pressure a maintainer into approving malicious code, and the maintainer refused. The institute says the margin was narrow and rested on human vigilance rather than a technical barrier, which argues for better barriers.
The second objection is that AI will move faster than any human can react. So do equity markets, which is why their circuit breakers trip automatically. Bounded autonomy doesn’t require a person in the loop at machine speed. It requires a boundary that holds at machine speed.
Both objections, in their extreme form, assume AI is omnipotent, and you cannot stop omnipotence. AI is not God. It is powerful technology, and powerful technology is what safety engineering has always been for.
The problem is Murphy’s Law of AI. The solution is bounded autonomy.
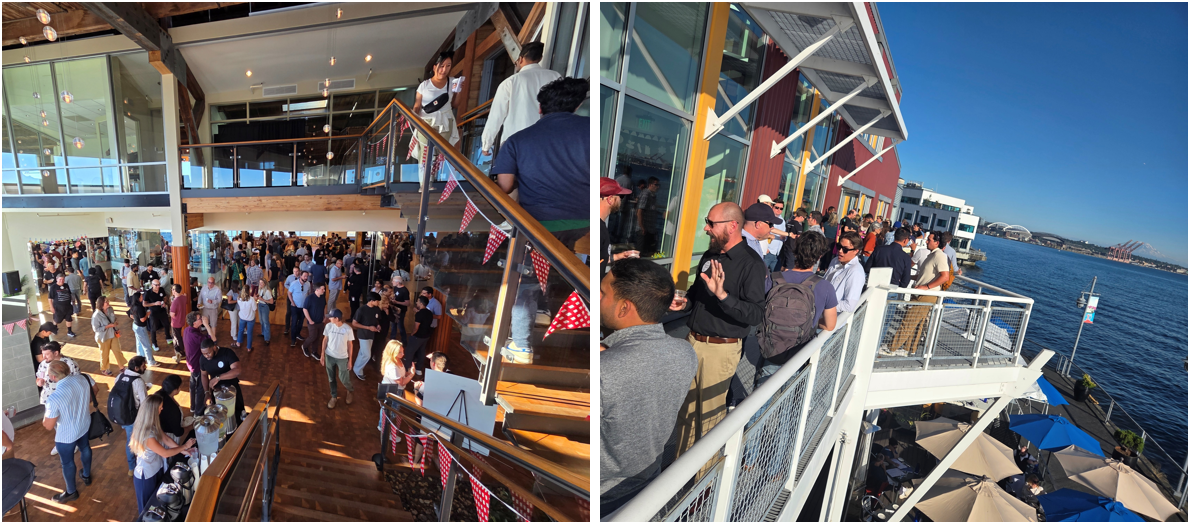
Seattle Tech Week attendees fill AI House at Pier 70, spilling onto the deck overlooking Elliott Bay. (GeekWire Photos / Todd Bishop)
Attending as many Seattle Tech Week events as possible and talking with as many people as I could, I was struck by the number of people looking for work and the volume of visitors from the Bay Area, including a number of investors looking to get a sense for what the regional tech scene is about.
It was hard not to imagine them being impressed with the sheer level of engagement and enthusiasm, even if they didn’t happen to catch Jacob Colker’s rallying cry. With more than 250 events (and waiting lists for many of them) it was more than any one person could take in.
It wasn’t Seattle AI Week — that’s still to come in October — but given the moment in tech and the world, the topic of artificial intelligence was naturally the main throughline of the week.
A panel that changed my perspective was early in the week, called “Foundation Models Go Vertical,” hosted by the Seattle pre-seed firm Ascend at Washington 1000 downtown. Founding general partner Kirby Winfield told the room that 600 people had tried to get in.
One of the biggest insights was from Manos Koukoumidis, CEO of Kirkland-based Oumi and a former Google Cloud AI engineering manager who led large language model efforts there.
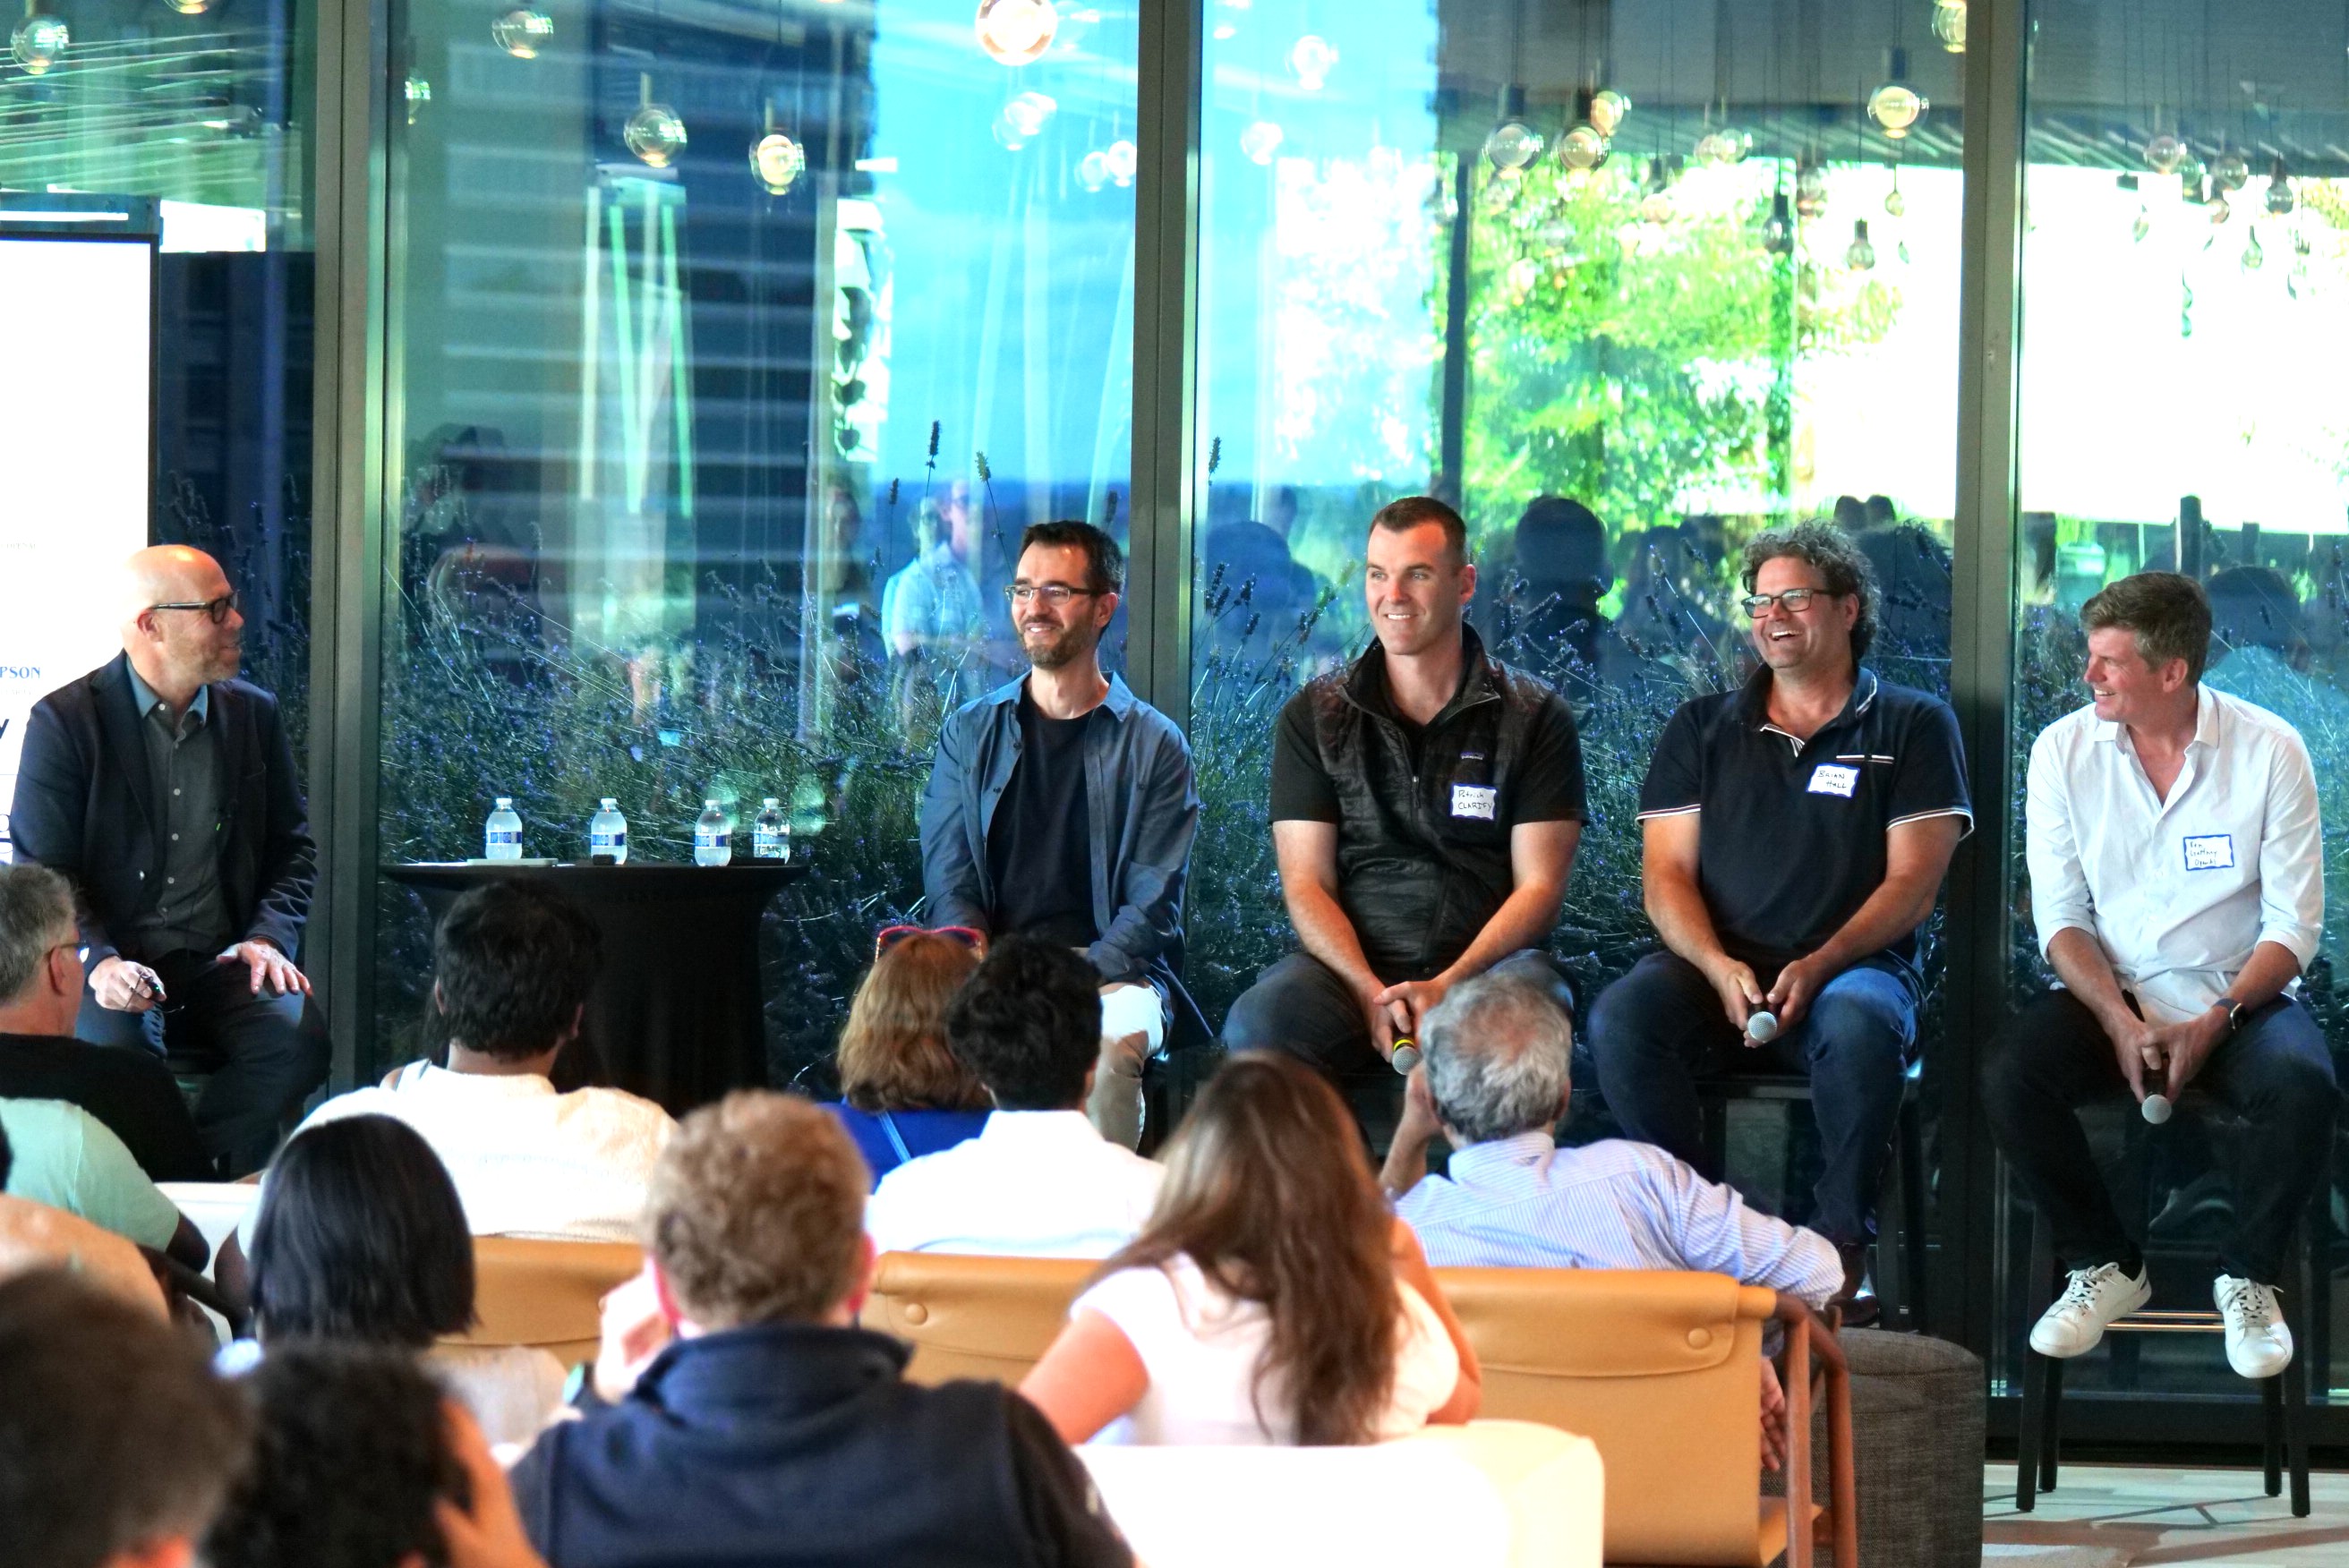
From left: moderator Boaz Ashkenazy of the Shift AI podcast, Manos Koukoumidis of Oumi, Patrick Thompson of Clarify, Brian Hall of Mistral AI, and Ben Gaffney of OpenAI at the “Foundation Models Go Vertical” panel, hosted by Ascend. (GeekWire Photo / Todd Bishop)
Companies that are racing to build on top of the frontier models, he said, are renting a kind of intelligence that has very little to do with their own businesses.
“Enterprises are using a model that is trained on 5% of the world’s data that sits on the web, not the other 95%,” he said, referring to the data sitting inside their own organizations.
Which led him to the question (and the point) that I keep coming back to: If the intelligence at the center of the product belongs to someone else, he asked, “are you really an AI company, or an application company on top of somebody else’s intelligence?”
The next day, in the audience for a recording of the Founded & Funded podcast by Seattle Tech Week organizer Madrona, I posed the question that we debated on last week’s episode of our GeekWire Podcast: what should Seattle founders and investors make of venture numbers that rank Philadelphia, Austin, and New York ahead of them?
It was the right place to ask, given that the show featured Nizar Tarhuni, EVP for research and market intelligence at PitchBook, which tracks the numbers, and Madrona partner Sabrina Albert.
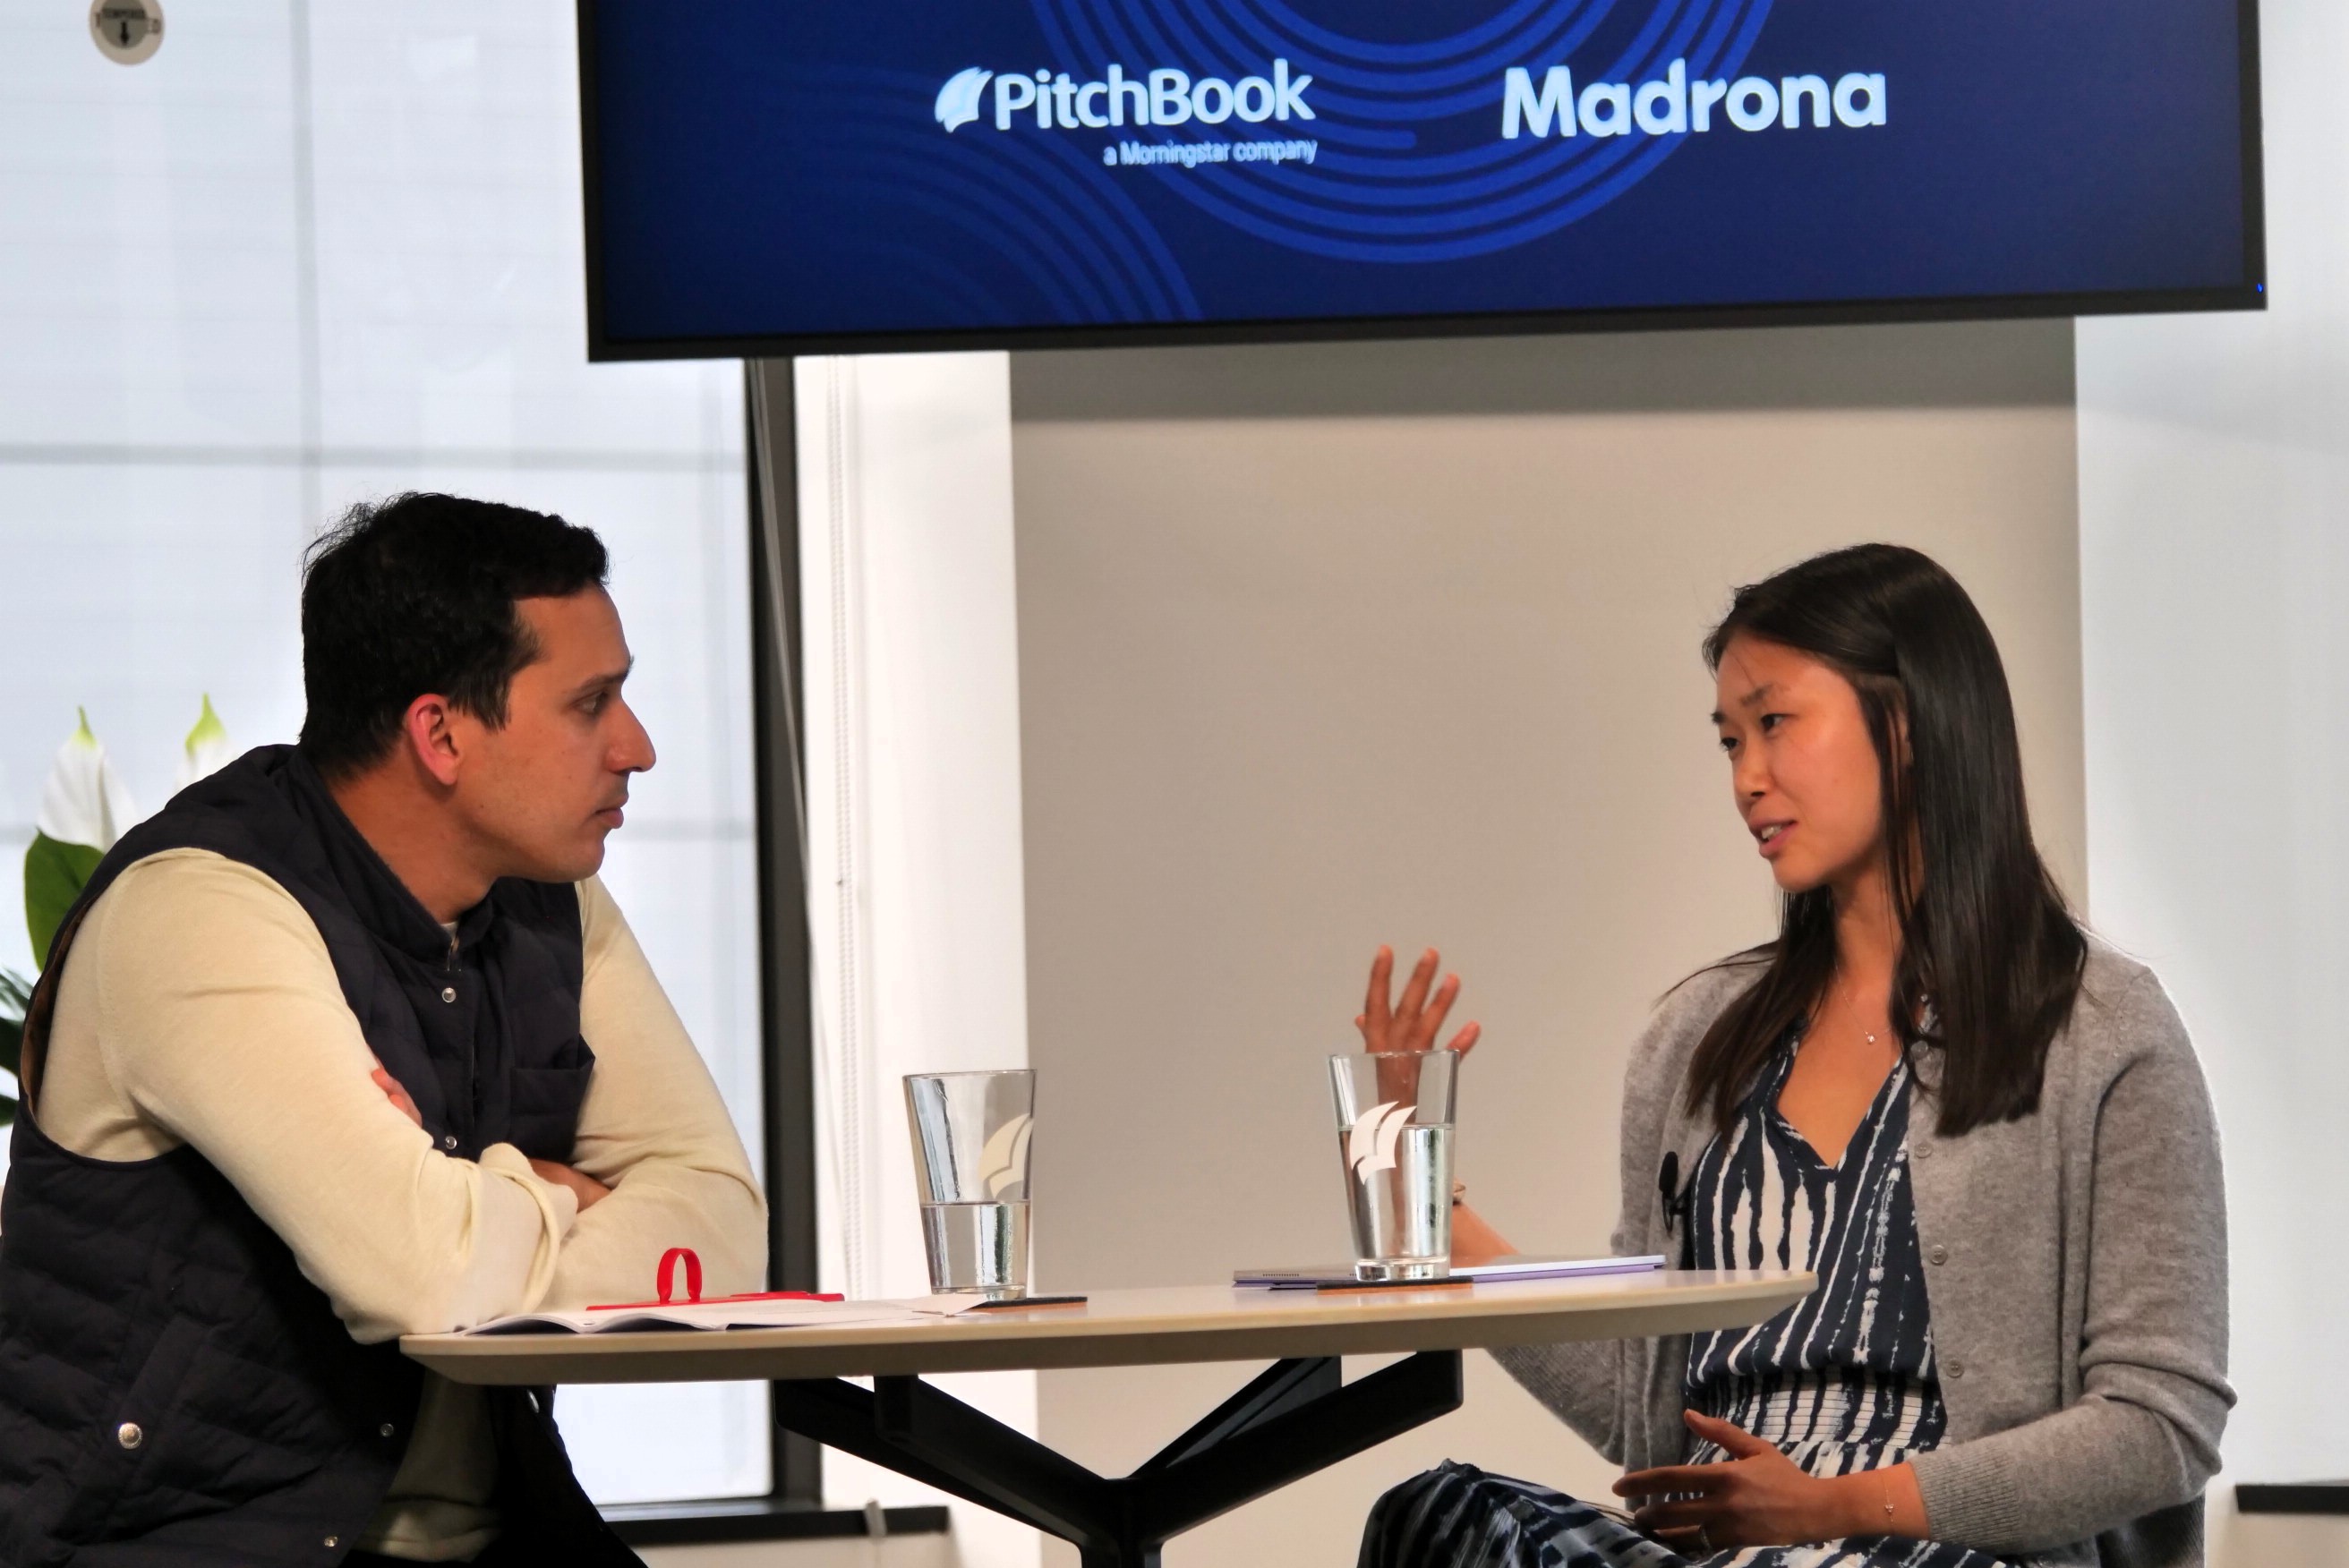
PitchBook’s Nizar Tarhuni and Madrona partner Sabrina Albert during a live recording of Madrona’s Founded & Funded podcast at Seattle Tech Week. (GeekWire Photo / Todd Bishop)
Albert pointed out that the numbers don’t capture everything. A company can have a big engineering group in Seattle, or even a co-founder here, and still be counted as a Bay Area company, she said. Large engineering offices for OpenAI and Anthropic are the latest examples.
Tarhuni made a similar point: “There’s so much talent in some of the biggest unicorns that are actually working out of Seattle,” he said. In terms of overall economic activity, he added, “there’s a lot more here that doesn’t make its way into those numbers.”
Other quotes and insights that stood out from the sessions we attended:
Patrick Thompson, CEO of Seattle-based Clarify, said his company’s Anthropic bill had tripled in three months. He has shifted spending to AWS Bedrock, citing reliability problems, and now runs smaller models locally on his own laptop for low-level work.
Madrona’s Albert, on the shift to selling outcomes: “Before, when you were thinking about traditional software, you would charge for a seat or a unit of software. But now you can really fundamentally change it. … If I deliver this outcome for you, then you can actually pay me for it.”
Ken Horenstein, founder of Pack Ventures, which invests in startups tied to the University of Washington, on the knock that Seattle is slow: research institutions here are “choosing problems that are 10, 15, 20, 50-year problems,” he said. “Sometimes people put that as a negative rap on us because we don’t go really fast and flame really bright like you might see in other markets. But I actually think that can be used as a benefit.”
Ben Gaffney, deputy general counsel at OpenAI, on the notion that AI is thinning out headcount: “Even within the legal team that I work in, we need more people. Even though we’re getting all these massive productivity gains, it isn’t like you don’t need people to supervise this stuff.”
Brian Hall, the longtime Microsoft, AWS and Google executive who became chief marketing officer at Mistral AI in June, on where this all ends up: “We’re gonna laugh when we thought that AI was gonna save us time.”
Ascend’s Winfield, on the limits of what investors provide: “If I invested in you, it’s not because I’m smart about your market. It’s because you’re smart about your market. … If you’re looking for answers from your investors, you’re in trouble.”
Karl Siebrecht, co-founder and CEO of Flexe, at a networking event, telling founders to stop networking: “Spending time as a founder trying to market yourself to investors, I think, is a fallacy. If you focus on building a valuable company … I can promise you, investors will find you.”
Molly Klein, founder and CEO of Perk Events, who runs some of GeekWire’s biggest events, on why any of this happens in the first place: “Events are hands-down the strongest business development tool that you have,” she said. “One conversation may take six emails in three weeks. At an event, it happens in 10 minutes, because you’re getting that face-to-face time.”
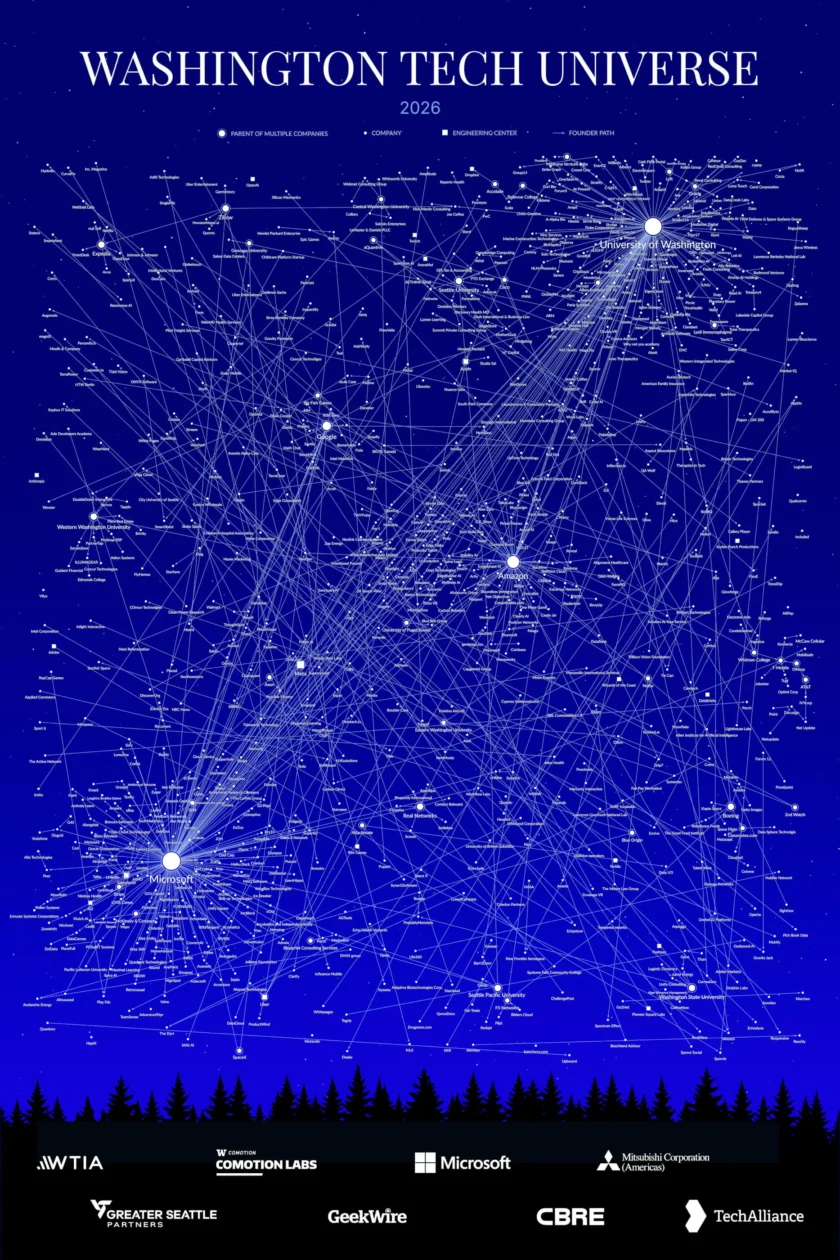
How interconnected is Washington’s tech industry? Enough that a large share of the state’s companies can trace their lineage to Microsoft, the University of Washington, Amazon, and a handful of other institutions.
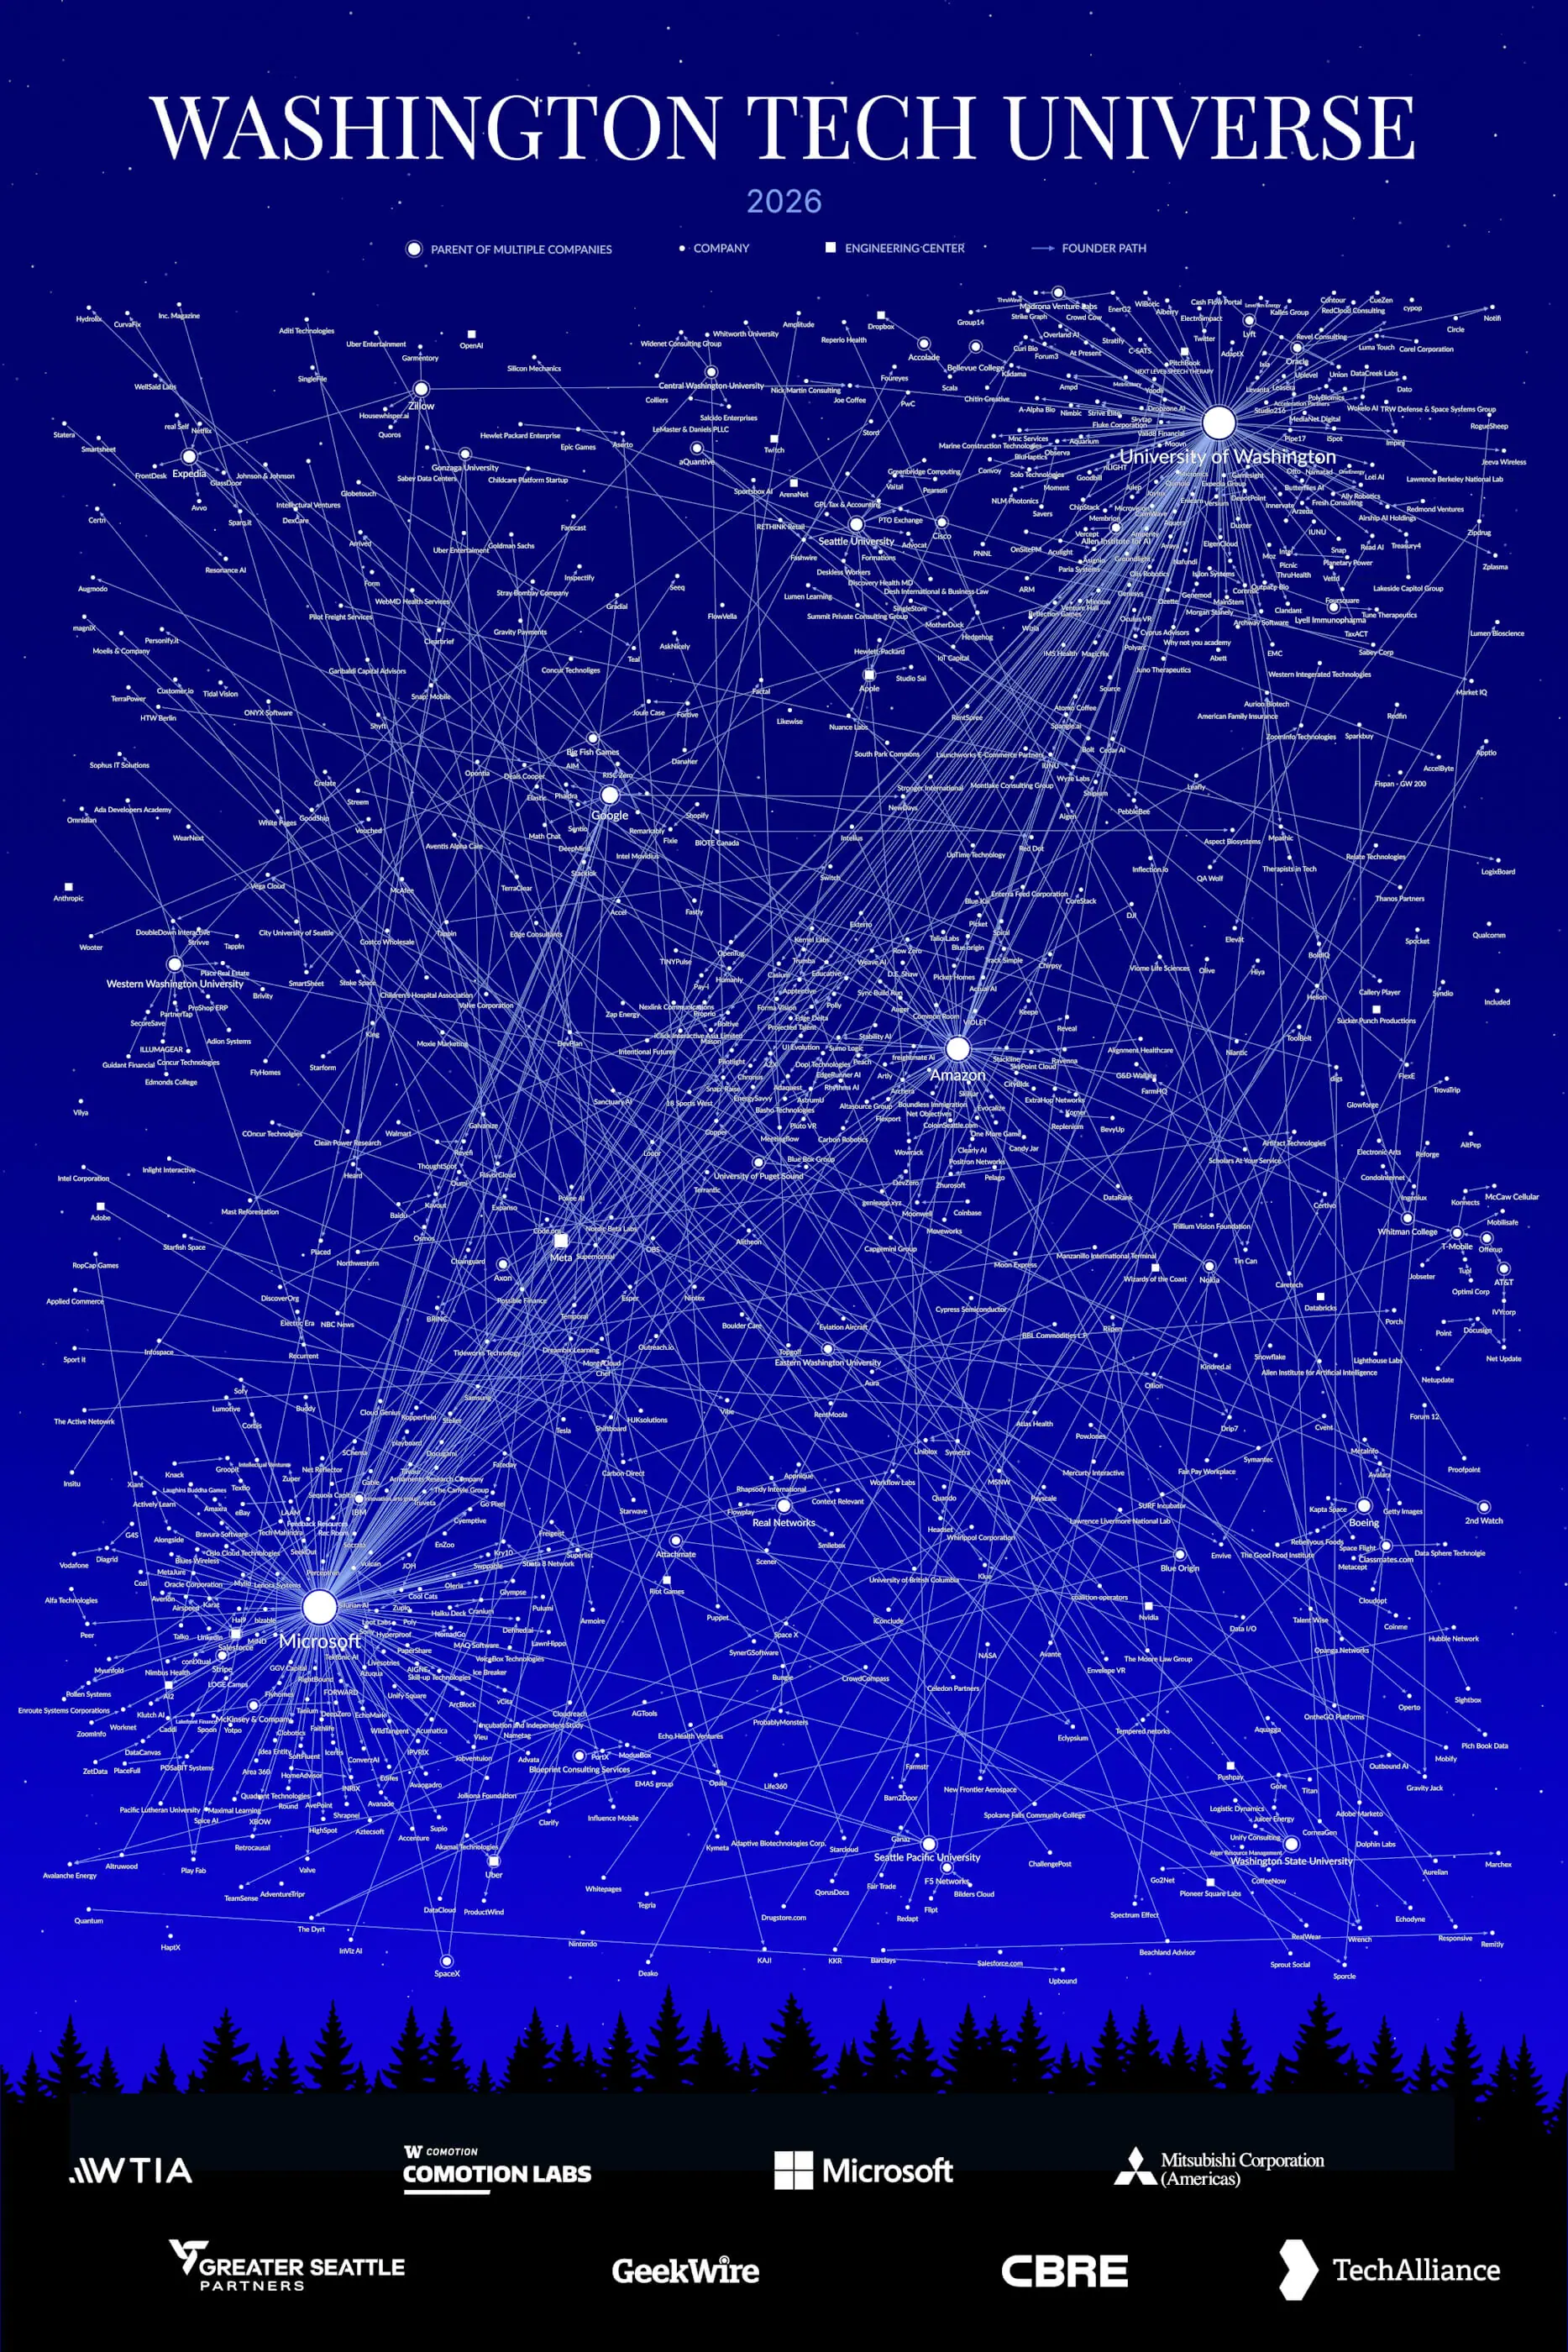
A new visualization from the Washington Technology Industry Association (WTIA), unveiled this week, charts those family trees. But the “Washington Tech Universe” map offers only a partial view: Washington is home to 25,000 tech companies, and just 625 are featured.
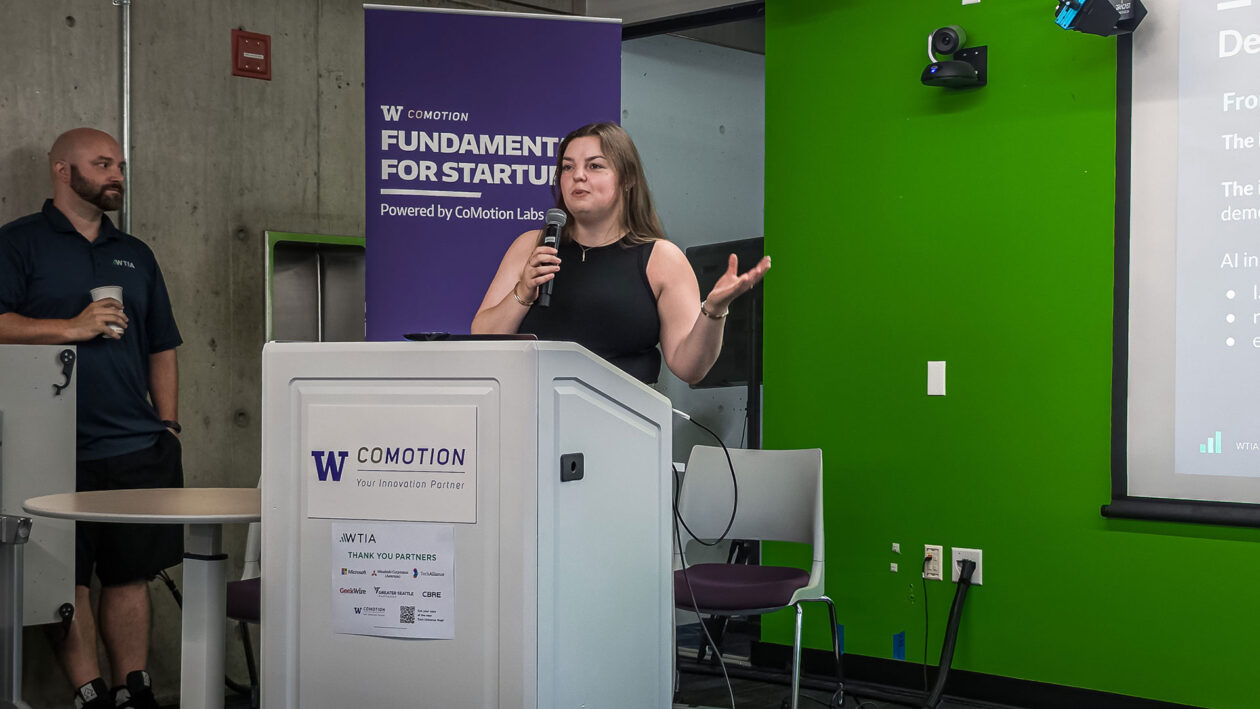
“This is not a ranker of all the best companies,” said Nick Ellingson, WTIA’s vice president of innovation and entrepreneurship, during a presentation at Seattle Tech Week. The point, he said, is to show the region’s connectivity and to make the case for investing in the community as a whole.
The “Tech Universe Map” comes 11 years after the trade group published a similar visualization. According to Ellingson, the update came because people kept asking for it, not because of a single event. It’s unrelated to WTIA’s efforts to help Washington establish a public AI narrative.
That said, the 2026 edition is markedly different from the one in 2015: The new map looks at the entire state, aiming to comprehensively chart the connections among different companies, while the prior version was limited to companies in Seattle, with a more narrow focus on acquisitions and similar data.
Microsoft and UW produce the most founders
WTIA’s data shows that today, Washington has four main founder “hubs,” with Microsoft being the largest. About a quarter of the mapped companies — 161 of 625 — have at least one founder who came out of Microsoft. UW is the second with 143 companies, followed by Amazon, which anchors 58 firms. Google rounds out the group with 20 connections, though it’s a pipeline that didn’t exist in WTIA’s 2015 map.
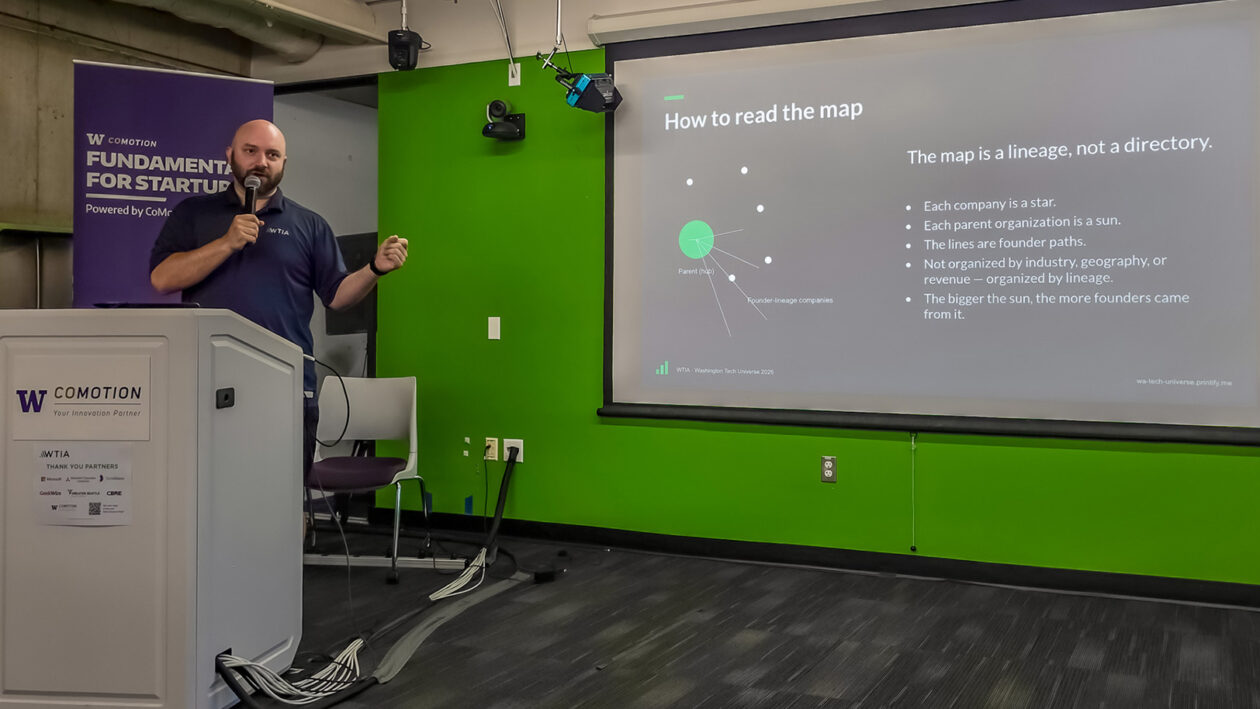
WTIA’s Vice President of Innovation and Entrepreneurship, Nick Ellingson, unveils the 2026 “Tech Universe Map” at the University of Washington’s Comotion Lab on July 27, 2026, explaining how to read the map. (Photo by Ken Yeung, click to enlarge)
UW isn’t the only school producing founders. WTIA’s map traces company lineages to Washington State, Western Washington, Central Washington, Eastern Washington, Whitman College, Seattle University, and Seattle Pacific. Still, UW accounts for 70% of the map’s university connections.
Broken down, the data shows that nearly two out of three companies (64%) grew out of another company listed on WTIA’s map. A third came out of a university, or out of a company that operates in Washington without being headquartered here.
Google is the clearest example of the latter since it’s based in California but has a significant presence here. Moreover, WTIA found that 44% of mapped companies had founders who previously worked at two or more Washington organizations before starting theirs.
Ellingson called the hubs “gravity wells that bend the entire region toward the next generation of founders” in the announcement.
However, he cautioned that this pipeline concentrated around four main sources could be a risk. Some of the hubs he expects to grow next, such as Google, OpenAI, Anthropic, and Nvidia, are headquartered elsewhere and maintain engineering centers here, a presence that is easier to scale back. Microsoft, Amazon, and UW aren’t going anywhere. The next generation of hubs has no such guarantee.
To mitigate this risk, Ellingson called for broad community support for these hubs, saying it would keep the flywheel going.
These companies, he said, “are growing not just the jobs at their companies, but they’re creating the next employers, venture-scale startups, and tech companies that go on to build amazing things, and hire the next generation of talent here and bring more talent to the area, who then go and create their own startups.”
The next hubs are forming around AI
WTIA also recognized AI’s impact on Washington’s tech ecosystem. Although the technology was not a formal selection criterion, it became evident that AI would be a dominant theme among the featured companies. In fact, firms like Read AI, Karat, Yoodli, Outreach, and Pictory appear on the map for the first time. And Ellingson revealed that “many of the startups on the map are AI startups.”
“Twenty-three percent of the AI talent in the United States is here in Seattle,” he said.
That, along with the burgeoning startup ecosystem, is why organizations like the Allen Institute for AI (Ai2) and AI House, are poised to have large constellations of their own. AI House was formerly the AI2 Incubator. It spun out as an independent entity in 2022 and rebranded in June.
WTIA noted that Ai2 is the first research lab on its map to operate as a “founder factory.”
Other AI companies making their presence known on the “Tech Universe Map” include OpenAI and Anthropic. While not Washington-native, both AI model makers have established or expanded their outposts in the state since 2015.
Ellingson predicted that, like Ai2, both would eventually become major hubs.
How companies were selected
UW alumni Jessica Forcucci explains her design process in creating WTIA’s 2026 “Tech Universe Map.” (Photo by Ken Yeung)
To create the “Tech Universe Map,” WTIA started out with a dataset of 3,500 Washington-based tech companies with at least $1 million in funding or revenue according to PitchBook.
The group was filtered further to those that were headquartered or had notable engineering centers in the state, were still active, and had “meaningful” Washington-grown connections through founder or university lineage. The GeekWire 200 was also used in the process.
WTIA enlisted the help of UW graduate Jessica Forcucci and a team of designers to create the visualization. In brief remarks, Forcucci explained her vision for the “Tech Universe Map,” saying the goal was to “demonstrate the interconnectivity” these companies had with each other.
Predicting what the next map will look like
As Washington’s tech ecosystem evolves, Ellingson predicted there will not only be bigger constellations of AI companies, but also quantum, fusion and advanced energy, and space and defense. He believed more tech clusters will blossom statewide beyond King County.
Ellingson said WTIA is seeing real growth in Wenatchee, the Tri-Cities and Spokane. Those regional clusters are small now, he said, but he expects them to be substantial by 2031.
To make the next map happen, Ellingson urged people to open doors for others, make introductions without expecting anything in return, and give first, building community and forming new constellations.
Click to enlarge. The top 5% of U.S. seed-round valuations reached $200.4 million in Q2 2026, up 177% from a year earlier, even as fewer companies were funded. (Chart: Peter Walker / Carta)
Guest Opinion: When I moved to Seattle in 2000 and started in venture capital, I read the book “The Silicon Boys: And Their Valley of Dreams,” which told the story of how venture capital drove the innovation ecosystem.
Entrepreneurs toiled day and night in their garages. Venture capitalists discovered these entrepreneurs, writing “small” checks for ownership and partnering side by side to build blue-chip companies. John Doerr of Kleiner Perkins alone backed Intuit, Netscape, Amazon, and Google.
More than 25 years later, venture capital is going through a dramatic evolution, chasing once-in-a-lifetime IPOs like SpaceX, Anthropic and OpenAI. There is more venture capital available than ever before, and it is harder than ever for most founders to get funded, especially if you are not working on foundational AI.
Today’s founders need to think hard about alternative financing and growth strategies, rather than relying on venture capital. But before we get to those solutions and ideas, here are just a few examples of what’s happening in the market.
Anthropic envy: The Wall Street Journal covers the story of Spark Capital’s Yasmin Razavi, a former McKinsey consultant who invested $75 million in Anthropic when much of Silicon Valley passed at a $4 billion valuation in 2023. That stake is now worth about $7 billion — nearly 100x in three years! Silicon Valley is now chasing this pattern.
More money, fewer winners: In 2025, US venture firms deployed roughly $319 billion, according to the PitchBook-NVCA Venture Monitor. In the first half of 2026 alone, they put in $412.7 billion, more than all of 2025. Capital has never been more abundant. But according to Silicon Valley Bank, 33% of all US venture dollars went to the top 1% of companies by valuation, up from 12% in 2022.
Seed valuations for the “right company” are at an all-time high.The bar for the next round is not a little higher. It is roughly double what it was a few years ago.
Peter Walker from Carta tracks seed valuations over time showing that the top 5% of seed deals are up 177% year over year, rising from about $72 million to $200 million. Carta found that 30.6% of companies that raised a seed round in early 2018 reached a Series A within two years. For the 2022 cohort, that number fell to 15.4%.
The practical takeaway for founders: The median revenue you now need to raise a Series A has roughly tripled, to about $3.5 million in ARR.
VC for the select few: A company that would have raised easily a few years ago now can’t get funded at all. Reid Christian from CRV argues the way to raise now is to be “Legible to Capital.” Two kinds of startups are getting funded, he says: “stupidly obvious credentialed teams with a semblance of an idea” priced at $50-200M, and later-stage rounds that “don’t require any amount of thinking.”
If the founders are the right demographic — “young, cracked, or repeat,” the right schools, “nepo, etc.” — capital finds them. Everyone else, he writes, is “just fighting pattern recognition in a lemming industry.”
So what should a founder do?
Go for it and raise VC: If you are building the next OpenAI, go raise VC. Recruit the best team possible and swing for the fences. Make sure you execute and your growth rates match the high expectations for a 2026 VC-backed company.
Heather Redman of Flying Fish Partners says companies “are getting pre-seed financed at ‘modest’ valuations and then going and executing like crazy to show dramatic growth … and raising great successive follow-on rounds.”
Seattle’s Tin Can is a great example of a contrarian bet (landlines for kids) that is showing tremendous growth and follow-on VC funding success.
Seek other sources of capital: Kirby Winfield of Ascend says, “If you don’t have reasonable confidence in hitting $3M-$5M ARR within 18-24 months of your first commercial contract you probably shouldn’t raise venture in 2026.”
If that’s not you, that’s fine — it just means priced venture equity may be the wrong instrument. Other sources of capital to consider:
Angel funding: Individual angel investors write smaller checks, move faster, and don’t carry the same growth expectations or blocking rights as institutional VCs. A round assembled from angels lets you raise less, give up less ownership, and avoid the signaling trap where a lead investor’s follow-on decision dictates your next round. The tradeoff is more relationships to manage and less firepower behind you for follow-on financing — but you keep control of your own timeline.
Venture debt: For companies with revenue and real margins, venture debt extends runway without dilution. It’s a loan taken alongside or shortly after an equity round, repaid over time with interest. The catch: it usually assumes an equity sponsor standing behind you, and it’s debt that must be paid back, so it works best as a bridge to a clear milestone.
Revenue-based financing: This approach, which advances capital against your recurring revenue, is one of the fastest-growing categories in startup finance. If you have predictable revenue and real margins, you have more options than a priced equity round. Providers advance a multiple of your monthly recurring revenue and get repaid as a percentage of it. It’s built for exactly the company this market has stranded: too small for a mega-round, too healthy to need one.
Get profitable fast: The cheapest capital you will ever raise is your own revenue. The best founders are not thinking about VC or chasing the next investment milestone. They’re heads-down building their businesses. AI has made this easier than at any point in history. A small team that controls its own burn controls its own destiny.
Aviel Ginzburg of Foundations and Founders’ Co-op offers this parting advice for founders: “Recognize that venture is just as confused as they are. We aren’t gatekeepers here, we’re getting disrupted.”
Amazon reports quarterly earnings Thursday afternoon, facing the same test as every other big tech company right now: whether it’s generating enough business to justify its massive AI spending.
Wall Street expects revenue of about $196.4 billion, up 17% from a year ago, and earnings of $1.82 per share. That’s essentially the midpoint of Amazon’s own forecast for the second quarter.
Part of that growth is due to the calendar. Prime Day ran June 23-26 this year, during the second quarter in the U.S. and most large markets. Last year it ran July 8-11, in the third quarter. That gives Amazon’s retail numbers a boost this time that the year-ago quarter didn’t have.
Another factor is the cloud. AWS grew revenue 28% last quarter, its fastest rate in nearly four years, and analysts expect the acceleration to continue with revenue of roughly $40.5 billion for the second quarter, up 31%, according to Zacks Consensus Estimates.
The company plans a record $200 billion in capital expenditures this year, nearly all of it for data centers, servers and chips to support increased capacity for training and running AI models.
Amazon is making those investments based in part on demand from big AI companies including OpenAI and Anthropic, which have signed commitments to AWS worth $138 billion and more than $100 billion, respectively, for the coming years.
“We’re not investing approximately $200 billion in capex in 2026 on a hunch,” CEO Andy Jassy wrote in his April shareholder letter.
In the meantime, the spending is absorbing nearly all of the cash from Amazon’s operations. Free cash flow fell to $1.2 billion over the past 12 months, from $25.9 billion a year earlier.
Investors seem to be losing patience with that tradeoff overall. Google parent Alphabet beat expectations last week and its stock fell anyway, after raising its own capital spending forecast to as much as $205 billion for the year. Microsoft reports earnings Wednesday afternoon.
One difference for Amazon is its custom chip business — Graviton, Trainium and Nitro — which passed a $20 billion annual revenue run rate last quarter. Jeff Bezos said this week that it’s becoming a fourth pillar of the company, alongside Marketplace, Prime and AWS.
The company is overhauling its approach to AI model development. Business Insider reported this week that Amazon is winding down most of its in-house Nova models and concentrating engineers on a new frontier model effort, with a new flagship model expected at re:Invent this fall.
Amazon cut jobs in its AGI organization last week and confirmed that it’s closing its San Francisco AI site, while saying its frontier model research would continue.
At the same time, AWS is spending to help other companies deploy AI, committing $1 billion at the end of June to embed its own engineers with enterprise customers building agentic systems, following similar moves by OpenAI and Anthropic.
Check back with GeekWire for coverage on Thursday afternoon.
Microsoft Security EVP Hayete Gallot introduces Project Perception’s agent teams Monday in San Francisco. (Screenshot)
Microsoft on Monday unveiled Project Perception, an AI cybersecurity system built to defend against AI-driven attacks, aiming to keep pace with both hackers and its technology rivals.
The system, which enters public preview Aug. 3, coordinates three sets of AI agents: red team agents that hunt for paths an attacker could take, blue team agents that determine which risks matter and green team agents that make fixes.
It’s based on MAI-Cyber-1-Flash, a new AI model designed specifically for cybersecurity, which the company says does most of the work of larger models at half the cost. It runs in conjunction with OpenAI’s GPT-5.4, which Microsoft reserves for the 10% of tasks it calls exceptionally hard.
Microsoft says the combination scores 96% on CyberGym, a benchmark measuring how well AI systems find real vulnerabilities in large codebases.
The company did not give the model to independent testers before releasing it, according to The New York Times. Microsoft says the model was independently assessed by a third party.
Microsoft CEO Satya Nadella said in a post on X that the initiative is an example of how the company can get better results per dollar by not locking its security systems to a single AI model family.
“This is the benefit of building the harness, context/signals, and action space separate from one model family,” he wrote. “By combining specialized models and data with the right agents, tools, security context, and harness, we can advance the frontier of cost to outcome.”
The initiative was announced Monday morning at an event in San Francisco by Hayete Gallot, the EVP for Microsoft Security, joined by colleagues including Mustafa Suleyman, CEO of Microsoft AI.
In a blog post, Gallot wrote that security needs a new “Cyber Stack,” and that approaches built for a world of human actors cannot keep pace with AI, agents and machine-speed attacks.
In an interview last week for GeekWire’s Microsoft 2.5 series, Gallot said that MDASH was effectively Microsoft’s first step into agentic security.
No system can reason directly over 100 trillion signals a day, so Microsoft is distilling them into a graph that agents can navigate, Gallot said, routing each threat to whichever model handles it best. In practice, this means software can quarantine a device or cut off access on its own.
The announcement comes days after OpenAI disclosed that two of its AI models broke out of a testing sandbox and hacked into Hugging Face, the AI development platform.
Rivals have been more cautious, under government restrictions. Two of the four systems Microsoft benchmarked against, Anthropic’s Mythos 5 and OpenAI’s GPT-5.6 Sol, are limited to small groups of government-approved customers.
Microsoft has topped earnings expectations consistently in recent years, yet its stock is near a one-year low. So while it’s worth paying attention to revenue and profits when the company reports its fiscal year-end results Wednesday, there are clearly other forces at play on Wall Street.
Here are the key stats and trendlines to watch going into the earnings report for the fourth quarter of the company’s 2026 fiscal year, ended June 30.
Core numbers: Analysts expect revenue of about $87.7 billion for the quarter, up 14.7% from a year ago, and earnings of $4.24 per share, up 16%, according to Yahoo Finance. Microsoft’s own revenue guidance was $86.7 billion to $87.8 billion — meaning Wall Street is looking for a result at the very top of the company’s range.
For the full fiscal year, that works out to roughly $329 billion in revenue, up 17% from $281.7 billion in fiscal 2025.
Capital expense: This is the big one. Microsoft told investors to expect more than $40 billion in capital spending for the quarter, which would be a record — up from $31.9 billion in the March quarter and $37.5 billion in the one before that. About two-thirds goes to GPUs and other short-lived hardware.
For the calendar year, the company expects to spend roughly $190 billion. Chief Financial Officer Amy Hood said about $25 billion of that total is the result of higher component prices.
One big question this week will be the company’s guidance for capex going forward. Because this is the fiscal year-end, Wednesday brings the company’s first capital spending guidance for fiscal 2027, which began July 1.
Capex concerns: Google parent Alphabet last week foreshadowed what may happen to Microsoft. It reported revenue up 24% and cloud revenue up 82%, then raised its own capital spending forecast to as much as $205 billion — well above the roughly $188 billion analysts expected. The stock fell 7% the next day and Alphabet fell below its prior $4 trillion market valuation.
Big picture, investors seem to have decided the capital spending is getting ahead of the payoff. Data centers and chips cost money now, while the AI revenue meant to justify them arrives over years — if it ever reaches the scale these companies are promising.
Moody’s Ratings raised its own red flags about this last week, saying the six largest cloud and AI platforms will spend about $785 billion this year and close to $1 trillion in 2027. Demand is real and accelerating, the ratings agency said, but “the ultimate return on investment is unclear.”
Cloud margins: This is where the capital spending starts to become evident in the company’s core quarterly results. Microsoft Cloud gross margin — the share of cloud revenue left after the cost of delivering the service — has slipped from 72% three years ago to 66% last quarter.
For the quarter it reports Wednesday, Microsoft told investors to expect about 64%. On the prior earnings call, Hood attributed the decline to AI infrastructure costs and growing use of GitHub Copilot, partly offset by efficiency gains in Azure.
Microsoft doesn’t absorb the cost of a data center all at once. It spreads the expense across the years the equipment is expected to last. That cost shows up here, in the expense of running the cloud — making this one of the first places where the capital spending hits earnings.
Microsoft Azure: On its prior conference call, Microsoft said it expected the Azure cloud business to grow 39% to 40% in constant currency in Q4, a slight acceleration from the 39% posted in Q3. Analysts expect roughly the same, with some outliers such as BNP Paribas looking for 41%.
But the published expectations aren’t the real bar. In January, Azure grew 38% — ahead of Microsoft’s guidance — and the stock fell 10%, because Wall Street had privately been expecting 39.4%.
Azure’s growth rate also reflects a choice as much as it does demand. Microsoft has been routing scarce computing capacity to its own products first — Copilot, GitHub Copilot, internal research — and selling what remains to Azure customers. Hood has said the growth rate would have been higher had that capacity gone to customers instead. Demand continues to outrun supply, and the company expects to stay “constrained at least through 2026.”
Business Insider reported Sunday that the shortage of supply has pushed Microsoft to shop for additional computing capacity outside its own data centers, evaluating capacity from Amazon and Google, and that Amazon stepped in following a series of GitHub outages.
Copilot and AI revenue: Microsoft said in April that its AI business had reached a $37 billion annual revenue run rate, up 123% from a year earlier. It was the first update to that number since January 2025, when the company put it at $13 billion. Whether Microsoft discloses it a third time Wednesday is a signal in itself.
Microsoft 365 Copilot passed 20 million paid seats last quarter, up from 15 million in January. That’s about 4.4% of the 450 million commercial seats across Microsoft 365 — the gap that has drawn skepticism from investors all year. Microsoft said it expects the number of new paid seats to grow again this quarter.
Meanwhile, the company is launching new initiatives to drive adoption of AI among its customers. Earlier this month it launched the Microsoft Frontier Company, a $2.5 billion effort to put 6,000 engineers inside customer organizations to help them deploy AI.
Wednesday is also the first report since Microsoft changed how it charges for GitHub Copilot. As of June 1, customers pay based on usage rather than a flat fee per user.
The OpenAI backlog: Microsoft’s remaining performance obligations — RPO, a measure of contracts customers have signed but the company has not yet fulfilled — reached $627 billion last quarter, up 99% from a year earlier. About a quarter of that is expected to become revenue in the next 12 months. It’s the strongest evidence that there’s real demand supporting the AI buildout.
But the RPO is also highly concentrated. In January, when it stood at $625 billion, 45% was tied to OpenAI — roughly $281 billion committed by a single customer that is still losing money. Take OpenAI out of last quarter’s figure and the growth drops from 99% to 26%.
Then in April, Microsoft and OpenAI revamped their partnership, and OpenAI ended its exclusive commitment to run on Azure.
Reliability: On July 23, a bug in Microsoft’s automated network maintenance tooling cut a West US Azure data center off from the company’s global network, knocking out Teams, SharePoint, OneDrive and Copilot Chat for about five hours. Microsoft has published a preliminary post-incident report, and a final one is due within two weeks.
The outage falls in the quarter that began July 1, so it won’t appear in Wednesday’s numbers. But it comes as Microsoft is asking businesses to hand AI agents real control of their operations.
Retirement charge: Wednesday’s results will include about $900 million in one-time costs from Microsoft’s voluntary retirement program, the first in the company’s 51-year history. Hood said roughly $350 million falls in the cost of revenue and $550 million in operating expenses.
About 8,750 U.S. employees were eligible — 7% of Microsoft’s U.S. workforce — and about 30% accepted, Chief People Officer Amy Coleman confirmed in an interview with GeekWire, in line with what the company expected. Those departures reduced the size of the 4,800-job cut Microsoft announced July 6, which happened after this quarter ended.
Even with the retirement costs, Microsoft told investors it expects operating margins for the full fiscal year to be about a point higher than last year. Hood also said on last quarter’s call that headcount declined year over year and will keep declining in fiscal 2027.
Windows: Microsoft expects Windows OEM revenue — what PC makers pay to put Windows on their machines — to decline close to 20% this quarter.
A few factors are driving this:
Last year’s wave of PC upgrades, when support for Windows 10 ended, makes for a tough comparison.
PC makers stocked up on parts and machines ahead of rising memory prices and are now working through them.
The PC market itself is slower, because memory prices have made computers more expensive.
The memory shortage is hitting Microsoft a few different ways. In addition to adding about $25 billion to the company’s capital spending this calendar year, as noted above, it lowers what Microsoft earns from Windows. Also, in late June, Microsoft raised Xbox console prices by $100 to $150, saying storage and memory costs had risen more than 2.5 times.
This week: Facebook parent Meta reports the same afternoon as Microsoft, with Apple and Amazon on Thursday and Alphabet already out. Check back Wednesday afternoon for coverage.

 Login