
โŒ

Reading view

There are new articles available, click to refresh the page.

Validation Workflows

Across all my posts about C2PA's flaws, there's one aspect that has been bothering me for years: you can upload the exact same picture to different C2PA validators and get conflicting results. It wasn't until I began flow-charting the validation process that I realized the scale of the problem.

In this blog entry, I'm going to compare the workflows used by TLS (required by HTTPS), Secure Evidence Attribution Label (SEAL), and C2PA. I'm specifically comparing TLS and SEAL to C2PA because (1) C2PA's proponents often compare C2PA's use of X.509 to TLS, and (2) C2PA's Chief Architect prompted me to come up with an alternative to C2PA, so I created SEAL.
TLS

Transport Layer Security (TLS) provides the framework for encrypting data over the internet. It uses a common container format called X.509, which holds the public keys and related meta information (issuer, subject, validity date range, etc.). Every web browser should handle the TLS information the same way, using the same logical flow.

TLS 5-step flowchart

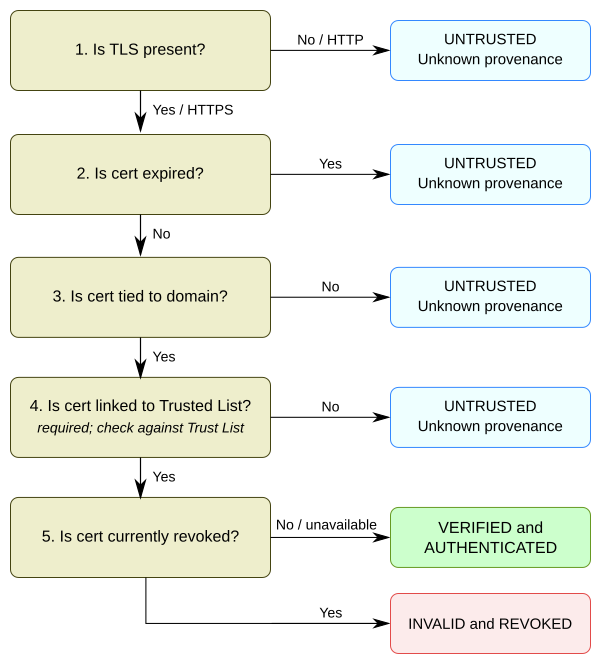
TLS uses a very straightforward flowchart:
  1. Is TLS present? If it isn't, then your connection is using plain old HTTP: unencrypted and untrusted. If it is present, then you're using HTTPS and can check the X.509 certificate information.

  2. Is the TLS certificate expired? An expired certificate should not be used. At minimum, it will generate a browser warning because the certificate is untrusted.

  3. Is the TLS certificate tied to the domain? Buried in the X.509 is a field that says "this certificate is associated with this domain name." For example, the certificate from my blog says that my certificate is associated with "hackerfactor.com" and "*.hackerfactor.com". If your browser sees my certificate associated with a different domain name, it will stop your access and inform you that the connection is insecure.

    Sample browser insecure error message

  4. Is the certificate linked to the trusted list? Your computer (and browsers) have a list of known trusted certificates, and the X.509 certificate defines a trust chain. This chain should link back to the trusted list. If it doesn't, then the certificate is untrusted, even if it came from the correct domain name.

  5. Is the certificate currently revoked? This doesn't just check the last certificate; it's designed to check every certificate in the chain. If any of them are revoked, then the certificate is explicitly invalid due to revocation. If it's not explicitly revoked, then it's valid, verified, authenticated to the domain, and chains to the trusted list. However, this has a soft-fail condition: if the revocation status cannot be determined, then it is treated as being "not revoked".

    This "Is it revoked?" check is actually a little more complicated. For example, the revocation may include a date. If the current time (for HTTPS) is before the revocation date, then the certificate is still valid. This may not make too much sense for real-time web requests because the current time should always be after the revocation date. However, this is required for checking digital signatures at a later time. If it was signed before the revocation date, then it's valid. If it's signed after, then it's revoked and invalid.
The precise order of these steps can vary. For example, you can check the domain name (Step 3) or trusted list (Step 4) before the expiration (Step 2) and it won't change the result. Regardless of the order, these rules are standardized.

There can be differences between implementations. Browsers mainly differ in trust stores (Step 4) and revocation policies (Step 5). Those differences are small, publicly documented, and seldom change:
  • Browser differences: Mozilla, Apple, Microsoft, and Google each maintain their own trusted lists (aka root store or trust store), but they coordinate through the Common CA Database (CCADB). This way, trust stores overlap significantly. Operating systems often add a few roots of their own (such as Microsoft or Apple adding trusted roots for their own update services). Similarly, private enterprise and government networks may include custom internal CAs in the local trust stores. (The U.S. Department of Defense and federal networks are classic examples.)

  • Revocation differences: Browsers can use different revocation methods, and these can change over time. For example, Chrome used to perform live revocation checking, but now uses downloaded lists (CRLSets). Firefox introduced its own downloaded-list mechanism, CRLite, in Firefox 137 (April 2025), and disabled OCSP for domain-validated certificates in Firefox 142 (August 2025).
Beyond these documented variations, validation remains consistent.

SEAL

While SEAL doesn't use X.509 certificates, it does use a similar flow chart. However, the flow is a little complicated because of the optional embedded public keys.

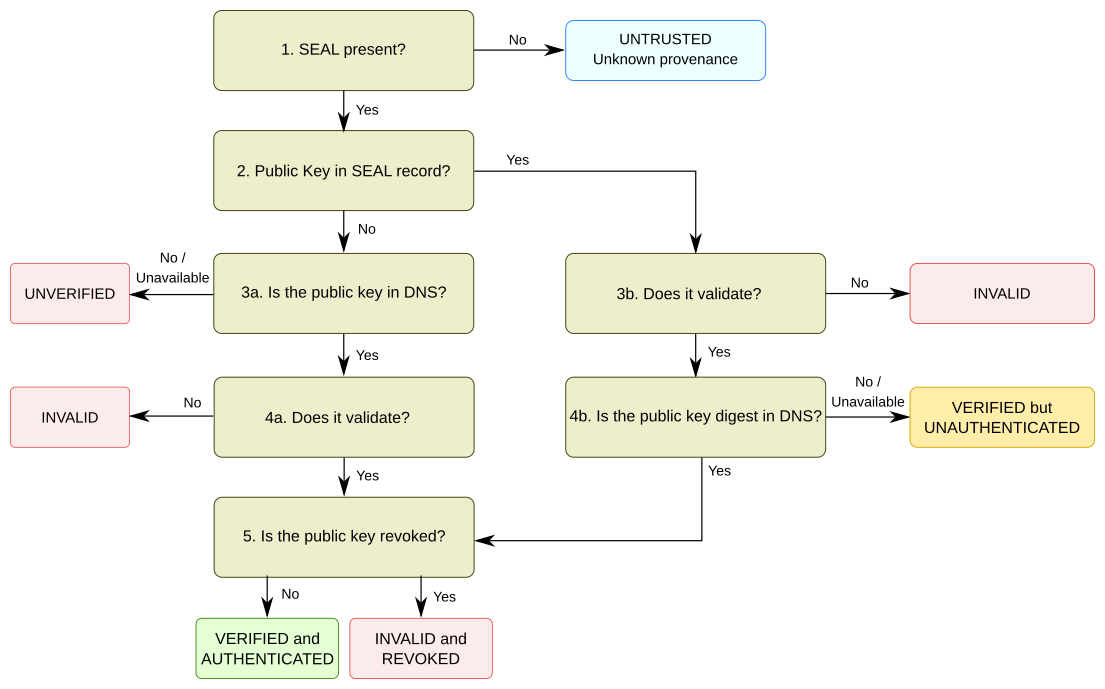
SEAL 5-step, 2-path flowchart
  • Is SEAL present? If there is no SEAL record, then there is nothing to check.

  • Is the public key in the SEAL record? This is an encoding option because post-quantum crypto keys can be too large for storing in DNS. Today's typical usage stores the public key in DNS. (If there is a public key then jump to 3b, otherwise continue to 3a.)

The typical use case today relies on DNS for storing the public key:

  • Is the public key in DNS? Most of the time, you don't have the public key in the SEAL record, so you retrieve it from DNS. If DNS is unreachable or the record doesn't include the public key, then the data cannot be verified.

  • Does it validate? You now have the public key from DNS. Does it validate the signature? If it doesn't, then the signature is invalid.

Following the alternative branch, when the public key is embedded in the SEAL record:

  • Does it validate? Since you have the key, check if the signature validates. If it doesn't, then it's invalid. But if it does validate, then you haven't authenticated the signature yet.

  • Is the public key's digest in the DNS? This check allows you to attribute the key to the signer. Without this, you have verification (the crypto worked) without authentication (you don't know who signed it).

Whether you check DNS and then validate (3a/4a) or validate and then check DNS (3b/4b), passing both tests still means checking for revocation:

  • Is the key revoked? SEAL doesn't use a trust chain; there is only one revocation to check and it comes from the DNS record. As with TLS/X.509, there are actually a bunch of 'if'-conditions around date revocation and default revocation records, but the basic gist is "Is it revoked?" If it is revoked, then the signature is invalid due to revocation.

    And if it isn't revoked? Then it's valid, with a verified signature and authenticated to the domain that holds the public key.

Every SEAL validator should handle this workflow the same way, so they should all get the same results under the same conditions. You might have noticed that I included the caveat "under the same conditions". If one validator can access DNS and another validator cannot (e.g., it's offline), then you may get different results. But even with this difference, the user can immediately tell why there is a difference. (Seeing that they cannot reach DNS because they are offline probably won't be a surprise to the user. And as mentioned in the previous blog entry, SEAL trusts DNS.)
C2PA

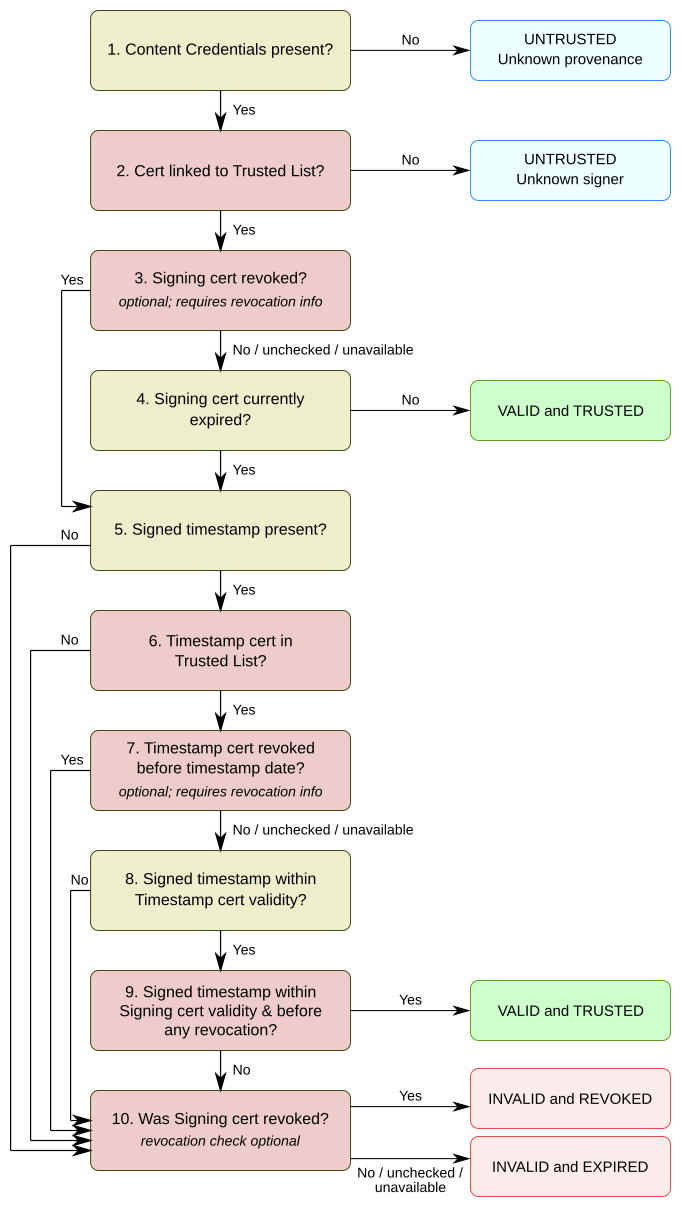
Compared to the other validation flows, C2PA is a long and complicated mess. It has 10 steps, 6 with optional implementations, and a major flow decision based on an optional signed timestamp (see Step 5).

C2PA 10-step conditional flowchart

  1. Are Content Credentials present? Simple and straightforward; you cannot validate it if it doesn't exist.

  2. Is the certificate linked to the trusted list? The C2PA spec does not recommend any specific baseline root store. Instead, every instance (generator, signer, and validator) decides what root stores they want to include. There are currently many independent root stores, and most have no overlap:


    I'm sure these are not the only C2PA trust lists; these are just the ones I currently know about.

    The X.509 certificate contains details about the signer responsible for the cert. However, it does not specify which trust list should be used or where to get the trust list.

    Asking "Is the signing certificate linked to the trusted list?" sounds like a simple yes/no question. However, it isn't. This is because every organization can use a different list! A user trying to validate the media should know which trust lists are being used and when they were last updated. If the validator includes multiple trust lists, then you also need to know the validator's rules for combining them. Unfortunately, validators don't generally provide this information.

    While TLS does have a similar problem with trust list variations, the significant overlap between different platforms minimizes any differences. In contrast, different C2PA trust lists often have no overlap (e.g., the lists from IPTC, Sony, and C2PA are completely different), leading to very different results.

    According to the W3C minutes, C2PA's Chief Architect Leonard Rosenthol was asked why they were using a separate trust list. His reply: "We've been trying to use the same model, just has different trust anchors." No, this really is not the same model. TLS and the significant overlap between trust store entries on different platforms are about interoperability; C2PA's vastly different trust stores with no required commonality are about enabling isolated walled gardens.

  3. Is the signing certificate revoked? X.509 supports two different revocation methods:

    • CRL: A Certificate Revocation List is a static list that you can download. It includes the cert serial number for every revoked certificate. In theory, the CRL can grow to be very large. In practice, they are typically tiny.

    • OCSP: The Online Certificate Status Protocol is newer than CRL, but the CA/Browser Forum has made OCSP optional and requires CRLs. Some CAs and browsers have moved away from OCSP entirely: Let's Encrypt and Google Trust Services have stopped issuing OCSP responses for most certificates, Firefox is disabling OCSP checks in favor of CRLite, and Chrome doesn't rely on live OCSP checks by default. In effect, OCSP is becoming obsolete.

    For CCADB-based lists, most of the certs have no defined revocation method. (On my Ubuntu system, 122 of the 146 certs had no defined revocation method.) This isn't a big problem for TLS since network connections are ephemeral. If you no longer trust a root, then the trust list managers will remove it from the list and your browser will stop trusting it after the next update.

    On the other hand, C2PA uses static signing certificates, not ephemeral network connections. This introduces a lot of problems. For example:

    • Revocation checking is optional and usually not implemented.

    • CRLs are explicitly not supported. C2PA only supports OCSP. (This is an ironic choice: C2PA is relatively new, yet it requires a deprecated technology. It's also ironic given that C2PA claims to care about privacy, while industry groups are rejecting OCSP due to privacy concerns.)

    • C2PA explicitly permits "OCSP Stapling", where the OCSP record is attached to the C2PA's manifest. But this is optional, typically not present, and has other problems (that really deserve a separate blog entry). OCSP Stapling is not a reliable solution.

    With C2PA, revocation checking is optional and different validators can return different results based on how they query for revocation. But it gets a little worse: C2PA supports an optional signed timestamp. This means that a revoked signing certificate could appear un-revoked based on the timestamp. (See Steps 5-9.)

  4. Is the signing cert currently expired? If the cert is not revoked (including unchecked or unavailable), then it is valid and trusted. Otherwise, you need to check for a signed timestamp (Step 5).

  5. Is there a signed timestamp? This is the point where C2PA's logic flow significantly deviates from TLS. If the signing certificate is expired or revoked, then a signed timestamp can still make it appear valid.

  6. Is the timestamp cert in the trusted list? To reach this step, we have an expired or revoked signing cert, but a signed timestamp is present. Do we trust the signed timestamp? This is similar to the "inconsistent lists" problem seen in Step 2, except that the C2PA and ITL use separate trusted lists for timestamp certificates. This allows validators to potentially mix-and-match. For example, they might permit a signing certificate from the IPTC trust list but the timestamp certificate from the "C2PA TSA Trust List" (which is different from the "C2PA Trust List").

  7. Is the timestamp certificate revoked before the timestamp date? As with Step 3, revocation checking is optional. Moreover, some validators seem to only check the last certificate in the chain for revocation, while others check the entire chain.

  8. Is the signed timestamp within the timestamp certificate's validity period? Every cert has a "Not Before" and "Not After" range. This is a sanity check step to make sure the trusted timestamp authority (TSA) used a date during the TSA cert's validity period. (A malicious TSA can still backdate or postdate the signature, but it must be within the "Not Before" and "Not After" range.)

  9. Is the signed timestamp within the signing cert's validity period and before any revocation? While Step 8 checked the signed time against the timestamp cert, this step checks the signed time against the signing cert. If the signed timestamp predates the signing cert's revocation date, then the cert is still valid. This permits the continued use of an expired or revoked signing cert (effectively un-expiring or un-revoking it). Unfortunately, I've seen some validators just check if the timestamp is valid, and not check if the revocation date predates the timestamp.

  10. Was the signing cert revoked? This is the final failure condition and triggers when the signing cert is invalid. Was it invalid due to the optional revocation checking (invalid and revoked) or expiration (invalid and expired)?
As with the other workflows, the specific order of these steps can vary. For example, an implementation might check the certificate expiration (Step 4) before checking the trust list (Step 2), but that just makes the line diagram a little more complicated. Changing the step ordering shouldn't change the decision process or final outcome.

C2PA's validation flow includes six steps where validators can make their own choices (Steps 2, 3, 6, 7, 9, and 10). Since every validator can do this differently, every validator can generate different and conflicting responses to the exact same media.
  • If a C2PA validator says you can trust the signature, there could always be another validator that says you cannot.

  • If a validator says you cannot trust it, then you can probably shop around to find a validator that says it is trustworthy.
This is the main difference between TLS, SEAL, and C2PA. With TLS and SEAL, the validation process is consistent and reliable. With C2PA, it is inconsistent by design.

In this blog entry, I covered how the logic flows differ. So far, that's all theory. In the next blog entry, I'll use real-world examples to demonstrate how different C2PA validators generate different results for the exact same media.

SEAL Tested, Hardened, and Honest

In the late night and evenings (and between meetings), I've been working on projects related to SEAL (Secure Evidence Attribution Label) and C2PA.

C2PA is the Coalition for Content Provenance and Authenticity. Don't read too much into the name, because it does not provide any kind of content authenticity or reliable provenance. Readers of my blog have seen me repeatedly document design flaws, demonstrate how C2PA's approach is unreliable, and how it can be used to create signed forgeries that, under C2PA's solution, look identical to untampered media.

Back in 2023, I was posting a series that disclosed C2PA's vast array of critical problems. It culminated in a chat between representatives from C2PA and CAI (all Adobe employees) and myself with a coworker. C2PA's Chief Architect acknowledged the problems and asked if I knew of any alternatives. (This false dichotomy bothered me because lacking another alternative does not mean that C2PA works.) A few weeks later, SEAL was created. (It was initially called VIDA, but was renamed to SEAL a few months later.)

Today, SEAL has full specs, implementations in C and JavaScript, a free remote signing server (SignMyData) with web-based validator (that does not require uploading content off your computer), and more!

SEAL Updates

Behind the scenes, SEAL has had some big updates.

I'm happy to say that SEAL has survived a serious review by some folks at the University of Maryland, Baltimore County (UMBC). They have a Protocol Analysis Lab (PAL) and Cyber Defense Lab (CDL) that evaluated SEAL in depth. They didn't just review the specs and code, they used formal methods with CPSA (Cryptographic Protocol Shapes Analyzer) to model the solution. Their findings?
  • Very positive: SEAL does what it claims. It provides a strong cryptographic signature over the file, identifies the signer, and prevents impersonation attacks. (These same goals have serious design and implementation weaknesses under C2PA. I can create authentic-looking forgeries with C2PA; with the fixes suggested by PAL/CDL, I cannot create authentic-looking forgeries with SEAL.)

  • Exclusion range: They found two nasty exploits related to the exclusion range. Basically, the specs didn't explicitly say that the exclusion range for computing the signature must be minimal. A malicious user could exclude the SEAL record from the signature, permitting post-signing alterations.

    Fortunately, both of these bugs were easily addressed in the specs and in the code. (The C implementation, SEAL-C has the fix, while the JavaScript version, SEAL-JS is coming.) The fix is fully backwards compatible with previous signatures. (If you intentionally made a lax exclusion range, it will be flagged and either warned or rejected depending on whether it touches the SEAL record itself.)

  • Security Documents: At the request of UMBC PAL/CDL, I've added a Security Considerations document. This describes many of the attacks, countermeasures, and mitigation options that they identified.

  • Missed Revocation Condition: In the JavaScript implementation, PAL/CDL found a missed if-condition. The fix has been submitted and checked in.
The issues were the only SEAL-specific findings, and they have been addressed.

Along with the SEAL-specific problems, PAL/CDL found a few other issues that impact virtually every public/private key cryptographic solution. The issues? Revocation and DNS.

The Revocation Problem


When using public/private key cryptography (PKI), what do you do if the private key is compromised? That's the revocation problem. The folks at PAL/CDL found a nasty attack that impacts almost every PKI solution. It definitely impacts both SEAL and C2PA, even though we have very different PKI implementations. It also impacts DKIM (email), signed PDF documents, single-sign-on (SSO), and pretty much all other solutions that use a cryptographic signature.

The problem: when a key is compromised, you revoke it. You can even attach a date for when the revocation takes effect. An attacker with the stolen key can easily backdate new media to a time before the revocation date. (Ouch!)

C2PA currently has no solution to this problem. They simply rely on a trusted signing authority (TSA) and hope it will never be compromised. But that just kicks the problem down the road. If a TSA's private key is compromised, then it can indefinitely backdate material to a time before the revocation.

Even worse: C2PA requires an RFC3161-compliant timestamp server. According to RFC3161, every TSA certificate MUST support revocation. C2PA currently has 22 C2PA-approved TSA certificates, of which 16 do not have any kind of revocation enabled. (C2PA's own trusted list is not compliant with C2PA's specs.)

With SEAL, we have a clever workaround. If the media is signed using a revoked key, then check the key's date. If it was signed after the date, then it is clearly revoked. But if it's signed before the date? Then it can be 'suspect' (neither valid nor invalid). To confirm the validation, it must be compared against some kind of independent service to make sure it existed before the revocation date. (Huh?)

Basically, if the media is dated 2026-08-15 and the revocation date is 2026-08-30 (after it was signed), then see if you can find some other instance of the media before the revocation date. For example:
  • Is it hosted on a news site, the Internet Archive, tagged by some kind of block-chain, etc.

  • If it's legal evidence or a tracked file, was it received before the revocation date?
If it can be shown to have existed before the revocation date, then it's still valid.

But what if you can't find it anywhere else? Then the file is suspect. It could be valid, but you need to confirm it using some other means.

This same cross-validation approach works for other documents. However, as far as I can tell, only SEAL explicitly defines this pre-revocation validation approach.

The DNS Problem

The Domain Naming System (DNS) is what converts a hostname (like "hackerfactor.com") into a network address (e.g., 104.21.67.249). The entire Internet is based on DNS. Even if you don't think your PKI solution uses DNS, you're using DNS.

For SEAL, the DNS usage is explicit: the public key is stored in a DNS record. DNS is only required during validation. The DNS record attributes the public key (for verification) with the signer and includes any revocation information.

For C2PA, the DNS usage is implicit, optional (in a bad way), and needed for both signing and validating. How C2PA uses DNS:
  • C2PA has different kinds of signatures. The minimum signature requires a signing cert. If you're part of C2PA's conformance program, then the signature is only good for 366 days (Assurance Level 1) or 90 days (Assurance Level 2). When the certificate expires, you can no longer validate the signature. You need DNS to access the conformance program listing, check if the signer is a conforming product, and retrieve the C2PA list of trusted certificates.

  • To keep the signature valid for more than 366 days, C2PA requires the use of timestamp from a known Time Stamp Authority (TSA). This requires Internet access, which requires DNS. Keep in mind, using a TSA is optional according to the C2PA specs.

  • The Google Pixel 10 tries to get around this network requirement by having a built-in TSA. That's good. However, their signing certificates all come from Google. The device pre-loads a handful of certs over the Internet (DNS!) and uses them for signing.

  • C2PA explicitly makes revocation checking optional. (This is the point where every cryptographer wakes up and shouts "WTF!") C2PA explicitly forbids the use of a downloadable certificate revocation list (CRL). Instead, they suggest (not require) the use of the Online Certificate Status Protocol (OCSP). (Let's ignore the fact that all of industry is moving away from OCSP and requiring CRLs.) As noted in the C2PA specs (my bold for emphasis):
    14.5.2. Certificate Revocation

    X.509 certificates support revocation status queries. A claim generator should use the Online Certificate Status Protocol (OCSP, RFC 6960) and OCSP stapling (as originally conceptualized in RFC 6066, Section 8, but implemented as described in this clause) to implement revocation. The claim generator shall not use Certificate Revocation Lists (CRLs, RFC 5280).
    ...
    15.9. Validate the Credential Revocation Information

    For CA certificates, the validator should determine revocation status as indicated in the Authority Information Access (AIA) extension as described in RFC 5280, section 4.2.2.1. The validator should make use of relevant OCSP responses included in the C2PA Manifest if the AIA extension indicates that OCSP is available.
    In spec-speak, "should" is optional, while "shall not" is a requirement. With OCSP, the certificate says where to access the online validation service (via URL, which means using DNS to find the service). Then again, CRLs also require using a URL (DNS) to download the list.
Regardless of whether you are using SEAL, C2PA, or some other provenance solution, what can a malicious actor do if they can alter your DNS query or the DNS response?
  • At best, they can block the reply and make a valid signature appear unverifiable.

  • At worst, they can alter the reply and make a valid signature appear revoked or invalid.

  • They can make a revoked signature appear valid or unverifiable.

  • If they can send you fake media to evaluate, then they can combine their own fake signature with a hijacked DNS response to make the signed file appear valid.
C2PA only defines two OCSP states: revoked and valid. If it's not revoked, then it's valid. If the network request cannot be completed (or is never attempted because it's optional), then the certificate appears valid. This means that two different validators can reach conflicting conclusions about the same media, and both can be right! (One validator says the media is invalid due to revocation, and the other finds it valid because it never checked.)

In contrast, SEAL's revocation checking is mandatory and it distinguishes between valid, invalid, and unverifiable. If there is a network or DNS problem, then it becomes unverifiable. Because this check is required, every up-to-date SEAL validator will reach the same conclusion about the same media. There is no validator inconsistency.

Hardening DNS

PAL/CDL did have a few suggestions to secure DNS, but I don't think they are practical today:
  • DNSSEC: DNS is normally unprotected. A malicious man-in-the-middle could easily change the query or the response. DNSSEC signs the DNS request and reply, ensuring that the results cannot be tampered with.

    However, at most domain registrars, DNSSEC is not enabled by default. User devices (Linux, Windows, MacOS, iOS, and Android) do not enable DNSSEC by default, and enabling it can be complicated (depending on the platform). This low adoption rate is why we cannot require DNSSEC right now.

    Moreover, DNSSEC breaks some technologies, which impacts adoption. For example:

    • Captive portals, where you must agree or login before connecting to the internet, work by hijacking the first DNS request. If you use DNSSEC, then the captive portal approach won't work and you'll see a browser error about a DNS problem.

    • DNSSEC isn't supported by most embedded devices because it is too resource-intensive for many small IoT systems.

    • Many companies run an internal DNS system that differs from the public DNS. (E.g., 'hackerfactor.com' from within my office network resolves to the direct server IP address, but the rest of the world uses a global DNS that directs to CloudFlare's address for DDoS-protection.) Enabling DNSSEC breaks this internal/external configuration. (After I enabled DNSSEC for hackerfactor.com, and before I could fix the problem, there was an hour where I couldn't access my own site from within my office!)

    Enabling DNSSEC can break many services, even if the DNS client allows downgrading from DNSSEC to DNS.

  • DoH and DoT: DNS is designed to propagate requests between DNS servers, until it finds a response. The propagation is unencrypted and vulnerable to alteration. DNS-over-HTTPS and DNS-over-TLS are used to encrypt the first hop of the query, from you to your direct DNS resolver.

    In theory, if the entire end-to-end path -- from client making the request to the authoritative response -- is encrypted, then this is a great solution. The problem is, you only know if your first hop is encrypted, not if the rest of the relayed path is encrypted. Also, these protocols have a chicken-and-egg problem: you need DoT/DoH to do the DNS lookup, but you need DNS to get and validate the TLS certificate before you can use it. Between newness, lack of "out of the box" configurations, and the chicken-and-egg problem, both of these protocols have even less support than DNSSEC.
While an ideal solution would require both DNSSEC and DoT (or DoH), the practical response is that these are recommended, but cannot be required. (SEAL recommends using them when possible, while C2PA's documentation doesn't mention this problem at all.)

Fortunately, DNS is a pretty good solution as-is. (Not perfect, but good enough.) For example:
  • The top level authoritative servers are hardened from decades of attacks.

  • The hundreds of thousands of intermediate relays are widely distributed, making it virtually impossible for an attacker to hijack or poison all of them.

  • The attacker doesn't know who, when, or from where the next DNS query will be generated. This makes it extremely difficult for them to attack a specific DNS lookup request.

  • DNS caches results. Even if the attacker manages to poison the cache on one DNS server, they must constantly refresh the attack or bad data will expire. (I'm not saying that DNS spoofing isn't possible. I'm saying it's not trivial to do, must be constantly re-applied, and will likely be noticed.)
While the threat doesn't go away, it is certainly mitigated. This is not secure by design; this is secure by infeasibility: an attacker cannot realistically poison DNS for the entire world at the same time, nor can they do it indefinitely.

An Honest Opinion

While C2PA defines an entire ecosystem (with every part vulnerable to fraud), SEAL focuses on one part and implements it successfully. The exclusion-range bugs that UMBC's PAL/CDL found were SEAL-specific, narrow, and have been fixed! That's the kind of finding you want from a formal review. Revocation and DNS are a different story: they're not bugs in SEAL or C2PA, they're weaknesses in every known solution.

The honest takeaway is that neither SEAL nor C2PA "solves" revocation or DNS trust; nothing solves it completely. What differs is how each system fails. C2PA's answer to a compromised TSA is to hope it doesn't happen and make revocation checking optional when it does. SEAL's answer is to treat a signature that pre-dates a revocation as suspect and to seek out independent corroboration, rather than defaulting to valid or invalid. That's not a magical fix, but it's an honest one: it tells you when you don't actually know, instead of quietly defaulting to "trust it."

The DNS problem is even less solvable in the near term. DNSSEC and DoH/DoT are the "right" answers on paper, but neither is a realistic requirement today. Both SEAL and C2PA are stuck relying on DNS's de facto resilience (scale, caching, and distributed relay network), rather than any cryptographic guarantees. But only SEAL is explicit about the difference, which is essential for anyone using this kind of provenance data as legal or journalistic evidence.

None of this is a reason to abandon content provenance. It's a reason to be specific about what a "verified" label actually promises. SEAL's approach, to identify facts and not fake certainty, is a smaller claim than C2PA's, but it is a claim that SEAL can formally provide.

Finishing Touches

In the United States, today is Labor Day, when we honor the American labor movement and the contribution of laborers. Considering how the middle class and laborers are currently under attack, with massive inflation, a growing gap between the ultra-rich and everyone else, and AI replacing workers, it's more important than ever to recognize this holiday.

For many people, today is a three-day weekend. One of my friend's kids knows that I'm self-employed. She asked if I got Labor Day off? I laughed. Nope, I use the extra day to catch up on all of my half-finished projects.

Among the things I accomplished?

Power!

I finally completed the DIY solar panel project that I started last year by putting the battery in a cabinet. It may not sounds like a big deal, but I can walk by the server rack without fear of electrocution.


Mounting it in the cabinet was much more difficult that it sounds. It required drilling holes through steel for the power cords, and mounting rubber grommets to prevent the sharp edges from damaging the cables. Inside:
  • The battery has plenty of space away from the walls so it won't short out, and it's sitting on a half-inch thick insulated foam mat to keep it isolated and safe.

  • A temperature sensor monitors it in case of overheating. The battery currently sits at 75ยฐF (23.9ยฐC) when idle or in use, and rises to 78ยฐF (25.6ยฐC) when charging. That's the sweet spot for keeping the battery running longer.

  • Fort Collins has surge pricing for electricity, where late afternoon's power is over 4 times more expensive. While I use this project for solar power, I'm also using it for load shifting. That's when you charge using cheaper power so you can use it later, when the price increases.

    To help with the load shifting, I mounted a battery charger plugged in at the bottom of the cabinet. The charger is controlled by a smart outlet. This allows the automated system to partially charge the battery at night, when electricity is cheap, and use the battery when power is more expensive.
On a typical day, this homemade solar solution provides about 5 hours of power on overcast days, and up to 9 hours when it's sunny. It's saving me about 30kWh per month. (That's about 28kWh when I subtract the charger's usage.)

At the current savings rate, it will probably pay itself off in 8 years. That's not bad for a fun (and dangerous) home project.

Music!

Last year, I wrote about how I sometimes relax by switching gears and doing something completely different. Yes, I'm still writing my bad poetry and still trying to put it to music. After a year, I'm happy to announce another album by Brain Dead Frogs: Reflections.


I often hear people say that AI music sounds like crap. However, the real problem is that people often put very little effort into the composition. Too many artists combine AI-written lyrics with AI-music, and very little manual effort. This results in meaningless lyrics, random quips, and no storyline. When the lyrics are dull, the music ends up sounding equally flat. On top of this, there's often no human curator to filter out the bad songs. This results in a flood of bad AI music.

With this album, I wrote all of the lyrics, selected and edited the compositions (sometimes fighting with Suno for days to make it sound the way I want it to sound), and manually curated the collection into an album. (I wrote over 20 songs, but only included the 12 best ones on this album.) The net result combines human-written lyrics with AI-generated music and vocals.

As far as topics and genres go, I have eclectic tastes. There's everything from 80s Big Hair Rock ("Bald") to Reggae ("I Ate The Last Unicorn"), latin guitar ("Dangerously Competent"), and even a Scottish Garage Band song written in Doric! (I used AI to translate my English poem into this Scottish dialect; it took a few iterations and help from a Doric dictionary.)

Since it's human written and human curated, I certainly hope it sounds better than typical "AI crap music."

The House!

After I left the office, I went to work at home. I mowed the lawn, swept the floor, and vaccummed the carpet. (It's allergy season, and this kind of cleaning really helps.) I also began moving piles of old stuff that we need to get rid of. On top of this, someone left a bunch of warm chocolate chip cookies on the counter, and I needed to help, uh, put them away!

If today was a holiday for you, then I hope your Labor Day was relaxing, fun, or productive. For me, I'm ready to get back to programming.

C2PA and Pixel Glitter Milk

The news has been full of incredible reports recently. Like this one:
BREAKING: Iowa Farmers Discover "Glitter Milk" from Unicorn Cows
DES MOINES, IA - May 25, 2026

A handful of Iowa dairy farmers say they've started milking unicorn cows, and the results have local nutritionists scratching their heads.

The milk sparkles.

"It's real pretty in the morning sun," said Polk County dairy farmer Dale Hutchins. "First time I saw one with a horn, I figured I'd accidentally bought somebody else's livestock. Then it started making glitter milk."

Researchers examining the milk say the shimmering particles appear to be naturally occurring protein crystals rather than actual glitter. Preliminary tests found the milk to be perfectly safe, with unusually high levels of vitamins and minerals. One eight-ounce serving reportedly contains an entire day's recommended vitamins A, C, D, E, B1, B2, B3, and B12.

"The numbers keep coming back looking impossible," said one nutritional biochemist involved in the testing. "Either we've discovered something genuinely remarkable, or one of our graduate students has been replacing the samples with breakfast cereal."

Children participating in a small nutrition study reportedly loved the milk, although several parents complained that the spilled cereal was "way harder to clean because the glitter goes everywhere."

Federal regulators have not commented, and the Iowa Department of Agriculture says it's waiting for additional testing before making any official statements.

If production continues, glitter milk could begin appearing in a few Midwestern co-ops later this year for about $8.99 a half-gallon.

- Staff Reporter, Heartland Agricultural Digest

As proof of this incredible story, we have a photo of a farmer milking a unicorn cow!


According to the metadata:
  • The photo is from a Google Pixel 10 Pro.

  • The picture has cryptographically signed C2PA metadata. This data says it is "Created by Pixel Camera". The C2PA metadata even includes a 1024x768 preview image of the photo. Everything in the cryptographically signed manifest is consistent with a real photo from a Google Pixel camera.

  • In my blogs, I have repeatedly detailed ways to create "authenticated forgeries" using C2PA. However, the one thing I cannot forge is the cryptographic signature itself. This picture has a valid X.509 certificate chain that traces back to the C2PA-managed trust list. The certificate is issued by Google for the Pixel cameras. To my knowledge, nobody can forge this signature; this was really signed by a Google Pixel camera.

  • The cryptographic signature includes a signed timestamp. The timestamp is dated "2026-05-25 17:04:19 GMT" and the signer is Google. Again, I cannot forge this signed timestamp; this is real.

  • The C2PA organization has a list of conforming products. If we upload this glitter-milk picture to Adobe's Inspect service (a conforming product), it reports that this is a legitimate photo from a Pixel Camera, recorded on May 25, 2026.

  • The Adobe-run Content Authenticity Initiative (CAI) provides C2PA implementations. Their CAI Verify validator reports that the contents shows "captured media", came from Google LLC, issued by a Pixel Camera with a notation that it is "Conformant" (a conforming product), and includes a verified timestamp of "May 25, 2026 at 11:04 AM MDT". (They show the time relative to your own time zone, and I'm in MDT.)
Everything says that this is a legitimate photo from a Google Pixel camera.

There's just one problem: It's a forgery. The picture is AI generated and the news article is fiction, but Google's signatures are real.

Industry best practices for responsible disclosure suggest giving vendors 45-90 days to respond. Since we are 90 days past the vendor notification, I'm following industry best practices and making the details public.

Early Reporting History

I've been working closely with a group of researchers at the University of Maryland, Baltimore County (UMBC). They have a Provenance and Authenticity Standards Assessment Working Group (PASAWG) that has been formally evaluating solutions like C2PA. (While I'm a regular attendee, I'm there as a guest and resource, not a member.) One of the things I like about PASAWG is that they have a more formal way to report bugs than my typical "shouting into the blogosphere".

Nearly a year ago (September 2025), Google made a big announcement about the Pixel 10 product line. They explained "How Pixel and Android are bringing a new level of trust to your images with C2PA Content Credentials". Their bullet points (with their bold emphasis):
  • The Pixel 10 lineup is the first to have Content Credentials built in across every photo created by Pixel Camera.

  • The Pixel Camera app achieved Assurance Level 2, the highest security rating currently defined by the C2PA Conformance Program. Assurance Level 2 for a mobile app is currently only possible on the Android platform.

  • A private-by-design approach to C2PA certificate management, where no image or group of images can be related to one another or the person who created them.

  • Pixel 10 phones support on-device trusted time-stamps, which ensures images captured with your native camera app can be trusted after the certificate expires, even if they were captured when your device was offline.
As Carl Sagan said, "Extraordinary claims require extraordinary evidence." So we began to take a closer look.

Two months later (November 2025), PASAWG, one of my coworkers (Shawn), and I reported to representatives from Google and C2PA about a potential problem with Google's Pixel camera. In particular, we theorized that someone with root on the device could sign any picture as if it were from the camera. While the C2PA representative listened to the concerns, the Google representative was adamant that this type of attack was not possible. In particular, the signing keys are stored in a secure chip and cannot be extracted, and the Android architecture prevents unauthorized applications from accessing the keys.

More Researchers

Unrelated to our research and reporting, I had been contacted by other researchers who thought that they found the same theoretical flaw. One in Canada, one in the US, and one in the UK; this shows that other people are thinking the same way. (And just because I didn't list any state-sponsored threat actors doesn't mean they are not also evaluating this vulnerability.)

Three months ago (May 2026), a researcher named retr0id (David Buchanan) contacted me. He took the exploit from theoretical to implementation. He sent me two sample pictures that were signed using a Google Pixel device. To say I was impressed is an understatement. But I wanted hard proof that he had implemented it. I sent him a challenge:
  1. Using ChatGPT, I generated the source picture of a unicorn cow being milked.

  2. ChatGPT's picture was a PNG with an embedded C2PA manifest. I stripped out the manifest and re-encoded the picture as a JPEG.

  3. I found a different picture from a Pixel 10 and copied over the metadata. This way, the forgery had all of the correct metadata fields for that camera. I intentionally left the EXIF date wrong (dated 2025-08-29 02:10:17 GMT) and set the EXIF camera model name to "Pixel 10 Pro Totally Legit".

  4. I sent my forgery to retr0id.

  5. Two minutes later (not kidding), retr0id sent the signed forgery back to me. That two minutes includes receiving the image from me, transferring it to the Google Pixel for signing, signing it, and zipping it up to send back to me. Just the data transfers probably took him a minute and a half. This means that it's mostly an automated exploit. (He's released some of his tools on GitHub and a technical write-up on his blog.)
The example demonstrates how someone with a Google Pixel device could sign any picture (real, fake, AI generated, etc.) as if it came from the Google Pixel's camera. Moreover, the forgery (excluding my intentional artifacts) is indistinguishable from a real photo. C2PA's metadata provides no reliable assurance of provenance or authenticity.

The Vulnerability

I'm going to be intentionally vague here because I don't want to enable bad actors. However, the vulnerability isn't very deep and anyone who can get past the first step is almost certainly able to exploit it.

When I asked retr0id how he did it, he sent me back a wonderful picture that explains the process:


The C2PA signing keys are in a subsystem called 'StrongBox'. This is a secure storage area for handling the keys. The keys go in and never come out. You need a special program in the Trusted Execution Environment (TEE) to access the keys. This special program sends data to be signed by the keys and receives the signature.

The exploit:

Step 1: Get root on the device.
This is the hardest part. The Android operating system is intentionally locked down, so it's hard to get root access.

A common attack for Android devices replaces the bootloader. However, replacing the bootloader requires a factory reset, so you cannot access any secrets or protected data that existed prior to unlocking. To implement the exploit, retr0id needed root access without a reset.

As a hardware specialist, retr0id used a well-known chip-based approach to get a root shell. His implementation was hardware-specific, but the underlying methodology has been around for at least a decade. Moreover, preventing this attack vector requires completely redesigning the hardware architecture.

However, we are not limited to a hardware exploit. During the 90-day responsible disclosure waiting period, two other software-only exploits came out that also granted root access. (Exploit #1 and Exploit #2.) It doesn't matter that these software exploits have been patched; a malicious attacker won't patch their system and can gain root access on their own device. (As far as I can tell, you can still take signed photos, even if the device hasn't been patched recently.)

Regardless of your method, you just need to get root on the device.

Step 2: Sign your data
Find the program that signs the C2PA metadata using the protected keys. Use the program to sign anything. This is a Confused Deputy attack. When using Android's secured environment, only the TEE program can submit data to be signed, but the root user can provide any data to the signing program. Fixing this part of the problem requires redesigning the entire Android security model. In other words, there is no easy patch.

If you have root on the Pixel device (and you didn't change the bootloader), then you can sign any file as if it came from the Pixel camera. The signature will be legitimately signed by Google.

As an aside: For most exploits, saying "start with root" means that additional exploits add nothing. If you have root, then you already control everything. I.e., creating more backdoors is trivial if you can already alter every file. However, with Google and C2PA, we're not using root to stay on the device; we're using it to create authoritative files. Those files will leave the device as the forgeries are disseminated. With this attack vector, gaining root is just the beginning.

Reporting Timeline

I currently have over 40 blog entries about C2PA problems, and most of them disclose distinct vulnerabilities. While the public didn't know most of these problems until I made them public, none of the vulnerabilities have been new to C2PA members.

For this Pixel vulnerability, we recorded the reporting history:
  1. We reported it, via email and verbally, to both Google and C2PA representatives. The reporting included details and the demonstration picture. Following best practices for responsible disclosure, we gave them 90 days to respond. (Today, Aug 25, is 90 days from the initial vendor reporting, and about 9 months since the theoretical vulnerability was disclosed.)

    • We reported it to Google because the exploit is explicitly demonstrated against Google's flagship product, the Pixel series of Android devices.

    • We reported it to C2PA because the Pixel 10 was the first "Level 2" conforming product. Assurance Level 2 means that it must protect the signing keys. However, while the keys are protected from extraction by the Android StrongBox, this exploit shows that the keys can still be used to sign anything. In effect, the keys are unprotected. So either Google is not Level 2 conforming (false advertising), or they are Level 2 on paper but not in the implementation (deceptive practices), or Level 2 is grossly insufficient for providing any kind of assurance (misleading). In any case, this is definitely a C2PA conformance program problem.

  2. I made it clear that I planned to blog about this problem. But I also offered to work with them on the release cycle. For example, if they were about to provide a patch, then I would be willing to delay the blog and coordinate a release. Both Google and C2PA repeatedly acknowledged my offer during the 90-day period. However, I received no feedback from either organization.

  3. Google has a bounty program that pays researchers for finding vulnerabilities. I never signed up because Google requires agreeing to legal terms. (Even if I conceptually agree to the reasons behind their terms, I cannot sign anything that could be construed as a legal agreement. I just want to report a bug.) However, retr0id doesn't have those same limitations. Since he implemented it, we (PASAWG, myself, and Google) asked him to submit it through Google's Vulnerability Reward Program (VRP). He did.

  4. Google's VRP almost immediately sent retr0id two emails. The first said that the vulnerability was out of scope. The second said to ignore the first email and that it was in scope. They did end up logging it as a received report.

  5. Fast forward two months. Retr0id received an email from Google's VRP. (I am including it here with his permission.)
    jo...@google.com #9 Jul 14, 2026 12:36AM

    Status: Won't Fix (Infeasible).

    Hello,

    The Android Security Team has conducted an initial severity assessment on this report. Based on our published severity assessment matrix (1) it was rated as not being a security vulnerability that would meet the severity bar for inclusion in an Android security bulletin. If you have additional information that you believe we should use to reassess this report, please let us know.

    Please note that notwithstanding our severity rating and the closure of this external bug, we may nonetheless pass this issue on to the feature team for remediation. Therefore, please know that we appreciate this submission and any future contributions.

    The Resolution Notes label has been set to NSBC (Not Security Bulletin Class) to reflect this assessment.

    Thank you,
    Android Security Team.
    (1) Severity Matrix: https://source.android.com/security/overview/updates-resources#severity

    How did we do? Please fill out a short anonymous survey.
    They closed it out as a "Won't Fix (Infeasible)". Google defines "Won't Fix (Infeasible)" as "The changes that are needed to address the issue are not reasonably possible."

    More importantly, Google labeled it as "NSBC (Not Security Bulletin Class)". This code means that it either isn't a security vulnerability or isn't considered severe. In effect, Google explicitly said that a vulnerability in Google's flagship Pixel product line, which permits anyone to sign anything as if it legitimately came from the camera, is not a significant security vulnerability. I disagree with Google: verifiable history (provenance), reliable source attribution, and secure key management are explicitly security concerns. (See NIST SP 800-193 Platform Firmware Resiliency Guidelines, NIST SP 800-57 Recommendation for Key Management, and NIST SP 800-53 Rev. 5 Security and Privacy Controls for Information Systems and Organizations.) This demonstrates a fundamental disconnect between how Google views "OS platform boundaries" and "content provenance integrity".
It took a while, but retr0id did receive payment for reporting this bug to Google. VRP bounties are only for security issues. By paying the bounty, Google implicitly confirms that this bug is a security problem, even though it was classified as NSBC and kept out of the security bulletin. The NSBC classification also means no CVE was assigned, which keeps the issue out of regulatory tracking, enterprise compliance audits, and the National Vulnerability Database (NVD).

We have done our due diligence for reporting this problem. Google has decided to downplay the vulnerability, claiming that it isn't a noteworthy security issue. In contrast, C2PA did not respond at all.

Revoking Certificates

Within days of demonstrating the bug and sharing the sample image, Google revoked the X.509 signing certificate used for the glitter-milk picture. That sounds like responsible incident response on the surface, but in practice, it reveals a fundamental flaw in how Content Credentials interact with public key infrastructure (PKI). Keep in mind, they quickly revoked the certificate (a security response), despite Google's formal response weeks later saying that it was not significant enough for a security bulletin.

There are two major problems with relying on revocation to fix forged media:
  1. Validators Don't Check Revocation
    The current C2PA specification does not require validators to perform revocation checks. As of this writing, I am unaware of any conforming validator products that check whether a manifest's certificate has been revoked. So even though Google revoked the certificate for the glitter-milk photo, most C2PA validation tools will still happily report the image as authentic.

  2. The Privacy Paradox: Unique Signing Certificates
    To prevent third parties from tracking users across photos, Google designed their C2PA implementation to issue an ephemeral, unique signing certificate for every single photo.

    The trust chain looks like this:

    • Root CA: Google's root certificate sits on the C2PA-managed trust list.

    • Intermediate Certificate: Google's root issues an intermediate certificate. As far as I can tell, every Pixel device uses the same set of intermediate certificates.

    • Leaf Certificate: The intermediate cert issues a brand-new, single-use leaf certificate that is used to sign an individual image capture.

    Because every picture gets its own unique signing certificate, revoking the glitter-milk certificate only invalidated that one specific photo. This does not prevent retr0id (or anyone else with this exploit) from generating millions of additional forged images on that exact same compromised Pixel.
This signing approach, with unique signatures per picture, introduces serious problems:
  • Ineffective Revocation: Google can only revoke certificates for forgeries that are actively discovered and reported to them. Unreported forgeries remain 100% valid.

  • Denial of Service: An attacker running an automated batch script could sign millions of synthetic images. Reporting all of these intentional forgeries would likely swamp Google's certificate revocation infrastructure.

    (At the technical level: this is an attack against the ingest pipeline and OCSP signer; C2PA does not support CRLs for revocation. Google currently lacks a portal or documented process for users to submit individual forged photos for revocation. If Google were to build a portal without rate-limiting, it risks becoming a bandwidth/DoS problem on its own. If they add CAPTCHA or other throttling to protect the ingest pipeline, then known forgeries may not be submitted in a reasonable time, and humans could become discouraged. Moreover, bulk OCSP revocation could plausibly strain cryptographic signing throughput.)

  • Verification Problem: When a user submits a picture to Google for revocation, how does Google know that it really is a forgery? With the glitter-milk example, we explicitly showed them how it was made. However, a malicious person could submit legitimate photos and claim they are forgeries. Google needs some way to identify whether a signed picture from a Pixel device is actually from the camera. This remains a hard problem. Depending on their implementation, Google could reject real forgery reports if the verification process is too strict or revoke legitimate photos if it's too lenient.

    • Without C2PA: Individual analysts must evaluate the media using whatever tools they have available.

    • With Google's C2PA signature: When someone submits a picture for revocation, the onus is on Google to provide the verification. (I suspect that nobody asked Google's legal department about whether the company wanted to be put in the position of validating all pictures.) Keep in mind: the entire premise of C2PA is that Google cannot otherwise verify whether a picture is authentic, so asking Google to verify whether a revocation request's media is real just restates the same unsolved problem.

  • Painted Into a Corner: With the current architecture, Google cannot revoke the device's intermediate certificate without instantly invalidating every authentic, legitimate Pixel photo ever taken. Google's revocation approach effectively becomes all or nothing. In either case, they cannot stop one individual from creating signed forgeries.
Since the core exploit impacts Android's StrongBox and TEE architecture, revoking individual certificates does not resolve this problem. Revoking a certificate, only to have an attacker compromise the replacement certificate in the exact same way, is not an effective security solution.

By choosing privacy through single-use certificates, and without addressing local key abuse, Google created a system where revoking a compromised image is nothing more than security theater.

Real-World Problems

It is easy to treat "Glitter Milk" as an amusing and harmless proof-of-concept. But the implications of a broken content provenance model are anything but funny.


Image provenance is critical for determining whether the media represents something real or fake. Whether it's a political proof-of-life, images of war or strife, or even something less extreme, like an insurance claim, there are direct consequences from forged provenance.
  • This Mitch McConnell picture has no camera-original metadata, but does include an XMP record showing that it was altered with an Adobe application hours before being released to the public. If someone replaced the metadata with fake Google Pixel information, and then had it signed by a real Google Pixel device, would it be more trustworthy?

  • The second picture is from an artist who creates AI-generated pictures of life in Russia. If we removed the Facebook re-encoding artifacts and had it signed by a Google Pixel device, would you think it was authentic?

  • The third picture is part of a product defect claim. Unlike the first two, this one isn't hypothetical: it carries a cryptographically-valid C2PA signature that genuinely came from a Google Pixel device. But now that we've shown that same "came from a camera" signature can be applied to non-camera media, should you trust it?
It's hard enough to debunk one false picture. However, with a little effort, a malicious actor could add in fake camera metadata and have it authoritatively signed by a trusted device. That significantly increases the effort to debunk a picture since it has the backing of Google's cryptographic signature as an unbreakable "official truth". (Remember kids: Strong cryptography over untrusted data does not make the data more trustworthy.)

Untrusted By Design

This glitter-milk picture demonstrates how any image can be assigned false provenance and signed with a cryptographically valid Google signature. Moreover, this problem also works in reverse: genuine photos with signatures can be easily dismissed as "just another C2PA forgery." Regardless of the ground truth, an analyst cannot determine if a picture is real or fake based on Google's implementation of C2PA; the signature effectively means nothing.

Google's initial announcement made some extraordinary claims that have failed to stand up to scrutiny:
  • Claim: "Pixel and Android are bringing a new level of trust to your images with C2PA Content Credentials".

    Fact: The devices can be used to sign any file, real or fake, with legitimate C2PA-signed claims identifying that the media came from the camera. This does not introduce a new level of trust; it enables a new way to commit fraud and disinformation.

  • Claim: "The Pixel 10 lineup is the first to have Content Credentials built in across every photo created by Pixel Camera."

    Fact: This is false. Nikon shipped C2PA Content Credentials in Z6 III firmware in late August 2025, weeks before Google's announcement. Days later, researcher Adam Horshack showed the camera could be used to sign arbitrary images, forcing Nikon to indefinitely suspend the service and revoke every certificate it had issued. Google isn't first; it's just the first to repeat Nikon's mistake with better marketing.

  • Claim: "Pixel Camera app achieved Assurance Level 2 ... only possible on the Android platform."

    Fact: While they acquired Assurance Level 2 on paper, it appears to be absent from the implementation. Moreover, they stated that protecting the keys from signing arbitrary images is not possible ("Won't Fix (Infeasible)"), so whatever Assurance Level 2 is meant to guarantee, it clearly doesn't hold up in practice on the Android platform.

  • Claim: "A private-by-design approach to C2PA certificate management, where no image or group of images can be related to one another or the person who created them."

    Fact: While true, this prevents them from revoking future pictures from a known-compromised device. A device that has been rooted and is generating signed forgeries can continue to operate unabated.

  • Claim: "Pixel 10 phones support on-device trusted time-stamps, which ensures images captured with your native camera app can be trusted after the certificate expires, even if they were captured when your device was offline."

    Fact: While it is true that the Pixel 10 has a built-in trusted time-stamp service, that does not mean that it is only applied to "images captured with your native camera app". This claim is misleading.
In effect, Google's C2PA-enabled devices provide no reliable protections or 'truth' about the media -- and Google knows it.

Flawed Foundations

The problems detailed in this blog are not limited to the Google Pixel or its C2PA Assurance Level 2 rating. These problems are fundamental and impact other C2PA implementations. For example, Evergreen Labs has a C2PA Assurance Level 2 application called "GreenCheckmark" (screenshot) that can be used to sign any image or video as if it came from the device. However:
  • C2PA's Conformance Program only checks the paperwork for compliance, not the implementation. In this case, the Conformance Program states that the app has Level 2 assurance.

  • According to Evergreen Labs, the app received approval for Level 2, but only implemented Level 1. There is no C2PA-provided or user-identifiable information that identifies this discrepancy.

  • Even if the app was fully implemented, Assurance Level 2 requires using Android's StrongBox/TEE, and Google already stated that it knows the environment does not provide adequate protections ("Won't Fix (Infeasible)").
GreenCheckmark isn't the point of failure here; failures are inherited from Google and C2PA.


If you still believe that C2PA works, then I have news for you: Scientists have created multi-colored sheep for dye-free yarn. According to Adobe Inspect (a conforming validator) and CAI Verify, this is legitimate "captured media" from a camera, signed by GreenCheckmark, and it is a Level 2 conformant application (screenshot). Similarly, YouTube's description reports that this video clip from the CGI movie "Big Buck Bunny" is signed by Evergreen Labs and "Captured with a camera" (screenshot).

The same class of vulnerability exists for Android and iOS (except that iOS is harder to root). Moreover, retr0id has additional working demonstrations from many other C2PA-enabled apps, including Proofmode (a Level 1 conformant app; see forgeries at Adobe Inspect and CAI Verify). To date, no C2PA implementations are immune to signing forged media.

We live in an era of deep skepticism, where public trust in visual media is at an all-time low. Proponents of C2PA argue that cryptographic signing solves this problem: if an official photo carries a valid, hardware-backed C2PA signature, the public can trust it. But the truth is that the C2PA signature carries no weight for providing any type of reliable authentication, validation, or provenance. Instead, it turns every device into a powerful tool for laundering disinformation as fact, which is worse than doing nothing.

Special thanks to retr0id, Shawn, and PASAWG for their assistance. All vendors whose products are shown signing forgeries in this blog were notified of the problem. Claude and Gemini were used to help write portions of the code for these demonstrations. (At one point, we had to pause for a few hours after running out of free tokens.) Getting root is hard. Writing the code to implement the vulnerability is a very low bar and can be done with an AI assistant.

PTSD and Sock Roundup

As part of my People Tech Support Duties (PTSD), I have come across all sorts of users. Usually they have at least a little computer literacy. For example, if I tell them over the phone to turn the computer off or press the power button, they usually don't need to be told where the button is located. (I say "usually", because there has been the rare case where I had to tell the person which box under the desk was the computer and where the power button was located.)

Ironically, I find the people who have some tech knowledge to be harder to help. They eagerly click things, open new windows, and wander off on tangents instead of following directions. (One of my repeated PTSD users often fights me for control of the mouse when I'm logged in and remotely controlling the desktop. When helping that user, I've learned to not use any remote desktop software. That kind of "Type A+" personality must remain in control.)

Less Than Technical

I recently came across a user who was far less computer literate and had difficulty with things like navigating with the mouse.

In her defense, I will point out that her husband always used the computer, so she didn't have to. And her prior computer experience was from the 1960s, where pressing the wrong button would require a technician two hours away to come on site and fix the computer. You absolutely didn't want to make a mistake.

Given this background, the user was very timid about moving the mouse, while trying to be overly precise when clicking. The entire concept of drag-and-drop was difficult. Basic instructions, like "Grab the window by the address bar and drag it to the left, so the entire window is on the screen" required defining 'window', 'address bar', 'drag', and explaining that you don't have to be very precise: clicking and holding the mouse button down anywhere on the address bar would work.

This wasn't the first user I've encountered who really didn't understand basic mouse concepts. Things like moving the mouse, clicking on something, and dragging it to a location are not always intuitive. These actions seem instinctive to experienced users, but they're actually built on several learned concepts: the desktop metaphor, the idea that the mouse controls an on-screen pointer rather than the computer itself, and enough hand-eye coordination to connect physical movement with what appears on the display.

When moving the mouse, there are also the occasional "avoidance" issues, like "do not mouse over that object, or it will automatically open a huge popup, preventing you from navigating to where you want to go." Even experienced users sometimes need to "steer around" poor interface designs.


(On the Vertiv/Liebert UPS web site, I accidentally moused over their "Products & Services" menu. This popped up a massive menu that covers the entire page of products and requires scrolling to get below the menu. If your mouse is at the top of the screen, then do not move it straight down to the product listing. Instead, navigate the mouse around the menu so you can get to the product listing.)

Socks Don't Suck

I decided to approach this problem a little differently than I normally would. I've spent the last few evenings creating a JavaScript game that requires moving the mouse, dragging objects, and navigating around obstacles.

Using games as a teaching tool goes back centuries. Scientific studies have repeatedly shown that people retained the material better when it is presented in a game. The game doesn't even need to be very good; Richard Mayer is a pioneer in computer game-based learning, who found that the mechanics are more important than the storyline or visual design. (The Mayer method: immediate feedback, scaffolded difficulty, and spatial integration.) Other researchers found that high quality graphics do not enhance learning and "seductive details" can hinder learning. In other words, a polished, commercial-quality game isn't necessary. A simple activity that repeatedly exercises the right skills is often just as effective.

I wanted a simple game that teaches four basic mouse skills:
  1. Moving to a target,
  2. Clicking accurately enough, but not requiring extreme precision,
  3. Dragging objects, and
  4. Navigation around hazards.
I also wanted it to have specific goals and tiered difficulty levels. I ended up with a really stupid game: "Sock Roundup".
  • The goal: You have a messy bedroom with socks strewn around the floor. Use the mouse to drag each sock to the washing machine. This requires identifying small items on the screen, clicking on them, and dragging them to the washing machine.

  • Avoidances: Dogs and cats are in the room and chasing your mouse. If they touch it, then they bite or scratch the pointer, and you lose the round. Each level adds more socks, dogs, and cats.

  • Bonuses: If you make it to level 5, then there's a red button. Clicking it will either drop dog biscuits around the room (diverting the dogs away from your mouse), or a red laser pointer that holds the interest of the cats.

  • Safe zones: Sometimes you just need to rest for a moment. There is furniture in the room. Hover the mouse over the furniture and the animals can't reach you. At least, for a short rest before they figure out how to jump onto the bed, desk, etc. (You can also drag the furniture to make barricades.)
Like I said, a really stupid game. The game is intentionally unwinnable. (I usually make it to level 7 or 8. Other users might only make it a few levels in before realizing that they have all of the mechanics down.) However, for someone new to using the mouse, it doesn't take much practice to get up to level 5 in a few minutes. More importantly, they realize that moving the mouse into a bad place (like touching a dog or cat) isn't actually that bad. The world doesn't end just because the pointer touches the wrong thing.

For anyone interested, here is the game. It is designed for a desktop system with a mouse, not a laptop with a trackpad or tablet with a touch screen. https://hackerfactor.com/games/sock_roundup.html


For full disclosure: The entire game is in JavaScript. The initial version was created using Claude based on a detailed description that I provided. I then edited to code and made some modifications to the gameplay.

If this game helps even one new computer user become comfortable with a mouse, then the project was worth an evening or two of JavaScript. If anyone has thoughts on how to make this game more engaging or entertaining, or have other suggestions to help inexperienced computer users learn how to use the mouse, then I'm open to suggestions!

On a Power Trip

My laptop is one of my most important tools. While my servers and office systems have all of my configured software and documents, I can't take them with me on customer trips, or even to the living room for some late-night catching up while watching TV. The laptop is basically my portable window into my office.

I don't need a powerful laptop. I'm not a gamer and I rarely develop software directly on it. The biggest applications I use are Impress for presentations and VLC for watching movies on airplanes. Most of the time, I'm simply accessing websites, running diagnostics, or remotely logging into my office. (If someone were to steal my laptop, they won't get much. They can't access the office without my passwords and biometrics. If it ever were stolen, I can immediately lock down all network access to my office with a single unpublished URL.)

More Laptop

Last year, I wrote about my laptop. Back then, the Windows 10 operating system was hitting end-of-life and needed to be replaced. The final straw was the "Patch Tuesday" where the laptop sat at "Restarting" forever. Since the laptop is only used for remote access, there was nothing that needed keeping. I ended up reinstalling it with Ubuntu Linux.

This OS switch came with a few pleasant surprises:
  • The laptop was significantly faster. (Windows is a resource hog!)

  • The hard drive had a lot more room. (Linux is smaller than Windows.)

  • Restoring the network from suspend worked perfectly. This had been a problem under Windows.

  • The original battery lasted 8-9 hours under Windows, but had aged to lasting 4-6 hours from a full charge. With Linux, I was getting 10-12 hours of use from the same hardware.

  • I had some touchpad issues under Windows. Switching to Linux made those issues mostly go away.

Touchpad

While the touchpad issues were mostly resolved, they weren't completely gone. The mouse cursor would move correctly, but sometimes the mouse buttons would become non-responsive or require multiple presses before they worked. A reboot would fix the problem temporarily, so I didn't think it was the hardware wearing out.

Under Windows, I found a few other people with the same problem, but "reboot Windows" was the cure for everything. With Linux, there are enough tools for a real diagnosis and easy fix.

The laptop communicates with the touchpad using a two-wire protocol called I2C. When the laptop suspends and restores, the I2C drivers can get into an inconsistent state, causing the buttons to fail. The solution? I created a system restore script that restarts the I2C drivers when it wakes up. With Ubuntu, create the executable file "/lib/systemd/system-sleep/restart-touchpad":
#!/bin/sh
case "$1" in
post)
# Unload the ACPI and I2C drivers
rmmod i2c_hid_acpi
rmmod i2c_hid

# Reload them for a clean reset
modprobe i2c_hid
modprobe i2c_hid_acpi
;;
esac
That's it. You don't need to restart anything. Now the touchpad works properly all of the time.

Old Hardware

I usually keep hardware until it stops working. For example, I had an old Pentium computer with a 120MB hard drive that I used as my mail server for over 20 years. OS patches? Ha! It was still running Redhat 5.1! (Old hacker security tip: nobody looks for 20-year-old vulnerabilities, and newer vulnerabilities didn't work on old systems.) In my opinion, as long as the system is stable, why risk replacing it? The only reason I retired that old mail server was that everyone was moving to TLS for secure email transfers and some of the OpenSSL dependencies were too complicated to port to the old system. The 30+ year old hardware itself still worked fine.

The same goes with laptops. For someone who has been in the computer field for over 40 years, I've only ever owned four laptops. My first one was an Apple. (Never again.) It lost OS support after 2 years. However, I didn't move off of the laptop until the browser providers (Chrome and Firefox) stopped supporting it. I needed a modern browser, so that meant a modern laptop.

My Asus EeePC was my favorite because it was tiny and lightweight. However, after a decade most OS's dropped support for the Atom processor, so I had to update again.

These days, I'm using a Dell XPS that I purchased in 2017. The hardware is designed to last, the only issue was the touchpad -- and that's fixed now. That just left the battery.

Battery

No laptop batteries last forever. With lithium-ion, they start with a long lifespan and then slowly degrade over time. However "slowly" isn't linear. After a few years, you'll start seeing the battery runtime decline, and as time passes it will decline very rapidly. When it's completely dead, it might hold a charge for five minutes.

Lithium-ion batteries typically last seven to ten years, although heavy cycling, deep discharges, and heat can shorten that lifespan. My laptop was from 2017, putting it well into the "old battery" range. When it was new, it could hold a charge for 8-10 hours while running Windows. After eight years, Windows was lasting 4-6 hours before I switched to Linux. Linux lightened the power requirements, bringing it back to a 10 hour battery. That doesn't mean that the battery is fresh; it just means that the new OS was more power efficient.

Over the last year, it had entered the fast decline that is typical for lithium batteries. Last month, a full charge was lasting 2.5 - 3.5 hours (still under Linux). If I can't last an entire airplane flight, then that's effectively a dead battery. While I'm thrilled to have had nearly 9.5 years out of this battery, I had to make a choice:
  • (A) Get a new laptop. These days, that would cost me $900 - $1500.

  • (B) Get a new battery. I saw prices that varied from $25 to $100.
My thought: if I could get a new battery and maybe another 7 years of life out of this laptop, then it was definitely worth it. (Also, I wouldn't have to lose all of the stickers I had plastered on the laptop.) In the worst case, either a new battery wouldn't help or I'd damage the laptop while swapping batteries. But for under $100? I was willing to experiment.

The huge price range really bothered me. As far as I can tell, all of the sub-$75 batteries were from pop-up providers. Vendors who were here today and gone tomorrow. Each had reviews that ranged from "5 stars: It works!" to "1 star" with long paragraphs about all of the problems and non-responsive vendors. Even though the batteries were all marketed as "new", they were probably "newly rebuilt" and not really "new".

Dell no longer makes this battery, but a few companies still have good reputations for selling genuinely new batteries rather than rebuilt packs. I had never purchased from iFixIt before. And now that I have, I highly recommend them. (I am not a paid spokesperson, I'm just a very happy customer. As an aside, I often blog about problems with vendors. This time, I only have positive things to say.)

The battery was affordable (under $100 and with free shipping). It arrived on time. It arrived well-packaged and undamaged. (This is always a concern with lithium batteries.) It said that the package included a small toolbox, but that wasn't part of my decision process. Now that I've used it, this is one of the nicest toolboxes I've ever had for repairing equipment. It includes:
  • A metal shim, for prying open lids without cracking the tabs.

  • A bunch of plastic shims, so the lid doesn't close while sliding the metal shim around the seams.

  • Every screw driver bit size you might need.

  • High quality tweezers.

  • A plastic tool that is great for helping peel up tape.

  • A suction cup, in case you're repairing a cellphone screen.

  • Even the toolbox lid is well-designed, with grids for holding screws. I populated it with the screws I pulled out (each type and location went in a different holder) and put the screwdriver bit next to it as I went.
I found out the hard way that it is designed for use with one hand! With my laptop, I had removed the screws and was using the metal shim to pry off the back. I realized that I needed a plastic shim to prevent the lid from snapping back on while I worked. With one hand, I held the metal shim in the lid. With the other hand, I was able to push down on one side of the plastic shim and have it pop up so I could grab it. I didn't realize that there were multiple plastic shims until they popped up and exploded all over the desk. This was a very pleasant surprise.

Here's the toolbox:

(Be careful pushing on the blue plastic triangular shims in the middle. There are a bunch of them and they will all suddenly pop out!)

And here's the laptop mid-replacement:

(The old battery is off the top of the photo. The new battery is the black rectangle in the top center. It goes over the touchpad, which is the green board at the bottom of the screen.)

A few years ago, I tried to replace the battery in my Samsung tablet. I had a hodgepodge collection of tools and ended up destroying the tablet. I was worried about doing the same thing to the laptop. But with the right tools, going slowly, and taking photos, I managed to replace the battery without any problems in under 30 minutes. (Now that I know what I'm doing, I could probably do it in 10 minutes without feeling rushed.) It was truly painless.

Calibration

After swapping the battery, the laptop wouldn't turn on. That's fine -- the new battery shipped without a charge. After 10 minutes of charging, I could turn the laptop on. (Good! I didn't break anything.)

The next step is to calibrate the battery. This isn't for the battery's health; it calibrates the software that reports how much power remains.
  • Typical batteries: With regular lead-acid and alkaline batteries, the output voltage is pretty linear. You can measure the voltage to determine the battery's remaining capacity.

  • Lithium-ion batteries: Lithium-ion batteries have a long, flat discharge rate. You can't just look at the voltage and determine how much battery time is left. During the flat discharge rate, the micro-voltage differences can be too small for the hardware to detect; there may be no measurable difference between 30% and 70% capacity. To estimate the remaining time, the OS uses a combination of measured voltage and a timer for how long it took to drain. For the calibration, you put it through a full charging cycle, full discharge, and full charge again. This helps the software guestimate the capacity during the flat discharge rate.
My laptop's battery is rated at 7.6V and 60Wh. With Windows, I was getting nearly 10 hours with the original battery. But now I'm on Linux, which consumes much less power. I had no idea how long this new battery would last.

To calibrate with Linux, you should remove the power history. This forces it to learn based on the new battery.
sudo systemctl stop upower
sudo rm /var/lib/upower/history-*
sudo systemctl start upower
Next, fully charge the battery. Let it charge for at least two hours beyond "fully charged".

The full discharge step is kind of a challenge, since the OS wants to be as efficient as possible. Turn off power-saving mode, turn off the screen saver, turn off suspend, etc. I gave it something to do: play the movie "The Bourne Identity" over and over until the battery was fully drained. (The computer will warn about low voltage, and then shutdown automatically. That's the full discharge.) With this new battery? I expected it to last for 12 or 14 hours. Instead, it ran for 30 hours! (I suspect that it was using a hardware-based video decoder which is very power-efficient, and letting the CPU itself effectively rest and consume flea power.)

The final full charge cycle probably only needed a few hours, but I let it go overnight.

With the new battery installed and calibrated, Linux reports "15 hours remaining". After five hours of use, I still have "14 hours remaining", and if I start compiling code, it drops to "10 hours remaining." I'm not too worried about the calibration's accuracy since it may take the OS time to learn. I might not be able to tell the time remaining with extreme accuracy, but I'm sure it will last an entire plane flight on travel days.

Right to Repair

There's an entire movement centered around the right to repair equipment. Being able to change a battery in a working device is one of those basic tenets. My Samsung tablet appeared designed to self-destruct when opened. My Dell laptop was built to be repaired, and the tools from iFixIt simplified this process. I'm sure my laptop is good for at least another seven years.

In my home town of Fort Collins, they are building a new library. This one will include an "innovation maker-space". They recently had an open house to discuss wants and needs with the community. People wanted everything from a 3D printer and laser cutter to sewing machines, button makers, and classes on gardening. One of the things that was repeatedly mentioned by attendees was a repair station. Whether it's a team of volunteers, one-time hands-on classes, or something in between, people have a strong desire to repair electronics before buying a replacement.

My successful weekend project is exactly why community maker-spaces are so vital. When manufacturers design hardware to be opened, and companies like iFixIt provide the exact toolkits to do it safely, fixing our own tech transitions from a stressful gamble to a rewarding afternoon project. We don't need to throw away perfectly good silicon just because a battery gets old. Keeping this laptop out of a landfill isn't just a win for my wallet, it's a small victory for a more sustainable, fix-it-first mindset.

The combination of a lightweight Linux OS, a fresh battery, and the right tools completely resurrected a piece of hardware that most people would have recycled years ago. It may not be the latest or greatest, but it's perfect for the next time I leave the office.

Meta's Un-Stable Signature

I'm wrapping up my investigation into invisible watermark algorithms and I am extremely disappointed. Not only do none of the modern AI-based algorithms work as they claim, it turns out that they are all making the same fundamental mistake.

I previously evaluated Google's SynthID and Adobe's TrustMark algorithms. Both of them claim to have incredibly accurate results.
  • According to Google's peer-reviewed and published paper, they claim to have a true positive rate (TPR) above 99.97% -- meaning that they will miss their own watermarks no more than 3 in 10,000 times. However, my own empirical testing found that is it much closer to 1 in 20. Moreover, SynthID is proprietary and only accessible through Google's "Gemini" AI system. Gemini has been observed hallucinating results and providing contradictory conclusions depending on how the question is phrased.

  • According to Adobe's Content Authenticity Initiative, their TrustMark "can exceed 96% bit accuracy at around 42-45dB PSNR quality under severe noise degradations". However, that statistic focuses on resilience and not accuracy. In my empirical tests, I found that TrustMark has a 10%-20% false positive rate, effectively making it useless. (If you see a TrustMark signature, then it is very likely random noise and not an actual signature.)
This time, I evaluated Meta's "Stable Signature" algorithm. (Their paper and code are in GitHub.) This system encodes a 48-bit sequence into the picture's visual content. The idea is that you can encode a unique 48-bit sequence as your watermark. If your decoder finds the same 48-bit sequence, then it can identify your own watermark.

WARNING: This blog entry leans heavily into math and statistics to prove that Stable Signature, TrustMark, and SynthID are nowhere near as reliable as their developers claim.

The Basic Algorithm

Traditional (non-AI) invisible watermarks typically hide in subtle locations, such as the least significant bits, changes in brightness (e.g., Digimarc) or the frequency spectrum (DCT or FFT). There is always the risk that image encoding could corrupt the hidden data, so these algorithms typically rely on repetition over the image to help identify the true signal. In addition, they may include error correction code (extra bits in the data) to fix any minor data errors.

However, there is a problem with the traditional approaches: injecting hidden data in the image could create visible distortions. The modern approach uses an AI system to better hide the data with less added distortion.

As with SynthID and TrustMark, Stable Signature encodes binary data and uses an AI-model to decide where to hide it in the image. The AI is tuned to minimize visible distortions when embedding the data. Later, an AI-based decoder looks at the image and identifies the likely location where bits are stored, then it extracts the data.

There is always the case that the data may be mixed with noise. Different AI-based watermarking systems rely on different techniques for reducing the noise. For example:
  • Google's SynthID only stores a few bits of data (effectively a flag or version number). This allows them to use a lot of data as repetition and to increase the accuracy rate.

  • Adobe's TrustMark uses the Bose-Chaudhuri-Hocquenghem (BCH) algorithm. This acts as a combination of checksum and error correcting code that should reduce the number of errors.
Meta's Stable Signature uses a simple Hamming distance.


The Hamming distance measures the number of bits that need to be swapped in order to correct the code. In effect, it defines a set of stable states (e.g., 10110 and 11000) and places a ring around each state that represents the single bit changes. If you change enough bits, then you will reach a different stable state.

According to Meta's Stable Signature research paper, the 48-bits should be uniformly distributed and cites a "false positive rate below 10-6", or 1 in one million. This means you can choose a 48-bit sequence to use as your signature. Every picture will generate a 48-bit sequence, and the sequence can vary a little based on noise in the picture. However, if you find a code that is within a short Hamming distance of your code (e.g., within 6 bits difference), then you can determine that it is the same code with a high reliability.

At least, that's the theory.

Empirical Testing

I went into this experiment assuming that everything works like they claim. I want to be able to reliably identify invisible watermarks associated with Meta. What I don't know is what sequence they use, or whether they use multiple codes depending on whether it comes from Meta's AI system, Facebook, Instagram, WhatsApp, etc.

Fortunately, this is something I can test! I grabbed an uncurated sample of pictures from FotoForensics: the first 10,000 unique images uploaded last month (May 2026). If the bit sequences are uniformly distributed with a "1 in 1 million" collision rate, then I should see a huge number of unique bit sequences and a few small clusters around pictures from Meta (Meta AI, Facebook, Instagram, etc.). Those clusters will represent the invisible watermarks used by Meta.

The results from my empirical test were definitely not what I expected. I found:
  • No clusters associated with any Meta images. This suggests that Meta does not use their own Stable Signature watermarking software found on GitHub.

  • With a random distribution, there should be no clusters. However, I had 25 different pictures that had the exact same bit sequence: 110110100111111011101001111000100111011000011101. With a 1 in a million collision rate, this should not happen! These pictures came from very different sources. Here's four of the 25 pictures (ranging from planets to light bulbs to text with a transparent (black) background):


    All of these pictures have dark/black backgrounds and something bright in the middle. This suggests that Stable Signature operates more like a perceptual hash than an invisible watermark.

  • Stable Signature uses a Hamming distance to identify a cluster. If I assume the 25 pictures are the center (centroid) of the cluster and use a 6-bit Hamming distance, then there are 356 pictures that are similar. And if I assume that the 25 pictures are not the center but part of a cluster, then a Hamming distance of 6 has a cluster of 450 pictures centered 3 bits away, at 110110000111111011101011111000100111001000011101. This cluster represents 4.5% of the uncurated image data set! Here are a few samples from this larger cluster:


    (I'm explicitly not sharing pictures with personal information, like invoices, recognizable people, and GPS information.)
It's not just one random cluster that is massively large (450 pictures out of 10,000). There's a cluster of 184 pictures at 110101001011001011001011111000100111001000011101, 58 pictures at 110100000011111010001001111000100111011000011101, etc. I found over 60 clusters with more than 10 pictures each at a Hamming distance of 6. That should not happen with a "1 in 1 million" collision rate.

Independent Analysis

I went back to Meta's research paper to see if I could find the discrepancy. And there it was, in section 3.1: They tested their system against the hypothesis that the 48-bits are each independent and uniformly distributed. The problem is, they use one neural network to generate the bits. That explicitly means that the bits are dependent, not independent.

Their paper assumes a binomial distribution. That is, given an arbitrary image, the 48-bits represent a random coin flip. The math becomes:
P(X โ‰ค T)=โˆ‘Tk=0(48k)(0.5)k(0.5)48โˆ’k

This computes the probability of 48 random bits being within a Hamming distance (T). The probabilities table becomes:

Hamming Distance Threshold (T)Bit Error Rate (BER)Probability of a Random Image Matching by Chance
14 bits or fewerโ‰ค 29.17%1 in 362.63
13 bits or fewerโ‰ค 27.08%1 in 957.81
12 bits or fewerโ‰ค 25.00%1 in 2,788.35
11 bits or fewerโ‰ค 22.92%1 in 8,999.08
10 bits or fewerโ‰ค 20.83%1 in 32,416.80
9 bits or fewerโ‰ค 18.75%1 in 131,390.28
8 bits or fewerโ‰ค 16.67%1 in 605,094.89
7 bits or fewerโ‰ค 14.58%1 in 3.20 Million
6 bits or fewerโ‰ค 12.50%1 in 19.83 Million
5 bits or fewerโ‰ค 10.42%1 in 146.19 Million
4 bits or fewerโ‰ค 8.33%1 in 1.32 Billion
3 bits or fewerโ‰ค 6.25%1 in 15.24 Billion
2 bits or fewerโ‰ค 4.17%1 in 239.15 Billion
1 bit or fewerโ‰ค 2.08%1 in 5.74 Trillion
0 bits (perfect match)= 0.00%1 in 281.47 Trillion

Meta's paper says that they use a Hamming distance of 7 bits (requiring 41 of 48 bits), which matches their claim of a "false positive rate below 10โˆ’6". However, I'm seeing problems at a Hamming distance of 6 (should be 1 in 20 million) and even collisions at 0 (1 in 281 trillion)!

The Core Problem

There is clearly a discrepancy between the theoretical probabilities and the empirical testing. When I looked back over Meta's research paper, I saw the problem:

According to Meta's paper, each of the 48-bits are independent. In a perfectly independent 48-bit hypercube, un-watermarked images should scatter uniformly across all 248 possible values. However, neural networks map a non-linear manifold (a multi-dimensional wavy surface) through this hypercube. This mathematical landscape is warped with its own peaks, ravines, and valleys. It has attractors that form clusters, and repulsers that form voids where stable values can never exist; this is a feature of a neural network. And most importantly, the output bits are explicitly not independent.


The left diagram illustrates an expected uniform distribution if all of the bits were independent. The right diagram are the types of theoretical clusters that form when the bits are dependent. There should be clusters around attractors and voids (areas with no dots) from the repelling regions.

Moving from theoretical to empirical, I graphed the data. The 48 bits can be represented as bytes. I took the first 24 bits and converted them into 8-bit red, green, and blue pixel colors. If the data is truly random, then the colored dots should be distributed across the RGB cube. However, if the bits are dependent, then there should be very clear clusters, structures, and voids. Here's the graph:


Yes, there are very clear structures that look like planes and lines. Within the planes are clusters, and outside the planes are very large voids -- areas where there are no dots at all. The data generated by Meta's Stable Signature implementation fails this basic test for independence.

The biggest cluster that I found represents a Zero Signal Bias (ZSB). When their neural network doesn't find a watermark, it moves the 48 bits toward a strong attractor, like a massive gravitational well. At 6 bits error, it should have a collision of around 1 in 20 Million. But in reality, my 10,000 pictures had a cluster of 450 images within 6 bits due to the ZSB. That's an error rate of around 1 in 22 with the ZSB alone. If we add in all of the other clusters that contain at least 10 pictures, then 2327 pictures are in various clusters; we're looking at an error rate around 1 in 4 -- and that's at a Hamming distance of 6, which is more conservative than their paper's Hamming distance of 7. (In AI terms, this is a representation collapse or structural bias that is typical for deep neural networks.)

(As an aside: Given their "1 in 1 million" claim, I could look for any clusters of 2 or more pictures. At clusters of 2 or larger, 5,237 of the 10,000 test images were in clusters, or 52%. If you show their algorithm 10,000 pictures, then there is a better-than 50% chance of a false positive match.)

Less Than Random

It's one thing for me to claim that there are visible clusters and to show pictures of clusters, but another to prove it mathematically. (Time to dust off my college textbooks from "Introduction to Statistics"...)

I fed Meta's code the first 10,000 images from May 2026. A few of the images were in unsupported formats (HEIC, WebP, and a few corrupted JPEG files), resulting in 9,847 viable pictures. I evaluated this data with elements from the NIST Statistical Test Suite (SP 800-22) for randomness, including a monobit test and Chi-Squared (ฯ‡2) test for independence.

The monobit test determines if the baseline frequency of adjacent bits seems independent.
  • Total Bits Processed: 9,847 pictures ร— 48 bits per signature = 472,656 bits
  • Observed Count of Ones ('1'): 266,419
  • Observed Count of Zeros ('0'): 206,237
  • Expected Count (E): 236,328 for each.
Running a simple standard Chi-Square Goodness-of-Fit test for this bit balance:
ฯ‡2=(266419 โˆ’ 236328)2236328+(206237 โˆ’ 236328)2236328= 3831.41 + 3831.41 = 7662.81
  • In mathemat-ese: with 1 degree of freedom, a ฯ‡2 statistic of 7,662.81 yields a p-value infinitely close to 0.0 (p ⋘ 10-100). (As an aside, most Chi-square tables usually evaluate the 1 degree of freedom up to around ฯ‡2=10. This ฯ‡2 value is so astronomically high that the probability p effectively becomes zero.)

  • In English: That's definitely not random or independent.
The watermark extraction is strongly biased toward producing 1s over 0s across global arbitrary images (roughly 56% ones to 44% zeros). This immediately violates the uniform distribution assumption.

The second test is the Chi-Square (ฯ‡2) Test for Serial Independence. If the bits were independent, the transition probability between adjacent bits would just be the product of their individual probabilities. This table shows the occurrence rate of the transition pairs across all of the observed 10,000 (well, 9,847) pictures:

Transition PairObserved Count (O)Expected Count under Independence (E)
0 to 0106,75090,051
0 to 195,296116,186
1 to 095,302116,186
1 to 1165,461149,976

ฯ‡2=โˆ‘(O โˆ’ E)2Eฯ‡2=16699290051+(โˆ’20890)2116186+(โˆ’20884)2116186+154852149976=3096.7 + 3756.2 + 3754.0 + 1599.0=12,205.9
  • In mathemat-ese: With 1 degree of freedom for the transition contingency table (accounting for fixed margins), a ฯ‡2 value of 12,205.9 gives a p-value of 0.0.

  • In English: Ain't no way this is random or independent.
And as if this wasn't conclusive enough, there are other tests we could apply:
  • Static Tail Patterns: Looking closely at the end of the 48-bit sequences, a massive cluster of strings end explicitly in ...111101 or ...00111101. Additionally, bit position 46 is nearly always "1" (228 zeros vs 9619 ones, or 97.7% of the time it is "1"), position 47 is "0" (8958 of 9847 images, or 90.97%), and position 48 is "1" (found with 9696 images, or 98.5%) across thousands of uncurated, real-world images.

  • Structural Clustering: Certain bit columns share an extraordinarily high Mutual Information score (I(X;Y)). For example, knowing the output of bit position 12 gives you better than an 80% accuracy in predicting bit position 28.
The assumption of a "uniform distribution over arbitrary pictures" relies on the idealistic premise that random natural image features project uniformly across the decision boundaries of a network. However, because the extraction network maps inputs to a constrained, highly continuous hyper-dimensional manifold, the network's latent layers natively enforce structural smoothness.

For the TL;DR crowd:
Meta's researchers made a fundamental mistake when computing their accuracy rates. It's not a "1 in 1 million" chance of a false match, it's closer to 1 in 4 -- because the 48 bit values per signature are not independent.

As I re-read Meta's research paper, I realized that the statistical error wasn't an oversight; Meta's researchers explicitly acknowledged the problem. In their paper (Section 4.1), they wrote:
Second, we observed that Wโ€™s output bits for vanilla images are correlated and highly biased, which violates the assumptions of Sec. 3.1 [the section about independent statistical test methods].
In other words, they recognized that the extracted bits are not independent. Despite this, their published false-positive analysis still relies on the assumption that the bits are independent.

Widespread Problems

Knowing that Meta's accuracy rate is grossly inflated due to assuming bit-wise independence when there is none, I looked back over Google's and Adobe's papers for their own watermarks. Did Google's and Adobe's researchers make this same mistake?
  • Google's SynthID research paper talks in terms of True Positive Rates (TPR). They do make this same "bit-wise independent" mistake, but it's obfuscated in the paper. You can see the error in their Equation 3 (PDF page 8), where they assume there is a uniform (independent) distribution. Their paper hyperfocuses on the true positive rate and never addresses the false positive distribution. (Either they didn't know to look, or they knew and decided to not report it because it would expose a serious weakness in their solution.)

  • Adobe's TrustMark research paper also makes assumptions of independence. You can see this in their PDF with the binary cross-entropy loss in Section 3.1.4. This mathematically treats each bit position as an independent Bernoulli trial. (By definition, a Bernoulli process strictly requires independence.) In their experiments (Section 4.1), they wrote "At test time, every image is associated with a random watermark", but they never tested if the random watermarks were similar to each other.
This introduction-to-statistics mistake is found in all three of these invisible watermarking technologies. The detections produced by these systems are so unreliable that an analyst cannot determine whether a reported detection is real or a false positive, or whether a reported non-detection is genuine or a false negative.

It's also worth noting that, shortly after releasing Stable Signature, Meta developed another algorithm: Pixel Seal. (Not to be confused with my own Secure Evidence Attribution Label / SEAL technology.) Pixel Seal moves to a 256-bit payload to increase the capacity, and their related model, Chunky Seal, pushes up to 1024 bits. While Meta's approach focuses heavily on addressing the invisibility side using an adversarial-only discriminator, the underlying approach still uses a neural network mapping. Using more bits only exacerbates this flaw.

Potential Uses

Algorithms can have uses. For example, Meta, Google, and Adobe are training their own AI models on images that they encounter. To prevent poisoning their training sets, they want to exclude images generated by their own systems. In this regard, watermarking does help them. For example, if Meta excludes an extra 25% of images (from false positives), then they still have a lot of images that they can train on.

However, that same usage does not work with legal cases. For example, consider an insurance company. Most insurance claims today include photographic evidence. The company wants camera-original photos, but have to use whatever the customer submits. The problem is that there is a lot of insurance fraud. In theory, seeing a watermark from an AI system like Meta, Google, or Adobe, should be great for identifying and ruling out fraud. Unfortunately, Stable Signature, SynthID, and TrustMark are so inaccurate that none of them can be trusted; it's not even worth testing to see if customer photos contain these invisible watermarks.

For these watermarking systems, I'm talking about very high error rates: roughly 1-in-4 for Meta, 1-in-5 for Adobe, and 1-in-20 for Google. But let's pretend that they work much better, like a 1-in-20,000 false positive rate. An insurer processing 100,000 claims per month would expect to accuse around 5 completely honest customers of fraud each month. Falsely denying 5 out of 100,000 claims? That creates a toxic customer service nightmare, severe legal liability, and fines from regulatory bodies for bad-faith claim denials. This could even become a class-action lawsuit that they couldn't win.

As bad as it is for insurance and financial institutions, there are much higher stakes at play. The EU AI Act (Article 50(2)), China's GB 45438-2025, California SB 942, and similar legislation are moving toward mandating AI content watermarking.

The failure of these three leading systems, from three Fortune-500 companies, to meet their own claimed accuracy rates is not just an academic curiosity. Regulators and courts will employ these systems for attribution and fraud detection. Reliable AI-based watermarking technology is not ready.

Three companies. Three algorithms. Three different research teams. The same fundamental error. The false positives won't go on trial. People will.
โŒ