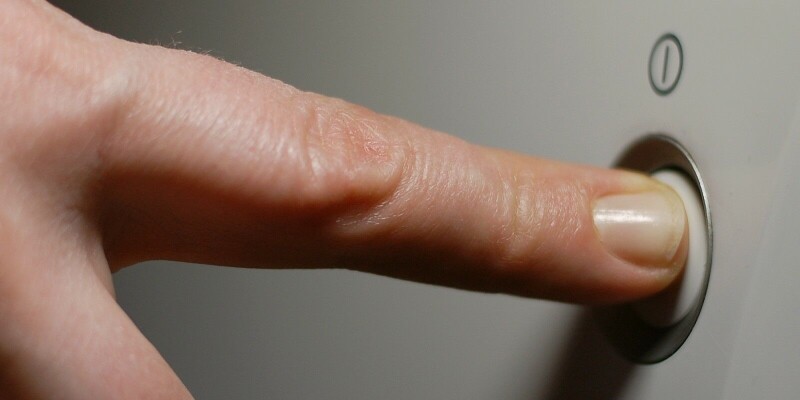
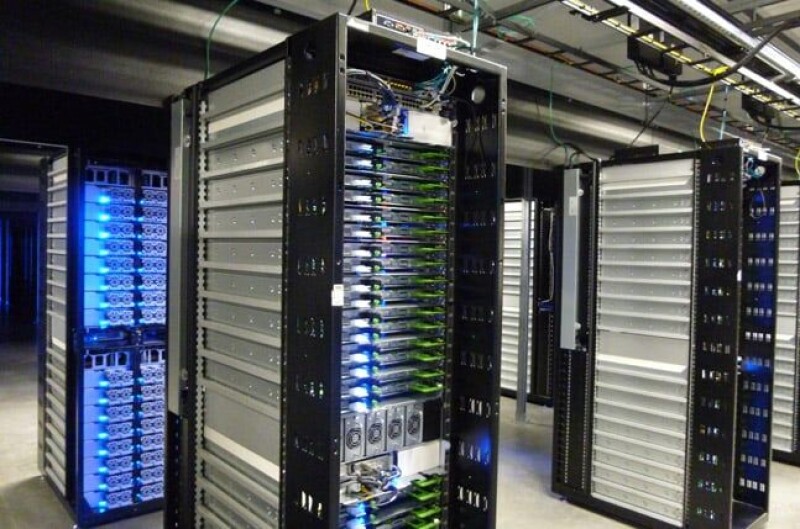
WHO, ME? Admitting to mistakes is a ticklish task, but one The Register tackles head-on each Monday in "Who, Me?" – the reader-contributed column that chronicles your worst working moments. This week, meet a reader we'll Regomize as "Bowman," who sent us a story from the early 2000s, a time when he says most servers were floor-mounted monsters. "I worked in an organization in Glasgow with a datacenter full of them, some with an external disk storage array sitting neatly beside the server." Maintenance was complicated by the arrays and servers looking remarkably similar. One fine day, Bowman learned that one of the servers needed some maintenance, including a hard reboot. A colleague named "Vince" set off to do the job, which everyone assumed would take a handful of minutes. Rather longer than expected passed before anyone realized Vince had not returned. Another member of the tech team was sent to check that Vince was all right. He soon returned with a grin and suggested that everyone should come and see what had happened. "Vince pressed what he thought was the relevant server's power button but immediately realized it belonged to the storage array sitting next to it," Bowman told The Register. Letting go of the power button would have turned off the array and caused an outage, but nobody else was within earshot. Vince therefore decided his best option was to keep his finger on the button. The entire tech team filed into the datacenter to witness Vince's predicament. "After taking sufficient time to show our support and compassion by pointing and laughing at him, and going to do under arm tickles, we finally asked the boss to take the server down with the excuse of 'urgent maintenance,'" Bowman wrote. "And that's how Vince's finger got some well-earned relief from the pressure it was under!" Have you been just a little cruel when confronted with a colleague’s misfortune? If so, you can confess by clicking here to send you story to Who, Me? ®
Nvidia spent a whopping $20 billion late last year to license Groq’s AI accelerator tech and hire away key members of its engineering team in an everything-but-the-kitchen-sink deal. The acquihire technically left Groq’s core inference-as-a-service business intact, but was clearly architected in such a way as to fly under regulators' radar. Only it didn’t. This week, The New York Times reported that the US Department of Justice had launched an antitrust probe into the deal. It’s hard to argue that Nvidia didn’t strip the startup for parts. It may not have been a merger in the traditional sense, but without its engineering staff, Groq may as well be Nvidia’s puppet at this point. Despite this, Nvidia contends the deal is a great American success story. “The Groq story is a prime example of the American system working as designed to promote innovation, reward entrepreneurs, and benefit consumers. The law is designed to encourage America's startup ecosystem and promote the fundamental rights of inventors and workers to pursue their dreams,” an Nvidia statement provided to El Reg and other media reads. Whether the acquihire of Groq actually harmed competition is another matter entirely. But, even if the Justice Department did force Nvidia to unwind the team, it’s probably too late. What exactly did Nvidia buy? Nvidia’s Groq acquihire bought it two key assets: mature silicon and the talent necessary to continue its development. Groq – which, by the way, is completely unrelated to Elon Musk’s Grok model series – made a name for itself using SRAM-heavy dataflow accelerators to speed up LLM inference to hundreds and now thousands of tokens a second, something that GPU-based systems from Nvidia had struggled to do on their own. But while faster than GPUs, the accelerators couldn’t achieve rapid throughput. Think of it this way: If Groq’s LPUs were the F1 cars, Nvidia’s GPUs were more like a city bus. But combine the two and you get something more akin to a sport pickup. At GTC in March, Nvidia unveiled its LPX racks, which are powered by 256 Groq-3 accelerators. As we understand it, they are really lightly modified versions of the startup’s existing Groq-2 chip designs, which makes sense, because three months is absurdly fast to tape out new silicon. Nvidia CEO Jensen Huang promised Groq-3 combined with its Vera Rubin GPU racks would deliver optimal performance across the entire spectrum of inference workloads. But, as we’ve discussed at length now, disaggregated compute architectures are not unique to Groq. Nvidia rival Cerebras is building similar systems with AWS and AMD, SambaNova is working with Intel, and d-Matrix and its partners are combining its in-memory compute platform with Nvidia GPUs to the same end as Nvidia’s Vera Rubin-LPX rack combo. The damage, if any, has been done Deals of this sort that are engineered to avoid regulatory scrutiny should get it anyway, several US senators have argued. While Nvidia didn’t outright buy Groq on paper, it may as well have. However, the real question for the DOJ is whether the deal was harmful to competition, and given the competitive landscape, proving harm may be easier said than done. But even if the DOJ found reason to litigate and was successful in unwinding the deal — it certainly wouldn’t be the first time regulators had torpedoed an Nvidia deal — it probably wouldn’t change much. Before Nvidia and Groq announced their licensing deal, the GPU giant was already laying the foundations for an ecosystem with its networking business at its center. In late 2024, the company contributed its MGX rack designs to the Open Compute Project (OCP) making it possible for any chipmaker to put their chips in racks originally designed for Nvidia GPUs. Then in mid-2025, GPUzilla opened its high-speed interconnect tech — the secret sauce that makes six dozen GPUs behave as one — to the broader industry through a licensing scheme called NVLink Fusion. As we recently discussed, the combination of open racks and Nvidia networking effectively meant that any chipmaker licensing the tech could slot their designs directly into Nvidia’s racks. If the DOJ blocked the acquihire and unwound the deal, Nvidia might lose direct control of LPU development and any revenues from the sale of the chips, but it wouldn’t necessarily be the end of its Groq LPX racks. Groq would just join the growing number of Nvidia hardware partners designing around the company’s AI factory ecosystem. In fact, if anything, the acquihire ensures that even if regulators eventually derail the deal, there will be plenty of alternatives lined up and ready to fill the void. ®
While high memory costs have hurt PC shipments, the server market continues to grow as AI infrastructure spending spreads beyond hyperscalers to corporate and government buyers. According to market intelligence firm IDC, the second quarter was a bumper one for the server sector, with vendor revenue reaching an all-time high of $166.3 billion. That was a 52 percent increase from the same period last year. The picture for servers therefore differs from that for laptops and desktops. There, unit shipments have fallen as buyers are discouraged by higher prices, driven by shortages of memory components. Yet higher prices have helped larger vendors sustain their revenue. In contrast, server shipments increased by 15.4 percent year-on-year in Q2, despite average selling prices being pushed up by elevated memory pricing and continued supply issues with other components. IDC said average selling prices increased across both GPU-accelerated and non-accelerated systems. Average selling prices for GPU-accelerated servers rose by nearly 44 percent to $170,200, even as GPU unit shipments fell 10.8 percent year-on-year. For non-accelerated systems, average pricing was up by more than 33 percent to nearly $13,000. AI infrastructure investment from hyperscalers and large cloud providers remains the largest source of demand, IDC observes. GPU-accelerated servers for the AI market made up nearly 53 percent of total revenue during Q2. However, it also says that AI server adoption is broadening beyond the largest players into enterprise and government-directed deployments across a growing number of countries, a policy and capex-driven layer of demand that is largely insulated from near-term commercial budget cycles. "The notable shift in the server market this quarter is in who is now buying," said Kuba Stolarski, IDC research vice president for Computing Platforms and Service Provider Infrastructure. "Demand is broadening beyond the largest hyperscalers toward specialized cloud providers (or neoclouds), sovereign AI programs backed by public capital, and enterprises beginning to adopt agentic and inferencing workloads," he added. Non-x86 servers now account for 44.8 percent of all server market revenue, according to IDC. That share has fallen from the first quarter, when they made up nearly half the total, despite the actual revenue figure rising from $58.7 billion to $74.4 billion. Another trend highlighted by IDC is that the big brands are starting to eat into the share of original design manufacturers (ODMs), the so-called white box server makers that have traditionally met the requirements of the hyperscalers. While ODMs collectively still make up the lion's share of server market revenue, this fell from over 60 percent last year to 53.9 percent in Q2. Leading the way is Dell Technologies, whose share rose from 7.7 percent a year ago to 13.4 percent. Supermicro is the second largest player, with 6.1 percent, followed by Lenovo on 5.1 percent, while HPE came fourth with 3.5 percent. The United States remains the biggest server market, generating $112.2 billion in Q2, or 67.4 percent of global revenue. China generated $26.4 billion, while Asia-Pacific excluding China and Japan reached $10.9 billion. Western Europe generated $9.1 billion and Central and Eastern Europe $0.7 billion. ®
AI infrastructure startup d-Matrix on Thursday joined the growing list of chipmakers licensing Nvidia’s NVLink Fusion interconnect tech and rack-scale reference designs to make its high-performance inference platform more accessible to customers. Under the deal, d-Matrix will integrate support for NVLink Fusion, a high-speed chip-to-chip interconnect that Nvidia began licensing last year, into future chip designs, including its upcoming Raptor accelerators. As we’ve previously reported, by embracing the tech, d-Matrix sidesteps many of the challenges associated with scaling its chip architecture across large compute clusters. By using NVLink over alternative interconnects and designing its compute blades around the GPU giant’s MGX reference designs, its customers can deploy its chips using the same racks and NVSwitch fabrics as Nvidia. By the end of next year, d-Matrix expects to offer systems with up to 144 Raptor accelerators connected by a single all-to-all NVLink fabric. While there’s a lot we don’t know about Raptor just yet, at the Hot Chips conference last month the company revealed each Raptor “card” would feature 32 GB of ultra-fast 3D-stacked DRAM on board capable of delivering 100 TB/s of memory bandwidth — roughly 4.5 times the memory bandwidth of Nvidia’s Rubin GPU. By the looks of things, the XPUs that will power d-Matrix's NVL144 racks are about half the size of the Raptor cards shown off at Hot Chips and include around 16 GB of 3D-DRAM and about 50 TB/s of memory bandwidth — still quite respectable by any measure. With 144 of these per rack, d-Matrix is looking at about 2.3 TB of memory capacity — enough for models exceeding four trillion parameters in size at 4-bit precision — and about 7.2 petabytes a second of peak aggregate memory bandwidth. This is achieved by bonding compute logic atop a stack of DRAM. The result is an in-memory compute platform that offers modest capacity while maintaining memory bandwidth closer to that of SRAM than is achievable using HBM. Memory bandwidth, as you may recall, is the biggest bottleneck for AI inference. The faster your memory, the faster the system can spew out tokens. This is exactly why Nvidia dropped $20 billion last year to license Groq’s IP and hire away its engineering talent. The chip’s SRAM-heavy dataflow architecture was capable of hitting 150 TB/s per chip, but the tradeoff is that SRAM isn’t very space-efficient and the chipmaker could only pack 500 MB of it onto a single die. d-Matrix's Raptor promises to deliver a decent fraction of that bandwidth with 64x higher capacity, which means the company can get away with using far fewer chips per model. Where a trillion-parameter model might need more than 2,000 Groq 3 LPUs at 8-bit precision, a single d-Matrix system would only need about 64 (32 at 4-bit precision). Just like Groq’s LPUs, d-Matrix chips can be deployed standalone, or as part of a heterogeneous compute config using GPUs for the compute-intensive prompt processing (prefill) phase of the inference pipeline and its Raptor accelerators for the memory bandwidth bound token generation (decode) phase. And for enterprises interested in the ultra-low latency inference capabilities of Groq, d-Matrix’s chips may offer a cheaper point of entry since fewer XPUs would be required. Nvidia’s walled garden We looked at Nvidia’s emerging IP licensing strategy in more detail last week, but in a nutshell, Nvidia stands to gain a lot more than licensing revenues from NVLink Fusion adopters. In addition to licensing Nvidia’s interconnect tech, d-Matrix plans to pair its accelerators with the GPU giant’s Vera CPUs, NVSwitch appliances, BlueField and ConnectX NICs, and SpectrumX Ethernet products. In other words, Nvidia stands to make a lot of money even if it’s not selling GPUs. It seems a fair number of chip designers are willing to make that kind of deal to avoid having to design their scale up networks or rack systems. Last week, MediaTek joined Marvell, Qualcomm, Arm, Fujitsu, and Amazon Web Services in adopting Nvidia’s NVLink Fusion interconnects. Nvidia is so invested in getting folks into its walled garden that it's spending billions on incentives to get them in the door. As part of the MediaTek deal last week, Nvidia invested $3.5 billion in the SoC designer, while it spent $2 billion to get Marvell in the door. No word on whether the latest deal included any such terms. ®
UPDATED OpenAI will design its next-generation AI accelerators with the help of South Korean foundry giant Samsung Electronics. This move could help the ChatGPT maker with memory, process tech, or other key things it needs to succeed. The announcement, made by OpenAI Korea general manager Harrison Kim in a press conference Wednesday, comes just weeks after the company showed its first-generation “Jalapeño” accelerators besting Nvidia’s Blackwell GPUs across a slew of inference workloads. "One of the areas where we have made the most progress and gained the most recognition with Samsung Electronics is our joint production and research on the next-generation chips we are developing," he said, according to Reuters. Following publication, OpenAI got in touch to clarify that Kim's comments were made in reference to OpenAI's existing relationship with Samsung announced last year, not a new deal. "The reference to expanding our collaboration with Samsung was made in the context of our existing relationship, including Samsung Electronics’ adoption of ChatGPT and the LOI announced last October. We have nothing new to announce. We did not announce plans to manufacture chips through Samsung," a OpenAI spokesperson told El Reg after the story published. Now that the hype has died down and Wall Street has convinced themselves that the rise of AI ASICs isn’t the threat to Nvidia’s dominance they feared, OpenAI still has to contend with the realities of being a fabless chip designer. The vast majority of leading edge silicon made today comes from a single company: TSMC. That means securing meaningful capacity requires competing with AMD, Nvidia, and practically every other chip biz and hyperscaler designing their own chips. But TSMC isn’t the only leading edge wafer fab out there. They’re just the biggest. Smaller, less popular options include Samsung Electronics and Intel Foundry. The supply of high-bandwidth memory (HBM), which OpenAI’s (and Broadcom if we’re being honest here) designs make extensive use of, is similarly constrained with just three major manufacturers capable of producing it in volume: SK Hynix, Micron, and you guessed it, Samsung Electronics. This puts OpenAI in a tough spot of having to compete with larger, higher volume chip designers for both logic and memory silicon. As such, OpenAI’s tie-up with Samsung could go two ways. The most obvious, but also the least interesting, is that Samsung will supply all or at least some of the HBM used in the model dev’s next-gen chips, which we’ll call Habanero for lack of an official code name. Detailed at Hot Chips last month, OpenAI’s Jalapeño AI inference chip uses HBM4, the same tech used by AMD and Nvidia’s latest GPUs. That tells us that there's a pretty good chance Habanero will likely use the faster HBM4E. And given the ongoing memory shortage, if OpenAI wants to secure ample supply, it’s going to need to forge these relationships early. Besides supply chain, timing is important because there’s a good chance OpenAI’s next chip will take advantage of custom base dies to move things like memory controllers or even some logic from the compute silicon to the HBM stack itself. If you recall Nvidia’s disclosures around NVHBM a few weeks back, it’s the same idea. However, these custom base dies require some coordination with the HBM supplier, so fostering a close relationship with Samsung now would benefit OpenAI, even if the compute chiplets themselves end up being manufactured by TSMC. While the most obvious reason for OpenAI’s tie-up with Samsung is memory-related, it could conceivably fab its next chip on Samsung’s 2 nm process tech just to have an alternative supplier to TSMC. Samsung is the second largest leading edge foundry operator in the world and used to produce a lot of silicon for the likes of Nvidia, Apple and others. Nvidia’s Ampere generation used Samsung’s 8 nm process tech for the majority of its PCIe-based cards, while its HBM-equipped accelerators were exclusively fabbed by TSMC. But a number of factors, including the rise of multi-die architectures requiring advanced packaging and broader adoption of HBM-based accelerators, made TSMC the more attractive option. Reported challenges with Samsung’s yields across its 3 nm process tech probably didn’t help either. But as of 2026, Samsung is looking a lot more compelling, with chip designers including Rebellions, Tenstorrent, and Groq building sophisticated AI accelerators at its fabs. Rebellions’ Rebel100 accelerator is a particularly useful proof point as it utilizes a multi-die architecture and HBM3E, both of which require sophisticated advanced techniques to stitch everything together. The chip shows that Samsung is more than capable of producing OpenAI’s next chip. What’s more, doing so could open the door to larger allocations than they would get from TSMC alone. ® Updated 9/10 at 2100 GMT to reflect that this is not a new deal.
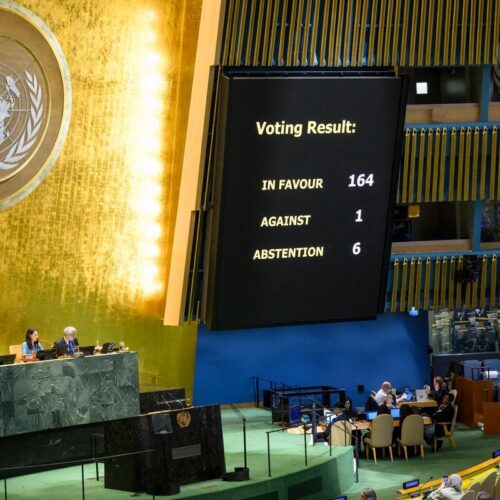
Nearly every country represented in the United Nations General Assembly recently voted in favor of promoting world maps that more accurately show the size of various continents. But the UN resolution is unlikely to change how millions of people regularly see versions of 16th-century Mercator maps depicting skewed continent sizes in navigation apps.
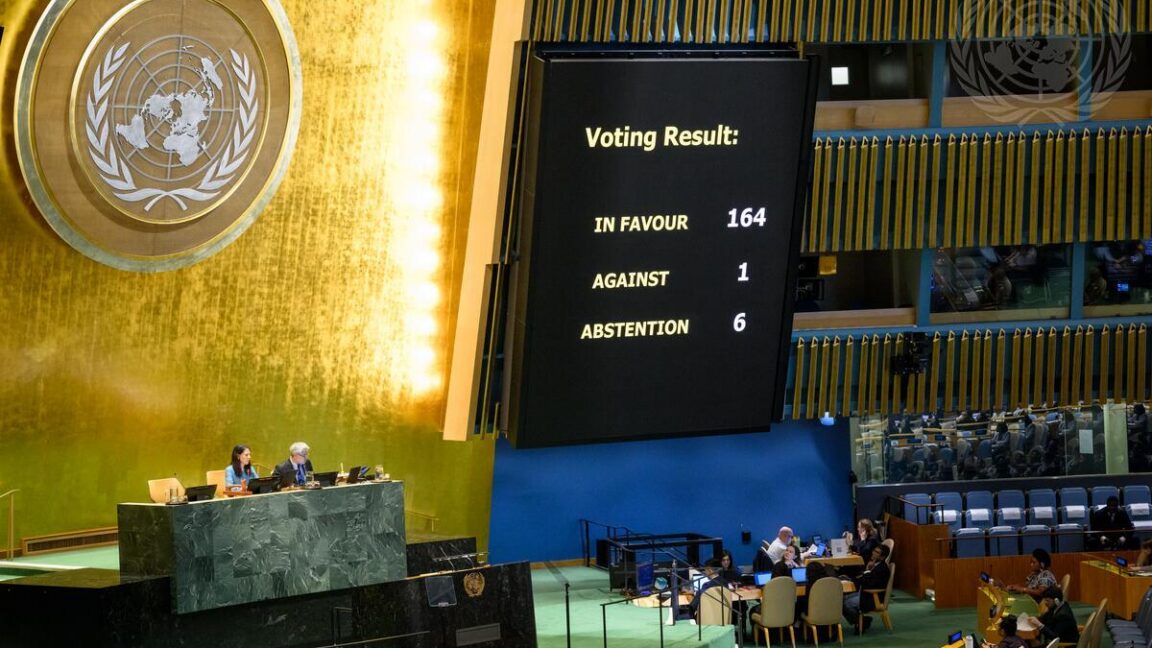
On September 4, the African-led resolution attracted 164 votes in favor, with six countries abstaining from voting. Only the United States voted to oppose the resolution after describing it as a “radical ideological project,” according to UN News.
The non-binding UN resolution does not impose map changes on anyone. Instead, it “encourages governments, schools, international organizations, and technology companies to use the Equal Earth projection and other so-called equal-area maps when relative size matters,” UN News reported. The resolution also encourages teaching about the trade-offs that arise from depicting a spherical planet on a flat map.
China’s military is exploring humanoid robots for urban combat as the country’s commercial robotics industry dominates global shipments and manufacturing.
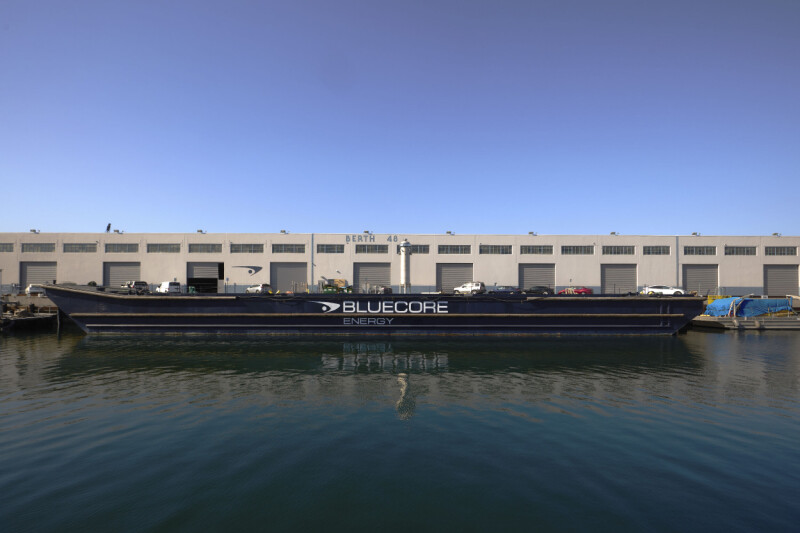
Startup Bluecore Energy has raised $50 million in seed funding to develop floating nuclear power plants intended to supply ports and other locations with rapidly growing energy demands. The California-based company said the Silverton Partners-led round, which includes $10 million in previously announced pre-seed funding, brought in several new investors. It plans to use the money to engineer and test its compact nuclear power system and pursue regulatory approval and maritime classification. Its initial design is intended to generate about 10 MWe – megawatts of electrical output – continuously using light-water reactor technology. Bluecore says the maritime system would be able to operate for years at a time and require refueling only once every few years. The company has secured its first barge and is developing a non-fueled, electrically heated reactor module prototype at its Port of Long Beach headquarters to test monitoring, sensor, and control systems. Bluecore is targeting ports, AI datacenters, and coastal infrastructure, with the reactors potentially deployed offshore and connected to customers by subsea cables. Remote islands and coastal settlements in places such as Alaska may also lack practical connections to a wider electricity grid. Bluecore claims its approach could provide reliable, zero-emission power to energy-intensive locations and open additional markets for nuclear generation. "Six months ago, we were building the foundation. Today, we have the capital, the team, the hardware, and some of the most important institutions in nuclear and maritime working alongside us," said Bluecore founder and CEO Kofi Asante. "Our focus now is simple: create and deliver zero-emission energy as safely and quickly as possible." The move follows the launch of the International Atomic Energy Agency's (IAEA) Atomic Technologies Licensed for Applications at Sea (ATLAS) initiative in the US capital last month. Secretary of Energy Chris Wright linked that event to the Department of Energy's own efforts to rapidly expand the provisioning of atomic energy generating capacity in order to meet the requirements of AI datacenters and other industries. Bluecore has begun discussions with the US Nuclear Regulatory Commission (NRC) and Coast Guard. The two agencies recently signed a memorandum of understanding to coordinate oversight of the design, construction, and operation of civilian floating nuclear power plants. The NRC says it is ready to license maritime reactors under existing federal regulations, while it develops an additional framework for microreactors and similarly low-risk designs. Bluecore remains years from commercial deployment. It has yet to build a fueled reactor or apply for the approvals required to operate one, and its Long Beach proposal must also navigate California's restrictions on new nuclear power plants. While some may have concerns about waterborne atomic power plants, America has a long history of maritime nuclear generation. All of the US Navy's active aircraft carriers are nuclear-powered, but the technology first went to sea aboard the submarine USS Nautilus in 1955. USS Enterprise became the first nuclear-powered aircraft carrier in 1961, while the cruiser USS Long Beach, commissioned the same year, was the first nuclear-powered surface combatant. Bluecore says its team includes former US Navy nuclear submarine officers and leaders with experience across organizations including SpaceX, Northrop Grumman, Toyota, Rivian, and Uber. Russia currently operates the world's only floating nuclear power plant. The barge-like Akademik Lomonosov is considerably larger than Bluecore's proposed design and can generate up to 70 MWe. ®
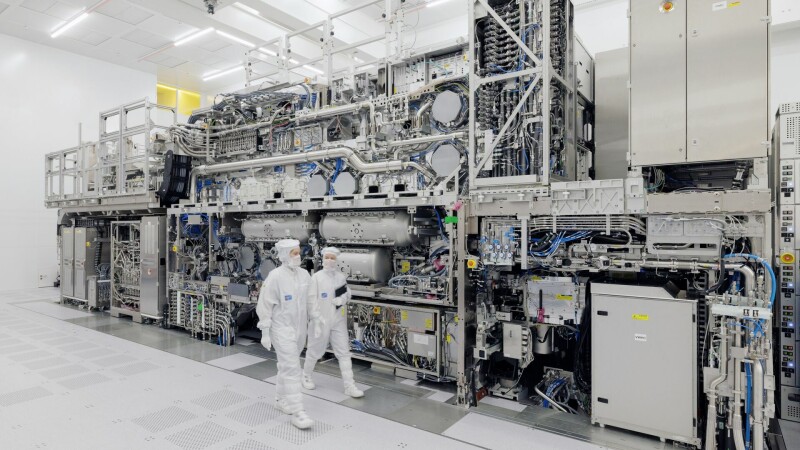
ASML and chipmaking giant TSMC have launched an industry-wide push toward 12-inch photomasks, saying the larger format could lower costs and overcome some limitations of high-NA EUV lithography. Dutch firm ASML, the only commercial supplier of EUV lithography systems, says it and TSMC have established a collaboration intended to lead the transition to larger-format photomasks for extreme ultraviolet (EUV) lithography. Intel Foundry and Samsung Electronics have also voiced their support. The initiative aims to establish a 12-inch mask pilot line by 2031 and have the supporting lithography systems ready for advanced node production by 2033. According to ASML, high-NA EUV will initially enter production using current 6-inch masks, but moving to 12-inch masks could increase fab productivity, lower costs, and remove stitching constraints. The push for larger masks stems from the anamorphic optical design ASML adopted for its first generation of high-NA EUV machines so chipmakers could continue using existing 6-inch masks. The "NA" in high-NA EUV stands for numerical aperture – a measure of an optical system's ability to collect and focus light. Achieving a higher NA required larger optics, which increased the angle at which light strikes the reticle, or mask, creating shadowing and contrast problems. ASML says it could have used optics that reduced the mask pattern by 8x in both directions, rather than the 4x used in existing systems, but that would have required larger masks. Instead, it adopted anamorphic optics that reduce the image by 4x in one axis and 8x in the other, allowing chipmakers to continue using 6-inch masks. The trade-off is an exposure field half the size of that in previous machines. Large dies that exceed this field may therefore require two separately exposed patterns to be stitched together, adding complexity and reducing productivity. ASML and TSMC now see larger masks as a way to restore the full exposure field as the industry pushes toward denser chips and smaller process nodes. "We expect the adoption of High NA EUV to increase progressively along the device scaling roadmap, first using current 6-inch masks and then further supported by 12-inch masks, which enable greater scanner productivity and allow the industry to meet the demand for smaller, faster and more energy-efficient chips," said ASML president and CEO Christophe Fouquet. TSMC has so far not used high-NA EUV, including for its 2 nm process, but says it intends to deploy the technology in high-volume manufacturing for advanced nodes beginning in 2030. It expects the number of layers requiring high-NA EUV will rise as new process nodes are introduced, driven by increasingly complex transistor architectures required for AI applications. Intel Foundry signaled its support for the initiative, with EVP Naga Chandrasekaran saying: "Within our lithography capabilities, Intel Foundry is focused on near term enablement of high-NA on 6-inch masks with or without stitching, and making the transition to 6x12-inch masks. We will continue to work closely with ASML and the entire industry to enable this transition." Samsung is also backing the initiative and says it plans to become the first chipmaker to introduce ASML's high-NA EUV technology into high-volume DRAM manufacturing by 2028. "The AI era is transforming the semiconductor industry and increasing the importance of technological innovation across the entire value chain," said Samsung Electronics vice chairman and CEO Young Hyun Jun. "By further strengthening our collaboration with ASML, we are helping lay the foundation for the next generation of AI and semiconductor innovation." IDC senior research director Andrew Buss told The Register that high-NA EUV creates design and manufacturing challenges for future products. Although reticle stitching and chiplet designs can mitigate these, he said, the move to 6 x 12-inch photomasks is a necessary step comparable to the industry's transition from 200 mm to 300 mm wafers. Buss said the transition would require toolmakers, chip manufacturers, mask suppliers, and designers to align their technologies and processes, making broad industry participation essential. ®
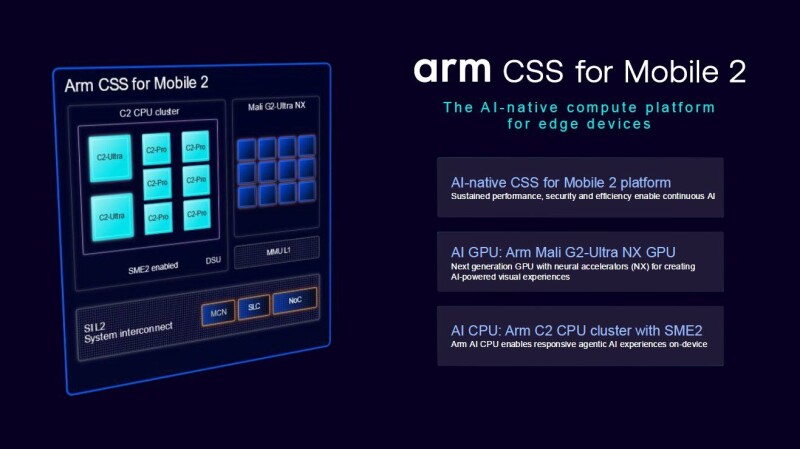
Arm's latest smartphone platform is optimized for running AI agents on mobile devices and introduces neural graphics that it claims can deliver desktop-class gaming within a smartphone's power constraints. Announced at the Arm Everywhere China event in Shanghai today, Compute Subsystem (CSS) for Mobile 2 succeeds last year's Lumex CSS and reflects Arm's embrace of AI as a strategy for future growth. Arm sees itself as central to this shift, arguing that AI workloads currently run largely in the cloud but will increasingly move to devices at the network edge. "When every interaction has to travel to a datacenter and back, there's implications for latency, connectivity, the cost of delivering those services at enormous scale, so this is where we're seeing it becoming more distributed, and I think few doubt now that basically everything you can push to the edge you will," says Arm's EVP of Edge AI, Chris Bergey. AI has evolved from background capabilities such as speech recognition and image processing into tools people actively engage with, including generative assistants, Bergey claims. Agentic AI goes further by interpreting objectives, coordinating applications and models, and executing sequences of actions. "So you have repeated inference, application logic, system orchestration, multiple workloads operating concurrently, and so that means you don't just need more CPU performance. You need multiple high-performance CPUs working in parallel to keep all those different workloads running," Bergey explains. With this in mind, the C2 CPU cluster features a new top-end C2-Ultra core that Arm claims delivers up to 15 percent higher single-thread performance than last year's C1-Ultra. The C2-Ultra cores have a larger execution engine to keep more instructions in flight, and Arm claims more accurate branch prediction and better fetch and target prediction to keep the instruction pipelines fed. Arm's chipmaker licensees can mix and match components to suit their requirements, as usual, but the firm touts a flagship cluster with two C2-Ultra cores, six efficiency-focused C2-Pro cores, and two SME2 units (Scalable Matrix Extensions), compared with one SME2 unit in last year's platform. Doubling the SME2 capability enables up to a 70 percent speedup on the latest small language models, according to Arm, while the cluster topology supports private caches on the individual CPUs plus a large shared L3 cache. All of this is tied together by the DSU, or the DynamIQ Shared Unit. Arm says the cluster has been optimized to reduce latency and keep concurrent agentic workloads responsive. CSS for Mobile 2 also introduces dedicated neural acceleration for graphics in the Mali G2-Ultra NX, which Arm calls its first AI-native Mali GPU. Arm previewed the neural technology last year, giving developers time to prepare for the hardware. The GPU introduces an all-new execution engine, neural accelerator hardware, and a third-generation ray tracing unit, built for full-scene lighting and shadows. The hardware supports Neural Super Sampling (NSS), which upscales game graphics from 540p to 1080p, and Neural Frame Rate Upscaling (NFRU), which generates intermediate frames to increase the frame rate. Using both techniques means the GPU renders one eighth of the pixels contained in the final sequence of displayed frames, with the neural hardware reconstructing the rest. Arm claims this makes desktop-class graphics possible within a 1 W power budget. "The G2-Ultra NX GPU is able to sustain a 30 frame per second gaming session on content with very rich and intricate ray traced scenery. And this is really enabled thanks to a 70 percent reduction in the overall ray tracing workload, which then translates to a 30 percent boost in performance," says GPU Product Manager Deyan Lazarov. Arm also demonstrated other games running at 60 frames per second. Like the CPU cores, Arm is offering Premium and Pro variants of the Mali G2 GPU, allowing its chipmaker customers to trade off performance against cost. To encourage uptake, Arm has published its neural graphics SDK and sample code on GitHub, with support for the cross-platform Vulkan graphics API. As with previous Arm smartphone platforms, chipmakers must now turn the designs into working silicon before smartphone vendors can bring devices to market, possibly as early as next year. ®
Huawei has launched a new processor it claims is free of US technology and is using it to drive a new three-screen folding phone. The Chinese giant dubbed the new processor the Kirin 9050 Pro and says its LinxiCore processor cores, GPU, and neural processing unit all feature its own designs. The SoC into which Huawei added them uses the "Tau Scaling” architecture that Huawei says arranges components closer to each other to reduce die size and improve performance without needing the kind of advanced chipmaking processes practiced by TSMC and Intel. As The Register wrote when Huawei announced Tau Scaling last May, analysts think Huawei has done interesting things with its silicon but don’t think the company has made any breakthroughs. Huawei begs to differ and says its new silicon offers 42 percent higher performance than the chip it used in the three-screen phone it delivered last year. The Chinese company uses the Kirin 9050 Pro in its new three-screen phone, the $2,979 Mate XT2. Analyst firm Counterpoint thinks Huawei will exit 2026 with 24 percent of the total folding phone market, which it believes accounted for 1.6 percent of smartphone sales last year. Huawei therefore has itself a chip that targets the high end of a market niche – and announced it a couple of days before pundits believe Apple will debut a folding iPhone that Counterpoint predicts will win 25 percent of the folding phone market by the end of the year. Huawei’s Kirin 9050 Pro will therefore hardly make a dent in the smartphone market. At its launch event, Huawei execs pointed to its totally-not-Android versions of HarmonyOS now running on 85 million devices. That’s strong uptake since Huawei delivered the OS in October 2024. Again, however, it is a fraction of the overall smartphone and smart device market. If Huawei can use the tech it created for the Kirin 9050 Pro in other roles that would allow local orgs to avoid comparable products from AMD, Intel, or Nvidia, its new chip will show that Chinese firms can create tech that reduces the nation’s reliance on imports. But amid all the hoopla of a phone launch, Huawei hasn’t said anything about its intentions to adapt its new chip for different roles. The Tau Scaling architecture is therefore not going to upset Huawei’s rivals for some time, although western chipmakers do know that Beijing is steering local buyers away from their products and encouraging adoption of local alternatives. Whether any of those Chinese chipmakers succeed beyond the Middle Kingdom is the wider question. China emphasizes export of consumer products as a tactic to fuel domestic growth, and its smartphone makers Xiaomi, Oppo, and Honor have delivered on that mission by winning solid sales across Europe, Africa, and Latin America – with phones running Android and tied to Google services. Huawei’s hardware and HarmonyOS ecosystem, by contrast, have not racked up notable success outside China. ®
ColorOS 17 brings a redesigned interface, new navigation, Lockscreen Island, performance changes, and closer integration across OPPO, OnePlus, and realme.
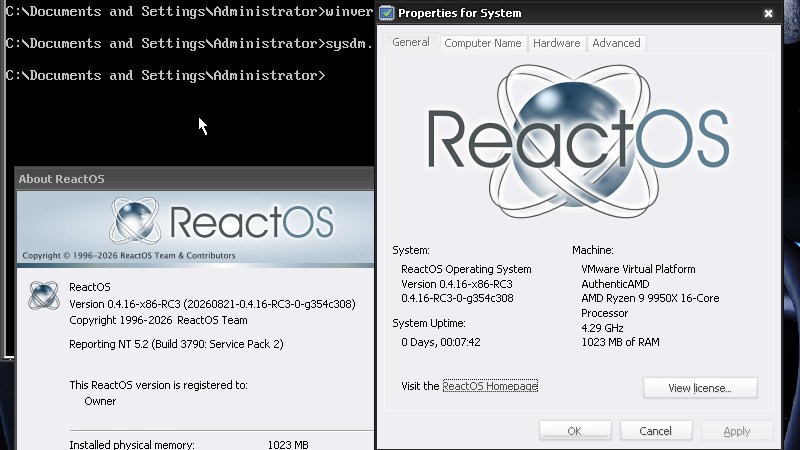
A perennial in the esoteric operating system space is ReactOS, a project with its roots in the 1990s which is doing a pretty good job of creating an open source clone of 32-bit Windows. They have a new version out, and it’s acquired some useful features.
Top of the list is a new graphical installer, removing the need for separate live and install ISOs, followed by improvements in video bug fixes and high definition audio drivers and subsystems. There’s a headless server install too, in which the GUI is suppressed. Perhaps most interesting, they are working on version syncing the open-source projects such as WINE on which they rely, meaning with luck that any improvements there will show up in ReactOS.
A while back we took a look at using ReactOS as a daily, and found it to be quirks aside, as usable as you’rd expect a Windows XP clone to be. Given that there are plenty of pieces of hardware and software around that still need an early-2000s era Windows to run, this remains an OS to keep an eye on.
The proliferation of custom AI ASICs, or XPUs, from OpenAI, Meta, Microsoft, and others has led many to question Nvidia's grip on the market. After all, if everybody's building their own, who needs the GPUs the AI arms dealer has made its fortune on? But Nvidia isn't concerned in the least and has instead invited its competition to raid – or, rather, license – the GPU giant's IP holdings, particularly those related to networking. On Monday, MediaTek became the latest to embrace Nvidia's NVLink Fusion high-speed interconnect technology for its fledgling datacenter XPU offering. In exchange, Nvidia has invested $3.5 billion in convertible bonds issued by MediaTek. The GPU giant will also continue to license the Taiwanese SoC provider's own designs for use in future DGX and RTX Spark systems. If you're curious, we explored MediaTek's datacenter ambitions last month. But the designer, best known for its Arm-based smartphone and tablet processors, is only one of several high-profile chip designers that plan to integrate the tech. Amazon, Fujitsu, Qualcomm, Arm, and Marvell are all on the same list. NVLink Fusion started as a commercialized version of Nvidia's high-speed inter-GPU interconnect, introduced early last year. Initially, it was offered in two varieties: a chip-to-chip (C2C) variant for connecting CPUs to GPUs (or XPUs) in a memory coherent fabric, and a switched fabric used to stitch together multiple accelerators into one big logical rack-scale chip. It's since expanded to become the blanket offering by which Nvidia licenses its semiconductor IP. Given how long it's taken Broadcom and others to develop competitive alternatives to NVLink, it's not surprising companies like MediaTek would license the tech, rather than reinventing the wheel, or piping alternative interconnects, like UALink, over regular old Ethernet. By licensing Nvidia's NVLink Fusion tech, companies can focus on building competitive accelerators without worrying about how they're going to scale in production. And because Nvidia's MGX rack designs are part of the Open Compute Project, MediaTek and its partners not only benefit from Nvidia's scale-up networking tech, but also can essentially take existing NVL72 racks and slot in their compute blades. This should dramatically reduce the system design and mechanical engineering experience required to go from silicon to AI racks. And this isn't theoretical. Amazon is doing just that with its Trainium series of AI accelerators. As we wrote at the time, Amazon used Nvidia's MGX NVL72 reference design for its Trainium3-based rack systems launched last year. Meanwhile Trainium4, expected late this year, will ditch Amazon's in-house NeuronLink interconnect tech for NVLink Fusion. Nvidia's cut So, what does Nvidia get from letting rival chip designers piggyback off its hard-won networking tech? A lot more than licensing fees: It's also a way to keep companies hooked on its other products. When NVLink Fusion was first announced, customers had two options. They could pair their XPUs with Nvidia's CPUs or their CPUs with Nvidia's GPUs. Customers also were on the hook for NVSwitches if they wanted to take advantage of the tech's scale up networking capabilities. So, on top of licensing the tech, Nvidia had the potential to sell roughly two GPUs per partner CPU, a Grace or Vera CPU for every two partner XPUs, and up to nine NVSwitches for every 72 or so accelerators, and that's just the rack. If you're already buying NVLink, why not use InfiniBand or Nvidia's Spectrum-X Ethernet kit to switch those racks together to train and serve even larger models at scale? Nvidia has since softened its stance and now seems content with the combination of NVSwitch sales and NVLink Fusion licensing. If it hadn’t, Amazon couldn’t have paired Graviton with Trainium. "The beauty about this platform is it provides the flexibility and the fungibility in order to meet the customers where they are. And so, leveraging the NVLink Fusion platform, they can adopt anywhere from the CPU to the GPU to the scale-up fabric to the scale-out networking across our Spectrum-X and InfiniBand, as well as our DPU within the scale-in fabric to do the north-south storage management as well as security isolation," Dion Harris, Nvidia's senior director of HPC and AI Hyperscale Infrastructure, told press on Monday. "So, the five different networking technologies and topologies that we offer in our technology stack are all available to customers via NVLink Fusion." Nvidia isn't quite ready to talk about the licensing structure just yet, but Harris says they won’t be giving it away. "…It is safe to assume that there will be some licensing elements in place in that Nvidia NVLink Fusion is an Nvidia technology," Harris said. It's not just about networking Nvidia is already the largest datacenter Ethernet networking provider in the world, thanks in no small part to the AI boom. Its quarterly networking revenue now exceeds $15 billion, and NVLink Fusion licenses and associated NVSwitch sales will only bolster that. However, Nvidia's licensing ambitions don't stop there. Last week, Nvidia detailed its latest IP offering in the form of NVHBM, essentially a custom base with an integrated memory controller. According to Nvidia, the approach frees up 25 percent of the die for compute while cutting HBM power draw by 15 percent and boosting effective bandwidth by 30 percent. Amazon's Annapurna Labs will be among the first to field the tech with its Trainium family of AI ASICs. But while Amazon's adoption of NVHBM is a clear win for Nvidia, it should be noted that the idea isn't unique to Nvidia. As we understand it, both Broadcom and Marvell are developing similar base-die tech as well. But the tech is another example of how Nvidia is leveraging its engineering might to extract revenues from everything associated with AI, including custom ASICs from others. A deal with the devil or mutually beneficial coexistence While Nvidia's fledgling IP offerings are rather narrow for the moment, it's not hard to imagine Nvidia competing with rivals like Broadcom or partners like Marvell and MediaTek on XPU design before long. Depending on how things play out, Nvidia, Broadcom, Marvell, and MediaTek could end up looking more like frenemies. XPUs are quickly becoming big business for both Broadcom and Marvell, but the networking required to scale that compute and system design required to bring it to market remains a competitive advantage for Nvidia. Sure, both have competent Ethernet switching appliances capable of going toe-to-toe with NVSwitch, but even then you still have to integrate that into a rack. The advantage of being able to slot a custom compute blade into a generic NVL72 system and for it to work out of the box is hard to ignore. If NVLink Fusion helps the XPU designers sell more chips, it could end up being a net benefit even if it means losing out on switch sales. Nvidia is clearly aware that while the barrier to entry for custom silicon has fallen through the floor, scaling that compute remains the hard part. ®
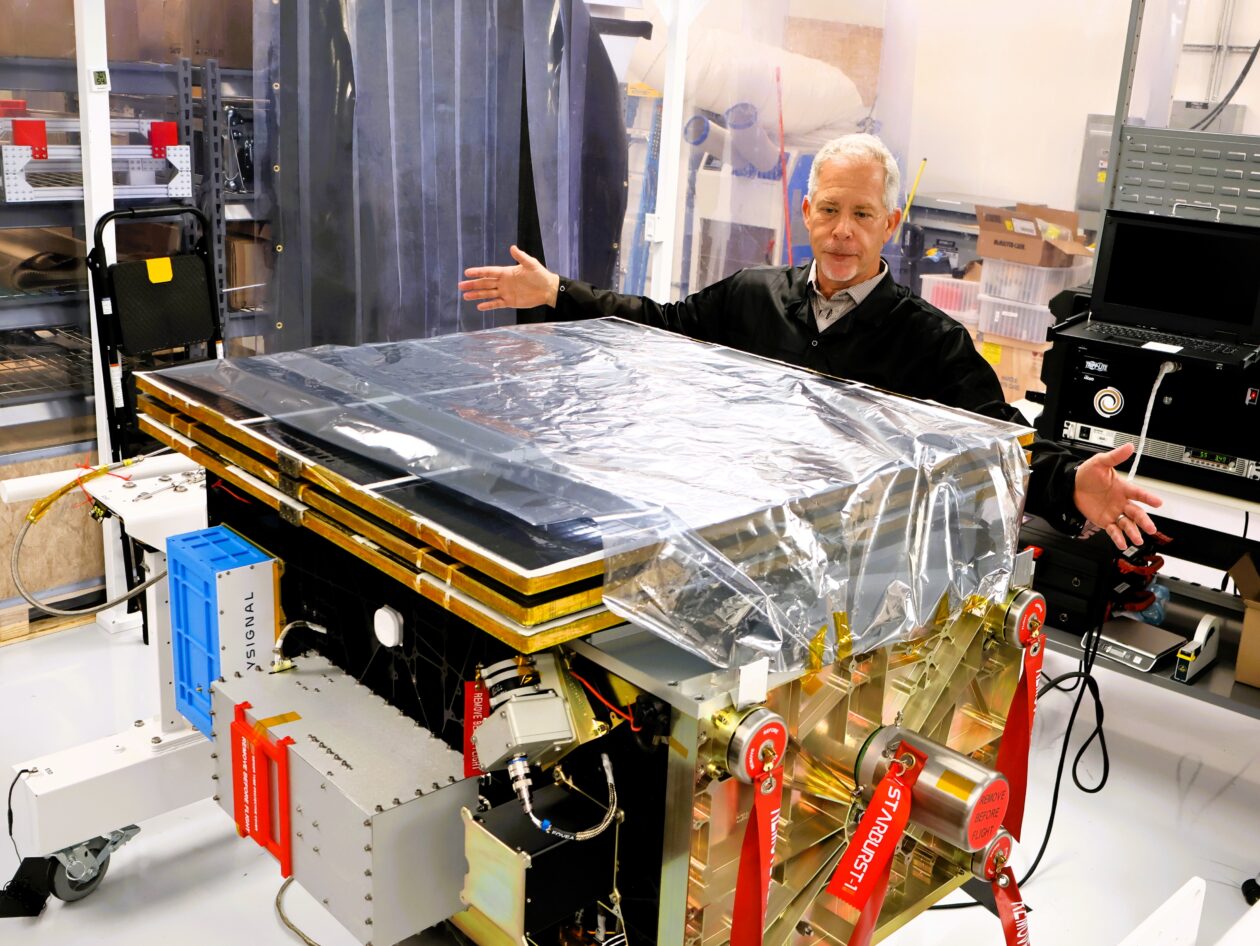
Portal Space Systems’ co-founder and CEO, Jeff Thornburg, shows off the Starburst-1 satellite in the company’s Bothell lab. (Portal Space Systems Photo)
BOTHELL, Wash. — Portal Space Systems is getting ready to send its first Starburst spacecraft to Florida for a milestone launch, and at the same time is fleshing out its plans for launching an even more capable spacecraft known as Supernova.
Both spacecraft are designed to offer rapid maneuverability in orbit at low cost, and both will take advantage of Portal’s core technologies, supply chains and manufacturing processes. But Supernova will be heavier than Starburst (1,100 pounds vs. 600 pounds) and will make use of an innovative solar thermal propulsion system to move within a wider range of orbits.
Starburst-1 will blaze the trail for Supernova. The desk-sized spacecraft recently returned to the Bothell lab after undergoing a round of vibration testing in California. It’s scheduled for an October launch from Cape Canaveral Space Force Station in Florida on SpaceX’s Bandwagon-5 satellite rideshare mission.
Portal CEO Jeff Thornburg said he expected Starburst-1 to be trucked to Florida in September, after engineers make their final software adjustments.
“Until we get ready to fly, we’ll be constantly testing it and evaluating its health, and making any tweaks that we think we need to make,” he said. “Anything that helps reduce the risk for the first flight, up to the point where we launch — we’ll implement that if we need to.”
Back in March, Portal sent a payload about the size of a tissue box into space to test the electronics and control systems designed for Starburst and Supernova. That instrument package, known as “Mini-Nova,” is still attached to an orbiting space vehicle, but a replica is displayed in a conference room next to the lab.
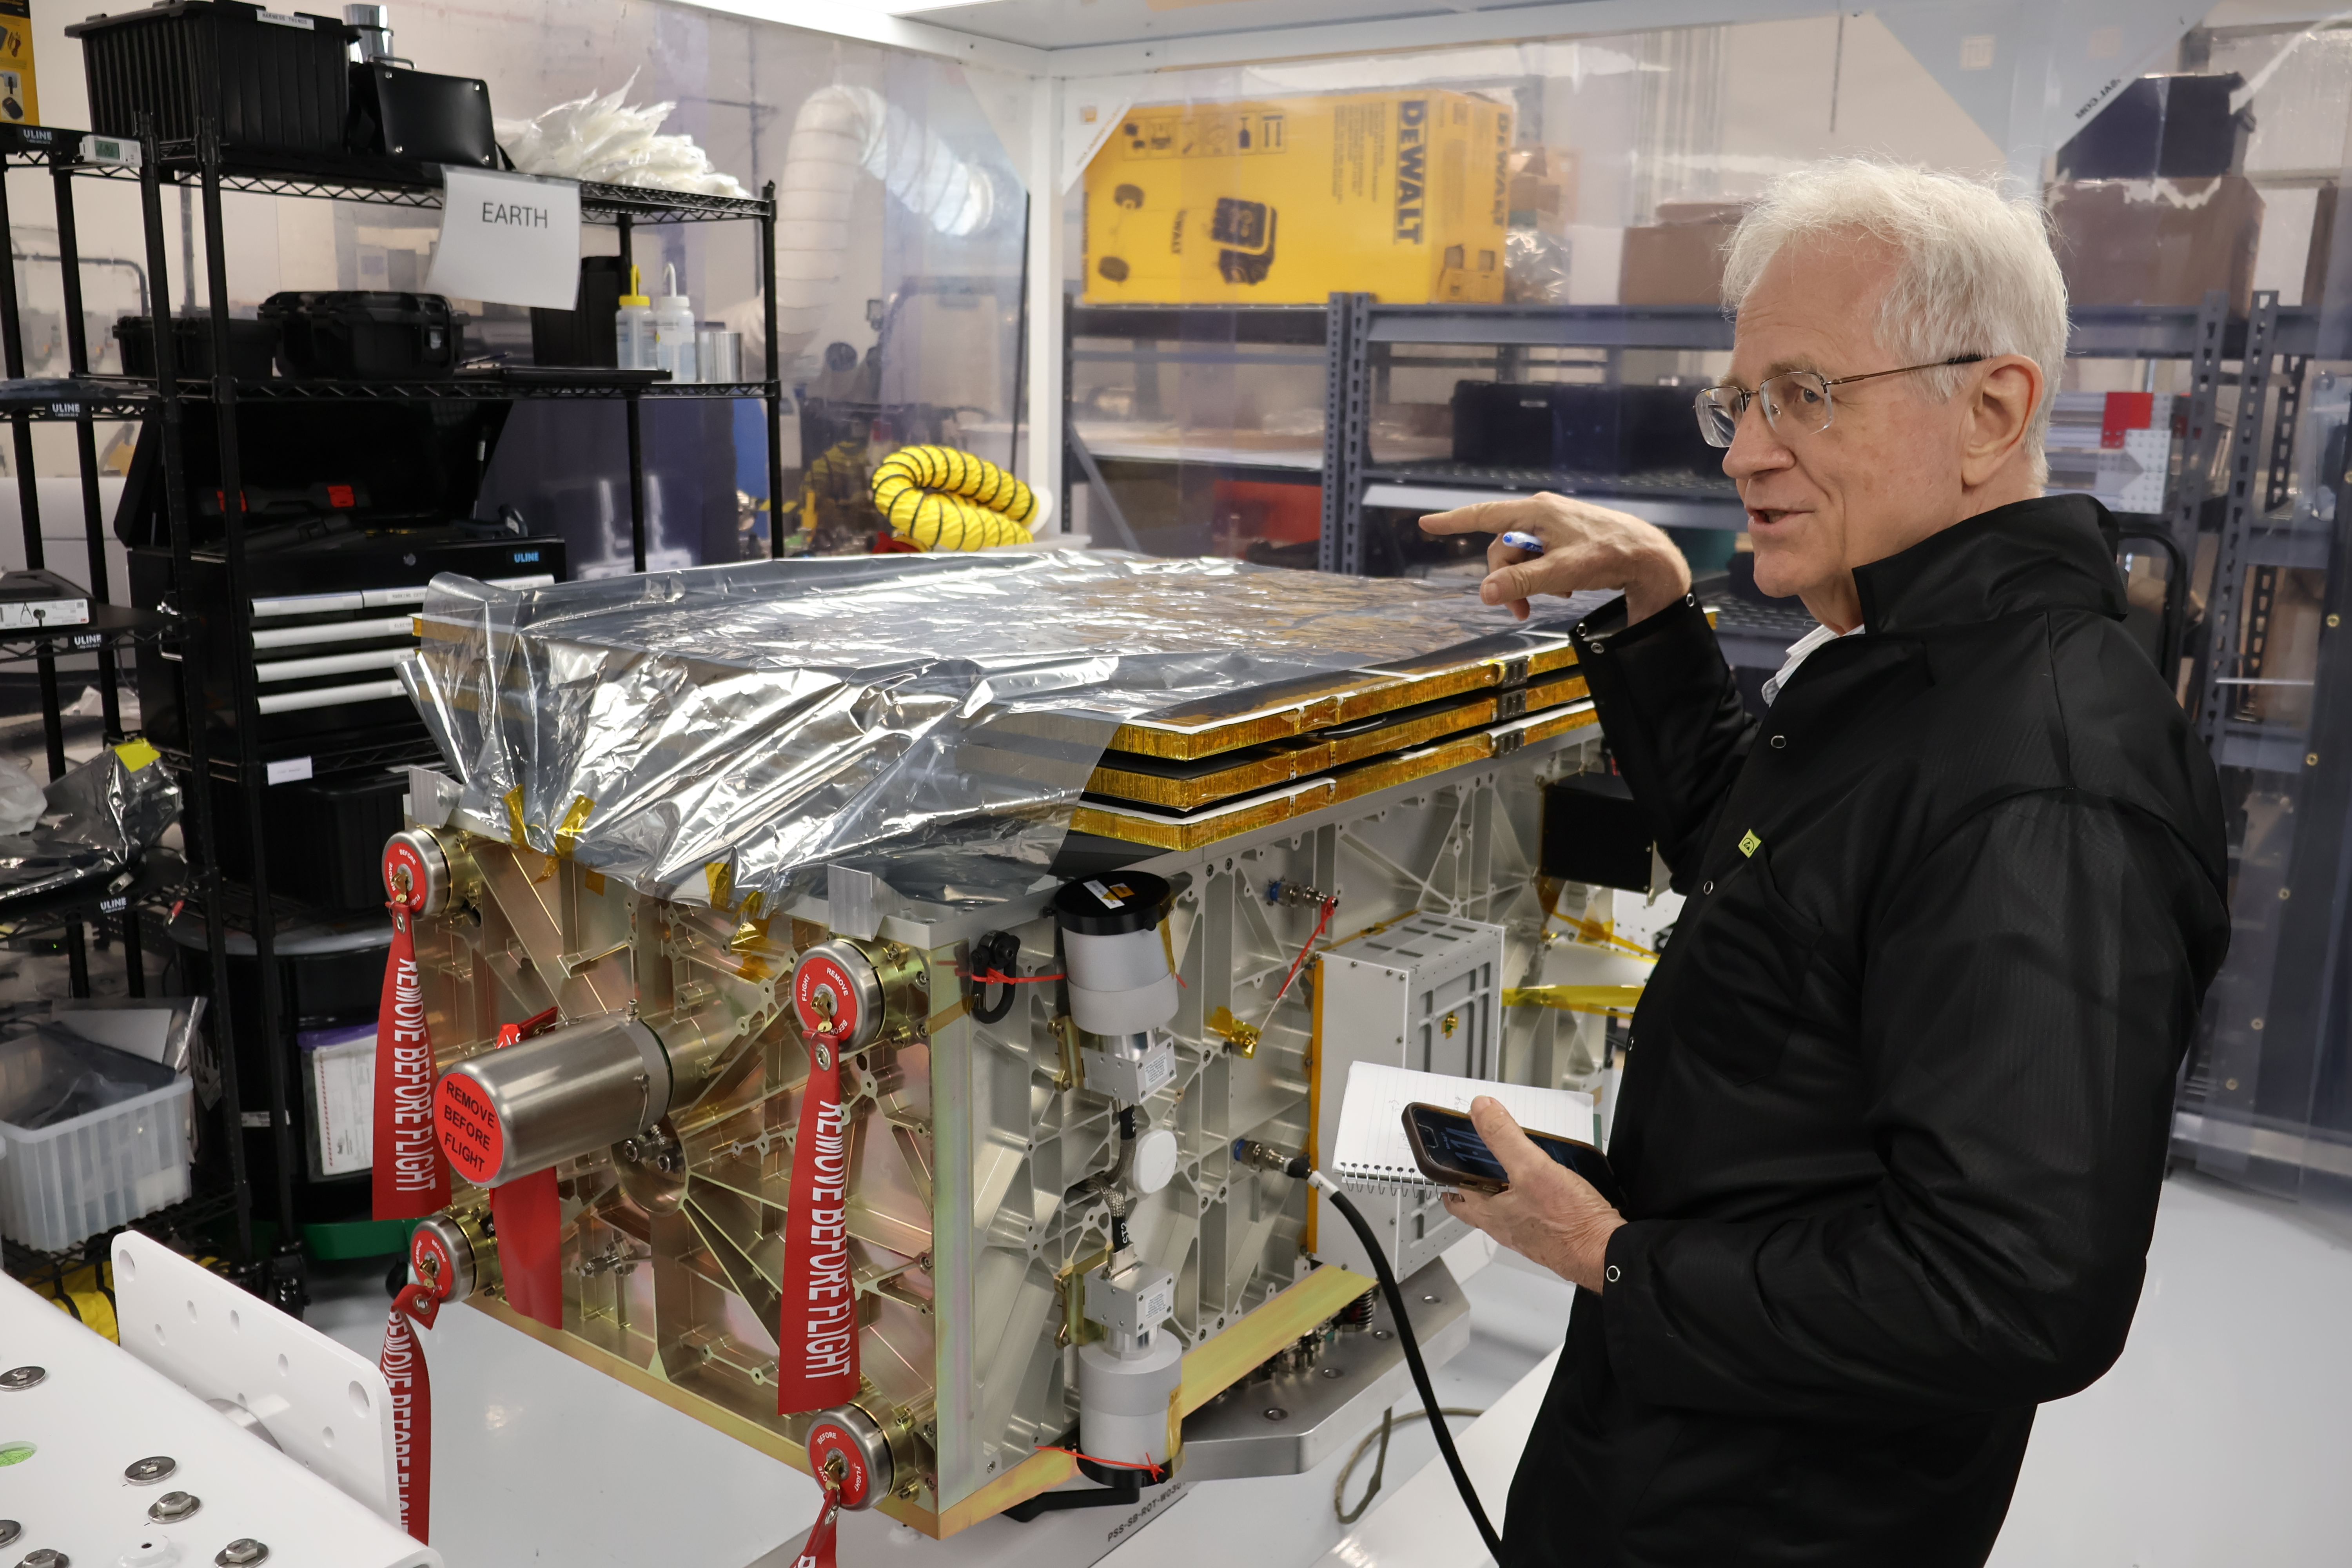
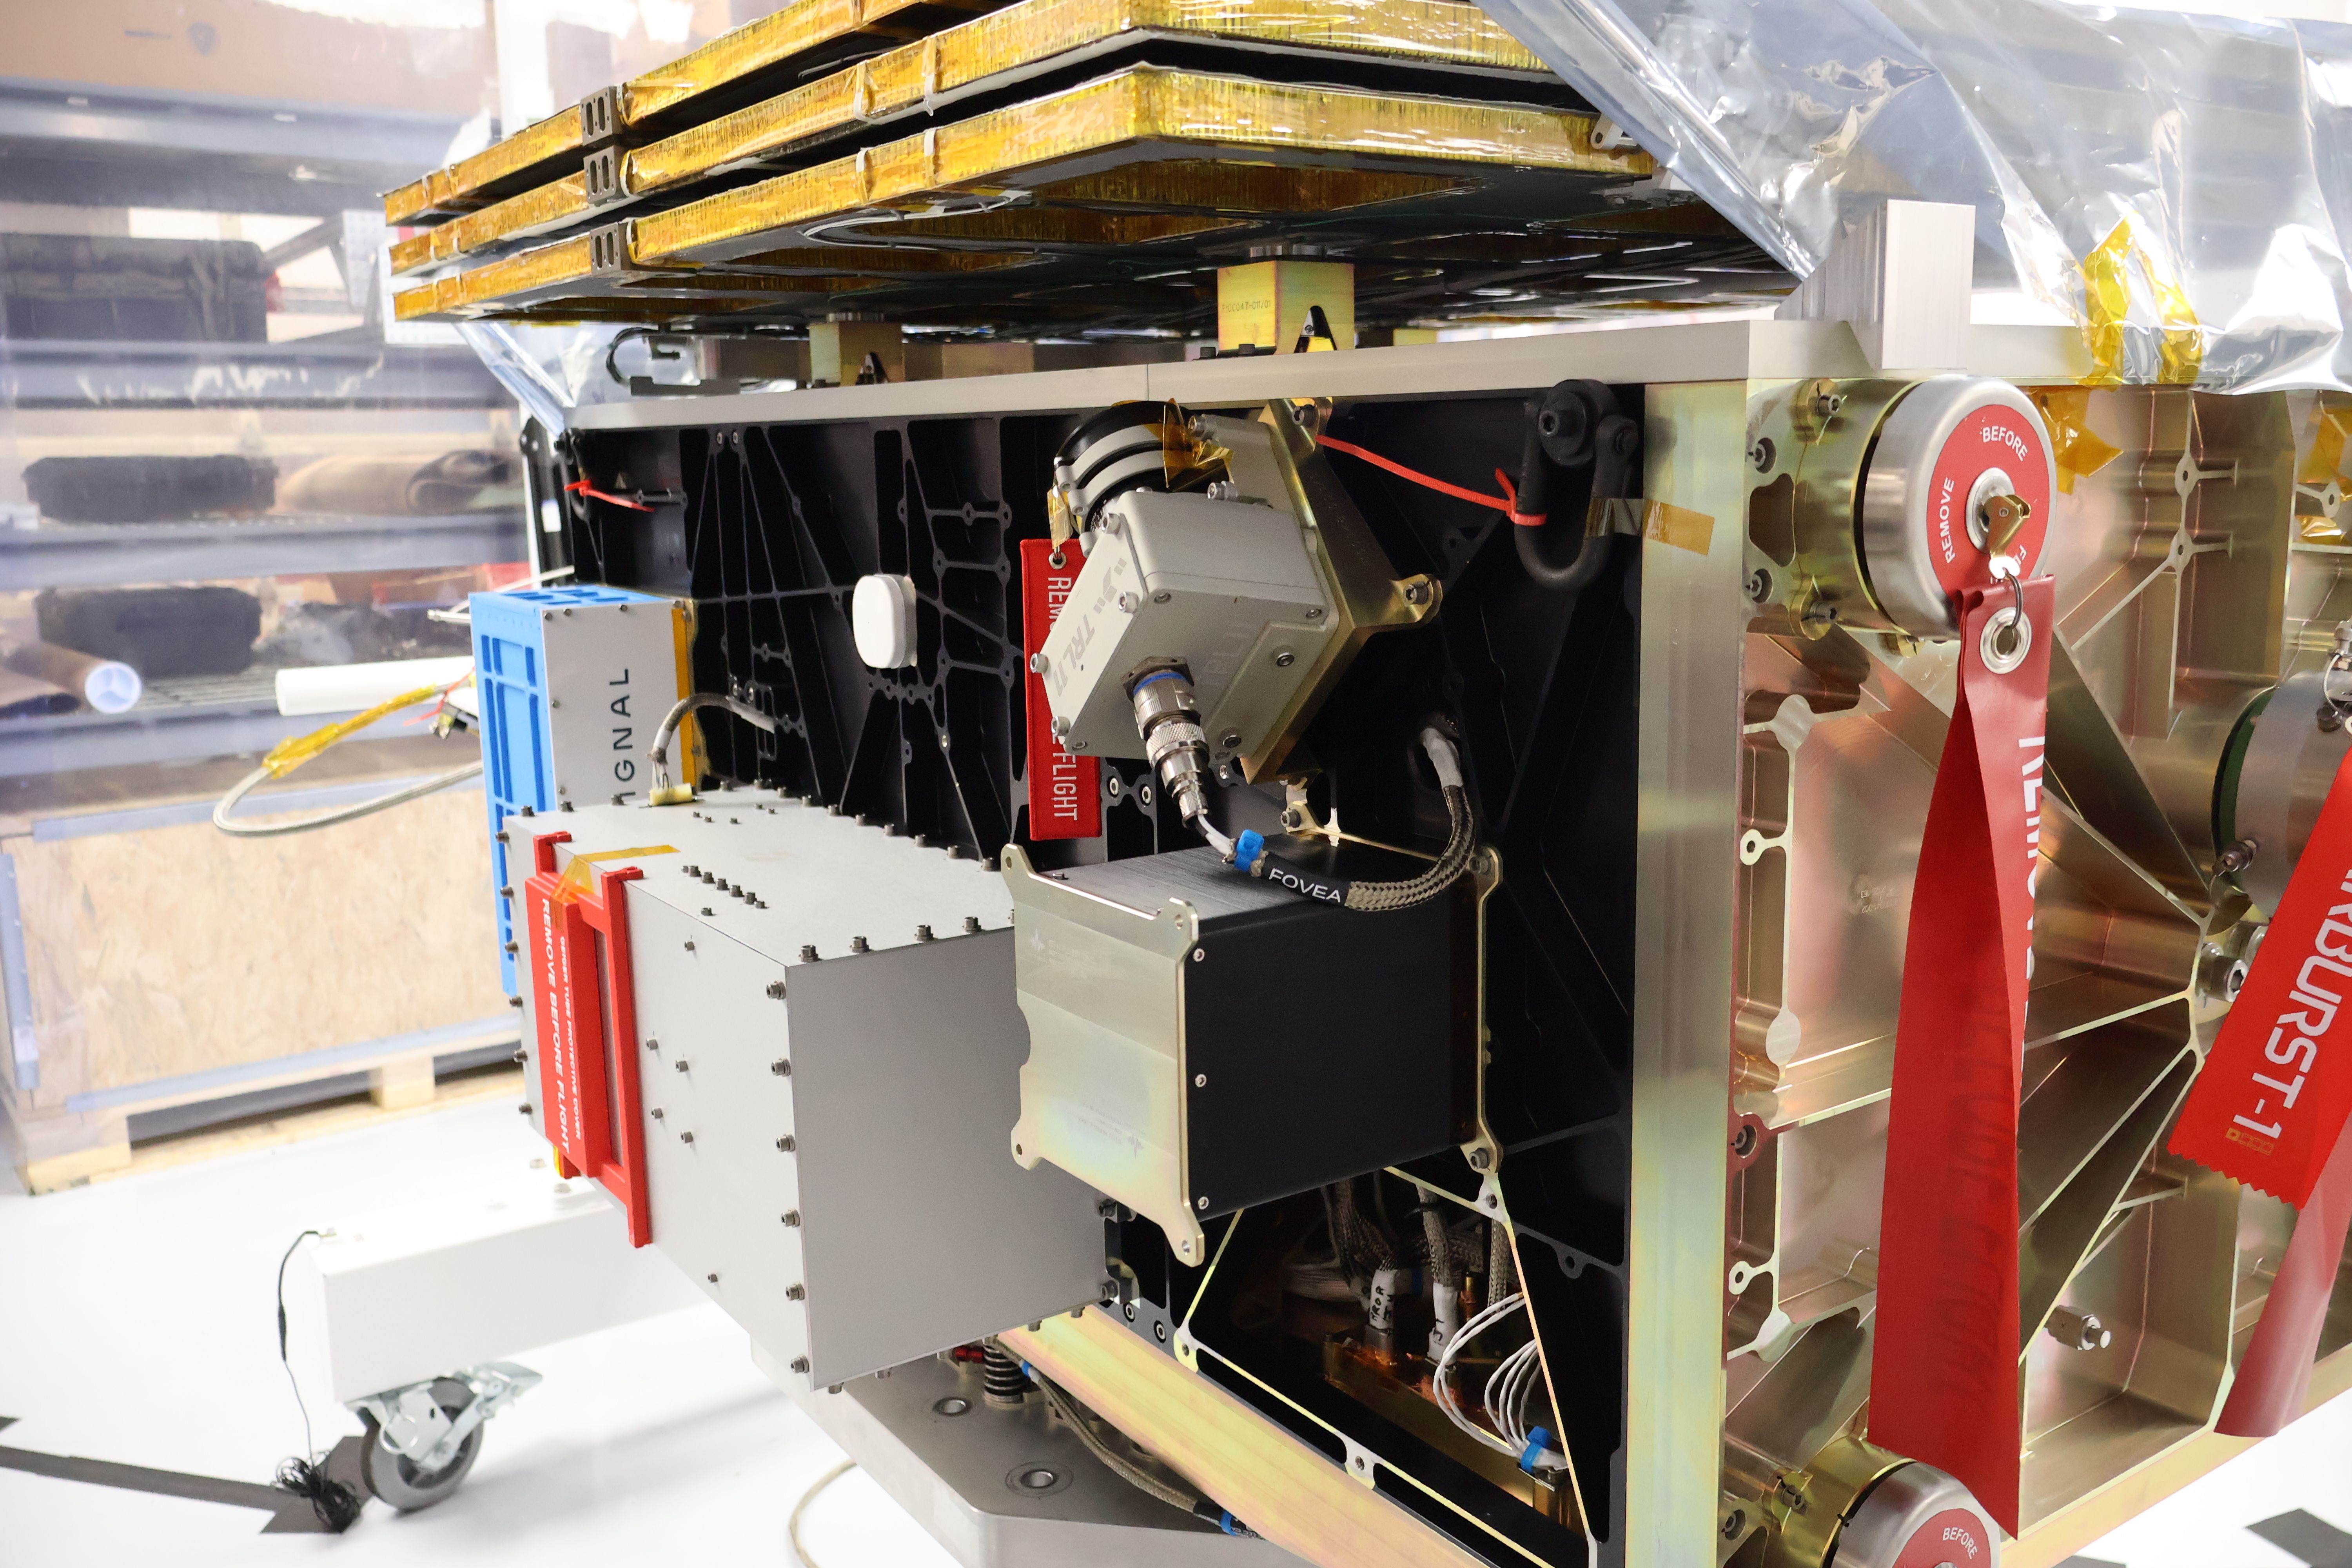
Starburst-1 takes center stage in the lab’s clean-room enclosure. The satellite’s solar arrays are stacked on top, and several contraptions stick out from the sides. The hardware includes Starburst-1’s star trackers and communications equipment. A full-motion video system, provided by TRL11, will monitor the spacecraft and its orbital surroundings.
Here’s a slideshow featuring Portal’s lab and Starburst-1:
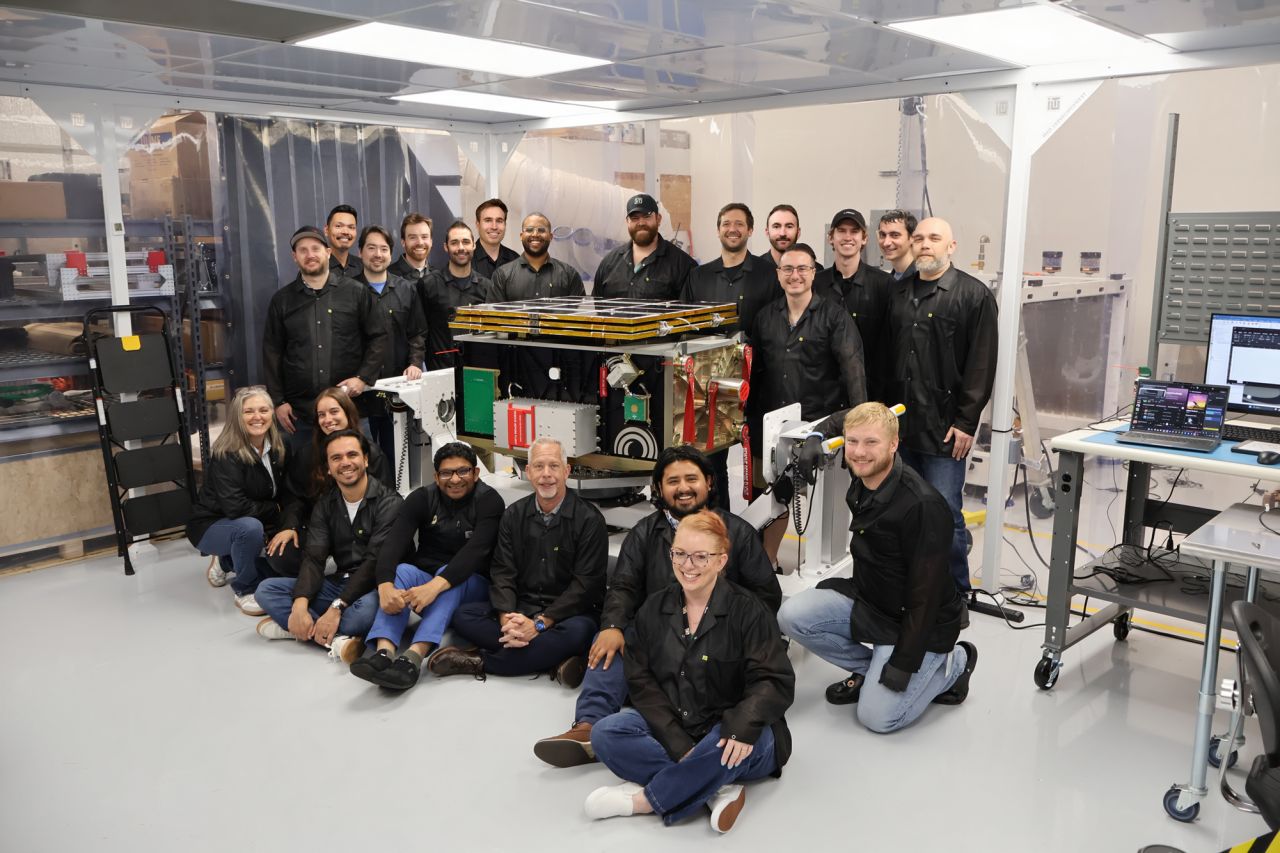
Members of Portal’s Bothell team gather around Starburst-1. (Portal Space System Photo)
GeekWire’s Alan Boyle gets a close look at Starburst-1. (Portal Space System Photo)
TRL11’s video system and Zenno’s superconducting magnet are attached to Starburst-1.
Starburst-1 will travel in this shipping container. (Portal Space Systems Photo)
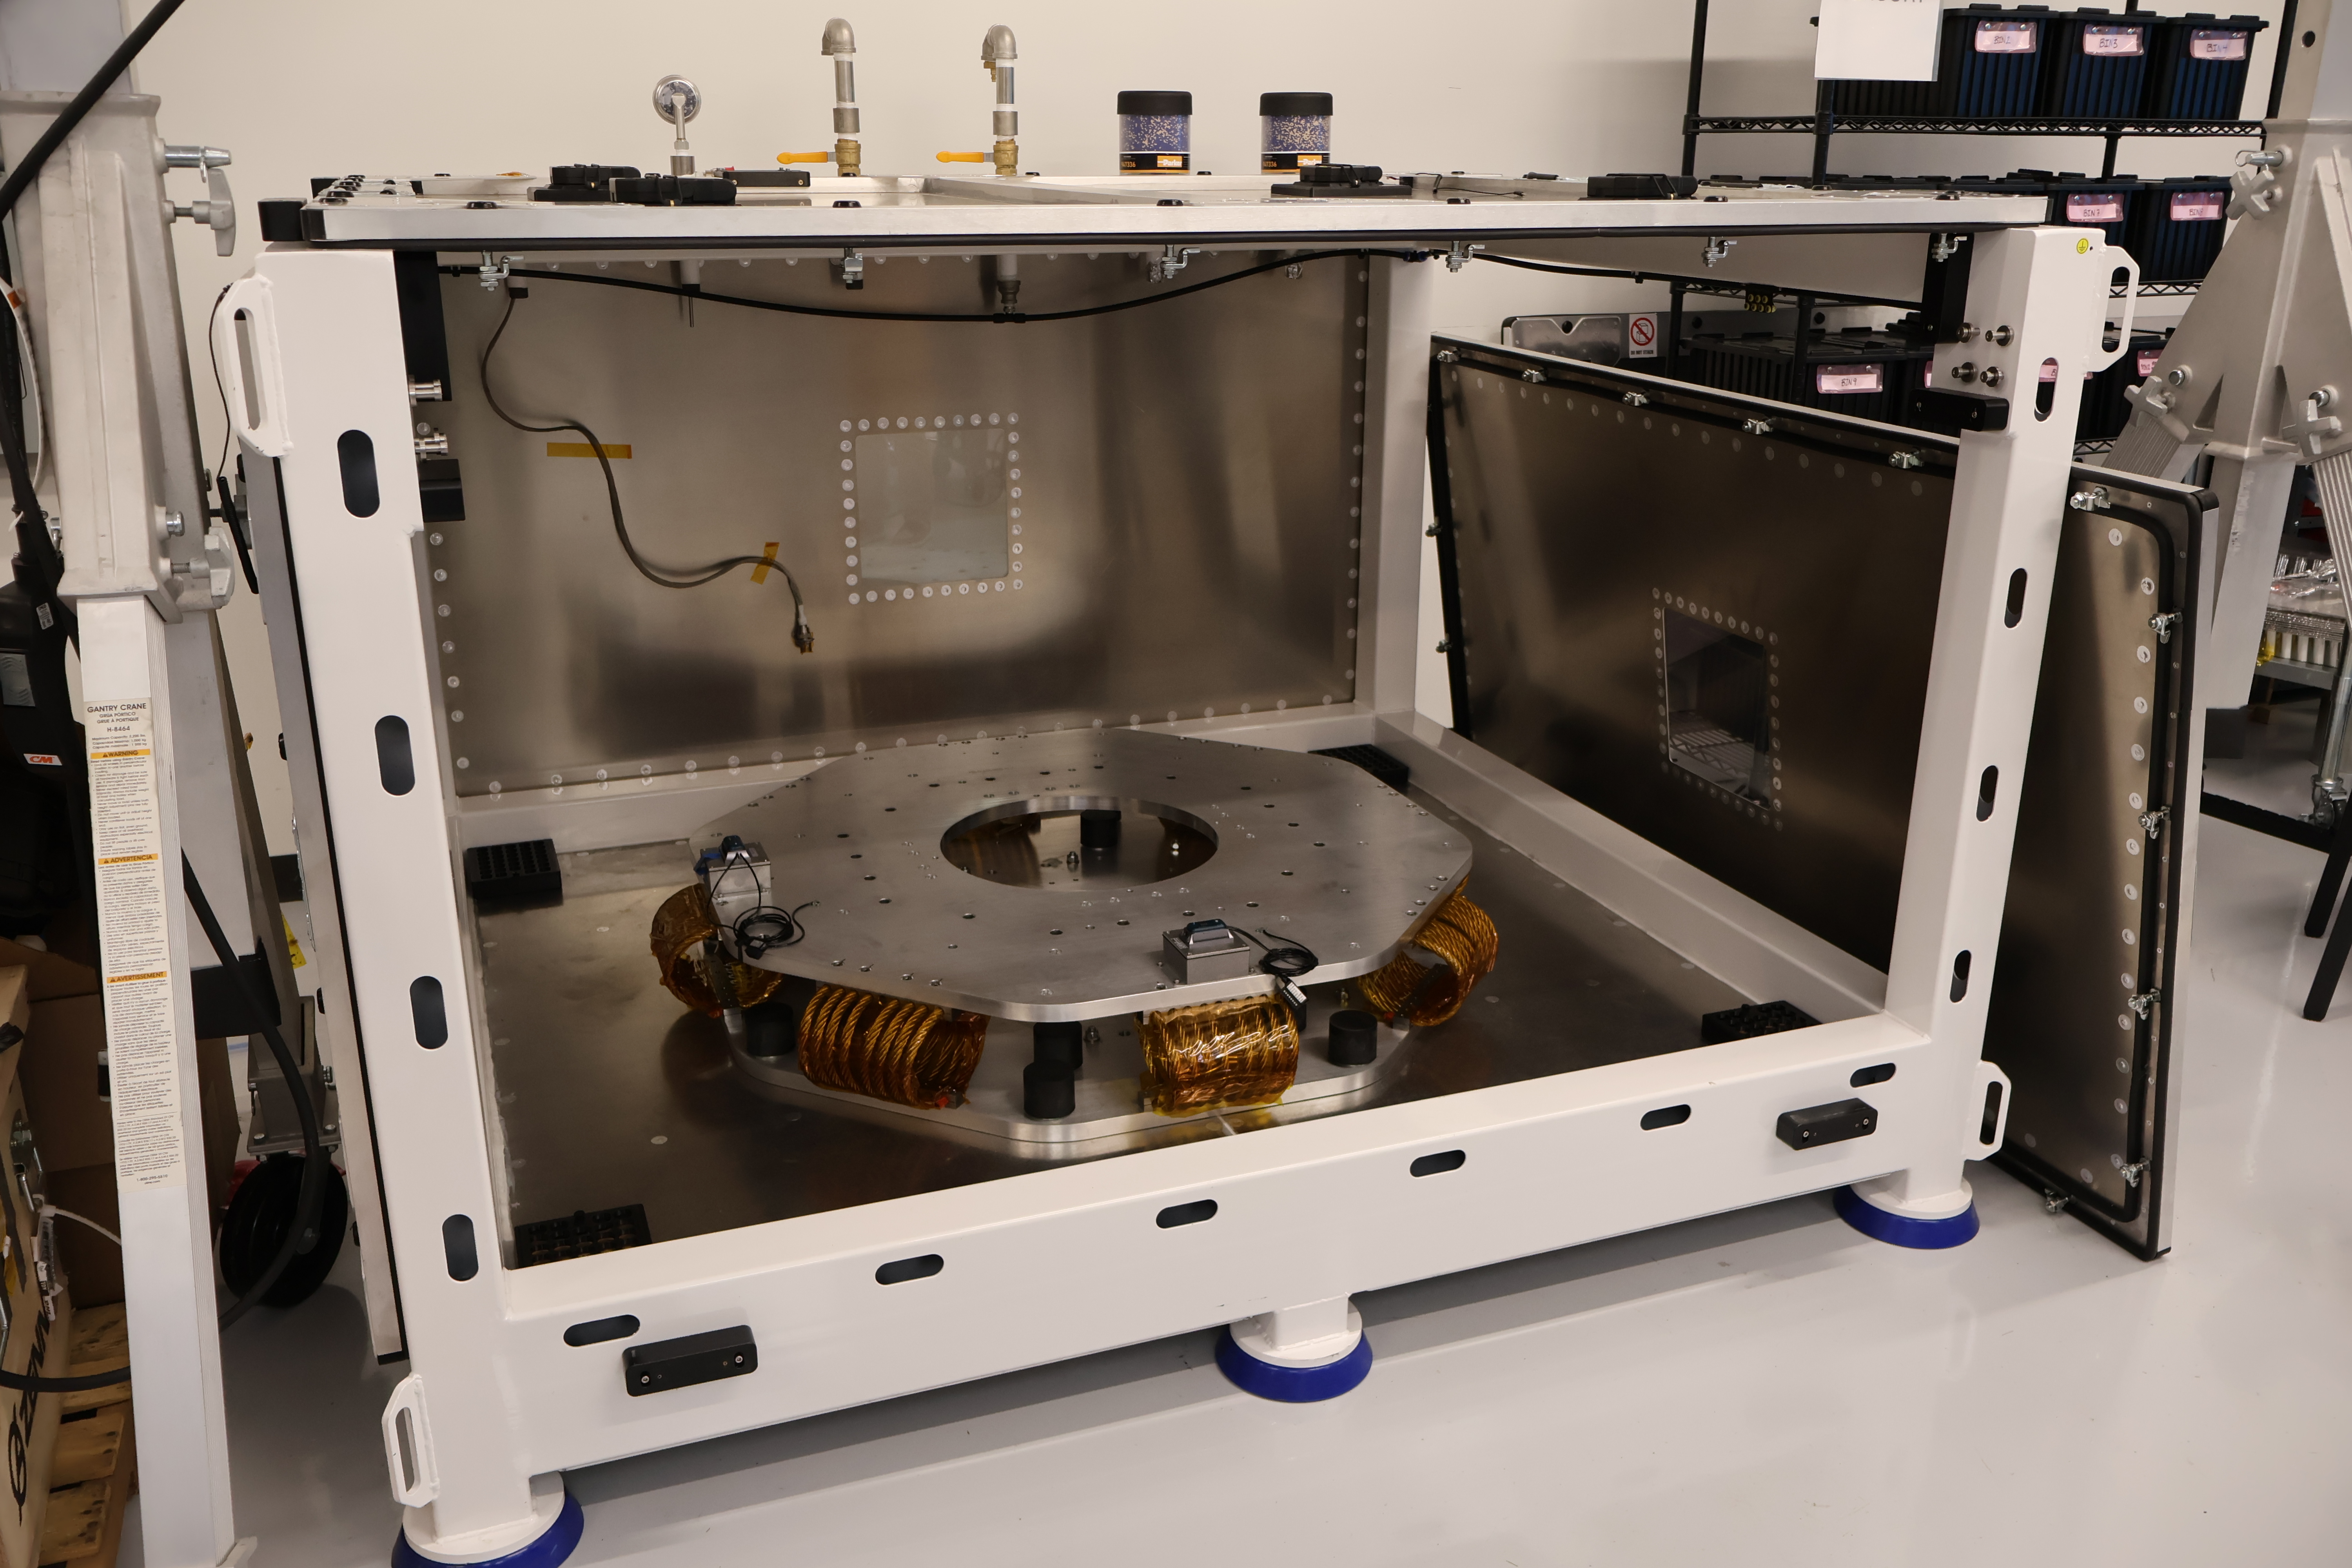
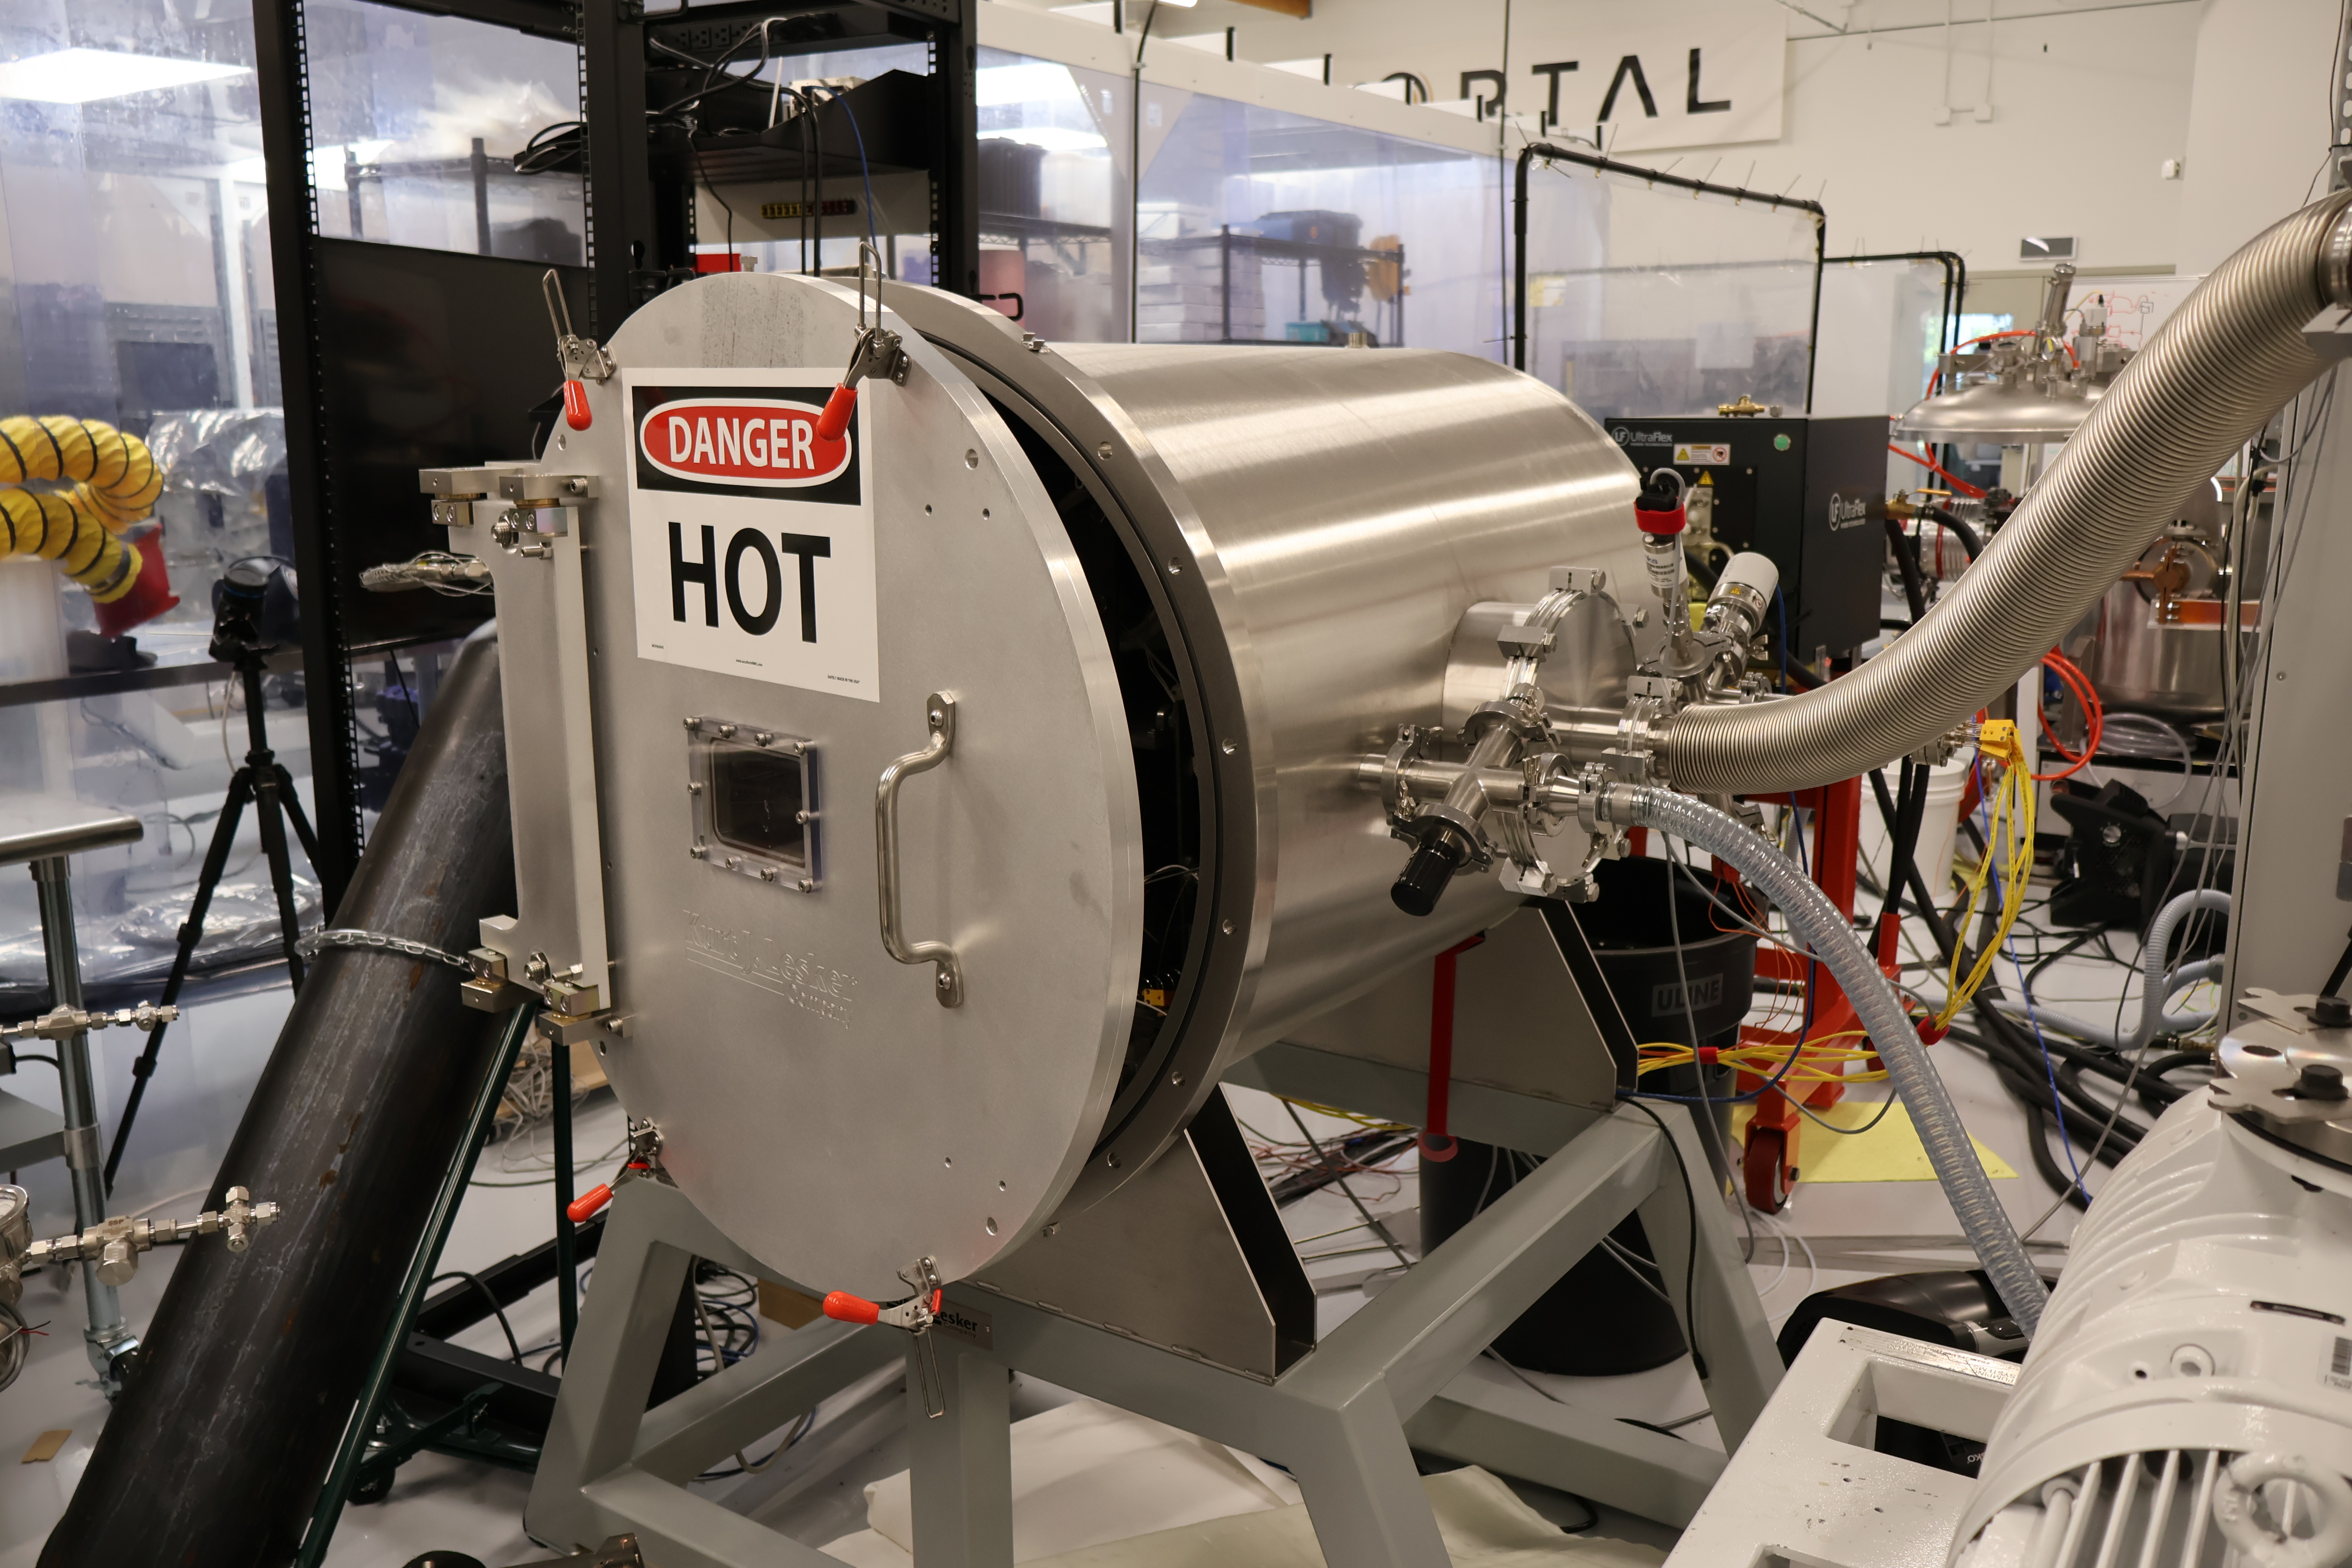
Hardware is tested inside this vacuum chamber. (Portal Space Systems Photo)
“It’s the Star Trek shields coming to life on the spacecraft,” Thornburg said. “That’s probably the use case I’m most excited about.”
Thornburg emphasized that testing the video system and the magnet are secondary mission objectives. The primary objective is to validate Starburst-1’s engineering design over the course of a year or more.
“Everything after a year becomes residual capability,” he said. “If all is healthy, then we’ll basically go into a stable orbit, and then we’ll re-engage this with other Portal spacecraft in the future to practice rendezvous proximity operations, and practice everything we need to refuel these spacecraft.”
By this time next year, Portal’s satellite manufacturing operation will have made the transition over to a much bigger facility in Bothell. “We have 65,000 square feet we’re moving into, just down the road about three miles, and it’ll have the capacity to produce 12 Supernova and 16 Starburst spacecraft a year,” Thornburg said.
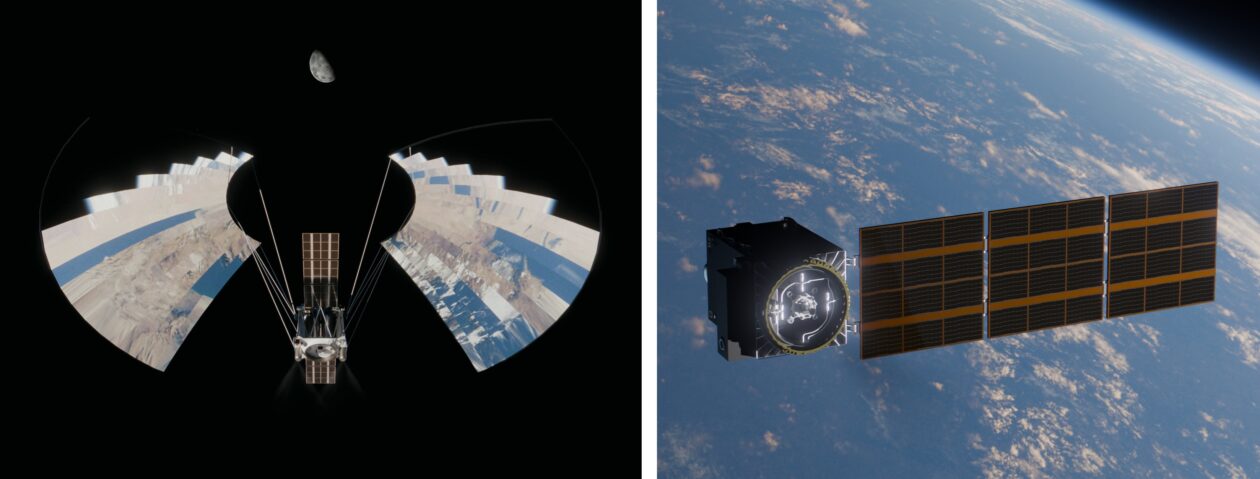
Portal Space Systems is working on two types of highly maneuverable orbital vehicles: Supernova, which uses large mirrors to concentrate sunlight on a heat exchanger / thruster system (at left); and Starburst (at right), a smaller spacecraft that leverages many of the technologies developed for Supernova. (Portal Space Systems Illustrations)
Supernova: Putting the plans in place
Supernova will be the flagship of Portal’s highly maneuverable space fleet. It’s designed to serve as an orbital platform for payloads that have to shift to different orbits in hours or days rather than weeks or months.
Today Portal announced that its first Supernova space vehicle will be launched in 2028 on a SpaceX Falcon 9 rocket. California-based Maverick Space Systems, which did the vibration testing for Starburst-1, will handle payload accommodation, integration and manifest optimization. Extra capacity on the Falcon 9 will be offered for third-party rideshare payloads.
“We’re designing an optimized payload stack for Portal, and bringing additional rideshare payloads to the mission, helping reduce launch costs for all mission partners,” Vidur Kaushish, Maverick’s chief operating officer and co-founder, said in a news release. “This new rideshare model is precisely what the industry needs. Portal’s ability to maneuver on orbit gives us the flexibility to select orbits that are truly valuable to rideshare customers.”
The key to Supernova’s rapid maneuverability is its solar thermal propulsion system, known as Flare. The system concentrates sunlight to heat up ammonia propellant in a heat exchanger, producing high-efficiency thrust without chemical combustion. Starburst also uses heated ammonia as a propellant, but in a more traditional electrothermal thruster system.
Supernova will be equipped with a battery to store heat when the spacecraft is in Earth’s shadow. “The thermal battery is a material that lives inside our heat exchanger, and it heats up and retains the heat for up to an hour,” Thornburg told me. “So, I don’t need to see the sun to be able to execute a maneuver.”
Supernova’s first mission will be called “Motus Via Sol,” meaning “Movement With the Sun.” And Portal Space Systems will be on the move as well.
“I think the timing will work out where all our future builds will be in our new facility,” Thornburg said. “I’d say in the next six to 12 months, we’ll probably have all of this capability in the new building, and then we’ll vacate this facility. But I’m not rushing engineering, because I don’t need to.”
Thornburg said it was only recently that he realized the full significance of that transition, and what it will mean for “our little mini-facility that did what it needed to do.”
“I was seeing the end of this building,” he said, “and the beginning of the next one.”

 Login