Philadelphia-based Raptor Defense Company is advancing in two U.S. Army programs with PIT VIPER, a small modular wheeled unmanned ground vehicle the company calls a “Personal Combat Vehicle” and designs to be fielded at the level of the individual soldier, the company announced. Raptor was selected for Phase II of GroundBreaker 1, a joint unmanned […]
Arc stops working on Mac and Windows Dec. 22, 2026. Learn how to export tabs, transfer your data, and prepare for changes to Arc Search on mobile devices.
Arc stops working on Mac and Windows Dec. 22, 2026. Learn how to export tabs, transfer your data, and prepare for changes to Arc Search on mobile devices.
The Browser Company has announced that the beloved web browser will ride into the sunset on December 2022, but will continue development of Dia browser.
Robinhood has taken a clear step into corporate Bitcoin ownership. On October 7, 2026, Johann Kerbrat, the company’s Senior Vice President and General Manager of Crypto and International, disclosed that Robinhood has added $25 million worth of Bitcoin to its own corporate balance sheet—its first proprietary BTC holding.
Kerbrat framed the purchase as more than a financial allocation. Speaking in an interview at the Digital Asset Summit Asia, he described it as a deliberate signal of commitment: “We care deeply about bitcoin and the ecosystem around it. For us, it’s more aligning our company and our vision with the crypto community.” He was equally clear about scale, noting that Robinhood’s market capitalization sits around $100 billion and that “the $25 million worth of bitcoin is not going to change a lot of the current trajectory of the company.”
The company did not disclose an exact coin count. Using this week’s average price near $84,960, the outlay equates to approximately 294 BTC. Other estimates based on prices around $84,000 place it near 300 BTC. The precise figure is expected to appear in Robinhood’s next public filing.
Signal Over Size
For Bitcoin For Corporations, the absolute size is less important than the decision itself. Robinhood is a publicly traded fintech platform with massive retail reach. Moving from solely facilitating customer crypto trading to holding Bitcoin as a corporate treasury asset represents a meaningful shift in posture. It is the difference between offering the product and putting principal capital behind the thesis.
This is distinct from the much larger pool of digital assets Robinhood already holds in custody for customers—roughly 185,000 BTC (approximately $15.5 billion) plus other cryptocurrencies, totaling around $25 billion across multiple chains according to on-chain analysis. Those assets belong to users. The new $25 million position belongs to the company.
An Early, Directional Allocation
Kerbrat’s comments make clear this is an initial step rather than the launch of a large-scale treasury program akin to Strategy’s. The amount is modest relative to Robinhood’s cash position and market value—roughly half a percent of reported cash holdings in some analyses and a rounding error against a $100 billion valuation. Yet first allocations of this kind often serve as internal and external catalysts: they align incentives, educate boards and investors, and create optionality for future expansion.
In the broader corporate landscape, the purchase lands alongside continued accumulation by established Bitcoin treasury companies. Strategy, for example, acquired 334 BTC for approximately $28.7 million in early October at an average price near $85,839, bringing its total holdings higher. Robinhood’s outlay sits in a similar dollar neighborhood but marks an entry point rather than an addition to an already dominant position.
Why This Matters for Corporate Strategy
Corporate Bitcoin adoption continues to mature from niche experiment to recognized strategic tool. Companies are increasingly evaluating Bitcoin as a reserve asset, a hedge against monetary debasement, a long-duration store of value, and a market signal that can differentiate them with investors and stakeholders. Robinhood’s move fits this pattern: a high-profile operating company in the financial sector publicly affirming Bitcoin’s role on the balance sheet.
For other public and pre-IPO companies watching, the lesson is practical. Allocations do not need to be transformative on day one to be strategically valuable. Clear messaging, disciplined sizing relative to overall capital structure, and alignment with the firm’s broader vision can turn a modest purchase into a credible signal. The next questions for Robinhood—and for peers considering similar steps—will center on governance frameworks, custody arrangements, accounting treatment, investor relations positioning, and whether this initial holding evolves into a more systematic treasury strategy.
Robinhood’s decision adds another data point to the growing list of public companies treating Bitcoin as a corporate asset. At Bitcoin For Corporations, we view every such step—large or small—as progress toward normalizing Bitcoin on balance sheets with clarity, confidence, and capital efficiency.
Disclaimer: This content was prepared on behalf of Bitcoin For Corporations for informational purposes only. It reflects the author’s own analysis and opinion and should not be relied upon as investment advice. Nothing in this article constitutes an offer, invitation, or solicitation to purchase, sell, or subscribe for any security or financial product.
— Silvia Candianihas been named corporate vice president of Worldwide Telco & Media within the Microsoft Frontier Company, a $2.5 billion initiative launched by the tech giant in July to embed engineers inside customers to build and run AI systems. In her new role, Candiani will lead Microsoft Frontier Company’s work with some of the largest telecommunications operators and media conglomerates.
“The momentum across our industry is extraordinary, and I believe we are only at the beginning of what AI can make possible,” said Candiani, who is based in Milan.
Before joining Microsoft in 2010 as a general manager, Candiani was a marketing director for Vodafone in Italy for more than a decade.
Kevin Frey. (LinkedIn Photo)
— Kevin Frey has been appointed vice president and chief impact officer of Microsoft Elevate, the company’s philanthropic effort providing technology support, donations, sales and AI training for educational organizations and nonprofits. Frey joined from UNICEF, where he was the first CEO of Generation Unlimited, the organization’s skills and employment initiative.
Frey said he was joining Microsoft because it’s “one of the only organizations in the world with the scale, scope and influence to bend the arc of the AI-powered future we are entering.”
“I will be spending my time and energy trying to ensure that the benefits of AI are shared broadly and safely across society — by every teacher, every student and every worker — regardless of their postal code,” he added.
— And while we’re on Microsoft, Anne Linge has been promoted to director of communications for commercial and consumer experiences after nearly 10 years with the company. She previously worked in communications at Weber Shandwick and Waggener Edstrom Worldwide, which has since rebranded as We.
Alexis Bateman. (LinkedIn Photo)
— Alexis Bateman has been promoted to director of global sustainability at Amazon Web Services after more than five years with the company. She was director of the MIT Center for Transportation & Logistics for 14 years before coming to Amazon.
Her work with AWS has given her the chance to help “shape sustainability at enormous scale,” Bateman said. “AI and cloud are transforming technology and society at an unprecedented pace, creating both enormous challenges and incredible opportunities for sustainability.”
Lynn Girotto. (LinkedIn Photo)
— Gradial has appointed Lynn Girottoas chief marketing officer. In June, the Seattle startup announced $65 million in new funding for its agentic AI platform that automates enterprise marketing. The company is No. 127 on the GeekWire 200, a ranked index of the Pacific Northwest’s top startups.
Girotto joins from Qualtrics, where she was CMO for two years. She has previously led marketing teams at companies including Vimeo, Tableau and Getty Images, and was a senior director at Microsoft for nine years earlier in her career.
“The best marketers I know want to build ideas and customer relationships, not manage processes,” Girotto said. “Gradial is the first company I’ve seen that’s built to give them that time back.”
Kam Ghaffarian. (LinkedIn Photo)
— A Seattle-area nonprofit group known as the Fermi Explorer Mission announced that Kam Ghaffarian has joined as co-founder. Earlier this month, the organization shared its plans to send a spacecraft on an 80,000-year trip to the nearest alien star system, Alpha Centauri.
Ghaffarian is a billionaire who helped launch companies including X-energy, Axiom and Intuitive Machines. “By committing to launching a spacecraft to Alpha Centauri by 2029, we are not just pushing the boundaries of current technology; we are inspiring a new generation to look up and dream of interstellar exploration,” Ghaffarian said.
Philip Johnston, co-founder and CEO of the Fermi Explorer Mission, also leads Redmond, Wash.-based Starcloud, a startup aiming to launch up to 88,000 satellites to serve as AI data centers.
Rachel Cougan. (LinkedIn Photo)
— Yoodli, the Seattle-based AI roleplay platform for enterprise training, has named Rachel Couganvice president of human resources. Cougan previously served as a fractional HR leader through her consultancy, Possible HR. Before that, she was VP of people for Logixboard and Hiya, and also served as VP of talent for Textio.
Yoodli, which launched in 2021, has grown to more than 100 employees. The company is No. 17 on the GeekWire 200.
Daniel Finney. (LinkedIn Photo)
— Kestra Medical Technologies has promoted Daniel Finney to vice president of research and development. The Kirkland, Wash.-based company sells cardiac monitoring and therapeutic devices. It raised $202 million in its IPO in March 2025 and was nominated for Deal of the Year at this year’s GeekWire Awards.
Finney has been with Kestra since 2019. CEO Brian Webster praised his role in developing the company’s FDA-approved monitoring device, adding that his “technical depth, product experience, and demonstrated leadership positions him to guide our next phase of innovation.”
Finney succeeds Phillip Foshee, Jr., who recently retired after leading Kestra’s R&D organization for nearly a decade.
— PATH has named Dr. Jeremy Farrar chief of its Asia, Middle East and Europe regional division. Farrar, a globally recognized leader in public health and clinical medicine, will join PATH effective Oct. 1 and be based in Geneva. His past roles include assistant director-general at the World Health Organization and director of the Wellcome Trust.
PATH CEO Nikolaj Gilbert praised the appointment, and noted that Farrar “possesses deep knowledge of the realities that prevent access, the people that make health care possible, and the need for PATH’s mission of ensuring breakthrough innovations reach all who need them.”
Emily Levesque. (AAS Photo)
— American Astronomical Society (AAS) announced that University of Washington scientist Emily Levesque is the next editor in chief of the AAS journals. She will succeed Ethan Vishniac, who is stepping down from the role at the end of summer 2027 after 12 years.
“In the writing and publishing landscape we’re facing today, sharing information has never been easier, but trusting information has never been harder — which makes the AAS journals’ combination of rigorous peer review and accessible science more valuable than ever,” Levesque said.
Levesque has been an assistant astronomy professor at the UW for 11 years. She leads the massive stars research group, which studies the evolution and death of the largest and “most extreme” stars in the universe.
— The Seattle Metropolitan Chamber has added eight members to its board of trustees:
Deniz Anders, Nordstrom’s executive vice president and chief marketing officer
Reuven Carlyle, founder of Earth Finance and former state senator
Carl Gipson, vice president of government and community affairs for Comcast
Trevor Gooby, executive vice president and chief operating officer for the Seattle Mariners
Daniel Huber, BNBuilders’ vice president of operations for the Northwest and Colorado
A joint Tenable-SentinelOne analysis of 93 CVE-actor attribution pairs reveals that both state-sponsored actors and cybercriminals independently converge on the same edge infrastructure.
It is the shared attack surface where state-sponsored threat actors and financially motivated criminal groups independently converge — not the province of a single adversary category, and not exclusively a nation-state problem, despite two years of headlines about China-nexus actors targeting Ivanti, Fortinet, and Palo Alto Networks. The data here tells a different and much broader story. One focused on vendors vs CVEs.
Key Takeaways
Two independent observation systems, Tenable exposure telemetry across thousands of customer containers and SentinelOne DFIR casework across 66 CVEs, converge 79% on the same vendor attack surfaces despite minimal CVE-level overlap.
Twelve CVEs in the combined dataset have confirmed multi-nexus attribution: state-sponsored and criminal actors independently exploiting the same vulnerability, across five nexus categories (China, Russia, DPRK, Iran, ransomware).
The exposure picture is flatter than the headlines suggest: Fortinet, the vendor most associated with edge-device attacks in the press, sits mid-pack on container-grain exposure (25%) — well behind F5 (54%) and in a tight 10-point band with Check Point, Ivanti, and Citrix.
54% of customer environments running F5 products have at least one exposed, actively-exploited CVE; Citrix customers show the slowest remediation patterns at 461 days median time to patch.
Remediation complexity, particularly of high priority CVEs, leads to a statistically significant 24-day remediation gap, leaving large windows of opportunity for attackers.
The same product lines get hit again and again: Ivanti EPMM and Ivanti Connect Secure each show a newly exploited CVE roughly every 8.5 to 13 months.
Leverage multiple defense-in-depth strategies: patch as quickly as possible, but also minimize the attack surface (feature-set minimization) and run endpoints in protect mode to better stop lateral movement from attacks that gain initial access.
The Convergence is the Story
Twelve CVEs in the combined dataset have confirmed multi-nexus attribution: state-sponsored and criminal actors independently exploiting the same vulnerability, across five nexus categories. Four examples illustrate the pattern:
CVE
Product
Actors (Nexus)
Significance
CVE-2026-15409
SonicWall SMA1000
UTA0533 (unattributed) + INC Ransomware
Espionage-to-ransomware succession on an active zero-day
CVE-2023-42793
JetBrains TeamCity
APT29 (Russia) + Lazarus (DPRK)
Two state-sponsored actors from different nations on the same CVE
CVE-2024-3400
PAN-OS GlobalProtect
UTA0218 (China) + INC Ransomware
China-nexus zero-day reused by ransomware operators
CVE-2024-24919
Check Point Quantum
PurpleHaze (China) + Fox Kitten (Iran)
China and Iran independently exploiting the same gateway vulnerability
The remaining eight confirmed multi-nexus CVEs span Fortinet, Citrix, Cisco, and Ivanti product lines. State-sponsored actors and ransomware operators are not operating in separate vulnerability ecosystems. They share the same entry points into the same products. The breadth of the convergence, not any single actor’s activity, is the finding.
That pattern holds across the full combined analysis. Three conclusions emerge:
Vendor attack surfaces are the persistent exploitation target. The same eleven vendors (i.e., Fortinet, Citrix, Ivanti, Palo Alto Networks, Cisco, Juniper, VMware, Microsoft, Oracle, CrushFTP, and Meta’s React framework) appear in both observation systems at 79% convergence, and all seven edge-product vendors converge. Serial exploitation timing on Ivanti products shows the vulnerability-to-exploitation pipeline refreshing at 8.5 to 13-month intervals on the same product lines. This is structural, not episodic. Patching the current CVE does not remove the vendor attack surface from the threat landscape.
State-sponsored and ransomware actors converge structurally. Twelve CVEs with confirmed multi-nexus attribution span all five nexus categories and cross the state-criminal divide. Defending against one actor category on edge devices necessarily requires defending against all of them, because the attack surface is shared. An organization that patches only for nation-state TTPs leaves itself exposed to ransomware operators exploiting the same vulnerability, and vice versa.
High-priority CVEs take more time to remediate, not less. Across Tenable’s 238-CVE high-priority list, high-priority CVEs carry a median remediation time of 146 days, compared to 122 days for all other CVEs — a 24-day gap that is statistically significant. The edge-appliance-specific subset (52 CVEs) shows a consistent 8-day gap in the same direction, which was not statistically significant, but suggests the direction may hold for edge appliances too. External data corroborates the pattern: the 2026 Verizon Data Breach Investigations Report (DBIR) found that median patch time increased from 32 to 43 days year over year, even as exploitation overtook credential theft as the number one initial access vector, and the 2025 DBIR, which incorporated Tenable RSO’s remediation trend analysis across 17 edge-related CVEs, found that only 54% of edge device KEVs were fully remediated. The explanation is structural: edge devices are the network boundary, so patching a VPN gateway or firewall means downtime for every user behind it, and change management gates multiply. These devices also resist standard patching workflows because they do not run endpoint agents, often require firmware-level updates with manual validation, and frequently lack active support contracts. The result is that the devices most worth patching are operationally the hardest to patch — and as the high-priority queue grows (the 2026 DBIR reports 50% more critical vulnerabilities to patch than the prior year), everything on it waits longer.
Background
Edge and perimeter devices occupy a uniquely consequential position in enterprise architecture. VPN gateways, firewalls, remote access appliances, and application delivery controllers sit at the boundary between trusted and untrusted networks. They are very often the first component an attacker touches and, for many organizations, the last component that gets patched. When one of these devices is compromised, the attacker inherits its network position: inside the perimeter, with access to internal resources, often without triggering endpoint detection.
This analysis combines two independent datasets to demonstrate that convergence. Tenable contributes exposure telemetry from the Tenable One Exposure Management Platform, covering thousands of customer containers and measuring what edge infrastructure is deployed, what is vulnerable, and how long it remains unpatched. This dataset extends Tenable Research’s ongoing analysis of edge device exposure trends, including the remediation telemetry Tenable contributed to the 2025 and 2026 Verizon DBIR reports. SentinelOne contributes findings from its digital forensics and incident response (DFIR) practice, documenting which threat actors actually exploit which vulnerabilities, observed firsthand inside compromised environments. Neither dataset was built for this analysis; each was constructed independently for different operational purposes.
The finding that makes this analysis compelling is not about any single CVE or any single actor. It is the structural convergence: two independent observation systems, looking at the problem from opposite sides, arrive at the same conclusion about which vendor surfaces are under persistent, broad exploitation, and by whom. (For how each dataset was built and scored, see the Methodology appendix below.)
What’s Exposed: The Vulnerability Surface
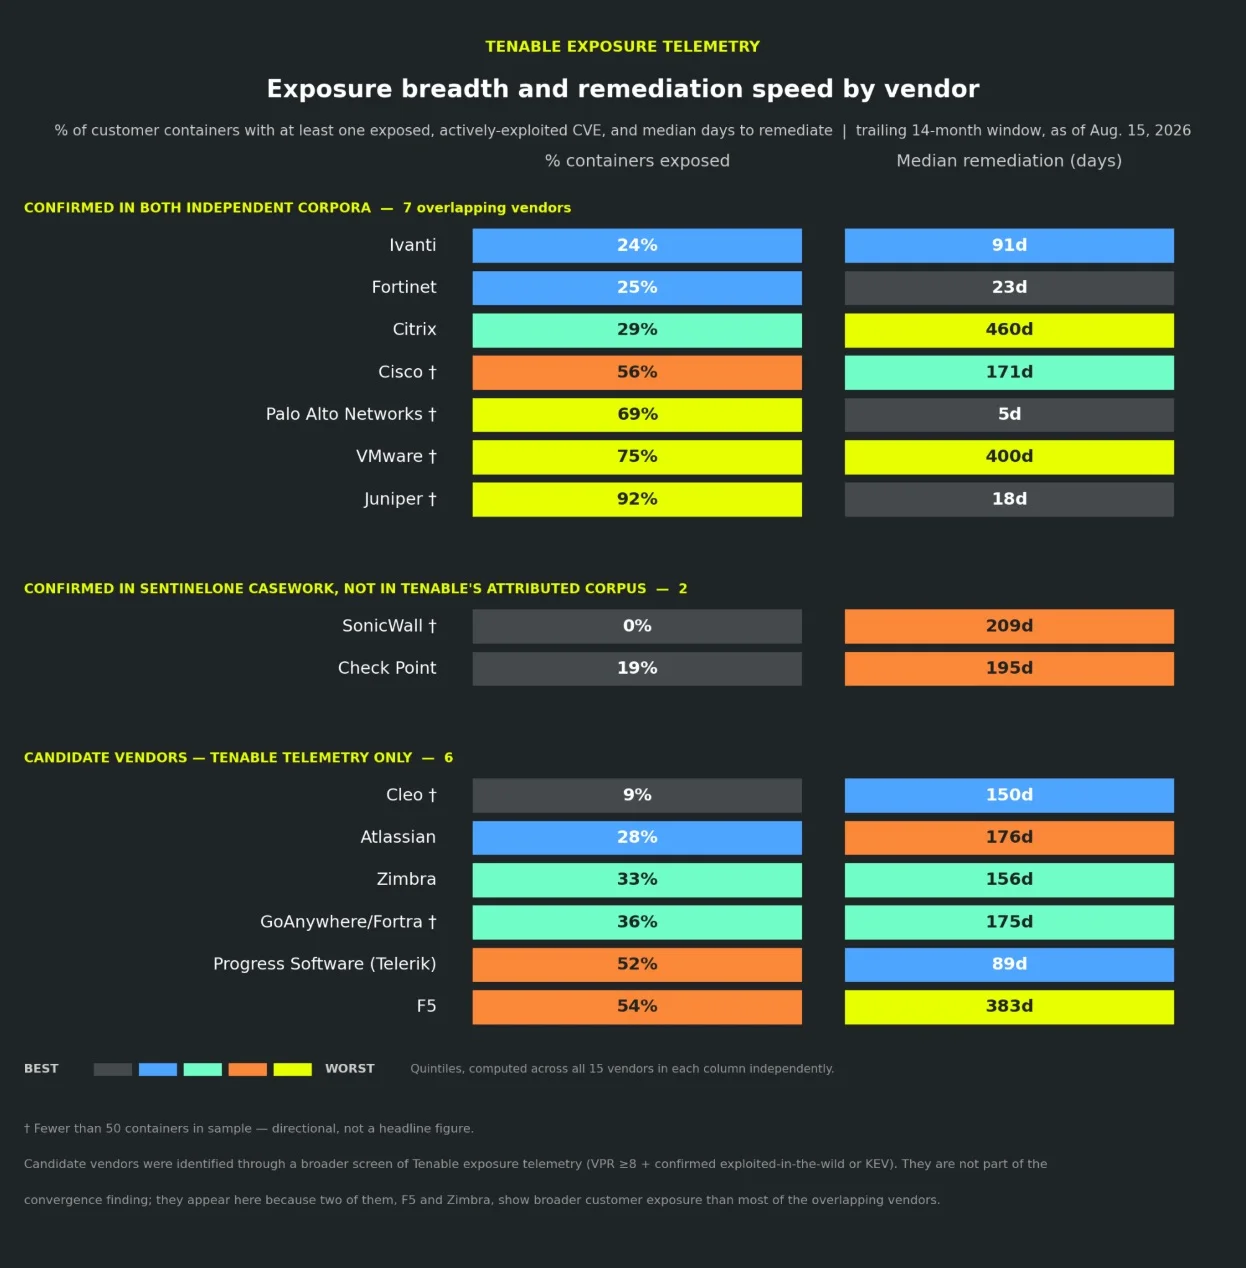
Tenable’s exposure telemetry provides the vulnerability-side view. All exposure metrics reported here use container-grain measurement: the percentage of customer environments (organizational containers) with at least one asset vulnerable to a given CVE as of Aug. 15, 2026, relative to total exposed containers over the preceding 14-month period. This measures breadth of organizational exposure to edge-product vendor vulnerabilities, not raw asset counts, across the sampling window.
This section covers 15 vendors in three groups: seven confirmed in both independently compiled corpora, two confirmed in SentinelOne’s casework but absent from Tenable’s attributed corpus, and six “candidate” vendors surfaced by a broader screen of Tenable telemetry. The candidates are not part of the convergence finding, but two, F5 and Zimbra, show broader customer exposure than most of the confirmed seven, so omitting them would understate the breadth of at-risk edge infrastructure.
FIGURE: Current vendor-level exposure heat map (container-grain, 15 vendors). Proportion of historically-exposed containers with at least one asset actively exposed to one or more relevant CVEs. Source: Tenable exposure telemetry.
F5 and Citrix lead for different reasons. Among vendors with statistically robust sample sizes, F5 customers are the most broadly exposed: 53.8% of 2,784 monitored customer environments running F5 products have at least one actively exploited CVE present. Citrix customers show the slowest remediation patterns: a median of 461 days to patch, with 71% of affected environments still carrying unpatched Citrix CVEs after a full year. F5 leads on scale of exposure; Citrix leads on persistent exposure.
The mid-pack is flatter than expected. Check Point (18.6%), Ivanti (24.1%), Fortinet (24.9%), and Citrix (28.8%) cluster within a 10-point band at container-grain. Fortinet, which dominates headlines, is mid-pack by this measure.
Thin-sample vendors show extreme rates but require caution. Juniper (91.7%), VMware (75.0%), Palo Alto Networks (69.2%), and Cisco (56.2%) all show container-exposure proportions above 50%, but each has fewer than 50 in-sample containers. These statistics are real directional signals, but should be considered within the context of the relatively low sample size.
Serial exploitation is structural. Two clean serial-exploitation sequences appear in the dataset: Ivanti EPMM (approximately 8.5 months between successive exploited CVEs) and Ivanti Connect Secure (approximately 13 months). Same product line, new vulnerability, repeat exploitation. Tenable Research has published advisories on both Ivanti exploitation sequences, tracking each CVE from initial disclosure through active exploitation, and the exposure data here extends that analysis with organizational remediation timelines not available at the time of the original advisories. The next one is coming.
Who Exploits What: The Threat Actor Landscape
This is not a targeted effort by a specific group. Edge infrastructure is a core focal point of attack across a broad range of threat actors and nexus categories. The combined Tenable-SentinelOne corpus documents exploitation by actors spanning five nexus categories: China, Russia, DPRK, Iran, and criminal (financially motivated). All five categories independently target the same vendor surfaces. Every attribution in the corpus is bucketed into one of three confidence tiers derived from a five-dimensional rubric evaluating attribution directness, evidence provenance, recency, exploitation role, and source corroboration. Confidence tiers, from high to low, are: DIRECT, TECHNIQUE-ALIGNED, or INFERRED.
Actor density scales with vendor exposure. Fortinet products face the broadest actor surface: 29 distinct threat actors across five nexus categories. Citrix follows with 22 actors across five categories, Ivanti with 19 across four, Palo Alto Networks with nine across three, and Check Point with six across two. Every focal vendor has confirmed exploitation from multiple nexus categories. No single vendor’s exposure is attributable to a single adversary group.
China-nexus actors are the highest-confidence case study, appearing across nine vendors in the corpus, with four DIRECT-tier attributions from the scored dataset alone. But the analytical value here is not that China targets edge devices. That is well established. The value is that China, Russia, DPRK, Iran, and ransomware operators all target the same edge devices, as the examples above illustrate. The governed attribution methodology is what allows this claim to be made with precision: we can distinguish confirmed multi-nexus convergence (DIRECT-tier evidence on both sides) from assessed convergence (INFERRED, requiring corroboration).
What Incident Response Sees That Telemetry Can’t
Exposure data shows which appliances are reachable, vulnerable, and unpatched. Incident response looks at what happened when attackers got in: what they accessed, what they took, and where they went next. In SentinelOne DFIR cases involving edge infrastructure, attackers used credentials stored on the appliances and the access those appliances already had to reach internal systems.
Credential Theft from Edge Appliances
Across three engagements, threat actors reached the management plane of FortiGate appliances and created rogue administrative accounts. In two, they also exported device configurations and extracted credentials that could be used to move further into the network. Two of these three are documented in detail in FortiGate Edge Intrusions.
In one of those two, the exported configuration contained LDAP bind credentials for a directory service account. The account was later used in the environment. A few hours later, the threat actor added two computers to the domain. Neither had a Service Principal Name, which is unusual for a legitimate domain join. The mS-DS-CreatorSID attribute on both accounts pointed back to the stolen service account.
We saw similar activity on an Ivanti Cloud Services Appliance in late 2024. A China-nexus actor chained CVE-2024-8963 with CVE-2024-8190 before the first public disclosure in the chain. After gaining access, the actor collected SSH keys and other stored credentials. That engagement is documented as Activity F in Follow the Smoke.
These appliances did not provide conventional endpoint telemetry. We had to follow the activity into authentication records, newly created Active Directory objects, and the later use of credentials taken from the appliances.
When the Initial Access Vector Cannot Be Confirmed
In December 2025, Fortinet disclosed CVE-2025-59718, an authentication bypass in its FortiCloud SSO integration affecting FortiOS and other products. Several weeks later, Fortinet disclosed CVE-2026-24858. This second flaw allowed an attacker with a FortiCloud account and a registered device to log into devices belonging to other customers when FortiCloud SSO was enabled.
That overlap mattered in one of the three engagements above. The appliance was running a version affected by both CVEs, but the available logs did not show when or how the attacker first gained access. The earliest retained malicious activity showed a rogue local administrator account. A few minutes later, a domain administrator authenticated from the appliance’s VPN address pool. Exposure data showed that the appliance had been vulnerable to both CVEs, but that alone did not establish how it was compromised. We treated both as possible, not confirmed, initial-access vectors.
Abuse of Trusted Management Access
In one SentinelOne DFIR engagement involving a FortiManager appliance, CVE-2024-47575 allowed an unauthorized device to register with the appliance through the management protocol. Two log entries, seconds apart, recorded the rogue registration and the settings change that followed. The threat actor then staged an archive of managed-device configurations that could expose credentials, addresses, and details about the network. The actor had been present for about a month before the customer detected the activity.
In a separate engagement, a threat actor chained SQL injection, pass-the-hash authentication, and authentication bypass against an internet-facing SonicWall GMS console (CVE-2023-34133, CVE-2023-34132, and CVE-2023-34124). The actor created administrative accounts on a platform operated by a managed service provider, then used existing shared access to enter multiple customer environments. Most of the resulting traffic was advertising-related, leading us to assess that the infrastructure was being used for click fraud.
The actors were after different things. One collected configuration data and information about the network. The other used the access to turn systems across several environments into proxies. In both cases, the actor inherited the access that the organization had already granted to the management platform. These cases show the difference between the two views: exposure telemetry finds the vulnerable device, while incident response shows what was taken from it and where the attacker went next.
What to Do About It
Patch F5 and Citrix edge devices immediately. These two vendors combine the highest exposure rates with the slowest remediation timelines across statistically robust samples. Look for strategies to reduce the remediation time, particularly for weaponized CVEs. Additionally, reduce the attack surface by minimizing the enabled feature set on these devices and aim for defense in depth by running endpoints in protect mode to limit lateral movement opportunities.
Audit Ivanti Connect Secure and EPMM deployments. Serial exploitation on observed 8.5 to 13-month cycles means the next exploitable CVE in these product lines is a question of timing, not probability. Organizations running Ivanti edge products should assume they will face a new actively exploited vulnerability within the next year and plan patching capacity accordingly.
Implement edge-device-specific patch SLAs. The delayed remediation paradox demonstrates that general priority frameworks do not translate into faster patching on the devices that sit at the network boundary. Edge devices and network infrastructure warrant dedicated remediation timelines that are shorter than the organizational default and commensurate with the elevated risk.
Treat edge device exposure as a cross-signal priority. Attribution, severity, and exposure volume identify different CVEs as “top priority.” Organizations need all three signals for complete coverage. A vulnerability management program that prioritizes exclusively by CVSS will systematically underweight CVEs with strong exploitation evidence but modest severity scores, and vice versa. The Tenable One Exposure Management Platform enables this cross-signal approach by combining vulnerability severity, exposure intelligence, asset context, and exposure data into a unified prioritization view.
Identifying Affected Systems
Tenable customers can use the Tenable Vulnerability Watch dashboard to monitor classifications for all CVEs discussed in this analysis. A list of Tenable plugins for the vulnerabilities discussed in this analysis can be found on the individual CVE pages at tenable.com/cve as they are released. This link displays all available plugins for each vulnerability, including upcoming plugins in our Plugins Pipeline.
How the corpus was built. Tenable’s 33-CVE corpus was derived by combining and deduplicating vulnerabilities with the highest exploitation volume and broadest actor adoption; SentinelOne validated CVEs across 14 vendors, and their 66-CVE landscape view reflects 12 months of DFIR casework with false positives removed. Combined, the two datasets identify 82 distinct CVEs, 17 of which appear in both. Layered on top of these sources is a governed attribution corpus of 93 CVE-actor pairs spanning approximately 39 named threat actors and five nexus categories.
Why Tenable tracks these CVEs. Tenable’s set comes out of exposure management. A CVE enters it through the Vulnerability Watch program, which classifies vulnerabilities under active or likely to be exploited, and is additionally scored with a Vulnerability Priority Rating (VPR). The question being answered is prescriptive: of everything actually deployed across customer environments, what should be prioritized and patched first? Threat-actor attribution is layered on afterward from definitive and confidence-scored sources (e.g., Federal cybersecurity advisories).
Why SentinelOne tracks these CVEs. SentinelOne’s set comes from the opposite direction: incident response. A CVE earns its place in their 12-month DFIR landscape because responders found it used in a real intrusion — the initial access vector in a case someone called them about. The question being answered is forensic: what happened here, and who did it? Coverage is shaped by who engaged them, not by install base.
What “overlap” means here. Overlap was measured at two levels, and the answer changes sharply depending on which level you use.
At the level of the individual vulnerability, the two sets barely intersect. Only 17 of 82, or 21%, of CVEs are common to both. Tenable and SentinelOne are, for the most part, not looking at the same vulnerabilities. However, the datasets converge at the product level. Eleven of the 14 vendors in Tenable’s focal CVE set appear in SentinelOne’s 12-month DFIR landscape – a 79% convergence: Fortinet, Citrix, Ivanti, Palo Alto Networks, Cisco, Juniper, VMware, Microsoft, Oracle, CrushFTP, and Meta’s React framework. That’s 79% convergence at the vendor level against 21% at the CVE level. Three vendors did not conform: Apache and SAP were absent from SentinelOne’s casework, and the one Progress case they worked on was closed as a false positive. Narrow the comparison to edge and remote-access infrastructure specifically, and the convergence is a perfect 100%. Tenable’s corpus independently identified seven edge vendors (i.e., Fortinet, Citrix, Ivanti, Palo Alto Networks, Cisco, Juniper, and VMware). All seven appear in SentinelOne’s casework. Two teams, working from unrelated evidence for unrelated purposes, arrived at the same seven vendors while sharing roughly one CVE in five.
Why the distinction matters. “Different vulnerabilities, same vendors” is not a weaker version of “same vulnerabilities.” It is a different and more actionable claim. Had both datasets converged on the same individual CVEs, the story would be that a specific handful of vulnerabilities is being widely exploited: patch those and the problem shrinks. What the data actually shows is that state-sponsored and criminal operators are independently arriving at the same small set of edge and remote-access product vendors, then finding their own separate ways in. The durable target is the vendor attack surface. Patching this quarter’s Ivanti CVE does not remove Ivanti from anyone’s target list.
All third-party product names, logos, and brands mentioned in this publication are the property of their respective owners and are for identification purposes only. Use of these names, logos, and brands does not imply affiliation, endorsement, sponsorship, or association with the third party.
The question has shifted. Security leaders spent several years debating whether AI would reshape security operations. That debate has settled. Now the conversation is about pace. How fast can the foundation be built, and what do organizations that moved early have to show for it?
For the second year, SentinelOne® commissioned 451 Research to survey 611 North American cybersecurity decision-makers and practitioners on the state of security operations strategy. The results confirm what we’ve been building toward, and they surface a finding that should recalibrate how most security leaders sequence their AI investments.
The Returns Didn’t Wait for the Roadmap
Many product roadmaps assume a clear sequence and start with building toward higher maturity first with returns following. The data shows that AI is running ahead of schedule.
Nearly all organizations surveyed (96%) are still operating AI at the earliest maturity levels:
Level 2: More senior triage analyst / basic incident responder and investigator
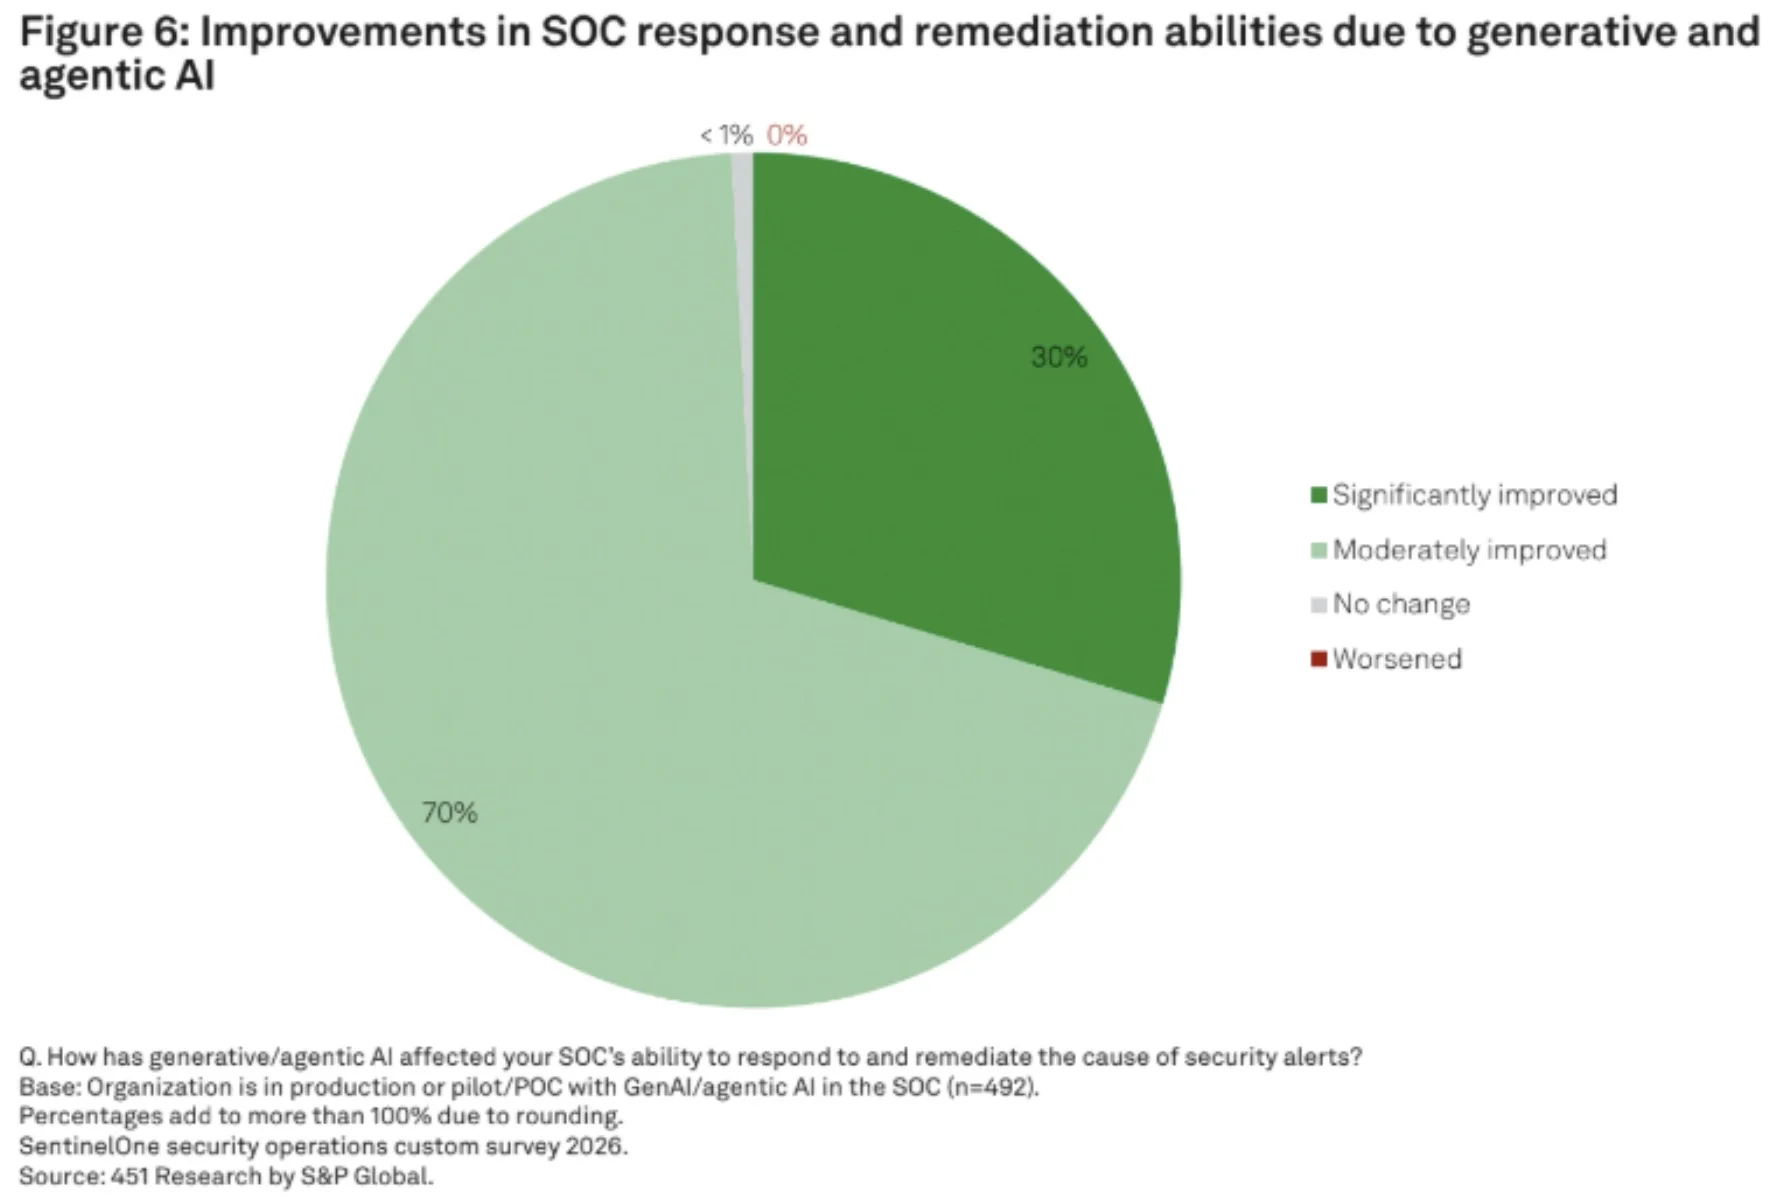
By most measures, AI adoption in the SOC is still early. And yet, 99% of those same organizations already report improvements in incident response and remediation.
The numbers are consistent. Early-stage AI (chatbots handling initial alert triage, automated tools sorting true positives from noise) is delivering before organizations reach advanced maturity. The gap between where most organizations are and what they are already getting is real and consistent across survey respondents.
Organizations waiting for higher AI maturity before building the supporting infrastructure are running the sequence backward. The returns are available now. The foundation built today determines how far those returns scale.
Platformization Has Reached A Verdict
The organizations accelerating AI adoption are also the ones consolidating onto platforms. A platform-oriented security architecture means moving from siloed, specialized tools to an integrated stack built on a foundation that coordinated AI decision-making can actually run on, and one that lets each new capability compound on the last.
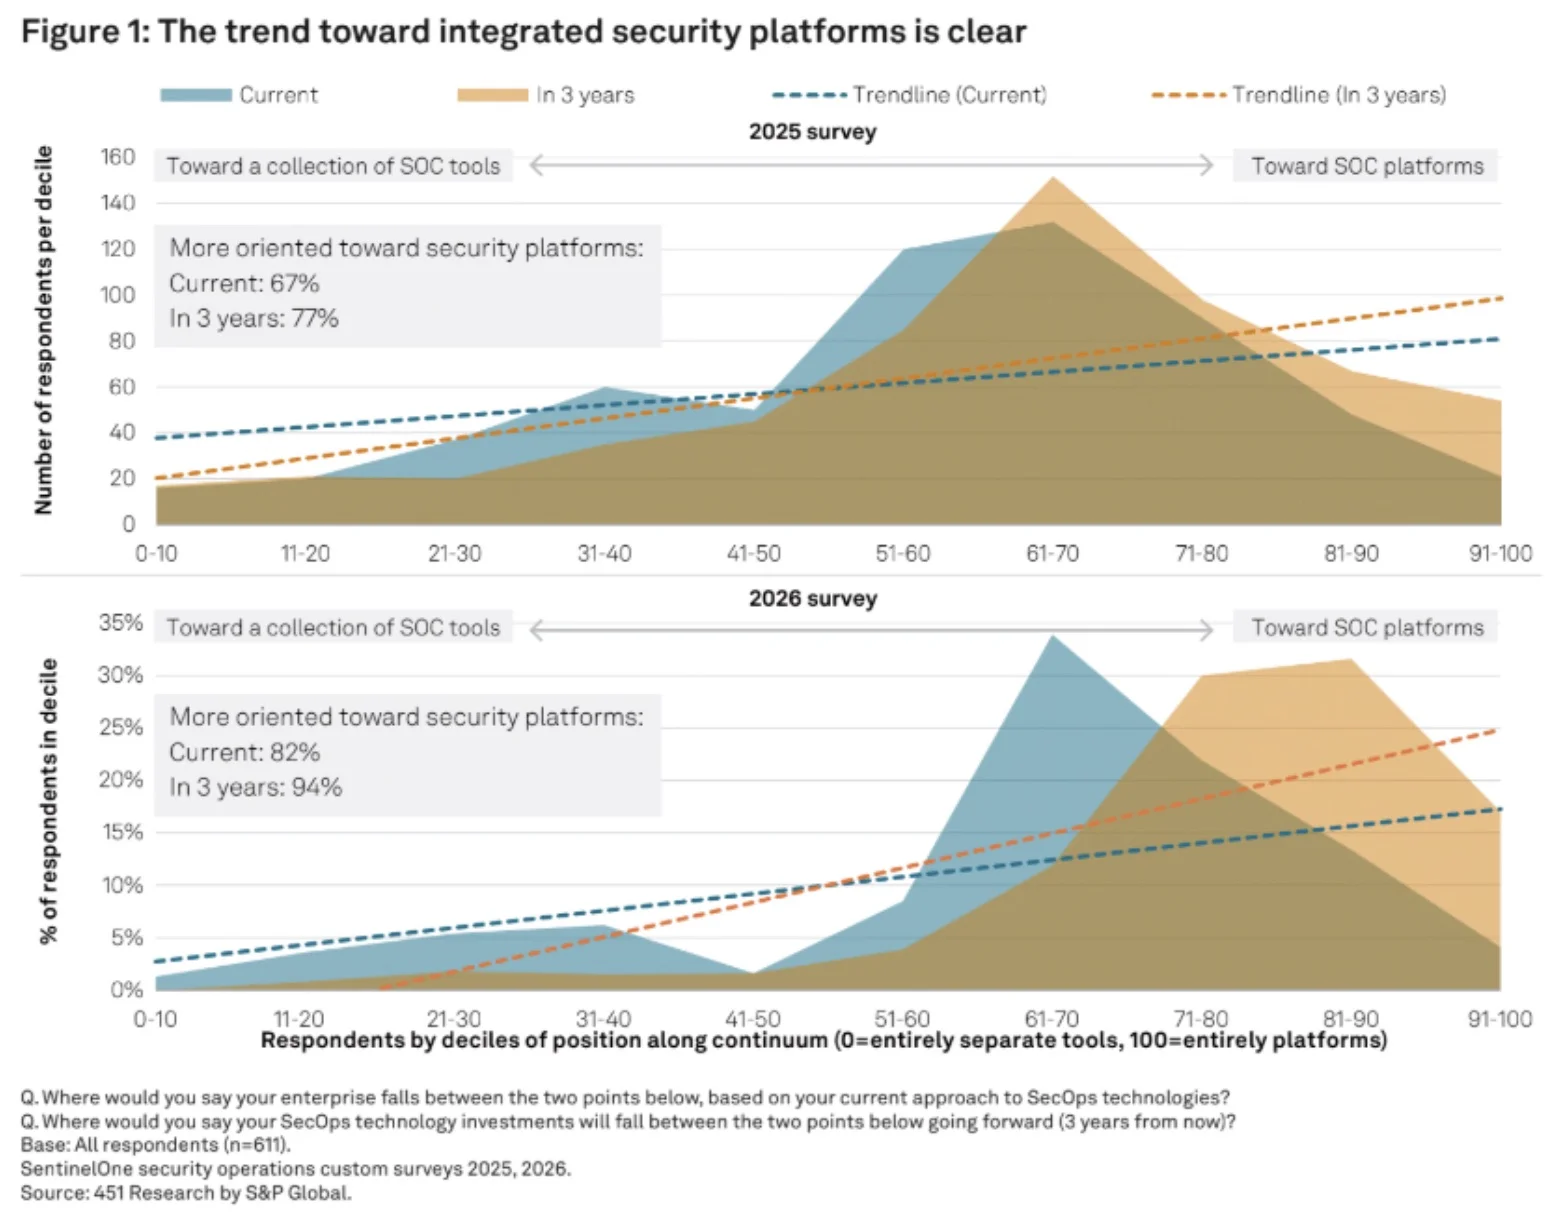
The platformization numbers from this year’s survey are clear. 82% of organizations describe themselves as platform-oriented, a 13-point jump in a single year, and 94% expect to be there within three years.
A common assumption is that platform adoption means replacing specialized tools. The data complicates that picture. The same technologies most frequently deployed as standalone tools (EDR, SIEM, CNAPP) are also the top anchors for integrated platforms. Organizations typically start with one of these and expand outward. What changes is the common data layer that enables coordinated AI decision-making, serving as the connective tissue underneath.
Platformization is not coincidental with AI’s emergence. Agentic AI needs connected, continuously updated data to accurately reason across signals and take autonomous action. Fragmented architectures, where telemetry is siloed and pipelines require manual effort, cannot support AI-driven SOC operations at scale. Platform adoption and AI adoption are converging because AI’s data requirements have made integration a structural necessity.
The survey makes the infrastructure connection an explicit one. The top-cited benefit of investing in a data lake for SecOps is supporting AI-driven SOC workloads and agents. Organizations that built the data foundation early have already cleared the barrier stalling others. Those who haven’t, face a prerequisite gap, and the distance is widening rapidly. Architectural readiness is the variable that determines how far AI investments can scale.
Job Satisfaction Is Rising
Every discussion of AI in the SOC centers on detection and response metrics. This report has those too, but there is a finding that security leaders managing attrition should weigh: analyst burnout is declining.
As AI handles repetitive, high-volume triage work, analysts report rising job satisfaction. The role is shifting away from processing an endless queue and toward investigation, threat hunting, and judgment-intensive work. In a market where SOC analyst turnover remains a persistent operational cost, that shift carries real dollar value.
The analyst role evolves, becoming more strategic and more consequential.
A New Attack Surface
The same AI systems changing how SOCs operate are also creating new targets. Adversaries are already probing AI infrastructure including agents, data pipelines, model endpoints, and the governance gaps that emerge when controls lag behind adoption. The report surfaces this tension clearly: Organizations are deploying AI faster than they are securing it.
An AI agent with misconfigured access or an unmonitored data pipeline is an exposure. Securing the AI infrastructure that powers the SOC is happening alongside deployment, whether organizations have planned for it or not. Those without a clear governance posture are accepting risk that may not be priced into their AI investment case.
The potential of GenAI and agentic AI in the SOC is already being realized. The organizations that capture it fully are those building governance alongside deployment. The platform that runs the Autonomous SOC and the platform that secures it are, increasingly, the same platform.
SentinelOne’s Vision: The Autonomous SOC
Everything the report surfaces, from AI returns arriving before maturity to platform consolidation to the improving analyst experience, points to how these are expressions of the same shift. The foundation that enables early AI returns is the same one that determines how far those returns scale, how capable analysts become, and how well the security of AI itself is governed.
The findings align with how SentinelOne has defined the path to autonomous security operations: A progression from AI-assisted triage at early maturity levels to increasingly autonomous investigation, threat hunting, and response, with humans in strategic and governing roles. The report validates that the market is moving through exactly that sequence. Organizations that understand the architecture behind it (the platform integration, the common data layer, the governance controls) are positioning themselves to capture returns at every stage rather than waiting for the destination.
The full 451 Research report goes further into detail, covering what progression looks like at each maturity level, the specific barriers organizations are encountering, and the data behind each finding in full.
All third-party product names, logos, and brands mentioned in this publication are the property of their respective owners and are for identification purposes only. Use of these names, logos, and brands does not imply affiliation, endorsement, sponsorship, or association with the third party.
This blog may include discussion of unreleased services or features. Any unreleased services or features referenced here are still in development and subject to change. Customers should make their purchase decisions based upon features that are currently available.
AI agents have made their way into virtually every layer of your environment. They run in the apps your employees adopt, on the endpoints where agents execute code, as users with access privileges those agents borrow, and in the cloud workloads that scale them. The platform that you trust to secure your endpoints is already already covering where AI operates today.
Here is the through-line that makes this one problem instead of four. Every AI attack starts as an interaction and ends as an action. A prompt gets manipulated, an agent gets tricked, and the damage lands on a host, reaches into an identity, or moves through the cloud. The tools that treat each surface as a separate product hand you fragments. SentinelOne treats them as one chain.
How SentinelOne Defends the Agentic Stack Today
Employee AI use is where the risk quietly enters. Your people are already using AI tools you never sanctioned, through browser, IDE, and API-connected apps and agentic AI tools. SentinelOne discovers that shadow AI use across browsers, IDEs, and copilots, highlights which tools and models are in play and governs it with policy. It keeps confidential data, PII, and secrets from reaching untrusted models, and it stops prompt injection and jailbreaks aimed at the tools you build. Legacy DLP reads patterns; this reads context, which is the only way to catch an attack aimed at AI systems that behave in a non-deterministic way.
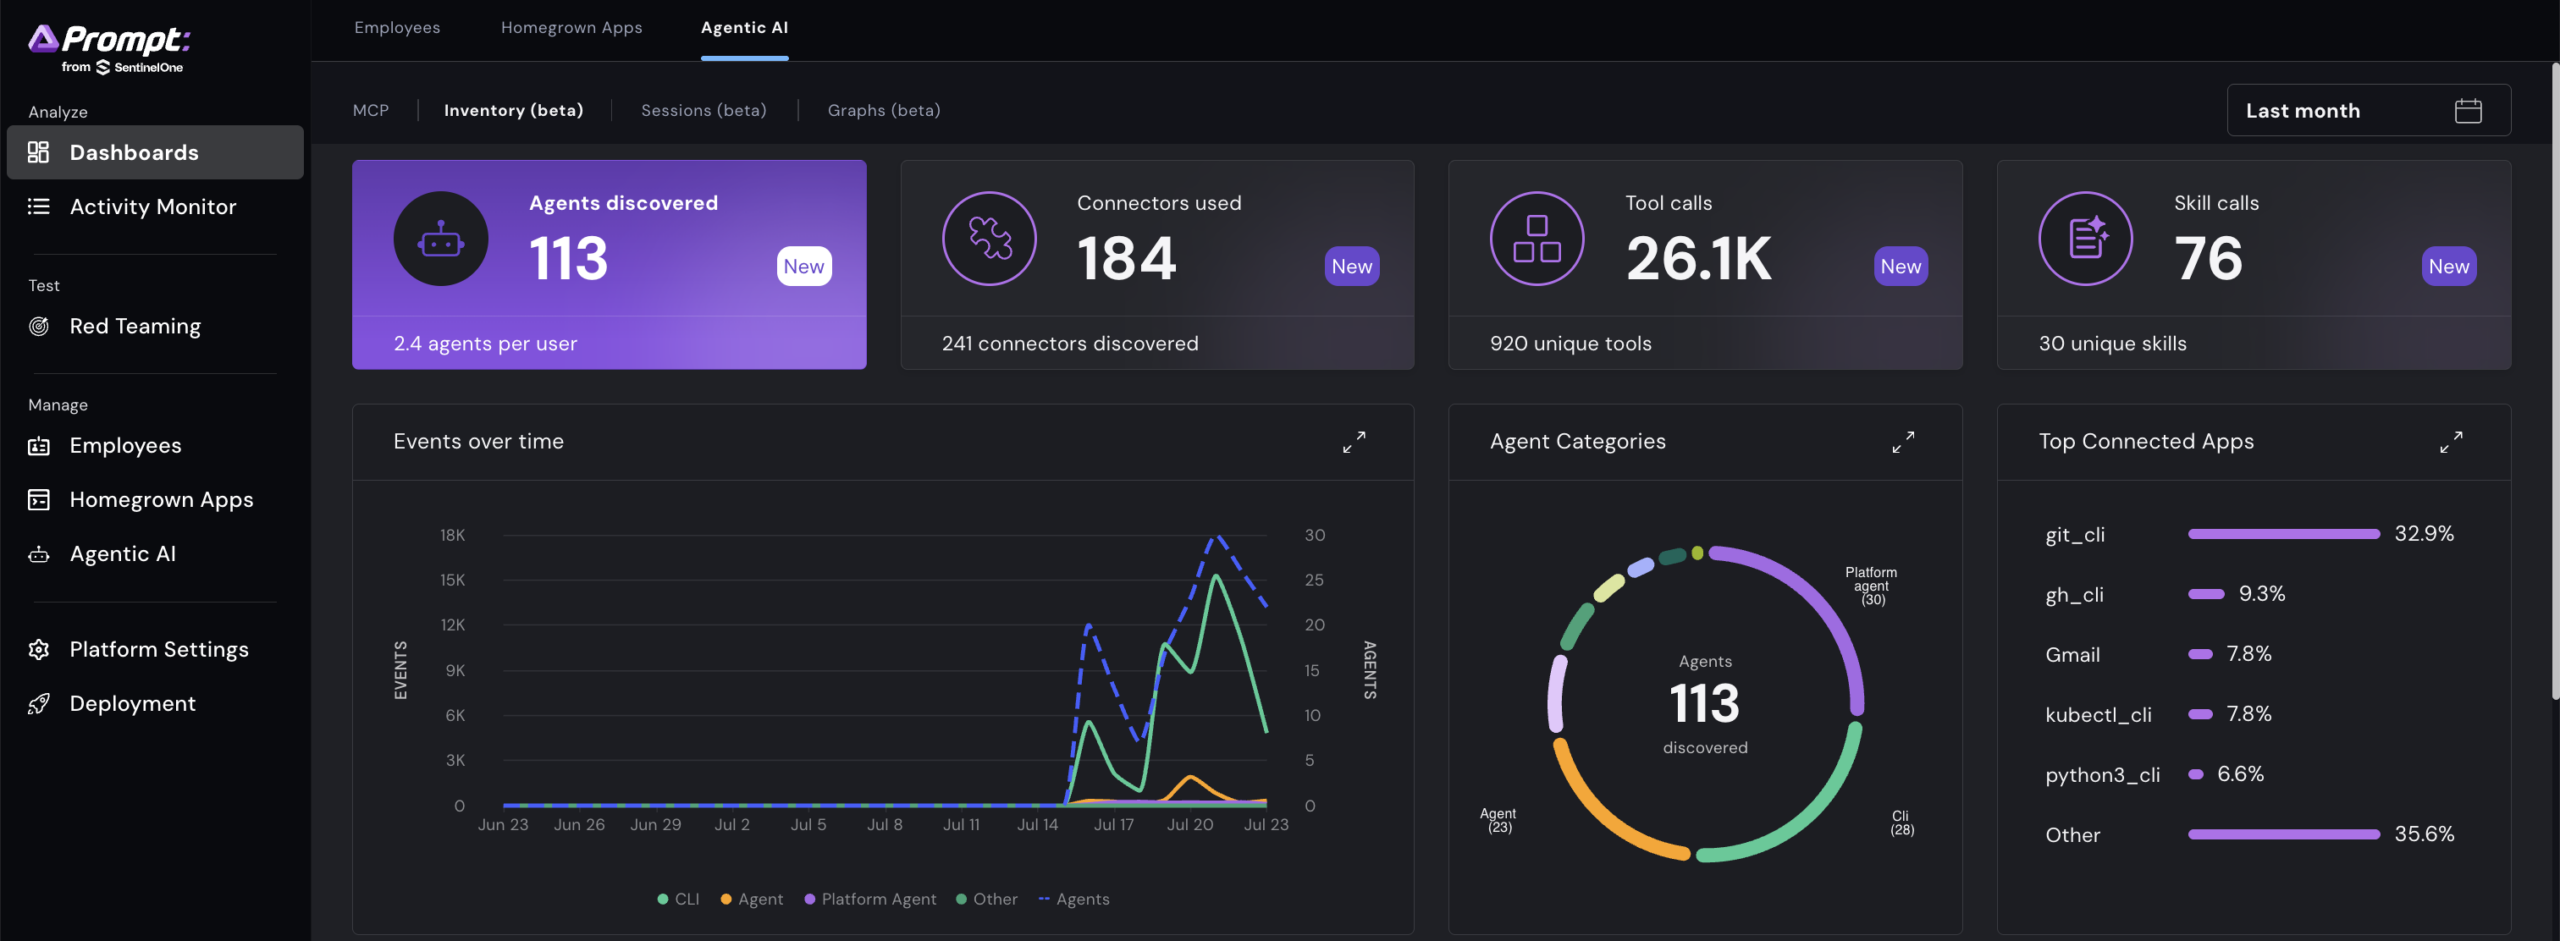
The agent layer is where AI stops advising and starts acting. An employee’s prompt sends text. An agent sends commands, holds credentials, calls APIs, and chain actions without a human approving each step. That makes them non-human identities with standing access. SentinelOne governs that access. It inventories the agents and MCP servers already operating and scores what each one can reach and holds every agent to the privileges its task requires. Then it inspects the tool calls themselves, so an injected instruction gets blocked at the moment it would execute. What gets executed lands in a searchable record, and the same enforcement doubles as a kill switch.
Inventory the agents already running in your environment, the connectors they reach, and every tool call they make.
While governance decides what an agent is allowed to do, the endpoint is where you find out what it actually did.
The endpoint is where agents execute. This is the frontier, and where SentinelOne has protected customers for over a decade. Our behavioral engine judges what a process does, not what it claims to be. That is how we caught QUIETVAULT – malware that spins up AI agents in “yolo” mode to exfiltrate secrets to GitHub. It is how we autonomously stopped the LiteLLM supply chain attack, where adversaries weaponized the Claude CLI to install a malicious payload. It is how we surfaced a DLL side-loading attack hidden inside an AI tool installer. Real detections, on the endpoint, today. Agents run on the host, and so do we.
The identity is where a hijacked agent runs next. Picture an employee’s AI coding agent that gets hijacked mid-task. It spawns a shell and reaches for cached credentials and cloud session tokens, trying to stop being a process and start being the user. That pivot to identity is what unlocks lateral movement, and it is where most AI attacks are headed. SentinelOne meets the move. It secures human and non-human identities alike, and seeds the environment with decoy credentials and honeytokens no legitimate user ever touches. The instant the hijacked agent grabs one, the trap trips, and Identity responds by forcing an MFA re-challenge, disabling the account, or isolating the host. Authorization at login is not enough. Access gets validated against behavior and pulled at runtime.
The cloud is where AI workloads scale. Consider an internal AI agent running in a Kubernetes cluster with standing access to a customer database. Security teams keep asking the same question about deployments like this. Where is the model connecting, and who is it talking to? SentinelOne answers with eBPF-native runtime protection that judges how the workload actually behaves, and flags the moment that inference service reaches an endpoint it has never touched before. It covers the control plane the deployment depends on, the secrets it reads, the pipelines it runs through, and the data it can access. Defending the AI you build takes more than watching it, it takes action on the workload in real time.
SentinelOne’s Singularity Platform Advantage
Each of these surfaces matters on its own. What closes the kill chain is following an attack across them without losing it at the handoff. This is where a single platform earns its keep. AI telemetry already streams into the Singularity Data Lake, alongside the endpoint data the platform has correlated for years. As identity and cloud signals join that same view, an analyst follows one attack from first prompt to final action, without stitching logs across six tools at two in the morning. A manipulated prompt, the process it spawns, the credential it reaches for, and the cloud resource it targets read as one story rather than six disconnected alerts.
Detection that only watches is observation. Runtime action is protection. When the Singularity Platform acts, autonomous response blocks the execution, rolls back the change, and revokes the access at the point of impact, without a human relaying orders between consoles. This is the difference between whether an attack is stopped or just gets logged.
That is the case for securing AI inside a platform built for autonomous runtime response. We are not adding a console to chase AI, we are extending the one already deployed where your agents run.
Questions to Ask When Assessing Your AI Security Options
When evaluating AI security, ask yourself three things.
Does the solution protect the endpoint where agents actually execute, or is it a roadmap item?
When a hijacked agent pivots to credentials and the cloud, does that telemetry land in the same platform, or are you manually connecting dots across three dashboards?
Can the solution act at the moment of execution, or only tell me what already happened?
SentinelOne protects the surfaces where AI runs today. This includes the apps your employees use, the agents they deploy, the endpoints where agents execute, the identities they borrow, and the cloud where they scale. One platform, built for autonomous response. While AI has changed the attack, it does not have to change your architecture.
See it for yourself. Talk to our team about securing AI across your endpoints, identities, cloud, and the AI apps your employees already use, all from the platform you run today. Contact SentinelOne today.
Third-Party Trademark Disclaimer:
All third-party product names, logos, and brands mentioned in this publication are the property of their respective owners and are for identification purposes only. Use of these names, logos, and brands does not imply affiliation, endorsement, sponsorship, or association with the third-party.
AI is absorbing the volume work that makes up the fundamental architecture of the Security Operations Center (SOC) tier system. While the tiers and the work aren’t going away, a junior and senior analyst’s day-to-day is changing fast.
At some point in the last week, every analyst on your team made the same call. Close an alert uninvestigated, because the queue was too long and triage ate the time real investigation and deep analysis was needed. Most of those calls were right, but odds are that at least one critical threat will eventually be overlooked.
The root cause here is the mathematical disparity. Nearly half of SOC teams lack the capacity to investigate more than fifty percent of the alerts they generate daily. Analyst capacity grows linearly while data volume compounds exponentially.
According to findings from SentinelOne®’s Annual Threat Report, what’s worse is that the math leans heavily towards the adversaries. Automated exploits have been recorded escalating privileges within a target environment in approximately 30 milliseconds. Similarly, malicious attack chains can progress from initial network access to establishing persistent footholds in under 50 seconds. No manual workflow currently matches these kinds of machine speed tempos.
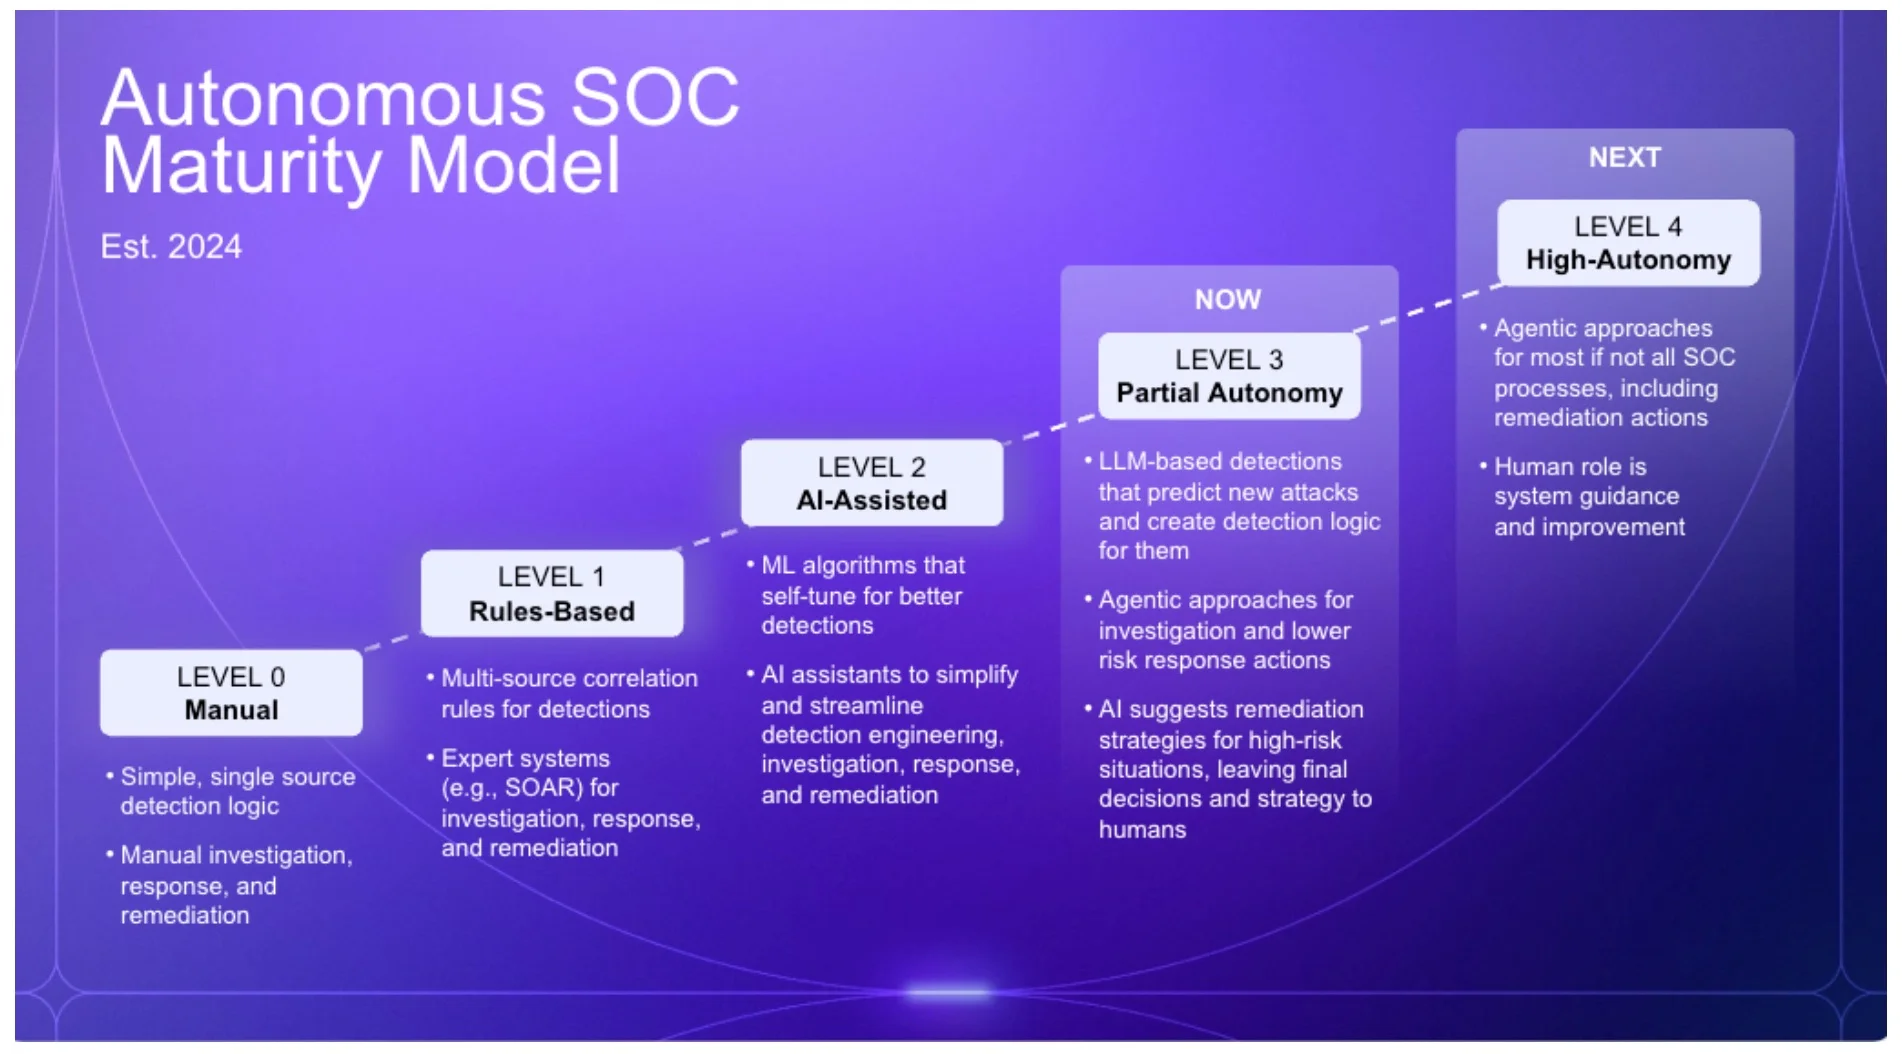
As a result, the traditional tier structure of the SOC is transforming in real time. AI is already absorbing the triage and correlation work that that structure was originally built to manage. The critical call-out here is understanding that these tiers are not dissolving; rather, they are evolving. Junior and senior analysts still exist and hold their titles, and continue to have a clear career path ahead of them. What’s changing is the nature of the tasks that fills their day.
Analyst Tiers, Redefined by Depth
Historically, the distinctions between Level 1, Level 2, and Level 3 analysts were established primarily to manage high-volume workloads. Those distinctions were built to manage volume: Alerts routed to the right skill level, junior analysts escalating what they couldn’t resolve, senior time reserved for what actually needed it. AI now handles the triage and correlation volume those tiers existed to manage. Volume stops being the variable that defines the role. As a result, analyst tiers are being redefined by depth of expertise rather than the ability to process large queues.
That evolution isn’t limited to junior and senior analysts:
Threat intel analysts move from manual feed correlation to directing AI-correlated intelligence
Security engineers move from manual rule-writing to guiding AI-generated detection logic
SOC managers move from tactical management to strategic leadership and AI governance
Depth of expertise replaces volume as the key differentiator: cloud architecture, identity, adversarial tradecraft. The kind of judgment that only comes from watching an environment long enough to know what normal looks like. AI can’t replicate nuanced, environment-specific skills that the legacy, volume-driven tiered system was never able to encourage or reward.
A Day in the Life, Before and After
In the legacy model, an analyst’s day typically begins by facing a queue containing hundreds of unvetted overnight alerts. Three or four hours go to manual triage, pivoting between tools to reconstruct what happened. The vast majority of the queue closes as false positives. The real threat, if there is one, surfaces hours later, pieced together across five or more disconnected consoles.
Adding in the administrative paperwork widens the gap even further. The legacy model requires analysts to spend upwards of an hour writing an incident report that adds nothing to the actual technical investigation. The new model allows the analyst to review and approve an AI-generated summary, adds environment-specific context, and closes the case in minutes.
In a modern model, the day starts with a prioritized queue instead of a noise wall: evidence-backed verdicts already assembled, ready for review. Thirty minutes go towards confirming the highest-priority case. That confirmation triggers a pre-approved response workflow within defined policy. Critical hours that were parcelled off to triage are used for proactive threat hunting instead.
Teams operating this way report the difference in hard numbers, according to two IDC research studies commissioned by SentinelOne.
Teams using AI-powered investigation report 63% faster threat identification and 41% more efficient investigation. (IDC Business Value of Purple AI®, July 2025)
AI SIEM customers on the Singularity Platform report 55% more efficient security operations and 4x more threats handled, at 55% lower solution costs. (IDC Business Value of Singularity AI SIEM, May 2026)
That time moves to where the judgment actually matters.
Governance is the New Core Skill
Recovered time only pays off if real judgment fills it. The most important judgment now is knowing when to distrust the AI.
The analyst who knows exactly where their AI is unreliable is more operationally effective than the one who trusts it uniformly. That skepticism is a skill and it has to be built on purpose, case by case.
Four capabilities define the analyst role going forward:
Validating AI output instead of accepting it by default
Designing the automation workflows that execute at machine speed
Forming hypotheses worth hunting instead of only answering tickets
Translating what the AI found into what it means for the business
Escalation frameworks must be designed to reflect that same judgment. Teams building trust in a new workflow route more cases to a human by default. Mature teams narrow that escalation path as their confidence in specific alert types grows. Either way, the analyst decides where the line sits, not the AI.
On top of this, analysts must govern the response earlier, setting the policy before events are triggered instead of reacting to it. Every automated action is scoped to a policy an analyst defined in advance. This keeps all of the details of the logged and fully auditable after the fact. The quality of what fires automatically traces back to the quality of that workflow.
The Career Path Forward
The evolution we are seeing in SecOps is directly addressing systemic issues of burnout and attrition, both significant risks to retaining talent within the cybersecurity industry. Under an AI-augmented model, every rung on the SOC career ladder gets more strategic:
Junior analysts move from manual triage to verdict review
Senior analysts move from reactive response to strategic hunting
Managers move from daily firefighting to designing the system everyone else works inside
None of this happens in one leap. Adoption works crawl-walk-run, workflow by workflow. ‘Crawl’ starts with AI-assisted triage, validated against your own judgment, alert by alert. ‘Walk’ enables automated responses for well-understood, lower-risk cases, with human approval required for anything novel. ‘Run’ hands full workflows to AI for established threat patterns, with analyst time going to verdict review and hunting. Different parts of a SOC can sit at different stages of that maturity at the same time.
All third-party product names, logos, and brands mentioned in this publication are the property of their respective owners and are for identification purposes only. Use of these names, logos, and brands does not imply affiliation, endorsement, sponsorship, or association with the third-party.
Security Operations Centers (SOCs) are currently confronting scalability challenges on two fronts: structural and cognitive. The day-to-day reality of modern defensive operations is stark: an analyst frequently begins a shift facing a queue deeply saturated with unvetted alerts. To process a single event, the analyst must open the alert, pivot to a secondary console to complete an investigation, manually enrich an IP address, copy a file hash into a third interface, and cross-reference an asset inventory that may not have been updated in months. Following this, they must author and refine queries, waiting for overloaded databases to return historical context.
The actual work of assessing the investigation’s results and moving to decision-making and action has not even begun. This is the administrative burden of the modern SOC. The true threats are not just those that attempt to bypass defenses, but the critical operational hours lost before an active mitigation attempt is even initiated. While analysts are highly trained professionals, the relentless requirement to perform manual data aggregation inevitably leads to exhaustion.
Misdiagnosing the Bottleneck: The Upstream Data Problem
Threat actors operate at machine speed, utilizing automation to pivot laterally across networks in a matter of seconds, frequently disappearing before defensive teams can even log into their terminals. Expecting human defenders to counter automated threat vectors by manually aggregating bad data is an architectural failure.
Every SOC inherits a highly fragmented data ecosystem. Telemetry is continuously generated by diverse sources, including firewalls, cloud workloads, identity providers, endpoint sensors, and legacy systems. This telemetry arrives in disparate dialects, varying formats, and highly inconsistent levels of fidelity. Before AI tools can accurately reason about a potential threat, or an analyst can initiate a logical investigation and run a playbook response, this raw telemetry must be synthesized.
Historically, organizations analysts take on these complex synthesis processes, manually normalizing data points across different vendor schemas. This represents a key misallocation of human intelligence. The asymmetry in modern security operations is not merely a discrepancy in speed; it is an imbalance in how security teams are forced to allocate their finite time. When operators spend the majority of their shifts wrangling data instead of actively investigating threats, the foundation of the SOC itself is inadequate. To achieve defensive velocity, organizations must recognize that fixing the data foundation is the mandatory prerequisite for improving all downstream security functions.
Architecting the Data Foundation with Singularity AI Data Pipelines
Addressing the upstream data problem requires the implementation of advanced data pipelines capable of resolving enterprise data chaos before it impacts the detection engine. Frameworks such as SentinelOne’s® Singularity AI Data Pipelines serve as this foundational layer, engineered to ingest telemetry from every source and in every format without requiring months-long integration projects or heavy manual engineering.
Modern pipelines utilize AI to normalize raw telemetry into standardized formats, specifically aligning with the Open Cybersecurity Schema Framework (OCSF). This structural alignment transforms fragmented logs into structured data that is immediately actionable. It eliminates the need for analysts to construct complex regular expressions during critical incidents simply to reconcile how two different software vendors format data, such as usernames or a timestamp.
Efficient data ingestion also requires dynamic, in-flight optimization. Not all telemetry possesses the same analytical value, and storing all generated logs in highly indexed, expensive storage tiers is financially and operationally untenable. Data pipelines optimize data streams by filtering out extraneous noise, trimming excess volume, and routing specific logs based on dynamic criteria. High-value security events are routed and indexed for rapid search retrieval, while lower-priority compliance or operational logs are routed to more cost-effective tiered storage. The result is a substantial reduction in infrastructure costs, a higher signal-to-noise ratio, and a structured data foundation that is completely prepared the moment an investigation is required.
When underlying data pipelines automatically enrich that log with identity and asset information, revealing (for example) that a specific financial director’s laptop in a remote office is communicating with a known botnet, the output transitions from a raw data point into a definitive starting point. Crucially, this enrichment occurs systematically before the human operator ever interacts with the alert. Solving this data problem end-to-end is a primary reason SentinelOne was recognized in the IDC MarketScape for AI SIEM.
Accelerating Detection via Singularity AI SIEM
When a clean, structured data foundation is properly established, the performance of downstream security tools accelerates. Modern detection engines, such as the Singularity AI SIEM, leverage indexless architectures to manage enterprise-scale telemetry. Because the data is normalized and optimized prior to ingestion, these platforms can execute petabyte-scale queries with minimal latency, ensuring investigative results are delivered before the analyst’s attention wanes.
Within this architecture, detection logic is executed continuously against a stream of clean, correlated telemetry. This transforms an ocean of disparate event logs into readable, centralized dashboards that provide immediate situational awareness. The quantitative benefits of this approach are substantial. With AI SIEM, organizations are already executing their queries 70% faster. Adding AI Data Pipelines further augments this workstream, providing cleaner data for AI to run at optimal efficiency. These improvements represent the direct result of ensuring that the data arriving at the SIEM is inherently fit for purpose.
AI SIEM remains a single, comprehensive SKU with customers automatically receiving integrated pipeline functionality for everyday data optimization rather than treating it as a premium add-on. For every unit of paid Data Ingest capacity, customers can process twice that volume through Data Pipelines. A customer with 500 GB/day SIEM entitlement can push 1 TB/day through the pipeline at no additional cost.
Transitioning to Agentic Reasoning Layers with Purple AI
The establishment of a structured data pipeline unlocks the capability for true agentic reasoning within the SOC. Unlike traditional rule-based automation, which executes static responses to predefined triggers, technologies like SentinelOne’s Purple AI operate as a dynamic investigative layer.
When an initial alert is generated, an agentic reasoning system does not simply pause and wait for human triage. It autonomously launches an investigation, comprehensively maps the potential blast radius of the incident, and synthesizes a clear, logical recommendation for containment. Then, the analyst logs into the console and is presented with a fully formed situational briefing rather than a blank investigation screen.
More importantly, an agentic AI layer possesses the capacity to evaluate broader adversarial campaigns rather than isolated security events. In isolation, a minor registry key modification, a singular file write, or a brief outbound network connection may not meet the threshold for a critical alert. Legacy security tools often fail to connect these disparate, low-signal events. However, Purple AI can assemble these seemingly unrelated activities into a cohesive narrative, exposing the overarching strategy of the attacker before a major breach occurs.
This level of autonomous intelligence is strictly dependent on the underlying architecture. Advanced AI algorithms cannot derive accurate conclusions from unparsed, low-quality telemetry. The analytical integrity of the agentic layer is entirely contingent on the principle of data quality; systems like Purple AI require clean, structured data to function effectively, avoiding the fundamental issue of “garbage in, garbage out”.
Governed Hyperautomation and the Human-in-the-Loop
The final component of a modernized, agentic SOC is the deployment of Hyperautomation to execute defensive responses. To counter threats effectively, organizations must deploy automated workflows capable of executing decisions at machine speed. These no-code workflows can be configured to trigger autonomously based on AI triage verdicts, the disclosure of new high-severity vulnerabilities, or specific incoming alerts. By automating the mitigation phase, the SOC evolves from an environment strictly dedicated to passive observation into a dynamic system that actively neutralizes threats.
However, the implementation of automated response mechanisms must be rigorously governed. Executing changes to enterprise infrastructure carries inherent risk. To mitigate this, automated workflows must integrate critical approval steps, ensuring that highly consequential actions are paused until human authorization is provided. The analyst retains the ultimate authority, defining the precise parameters of what processes may run automatically and what workflows require manual judgment.
Redefining the Analyst Mandate via Autonomous Security Intelligence
The strategic objective of integrating data pipelines, agentic reasoning, and Hyperautomation is not the removal of the human operator. Instead, the overarching goal is the restoration of the analyst’s primary function: exercising expert judgment.
By offloading repetitive tasks to technological systems, organizations systematically remove operational friction. The data layer filters out irrelevant noise, allowing the analyst to clearly see the threat. The AI investigation layer removes the administrative grind of data collection, allowing the analyst to focus purely on analytical thinking. Finally, the automated response layer eliminates procedural delays, ensuring the analyst’s decisions are executed rapidly enough to matter. This creates an intelligence fabric, known as Autonomous Security Intelligence (ASI), where data, investigation, and response function concurrently as a single, unified system.
Under this model, the operational output of a single analyst is exponentially multiplied, allowing one unburdened professional to accomplish the work of ten while still owning every critical decision. While the alert queue will perpetually require attention, the fundamental nature of the work fundamentally changes. The timeline of a manual initial triage to active investigation compresses from a multi-hour ordeal into a matter of minutes. The data arrives clean, the investigation runs automatically, and the response mechanisms are prepared. The hours previously consumed by administrative waiting are directly reallocated to strategic decision-making.
Conclusion
When defensive systems are finally architected to operate at the speed of the modern threat landscape, the role of the human operator transforms. Analysts are no longer forced to act as passive passengers, grateful to be carried by fragmented tools. They are elevated to the role of pilots, operating with full situational awareness, retaining their judgment, and actively directing the defensive posture of the organization. This is the paradigm of the agentic SOC, and it is entirely predicated on the foundation of clean, structured data.
Contact us today to learn more about how SentinelOne is leading the way forward with Agentic SOC.
The US Federal Government is committing $600 million to build one of the world’s most advanced AI infrastructure systems. Executive Order 14363, the Genesis Mission, connects national laboratory supercomputers across nuclear simulation, biodefense, energy grid modeling, and every major scientific domain. Fifty-one organizations signed on, including NVIDIA, OpenAI, IBM, Microsoft, AWS, Google, and Oracle.
The security framework governing these workloads was not written for this scale of use.
NIST SP 800-234, the High-Performance Computing Security Overlay, is well-constructed, tailoring 60 controls across four security zones, building on the SP 800-53B moderate baseline. It was designed for deterministic HPC workloads such as climate simulations, finite element analysis, and computational fluid dynamics. These workloads share a common attribute: code that runs the same way, every time, and behaves predictably under well-understood inputs. The security controls governing those workloads assume you can scan at the perimeter, clear memory between jobs, and attest to integrity at load time.
AI workloads break every one of those assumptions.
SentinelOne has submitted a formal proposal to the NIST HPC Security Working Group regarding this gap, and NIST has acknowledged it. We have a post on LinkedIn to share our proposal, and welcome commentary from across the industry.
The supply chain problem just got a lot more dangerous
This spring, in just three weeks, three AI-driven supply chain attacks targeted widely deployed software: LiteLLM, the most-used AI infrastructure package in Python development environments, Axios, the most-downloaded HTTP client in the JavaScript ecosystem, and CPU-Z, a trusted system diagnostic tool with a legitimate signed binary from the official vendor domain.
SentinelOne stopped all three on the same day each attack launched, with no prior knowledge of any payload.
The most important aspect of this outcome is how these attacks were stopped, and why signature-based detection couldn’t work. Each attack arrived through a trusted delivery channel. LiteLLM was compromised after credentials were stolen via Trivy, a security scanner. The attacker published two malicious versions to the PyPI repository. In at least one confirmed case, an AI coding agent with unrestricted permissions auto-updated to the infected version, meaning there was no human review or approval step before the payload ran. The Axios attacker exploited a legacy access token that the project maintainers had forgotten to revoke, bypassing every npm security control. CPU-Z attackers targeted the vendor’s distribution infrastructure directly; anyone who downloaded from the official website received a properly signed binary containing a payload. In all three cases, while the authorization chain was legitimate, the intent was not.
This is the defining characteristic of modern supply chain attacks: the workflow is verified, but the intent has been subverted. Every perimeter control, signature library, and reputation lookup checks authorization and passes. These attacks were designed to exploit that gap, and they ran at machine speed through automated pipelines with no human checkpoint.
To put this into the context of HPC and AI workloads running at scale, a compromised Python package in a developer’s environment is a serious incident; a poisoned training pipeline on classified biodefense data on a national laboratory supercomputer is on a different order of magnitude. The model it produces may be correct 99.9 percent of the time and adversarially wrong under precisely targeted conditions. No perimeter scan, signature check, or load-time integrity verification will catch it after training completes.
Where the current framework falls short
Of the 60 controls SP 800-234 tailors, three bear directly on AI workload protection, and each carries a documented gap. In a fourth area, supply chain, the overlay does not tailor at all.
SI-3 (Malware scanning): The control acknowledges that real-time scanning is most effective but explicitly permits tailoring for performance on HPC systems, deferring to perimeter scanning before data reaches the compute zone. For traditional HPC workloads, that tradeoff may be defensible, but for AI workloads, it leaves behavioral analysis of the execution process completely unaddressed. A poisoned training run that executes within the expected statistical range of a training job looks like legitimate compute to a perimeter scanner.
SI-4 (System monitoring): The control notes that high-speed data flows in HPC environments can overwhelm standard monitoring tools, and lacks AI-specific monitoring requirements or telemetry collection requirements from execution pipelines. The practical interpretation of this is: monitor what you can, accept the gap for what you can’t. On infrastructure running AI at scale, that gap creates a primary attack surface.
SC-4 (Information in shared resources): Requires GPU memory clearing between user reassignments. It addresses data residency at the transition but does not address runtime behavioral monitoring of workloads during execution, side-channel attack detection, or anomalous compute-pattern identification while training is active.
SR family (Supply chain risk management): The overlay carries all 12 moderate-baseline SR controls forward from SP 800-53B, with no HPC or AI-specific guidance, and supply chain is not among the 14 categories it tailors to. The SR controls still address only the conventional software and hardware supply chain; they say nothing about training-data provenance, model-weight integrity, or pre-trained-model validation, and the framework defines no AI equivalent of a software bill of materials. LiteLLM, Axios, and CPU-Z all arrived through legitimate software supply chain channels. AI workloads carry that same exposure one layer deeper, in the data and model artifacts that software trains on, which is exactly where the overlay is silent
AI Runtime Threats
The attacks against AI workloads on HPC are not theoretical, and they are not detectable at the perimeter.
Training data poisoning scales at rates most security teams are not equipped to respond to. Research1 across 41 studies documents attack success rates exceeding 60 percent from manipulation of 100 to 500 training samples, a fraction of a percent of a typical dataset. Poisoning as little as 3 percent2 of training data achieved 41 percent attack success rates in code-generating models. OWASP’s LLM Top 103 documents the consequence. Backdoors leave model behavior intact until a specific trigger activates adversarial outputs. The model ships, it gets deployed, and operates correctly, until it doesn’t. No post-training audit reliably catches a well-designed poisoning attack.
GPU side-channel attacks are executed remotely by a co-tenant workload on shared GPU infrastructure; no physical access is required. The NVBleed research demonstrated covert channel attacks on NVIDIA NVLink, achieving over 91 percent accuracy in recovering data-dependent information from co-tenant GPU workloads on a shared fabric. The BarraCUDA research demonstrated the extraction of neural network weights via electromagnetic side channels from NVIDIA hardware. Both attack classes execute during active training, not at job transition. If your HPC environment runs multiple projects or security classifications on shared accelerators, the co-tenancy model is an active attack surface today.
Inference pipeline compromise survives load-time integrity checks. A model with clean weights at deployment faces attacks through three vectors: hot-swap modification of serving configurations while inference runs; preprocessing and postprocessing layer injection that alters inputs before they reach the model or modifies outputs before delivery; and adversarial input manipulation that triggers targeted misbehavior in a model that appears fully operational. For AI serving safety-critical inference, each is a security risk, not just a research concern.
The characteristic that makes AI workloads uniquely difficult is persistence. A compromised simulation may produce visibly wrong results, but a compromised model can produce correct results the overwhelming majority of the time and adversarially wrong results under precisely targeted conditions. By the time anyone has reason to investigate, the window for recovery has often closed.
Securing HPC AI Workloads
We know the technology required to address these gaps exists and has been proven at scale in environments with performance constraints far tighter than those in HPC. What is needed is a well-defined architecture that enables the secure execution of large-scale AI workloads.
Dedicated security compute. Runtime security that shares CPU resources with the workload it monitors can be starved of CPU time under heavy load and interfered with by a workload that achieves kernel-level access. The SPiCa research demonstrated that eBPF monitoring pipelines can be manipulated from within the kernel by rootkits filtering events before they reach the analysis engine, meaning that a co-scheduled monitor is not a reliable monitor.
Every other infrastructure function on an HPC node has dedicated resources. The job scheduler, the filesystem client, and the out-of-band management plane. Security monitoring is infrastructure and should be afforded the same dedicated resources.
Modern HPC nodes have 128 to 256 CPU cores. One reserved for security monitoring is less than one percent of the available compute. Linux kernel CPU isolation via isolcpus, nohz_full, and rcu_nocbs is production-proven in high-frequency trading and real-time systems, with bounded, predictable overhead.
eBPF-based behavioral telemetry at the training layer. Effective monitoring of an AI training pipeline means continuous observation of compute behavior profiles, memory access patterns, GPU utilization, and inter-node communication, with behavioral baselines established for approved training configurations. A poisoning attack that executes within expected statistical ranges is not visible to a perimeter scanner, but it is visible to a behavioral baseline that knows what the training job should look like.
This is the same principle that SentinelOne’s on-device Behavioral AI detected for LiteLLM, Axios, and CPU-Z. The LiteLLM detection flagged a Python interpreter executing Base64-decoded code in a spawned subprocess. The CPU-Z detection flagged an anomalous process chain: cpuz_x64.exe spawning PowerShell, which spawned csc.exe, which spawned cvtres.exe. CPU-Z doesn’t do that. The behavioral baseline knew what legitimate execution looked like, and in these cases, that behavior was the decisive signal.
Cloudflare uses an eBPF-based architecture to mitigate DDoS attacks exceeding 7 Tbps. SentinelOne uses it to detect and stop threats in under one second across enterprise fleets. A training job that begins writing to unexpected locations, establishing anomalous inter-node communication, or deviating from its expected compute profile is detectable at runtime, before the model completes training. The performance argument against runtime monitoring on HPC was never about the technology; it requires a shift in architecture.
Inference-time output monitoring. Deployed models require continuous observation of output distributions, latency patterns, confidence score distributions, and input-output statistical properties. A model under adversarial input attack, or serving modified weights, exhibits detectable output patterns before any human analyst notices the outputs are wrong. Circuit-breaker logic needs to be designed into the serving architecture, not added after the first incident.
Model integrity verification that runs during inference. Load-time attestation is a necessary and important requirement; it is not sufficient. Long-running inference deployments are vulnerable to hot-swap attacks that replace weights after the initial integrity check passes. Continuous cryptographic hash verification of loaded model weights, running on the dedicated security core with automated circuit-breaker logic on failure, closes that vector. For a model serving safety-critical calculations, the re-verification frequency should match the workload’s risk profile with predictable overhead.
An SR-family extension for the AI supply chain. The existing SR controls address software supply chain risk. They do not address training data provenance, model weight integrity at ingestion, or pre-trained model validation. An AI bill of materials, including cryptographic documentation from the training data source through intermediate checkpoints to the deployed model, is the model-layer equivalent of software supply chain controls. Without it, every pre-trained model loaded into an HPC environment is an unverified artifact from an unverified chain.
Defending AI at Every Layer
The supply chain attacks this spring demonstrated what happens when defense architecture falls behind the delivery mechanisms attackers use. LiteLLM, Axios, and CPU-Z all arrived through trusted channels, carrying payloads no signature database contained. They were stopped because behavioral detection does not require prior knowledge of the payload. It requires knowing what legitimate execution looks like and acting when execution deviates.
Defenders protecting AI workloads face that same problem across every layer they own. HPC is the hardest version of it. But identities, endpoints, applications, and infrastructure all carry the same exposure at different scales. SentinelOne gives defenders coverage across all four, with behavioral AI running at each layer to catch what signatures miss. The specifics of how that works across your AI environment are in our AI security overview.
Citations
1 “Data Poisoning 2018–2025: A Systematic Review. IACIS (2025)”, and “Data Poisoning Vulnerabilities Across Health Care AI Architectures. JMIR (2026)
2 “Poisoning Attacks on LLMs Require a Near-Constant Number of Poison Samples” (2025). arXiv:2510.07192 and Huang et al., 2020.
3 OWASP (2025) LLM04:2025 Data and Model Poisoning. OWASP Gen AI Security Project.
When SentinelOne® introduced the Autonomous SOC maturity model, we made a deliberate choice: describe a journey, not promise a destination.
The industry had no shortage of vendors declaring that AI would transform security operations. We thought the more useful contribution was a framework for understanding what that transformation looked like, at what pace it was realistic, and what conditions each stage of progress required.
Security teams found the model useful. Not as a marketing claim, but as a map. CISOs and SOC leaders started placing their organizations on it, asking what it would take to move forward.
What happened next was telling. By RSAC 2026, ‘autonomous SOC’ appeared in vendor keynotes and product launches from companies that hadn’t used the term twelve months earlier. Add in pseudonyms like Agentic SOC and AI SOC, and the list explodes. Fast adoption brings loose definitions. For us, it’s worth being precise about what the concept means and what it doesn’t.
Here is what SentinelOne has learned from 18 months of real-world Autonomous SOC deployments.
What Held Up
Today, the progression still maps accurately to where organizations are and what separates each stage from the next. That accuracy holds even for a framework built before most organizations had meaningful AI deployment experience. The inflection points reflect real operational transitions at each maturity step.
The “journey not destination” framing has proven more important than we anticipated when we wrote it. In early 2026, Gartner published guidance to help buyers evaluate AI SOC claims more critically, noting that vendor credibility in this space depends on honest representation of where the technology is:
“Some vendors exaggerate capabilities (like being able to deliver a fully autonomous SOC), risking buyer trust and harming the reputation of legitimate solutions.”1
A maturity model is structurally honest. It reflects where you are, not where a vendor wishes you were. Gartner’s research found that while 40% of organizations are actively evaluating AI SOC capabilities, only 18% have actually deployed2. The gap between evaluating and deploying is rarely about technology. Most organizations cannot advance because they lack a clear view of where they stand or what the next stage requires.
When security leaders use the model as a reference point, the evaluation conversation changes. The question shifts from “does your product make my SOC autonomous?” to “what would it realistically take to advance, given where we are today?” A feature list cannot answer that question. An honest vendor can.
Watch our webinar on why most AI SOC deployments stallhere.
What We Underestimated
The levels were always sound. What we underestimated was how much organizations needed to build before they could operationalize them. Customers understood where they wanted to go. But achieving Partial Autonomy (Level 3) requires a data foundation, a workflow architecture, and AI readiness that most teams were still building when we first published this model. That’s a fact about where most security organizations were in 2024.
The transition from AI-Assisted Operations (Level 2) to Partial Autonomy (Level 3) is primarily a governance problem, not a tooling one. The tools are capable. What most organizations are missing is an understanding of the foundation of data and trust that Partial Autonomy (Level 3) requires, including the role humans play in building it.
When analysts work with AI assistance, they leave traces. Which queries they accept. Which results they act on. Which steps they modify or override. Over time, the system learns which investigation patterns the team trusts, which AI recommendations get acted on, and where analyst expertise is required – the kind of institutional knowledge that only comes from doing the work. Partial Autonomy is built on that record, not installed on top of an existing stack.
The path from AI-Assisted Operations to Partial Autonomy starts earlier than most organizations realize. It begins before they’re thinking about autonomy at all. Every assisted workflow is building toward what comes next.
What Holds Organizations Back
The primary barrier between AI-Assisted Operations (Level 2) and Partial Autonomy (Level 3) is accountability.
Consider how the automotive industry defined its equivalent of Partial Autonomy – SAE Level 3.
Taxonomy and Definitions for Terms Related to Driving Automation Systems for On-Road Motor Vehicles3
The designation applies only within specific, defined operational conditions. Outside those conditions, the human must take control. What qualifies a system for L3 is defined before autonomous operation begins: explicit parameters, a defined scope, and clear conditions for human override. Governance precedes autonomy.
Consider Waymo. It is the most capable autonomous system deployed at scale today — L3+ — operating without a safety driver under defined conditions. The vehicle is remarkable. But Waymo’s primary innovation is the organization built around it: the cloud infrastructure that keeps cars in autonomous condition, the human operations that handle exceptions the system cannot cover. The more autonomous the system, the more organizational maturity it required to build. High autonomy is an organizational capability.
The same logic applies in security operations. Accurate AI is the foundation. What makes Partial Autonomy legitimate is what gets built on top of it: defined rules of engagement, pre-approved policies, audit trails, and a clear organizational answer to who is responsible when an AI verdict is acted on. That accountability sits with the security team. When automation fires, it fires because someone made a deliberate governance decision to allow it. That is what makes it auditable, defensible, and durable.
Gartner’s readiness criteria for AI SOC deployments require that operational workflows be established in playbooks before AI is introduced4. In practice, the organizations that advanced most consistently treated that requirement as a sequencing discipline, not a box to check. They defined their rules of engagement before turning on automated response.
The second learning was the attacker asymmetry. Defenders who stall between AI-Assisted Operations and Partial Autonomy have often done the validation work. The AI logic checks out. What remains is the decision to extend that trust to autonomous action — and that decision takes time. Attackers move differently. They deploy, observe what works, and iterate. Governance is an externality. Trial and error with no consequences for failure is a significant operational advantage. The gap between a defender’s trust-building timeline and an attacker’s operational tempo is structural. It compounds.
Why High Autonomy Stays on The Horizon. And Why That Matters Less Than We Thought
Eighteen months of deployment have also changed how we think about the upper end of the model.
When the original post was written, High Autonomy (Level 4) was described as dependent on a level of AI reasoning we hadn’t yet seen in production security environments. That remains the right framing. What’s changed is how close that horizon has become. Two years ago, asking a model to reason through a multi-stage attack, correlate signals across data sources, and produce an auditable verdict required significant scaffolding and produced inconsistent results. That’s no longer true. The gap between where AI was and where High Autonomy requires it to be has narrowed substantially.
High Autonomy still requires more than capable models. Institutional trust takes time to build. Accountability structures have to go beyond controlled tests to survive real incidents. Human oversight has to be redefined from reviewing individual actions to governing a system’s behavior within a defined scope. Those are organizational problems, technology doesn’t solve them. That work is already underway at Partial Autonomy (Level 3). What the road to High Autonomy requires is only visible from Partial Autonomy. Organizations that haven’t operated there yet are planning for a destination they haven’t seen. The knowledge of what it takes is path-dependent, and it emerges from operation, not from design.
As organizations move deeper into Partial Autonomy, the distinction between levels matters less in practice. What security leaders actually want is relevant control: governance over the decisions that matter, without being burdened by the ones that don’t. You cannot be responsible or accountable for a system that asks you to review everything.
Control over the right decisions is what matters. An analyst reviewing every alert has maximum control and minimum leverage. A system that acts autonomously on well-understood threat patterns, surfaces only the ambiguous and novel cases for human judgment, and maintains a complete audit trail, gives the analyst control over exactly what deserves their attention. That is a better and more focused version of human oversight.
High Autonomy, seen through this lens, is AI that has earned sufficient trust within a defined scope. The remaining human decisions are the ones that require human judgment, because the governance architecture evolved to allocate human attention correctly.
In the same way, a pilot does not manually adjust every control surface for the duration of a flight. They set the destination, define the parameters, and monitor the instruments. The system handles thousands of micro-corrections that would be impossible to manage directly. The pilot’s job is to govern the conditions under which the aircraft flies itself, not to manage every control input directly. Nobody describes this as a lack of pilot control. It is a better allocation of pilot judgment. And it works because of the environment surrounding the autopilot: pilot training standards, airline operational doctrine, air traffic control, and regulatory frameworks. The technology is one layer of a much larger system.
The governance work done at Partial Autonomy is the same work that produces High Autonomy. Organizations investing in it now are not waiting for a future capability release. They are building the foundation on which High Autonomy operates.
What This Means for the Road Ahead
The first step toward Partial Autonomy is a policy decision. Define the conditions under which your organization will allow a system to act: which response actions, against which threat types, within what scope, under whose authority. Write it down, however rough. That document is the actual starting point. Without it, the tooling is irrelevant.
The work at Partial Autonomy is real, meaningful, and available now. Security teams that define accountability structures before deploying autonomous systems, build a record of AI efficacy in their specific environment, and treat governance as a prerequisite rather than an afterthought, are the ones that reach and sustain Partial Autonomy. They are also the ones best positioned for what comes next. That work produces a more integrated SOC — data, AI, and response operating as a unified system.
High Autonomy remains the north star. This clearly articulated ideal state stops organizations from settling too early. It is the same function that “zero trust” serves as an architectural principle: no organization fully achieves it. Every organization is better for pursuing it.
The tools are capable. The frontier models have advanced significantly since our maturity model was first introduced. The capability gap that once made waiting feel reasonable has narrowed. What remains is the institutional work. That work is always harder than buying a product, which is why vendors who are honest about it are worth paying attention to.
SentinelOne customers operating the Autonomous SOC are seeing it in their numbers: 75% faster investigations, 4x more threats handled, 42% fewer false positives5. Read the IDC Business Value Snapshot.
References
1 Gartner, “AI SOC Agents: Harnessing Innovation, Managing Expectations,” Kevin Schmidt, Alex Tytarenko, Steve Santos, 25 February 2026. G00841784.
2 Gartner, “AI SOC Agents: Harnessing Innovation, Managing Expectations,” Kevin Schmidt, Alex Tytarenko, Steve Santos, 25 February 2026. G00841784.
3 SAE International, “Taxonomy and Definitions for Terms Related to Driving Automation Systems for On-Road Motor Vehicles,” SAE Standard J3016_202104, April 2021. https://www.sae.org/standards/content/j3016_202104/
4 Gartner, “AI SOC Agents: Harnessing Innovation, Managing Expectations,” Kevin Schmidt, Alex Tytarenko, Steve Santos, 25 February 2026. G00841784.
5 IDC Business Value Snapshot, “The Business Value of SentinelOne Singularity AI SIEM,” Michelle Abraham and Matthew Marden, May 2026, sponsored by SentinelOne. #US54435826-BVS.
Third-Party Trademark Disclaimer
All third-party product names, logos, and brands mentioned in this publication are the property of their respective owners and are for identification purposes only. Use of these names, logos, and brands does not imply affiliation, endorsement, sponsorship, or association with the third party.

 Login

 Philadelphia-based Raptor Defense Company is advancing in two U.S. Army programs with PIT VIPER, a small modular wheeled unmanned ground vehicle the company calls a “Personal Combat Vehicle” and designs to be fielded at the level of the individual soldier, the company announced. Raptor was selected for Phase II of GroundBreaker 1, a joint unmanned […]